先去找类型的a标签 取出图片所在网址 取出https://desk.3gbizhi.com/deskMV/438.html
搭建Form界面
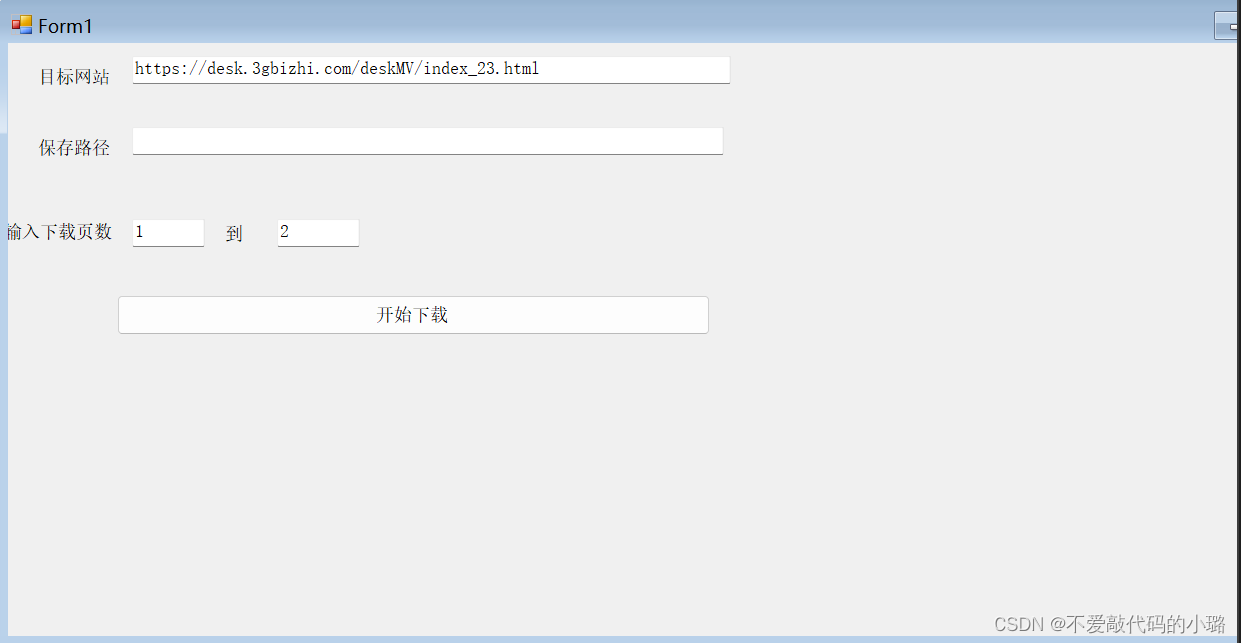
Http类
cs
public static HttpClient Client { get; }
static Http()
{
    HttpClientHandler handler = new HttpClientHandler();//处理消息对象
    //ServerCertificateCustomValidationCallback  是否开启免验证策略,有的网站不安全,
    //浏览器阻止你访问,需要把验证忽略掉
    handler.ServerCertificateCustomValidationCallback = (message, cart, chain, error) => { return true; };
    Client = new HttpClient(handler);//请求对象


}
图片所在页面网址的正则
cs
Regex imgHtml = new Regex(@"<a href=""(https://[a-zA-Z0-9/\.]+\.html)"" class=""[a-zA-Z0-9]* imgw"" target=""_blank"">" );
//< a href = "https://pic.3gbizhi.com/uploadmark/20231006/c54bae39ffc4a10b023fc5c7adfee803.jpg" class="arrows" target="_blank"><i class="fa fa-search-plus fa-fw"></i></a>
Regex picReg = new Regex(@"<a href=""(https://pic\.3gbizhi\.com/uploadmark/\d+/[a-zA-Z0-9]+\.(jpg|png))"" class=""arrows"" target=""_blank"">");
按钮的点击事件
cs
string url = this.textBox1.Text;// 获取爬虫的url index_23.html
int start = int.Parse(this.textBox3.Text); //开始页数 index_1.html
int end = int.Parse(this.textBox4.Text); //结束页数 index_2.html
Regex reg = new Regex(@"index_\d+\.html$");
url = reg.Replace(url,""); //Replace =替换,把后面替换前面类型的字符串https://desk.3gbizhi.com/deskMV/
cs
for (int i = start; i <=end; i++)
{
    string nowURL = $"{url}/index_{i}.html";
    HttpResponseMessage res = await Http.Client.GetAsync(nowURL);
    string data = await res.Content.ReadAsStringAsync();
     // 整体html字符串
    // 从data所有字符串匹配满足正则的字符串 返回结果是MatchCollection的数据集合
    MatchCollection maths = imgHtml.Matches(data);

    foreach (Match item in maths)
    {

        //下面需要根据html 匹配类型以下格式图片
        var res1 =  await Http.Client.GetAsync(picURL);
        string data1 = await res1.Content.ReadAsStringAsync();


        string picURL1 = picReg.Match(data1).Groups[1].Value;
        Console.WriteLine(picURL1);
        downLoad(picURL1);
    }
}
cs
 public async void downLoad(string url)
 {
    var res =  await Http.Client.GetAsync(url);
     byte[] b1 = await res.Content.ReadAsByteArrayAsync();
     //C:\Users\Administrator\Desktop
     File.WriteAllBytes(@"C:\Users\Administrator\Desktop\PP\"+Path.GetFileName(url), b1);
 }