源代码来自于网络
使用pytorch_grad_cam,对特定图片生成热力图结果。
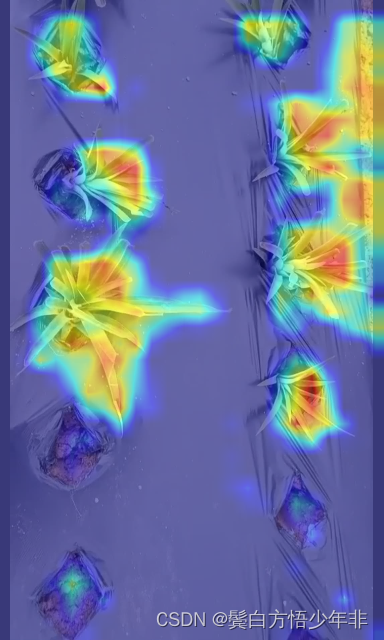
安装热力图工具
shell
pip install pytorch_grad_cam
pip install grad-cam# get_params中的参数:
# weight:
# 模型权重文件,代码默认是yolov8m.pt
# cfg:
# 模型文件,代码默认是yolov8m.yaml,需要注意的是需要跟weight中的预训练文件的配置是一样的,不然会报错
# device:
# 选择使用GPU还是CPU
# method:
# 选择grad-cam方法,默认是GradCAM,这里是提供了几种,可能对效果有点不一样,大家大胆尝试。
# layer::
# 选择需要可视化的层数,只需要修改数字即可,比如想用第9层,也就是model.model[9]。
# backward_type:
# 反向传播的方式,可以是以conf的loss传播,也可以class的loss传播,一般选用all,效果比较好一点。
# conf_threshold:
# 置信度,默认是0.6。
# ratio:
# 默认是0.02,就是用来筛选置信度高的结果,低的就舍弃,0.02则是筛选置信度最高的前2%的图像来进行热力图。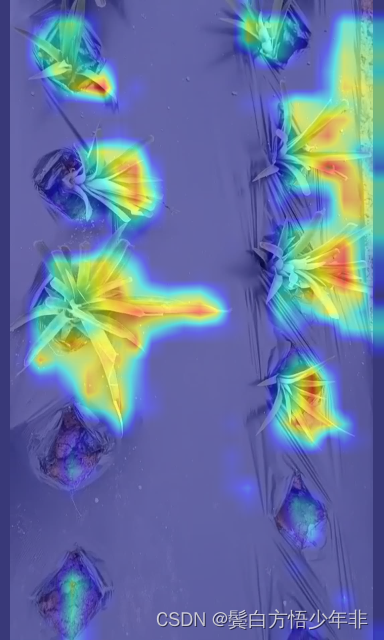
python
import warnings

warnings.filterwarnings('ignore')
warnings.simplefilter('ignore')
import torch, cv2, os, shutil
import numpy as np

np.random.seed(0)
import matplotlib.pyplot as plt
from tqdm import trange
from PIL import Image
from ultralytics.nn.tasks import DetectionModel as Model
from ultralytics.utils.torch_utils import intersect_dicts
from ultralytics.utils.ops import xywh2xyxy
from pytorch_grad_cam import GradCAMPlusPlus, GradCAM, XGradCAM
from pytorch_grad_cam.utils.image import show_cam_on_image
from pytorch_grad_cam.activations_and_gradients import ActivationsAndGradients


def letterbox(im, new_shape=(640, 640), color=(114, 114, 114), auto=True, scaleFill=False, scaleup=True, stride=32):
    # Resize and pad image while meeting stride-multiple constraints
    shape = im.shape[:2]  # current shape [height, width]
    if isinstance(new_shape, int):
        new_shape = (new_shape, new_shape)

    # Scale ratio (new / old)
    r = min(new_shape[0] / shape[0], new_shape[1] / shape[1])
    if not scaleup:  # only scale down, do not scale up (for better val mAP)
        r = min(r, 1.0)

    # Compute padding
    ratio = r, r  # width, height ratios
    new_unpad = int(round(shape[1] * r)), int(round(shape[0] * r))
    dw, dh = new_shape[1] - new_unpad[0], new_shape[0] - new_unpad[1]  # wh padding
    if auto:  # minimum rectangle
        dw, dh = np.mod(dw, stride), np.mod(dh, stride)  # wh padding
    elif scaleFill:  # stretch
        dw, dh = 0.0, 0.0
        new_unpad = (new_shape[1], new_shape[0])
        ratio = new_shape[1] / shape[1], new_shape[0] / shape[0]  # width, height ratios

    dw /= 2  # divide padding into 2 sides
    dh /= 2

    if shape[::-1] != new_unpad:  # resize
        im = cv2.resize(im, new_unpad, interpolation=cv2.INTER_LINEAR)
    top, bottom = int(round(dh - 0.1)), int(round(dh + 0.1))
    left, right = int(round(dw - 0.1)), int(round(dw + 0.1))
    im = cv2.copyMakeBorder(im, top, bottom, left, right, cv2.BORDER_CONSTANT, value=color)  # add border
    return im, ratio, (dw, dh)


class yolov8_heatmap:
    def __init__(self, weight, cfg, device, method, layer, backward_type, conf_threshold, ratio):
        device = torch.device(device)
        ckpt = torch.load(weight)
        model_names = ckpt['model'].names
        csd = ckpt['model'].float().state_dict()  # checkpoint state_dict as FP32
        model = Model(cfg, ch=3, nc=len(model_names)).to(device)
        csd = intersect_dicts(csd, model.state_dict(), exclude=['anchor'])  # intersect
        model.load_state_dict(csd, strict=False)  # load
        model.eval()
        print(f'Transferred {len(csd)}/{len(model.state_dict())} items')

        target_layers = [eval(layer)]
        method = eval(method)

        colors = np.random.uniform(0, 255, size=(len(model_names), 3)).astype(np.int32)
        self.__dict__.update(locals())

    def post_process(self, result):
        logits_ = result[:, 4:]
        boxes_ = result[:, :4]
        sorted, indices = torch.sort(logits_.max(1)[0], descending=True)
        return torch.transpose(logits_[0], dim0=0, dim1=1)[indices[0]], torch.transpose(boxes_[0], dim0=0, dim1=1)[
            indices[0]], xywh2xyxy(torch.transpose(boxes_[0], dim0=0, dim1=1)[indices[0]]).cpu().detach().numpy()

    def draw_detections(self, box, color, name, img):
        xmin, ymin, xmax, ymax = list(map(int, list(box)))
        cv2.rectangle(img, (xmin, ymin), (xmax, ymax), tuple(int(x) for x in color), 2)
        cv2.putText(img, str(name), (xmin, ymin - 5), cv2.FONT_HERSHEY_SIMPLEX, 0.8, tuple(int(x) for x in color), 2,
                    lineType=cv2.LINE_AA)
        return img

    def __call__(self, img_path, save_path):
        # remove dir if exist
        if os.path.exists(save_path):
            shutil.rmtree(save_path)
        # make dir if not exist
        os.makedirs(save_path, exist_ok=True)

        # img process
        img = cv2.imread(img_path)
        img = letterbox(img)[0]
        img = cv2.cvtColor(img, cv2.COLOR_BGR2RGB)
        img = np.float32(img) / 255.0
        tensor = torch.from_numpy(np.transpose(img, axes=[2, 0, 1])).unsqueeze(0).to(self.device)

        # init ActivationsAndGradients
        grads = ActivationsAndGradients(self.model, self.target_layers, reshape_transform=None)

        # get ActivationsAndResult
        result = grads(tensor)
        activations = grads.activations[0].cpu().detach().numpy()

        # postprocess to yolo output
        post_result, pre_post_boxes, post_boxes = self.post_process(result[0])
        print(post_result.size(0))
        for i in trange(int(post_result.size(0) * self.ratio)):
            if float(post_result[i].max()) < self.conf_threshold:
                break

            self.model.zero_grad()
            # get max probability for this prediction
            if self.backward_type == 'class' or self.backward_type == 'all':
                score = post_result[i].max()
                score.backward(retain_graph=True)

            if self.backward_type == 'box' or self.backward_type == 'all':
                for j in range(4):
                    score = pre_post_boxes[i, j]
                    score.backward(retain_graph=True)

            # process heatmap
            if self.backward_type == 'class':
                gradients = grads.gradients[0]
            elif self.backward_type == 'box':
                gradients = grads.gradients[0] + grads.gradients[1] + grads.gradients[2] + grads.gradients[3]
            else:
                gradients = grads.gradients[0] + grads.gradients[1] + grads.gradients[2] + grads.gradients[3] + \
                            grads.gradients[4]
            b, k, u, v = gradients.size()
            weights = self.method.get_cam_weights(self.method, None, None, None, activations,
                                                  gradients.detach().numpy())
            weights = weights.reshape((b, k, 1, 1))
            saliency_map = np.sum(weights * activations, axis=1)
            saliency_map = np.squeeze(np.maximum(saliency_map, 0))
            saliency_map = cv2.resize(saliency_map, (tensor.size(3), tensor.size(2)))
            saliency_map_min, saliency_map_max = saliency_map.min(), saliency_map.max()
            if (saliency_map_max - saliency_map_min) == 0:
                continue
            saliency_map = (saliency_map - saliency_map_min) / (saliency_map_max - saliency_map_min)

            # add heatmap and box to image
            cam_image = show_cam_on_image(img.copy(), saliency_map, use_rgb=True)
            cam_image = Image.fromarray(cam_image)
            cam_image.save(f'{save_path}/{i}.png')

def get_params():
    params = {
        'weight': './weights/bz-yolov8-aspp-s-100.pt', # 这选择想要热力可视化的模型权重路径
        'cfg': './ultralytics/cfg/models/cfg2024/YOLOv8-金字塔结构改进/YOLOv8-ASPP.yaml', # 这里选择与训练上面模型权重相对应的.yaml文件路径
        'device': 'cpu', # 选择设备,其中0表示0号显卡。如果使用CPU可视化 # 'device': 'cpu' cuda:0
        'method': 'GradCAM', # GradCAMPlusPlus, GradCAM, XGradCAM
        'layer': 'model.model[6]',   # 选择特征层
        'backward_type': 'all', # class, box, all
        'conf_threshold': 0.65, # 置信度阈值默认0.65, 可根据情况调节
        'ratio': 0.02 # 取前多少数据,默认是0.02,可根据情况调节
    }
    return params

if __name__ == '__main__':
    model = yolov8_heatmap(**get_params()) # 初始化
    model('output_002.jpg', './result') # 第一个参数是图片的路径,第二个参数是保存路径,比如是result的话,其会创建一个名字为result的文件夹,如果result文件夹不为空,其会先清空文件夹。