背景需求
因为win电脑坏了,所以换了一个只有WPS的电脑,所有的周计划py都要重做
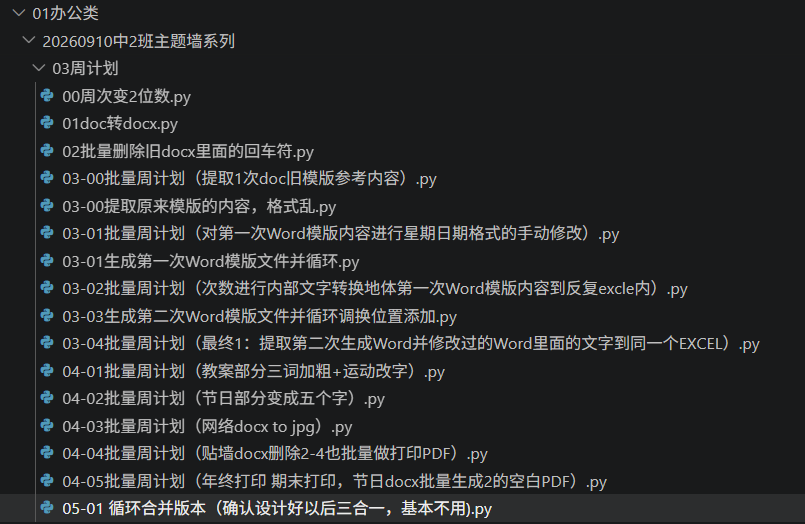
零、原有资料
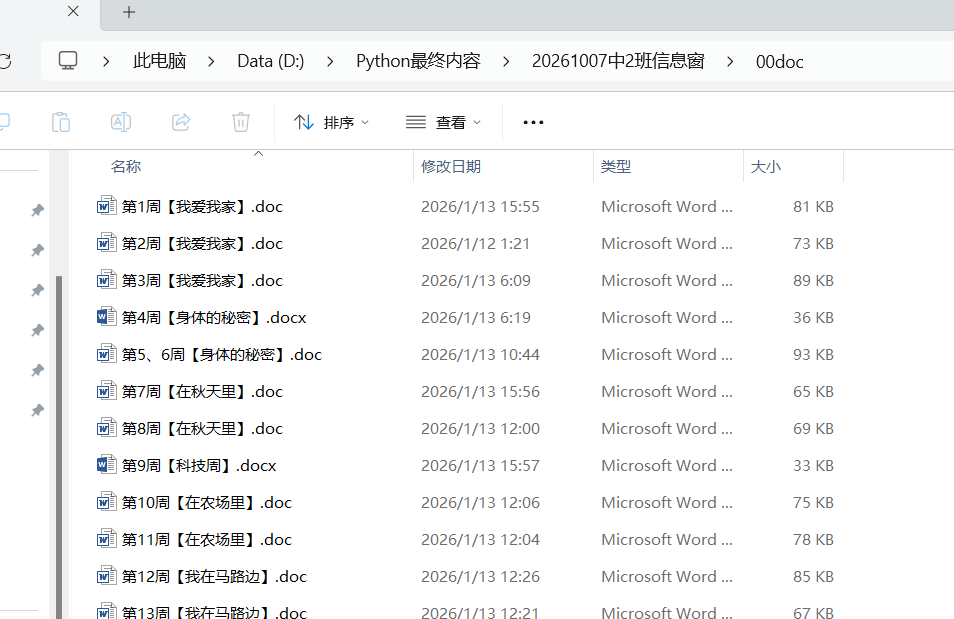 一、doc改名成01周、02周
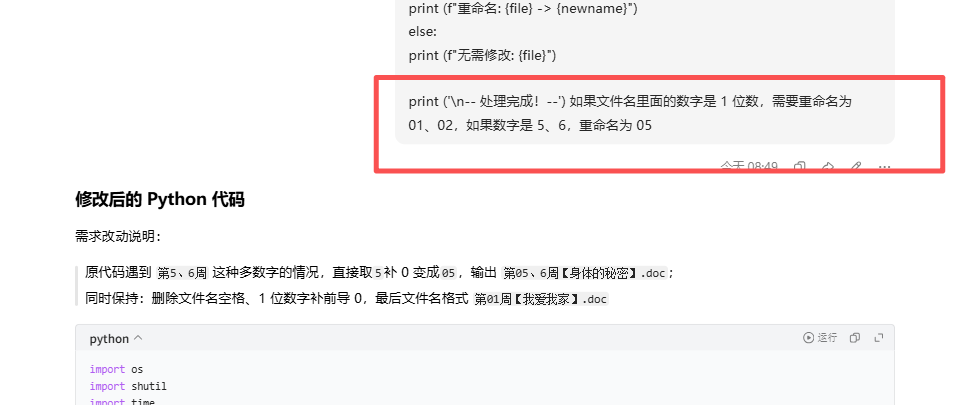
因为每次提供的原始的文件名标注不一样,所以重新用豆包写新的代码(文件名数字变成两位数)
python
import os
import shutil
import time
import re


import os
import re
import shutil

# 定义路径
path = r"D:\Python最终内容\20261007中2班周计划"
path1 = path + r"\00doc"   # 源文件夹
path2 = path + r"\01doc"   # 输出目标文件夹

# 创建目标文件夹
os.makedirs(path2, exist_ok=True)

print('--开始:保留原文件名空格,周次数字转为两位数,处理结果保存到01doc-----')

# 获取源文件夹文件列表
fileList = os.listdir(path1)

for file in fileList:
    old_full_src = os.path.join(path1, file)
    # 跳过文件夹,只处理文件
    if not os.path.isfile(old_full_src):
        continue

    match = re.search(r'第(.*?)周', file)
    if match:
        week_str = match.group(1)
        print(f"原始周文字:{week_str}")

        # 提取周段开头第一个数字
        num_match = re.search(r'^\d+', week_str)
        if num_match:
            first_num = num_match.group()
            if len(first_num) == 1:
                new_first = f"{int(first_num):02d}"
                new_week_str = week_str.replace(first_num, new_first, 1)
                newname = file.replace(f'第{week_str}周', f'第{new_week_str}周')
            else:
                newname = file
        else:
            newname = file
    else:
        # 没有匹配到"第xx周",文件名不变
        newname = file

    print(f"处理后文件名:{newname}")
    new_full_dst = os.path.join(path2, newname)

    # 复制文件到01doc,使用新名称,源文件保持不变
    shutil.copy2(old_full_src, new_full_dst)
    print(f"已复制: {file} -> {newname}\n")

print('\n--全部处理完成!结果全部保存在01doc文件夹--')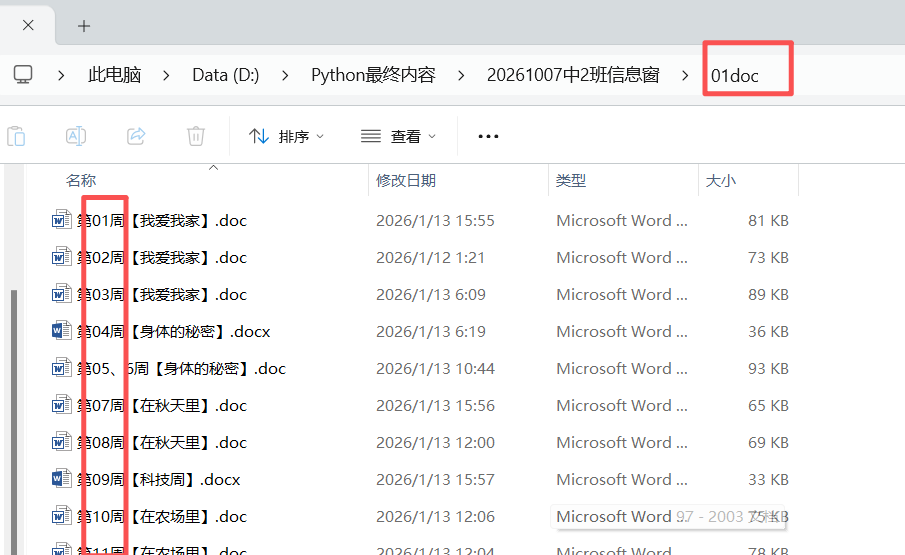
二、doc改成docx
python
'''
doc转docx
Deepseek,阿夏
20260228
'''
import os
from win32com import client as wc

# 路径设置
path = r"D:\Python最终内容\20261007中2班信息窗"
oldpath = os.path.join(path, r'01doc')  # 原文件doc地址
newpath = os.path.join(path, r'02docx')  # 新文件docx地址

# 确保新路径存在
os.makedirs(newpath,exist_ok=True)

# 提取所有doc和docx文件的路径
files = []
for file in os.listdir(oldpath):
    if file.lower().ends
'''
doc转docx
Deepseek,阿夏
20260228
'''
import os
from win32com import client as wc

# 路径设置
path = r"D:\Python最终内容\20261007中2班周计划"
oldpath = os.path.join(path, r'01doc')  # 原文件doc地址
newpath = os.path.join(path, r'02docx')  # 新文件docx地址

# 确保新路径存在
os.makedirs(newpath,exist_ok=True)

# 提取所有doc和docx文件的路径
files = []
for file in os.listdir(oldpath):
    if file.lower().endswith(('.doc', '.docx')) and not file.startswith('~$'):
        files.append(os.path.join(oldpath, file))

# 打开并转换文件
word = wc.Dispatch("Word.Application")
word.Visible = False  # 设置为False以在后台运行
try:
    for file in files:
        print("处理文件:" + file)
        doc = word.Documents.Open(file)

        # 提取文件名和修改扩展名
        base_name = os.path.basename(file)
        name, ext = os.path.splitext(base_name)
        new_file = os.path.join(newpath, name + '.docx')

        # 保存为docx格式
        doc.SaveAs(new_file, 12)  # 12表示docx格式
        doc.Close()
except Exception as e:
    print(f"发生错误:{e}")
finally:
    word.Quit()with(('.doc', '.docx')) and not file.startswith('~$'):
        files.append(os.path.join(oldpath, file))

# 打开并转换文件
word = wc.Dispatch("Word.Application")
word.Visible = False  # 设置为False以在后台运行
try:
    for file in files:
        print("处理文件:" + file)
        doc = word.Documents.Open(file)

        # 提取文件名和修改扩展名
        base_name = os.path.basename(file)
        name, ext = os.path.splitext(base_name)
        new_file = os.path.join(newpath, name + '.docx')

        # 保存为docx格式
        doc.SaveAs(new_file, 12)  # 12表示docx格式
        doc.Close()
except Exception as e:
    print(f"发生错误:{e}")
finally:
    word.Quit()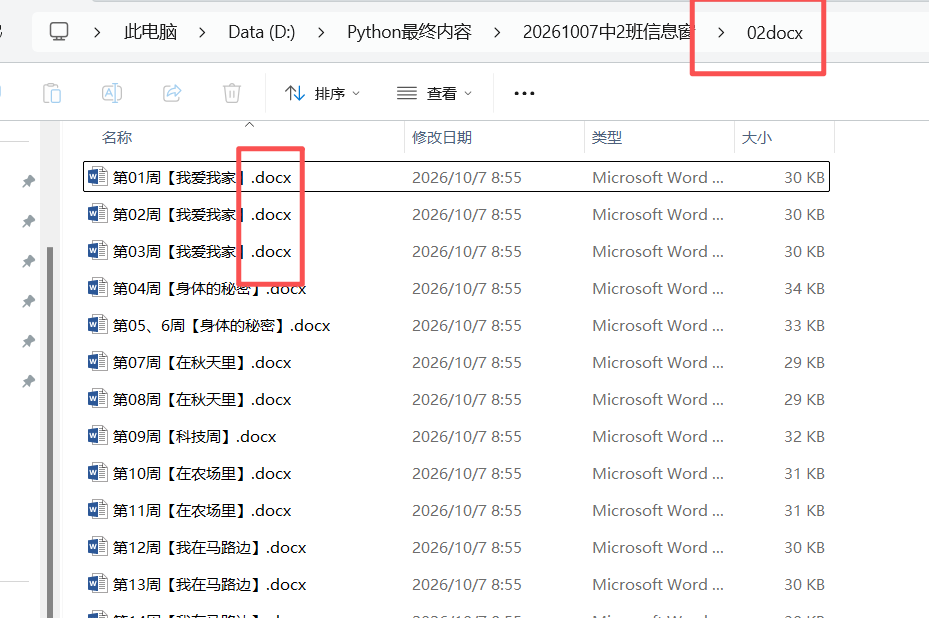
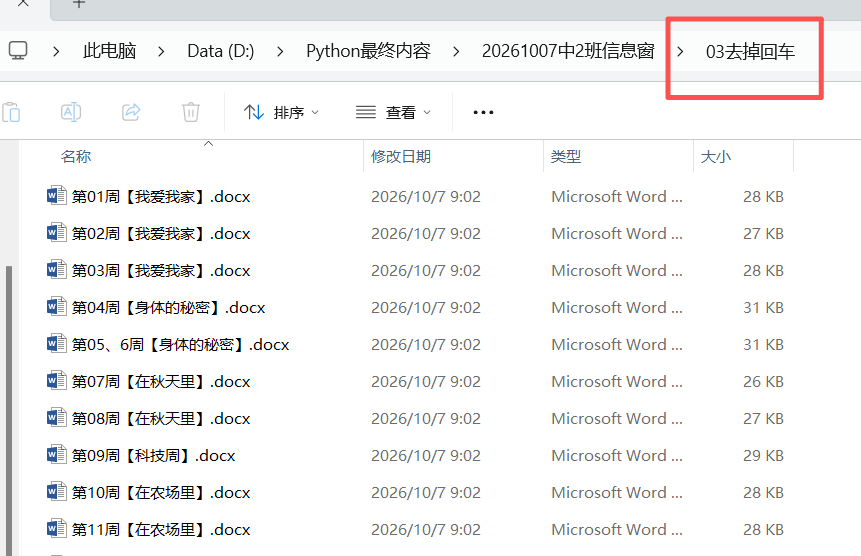
三、去掉回车
python
'''
去掉docx文件里的回车
Deepseek,阿夏
20260228
'''


import glob,os
from docx import Document


path = r"D:\Python最终内容\20261007中2班周计划"

newpath = os.path.join(path, r'03去掉回车')  # 新文件docx地址
os.makedirs(newpath,exist_ok=True)

docx_files = glob.glob(path + r'\02docx\*.docx')  # 读取所有.docx文件

for file_path in docx_files:  # 遍历每个文件路径
    file_name = os.path.basename(file_path)  # 获取文件名
    print(f"Processing file: {file_name}")

    doc = Document(file_path)  # 打开文档

    # 使用列表推导式创建一个新段落列表,排除空段落
    new_paragraphs = [p for p in doc.paragraphs if p.text.strip()]

    # 清空当前文档的所有段落
    doc.paragraphs[:] = []

    # 将非空段落添加回文档
    for p in new_paragraphs:
        doc.add_paragraph(p.text)

    doc.save(newpath +fr"\{file_name}")
# # # ------------------------------------------------
# # # 版权声明:本文为CSDN博主「lsjweiyi」的原创文章,遵循CC 4.0 BY-SA版权协议,转载请附上原文出处链接及本声明。
# # # 原文链接:https://blog.csdn.net/lsjweiyi/article/details/121728630
四、word导出到EXCEL内容第一次
python
from docx import Document
import os
import glob
from openpyxl import Workbook
newpath = r'D:\Python最终内容\20261007中2班周计划'
new = newpath + r'\03去掉回车'
os.makedirs(newpath, exist_ok=True)
pathall = []
for file_name in os.listdir(new):
fullp = os.path.join(new, file_name)
pathall.append(fullp)
print(pathall)
print(len(pathall))
# 使用openpyxl新建工作簿
wb = Workbook()
ws = wb.active
ws.title = "sheet1"
titleall = ['grade', 'classnum', 'weekhan', 'datelong', 'day1', 'day2', 'day3', 'day4', 'day5', 'day6', 'day7', 'life', 'life1', 'life2',
'sportcon1', 'sportcon2', 'sportcon3', 'sportcon4', 'sportcon5', 'sportcon6', 'sportcon7', 'sport1', 'sport2', 'sport3', 'sport4',
'sport5', 'sport6', 'sport7', 'sportzd1', 'sportzd2', 'sportzd3', 'game1', 'game2', 'game3', 'game4', 'game5', 'game6', 'game7',
'gamezd1', 'gamezd2', 'theme', 'theme1', 'theme2', 'gbstudy', 'art', 'gbstudy1', 'gbstudy2', 'gbstudy3', 'jtstudy1', 'jtstudy2',
'jtstudy3', 'jtstudy4', 'jtstudy5', 'jtstudy6', 'jtstudy7', 'gy1', 'gy2', 'fk1', 'pj11', 'fk1nr', 'fk1tz', 'fk2', 'pj21', 'fk2nr',
'fk2tz', 'dateshort', 'weekshu', 'title1', 'topic11', 'topic12', 'jy1', 'cl1', 'j1gc', 'title2', 'topic21', 'topic22', 'jy2', 'cl2',
'j2gc', 'title3', 'topic31', 'topic32', 'jy3', 'cl3', 'j3gc', 'title4', 'topic41', 'topic42', 'jy4', 'cl4', 'j4gc', 'title5',
'topic51', 'topic52', 'jy5', 'cl5', 'j5gc', 'title6', 'topic61', 'topic62', 'jy6', 'cl6', 'j6gc', 'title7', 'topic71', 'topic72',
'jy7', 'cl7', 'j7gc', 'fs1', 'fs11', 'fs2', 'fs21', 'T1', 'T2', 'T3', 'T4', 'T5', 'T6', 'T7']
# 写入表头
for col_idx, val in enumerate(titleall):
ws.cell(row=1, column=col_idx + 1, value=val)
n = 2 # excel行从第2行开始写数据,第一行表头
for h in range(len(pathall)):
LIST = []
doc_path = pathall[h]
print(f"\n=====正在解析文件:{os.path.basename(doc_path)} =====")
try:
doc = Document(doc_path)
tables = doc.tables
total_table_count = len(tables)
print(f"本文件总表格数量 total_table_count={total_table_count}")
first_table = doc.tables[0]
first_row = first_table.rows[0]
num_columns = len(first_row.cells)
print(f"第{n - 1}张表格有 {num_columns} 列")
# 获取文档第一段落:中(2)班 第XX周 活动安排
bt = doc.paragraphs[0].text.strip()
LIST.append(bt[0])
LIST.append(bt[2])
if len(bt) == 16:
LIST.append(bt[8:9])
else:
LIST.append(bt[8:10])
rq1 = doc.paragraphs[1].text.strip()
LIST.append(rq1[3:])
table = tables[0]
d = [9, 10, 11]
dl = [8, 9, 10]
tj = [2, 1, 0]
for dd in range(len(d)):
if num_columns == int(d[dd]):
for xq in range(3, dl[dd]):
xq1 = table.cell(0, xq).text
LIST.append(xq1)
for tx in range(int(tj[dd])):
LIST.append('')
# 生活内容
l = table.cell(1, 4).text.strip()
ll = l.split('\n')
LIST.append(l)
for lll in range(2):
if lll < len(ll):
item = ll[lll]
if len(item) > 2:
LIST.append(item[2:])
else:
LIST.append("")
else:
LIST.append("")
# 运动集体、分散游戏
for dd in range(len(d)):
if num_columns == int(d[dd]):
for jt in range(3, dl[dd]):
jt1 = table.cell(3, jt).text
LIST.append(jt1)
for tx in range(tj[dd]):
LIST.append('')
for jt2 in range(3, dl[dd]):
jt3 = table.cell(4, jt2).text
LIST.append(jt3)
for tx in range(tj[dd]):
LIST.append('')
# 运动观察指导
s = table.cell(5, 4).text.split('\n')
for sss in range(3):
if sss < len(s):
LIST.append(s[sss][2:] if len(s[sss]) > 2 else "")
else:
LIST.append("")
# 游戏内容
for dd in range(len(d)):
if num_columns == int(d[dd]):
for fj in range(3, dl[dd]):
fj2 = table.cell(7, fj).text
LIST.append(fj2)
for tx in range(int(tj[dd])):
LIST.append('')
# 游戏观察指导
g = table.cell(8, 4).text.split('\n')
for ggg in range(2):
if ggg < len(g):
LIST.append(g[ggg][2:] if len(g[ggg]) > 2 else "")
else:
LIST.append("")
# 主题
ti = table.cell(9, 4).text.split('\n')
LIST.append(ti[0] if len(ti) >= 1 else "")
for ttt in range(1, 3):
if ttt < len(ti):
LIST.append(ti[ttt][2:] if len(ti[ttt]) > 2 else "")
else:
LIST.append("")
#个别化学习
iiii = table.cell(10, 4).text
LIST.append(iiii)
ii8 = table.cell(11, 4).text
LIST.append(ii8)
ii = table.cell(12, 4).text.split('\n')
for iii1 in range(3):
if iii1 < len(ii):
LIST.append(ii[iii1][2:] if len(ii[iii1]) > 2 else "")
else:
LIST.append("")
#集体学习栏目
for dd in range(len(d)):
if num_columns == int(d[dd]):
for e in range(3, dl[dd]):
k = table.cell(13, e).text
LIST.append(k)
for tx in range(int(tj[dd])):
LIST.append('')
#家园共育
yy = table.cell(14, 4).text.split('\n')
for yyy in range(2):
if yyy < len(yy):
LIST.append(yy[yyy][2:] if len(yy[yyy]) > 2 else "")
else:
LIST.append("")
#反馈调整
for dd in range(len(d)):
if num_columns == int(d[dd]):
ff = table.cell(1, dl[dd]).text.split('\n')
for j in range(2):
pos = j * 4
if pos < len(ff):
LIST.append(ff[pos][0:4])
LIST.append(ff[pos][10:-1])
else:
LIST.append("")
LIST.append("")
if pos + 1 < len(ff):
LIST.append(ff[pos + 1])
else:
LIST.append("")
if pos + 3 < len(ff):
LIST.append(ff[pos + 3])
else:
LIST.append("")
date1 = ""
date2 = ""
bt2 = ""
for p in doc.paragraphs:
text = p.text.strip()
if "期" in text and "第" in text:
bt2 = text
break
if bt2:
start_index = bt2.find('期')
end_index = bt2.find('第')
if start_index != -1 and end_index != -1 and start_index < end_index:
date1 = bt2[start_index + 1: end_index].strip()
start_index2 = bt2.find('(')
end_index2 = bt2.find(')')
if start_index2 != -1 and end_index2 != -1 and start_index2 < end_index2:
date2 = bt2[start_index2 + 1: end_index2].strip()
LIST.append(date1)
LIST.append(date2)
ts = [3, 4, 4]
ks = [12, 6, 0]
for dd in range(len(d)):
if num_columns == int(d[dd]):
for a in range(1, ts[dd]):
for b in range(2):
# =========边界判断!!防止索引越界========
if 0 <= a < total_table_count:
table = tables[a]
else:
print(f"警告:a={a}超出表格总数{total_table_count},填充空值")
for _ in range(6):
LIST.append('')
continue
all_lines = table.cell(0, b).text.split('\n')
if len(all_lines) == 1:
for _ in range(6):
LIST.append('')
else:
fs1 = all_lines[0].strip()
title = ""
if ":" in fs1:
start_idx = fs1.index(":") + 1
if "执" in fs1:
end_idx = fs1.index("执")
title = fs1[start_idx:end_idx].strip()
else:
title = fs1[start_idx:].strip()
LIST.append(title)
target_start_idx = -1
for idx, content in enumerate(all_lines):
if "活动目标:" in content:
target_start_idx = idx
break
for i in range(1, 3):
if target_start_idx != -1 and (target_start_idx + i) < len(all_lines):
mb = all_lines[target_start_idx + i].lstrip("1234567890.、").strip()
LIST.append(mb)
else:
LIST.append("")
experience_prep = ""
material_prep = ""
prep_start_idx = -1
for idx, content in enumerate(all_lines):
if "活动准备:" in content:
prep_start_idx = idx
break
if prep_start_idx != -1:
for i in range(prep_start_idx + 1, len(all_lines)):
line = all_lines[i].strip()
if not line:
continue
if line.startswith("经验准备:"):
experience_prep = line[5:].strip()
elif line.startswith("物质准备:"):
material_prep = line[5:].strip()
LIST.append(experience_prep)
LIST.append(material_prep)
pro_lines = []
flag = False
for line in all_lines:
if "活动过程:" in line:
flag = True
continue
if flag:
pro_lines.append(line)
PRO = '\n'.join(pro_lines)
LIST.append(PRO)
for a in range(int(ts[dd]), int(ts[dd]) + 1):
for b in range(1):
if 0 <= a < total_table_count:
table = tables[a]
else:
print(f"警告 a={a}超出表格总数{total_table_count},填充空")
LIST.append('')
for _ in range(5):
LIST.append("")
for _ in range(int(ks[dd])):
LIST.append('')
continue
all_lines = table.cell(0, b).text.split('\n')
if len(all_lines) == 1:
LIST.append('')
else:
fs1 = all_lines[0].strip()
title = ""
if ":" in fs1 and "执" in fs1:
s_idx = fs1.index(":") + 1
e_idx = fs1.index("执")
title = fs1[s_idx:e_idx].strip()
LIST.append(title)
for t in range(2, 4):
if t < len(all_lines):
LIST.append(all_lines[t][2:].strip())
else:
LIST.append("")
if 5 < len(all_lines):
LIST.append(all_lines[5][5:].strip())
else:
LIST.append("")
if 6 < len(all_lines):
LIST.append(all_lines[6][5:].strip())
else:
LIST.append("")
pro = all_lines[8:] if 8 < len(all_lines) else []
PRO = '\n'.join(pro)
LIST.append(PRO)
for _ in range(int(ks[dd])):
LIST.append('')
for c in range(2):
a_idx = ts[dd]
if 0 <= a_idx < total_table_count:
table = tables[a_idx]
else:
print(f"警告 a_idx={a_idx}超出表格总数{total_table_count}")
LIST.append("")
LIST.append("")
continue
fs = table.cell(c, 1).text.split('\n')
if len(fs) >= 2:
fs2 = fs[1]
title_reflect = ""
if ":" in fs2 and "执" in fs2:
s_idx = fs2.index(":") + 1
e_idx = fs2.index("执")
title_reflect = fs2[s_idx:e_idx].strip()
LIST.append(title_reflect)
reflect_text = '\n'.join([" " + x for x in fs[2:]])
LIST.append(reflect_text)
else:
LIST.append("")
LIST.append("")
extracted_texts = []
for tab in doc.tables[:5]:
for cell in tab.rows[0].cells:
ct = cell.text.strip()
if '执教:' in ct:
s = ct.find('执教:') + len('执教:')
e = ct.find('\n')
extracted_texts.append(ct[s:e].strip() if e != -1 else ct[s:].strip())
for tname in extracted_texts:
LIST.append(tname)
# 写入excel一行
for col_index, cell_val in enumerate(LIST):
ws.cell(row=n, column=col_index + 1, value=cell_val)
n += 1
except Exception as err:
print(f"!!!解析文件 {doc_path} 发生异常:{err}")
print("跳过该文件,继续下一个")
#保存文件
out1 = os.path.join(newpath, r'09_00 旧版周计划提取信息(导出一次).xlsx')
out2 = os.path.join(newpath, r'09_01 旧版周计划提取信息(手动修改).xlsx')
wb.save(out1)
wb.save(out2)
print(f"\n全部处理完成,输出文件:\n{out1}\n{out2}")提取的内容有大量缺失,说明每个Word的周计划表格是不一样的。
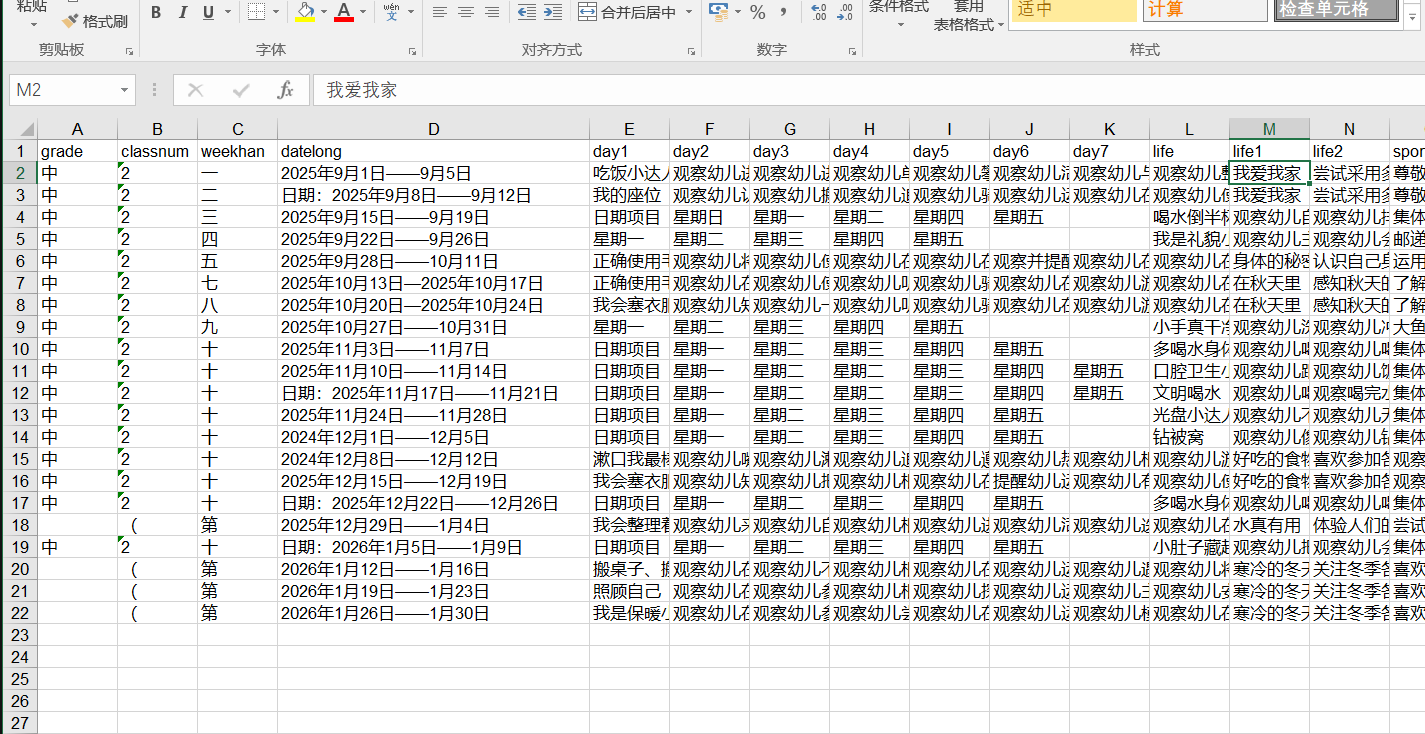
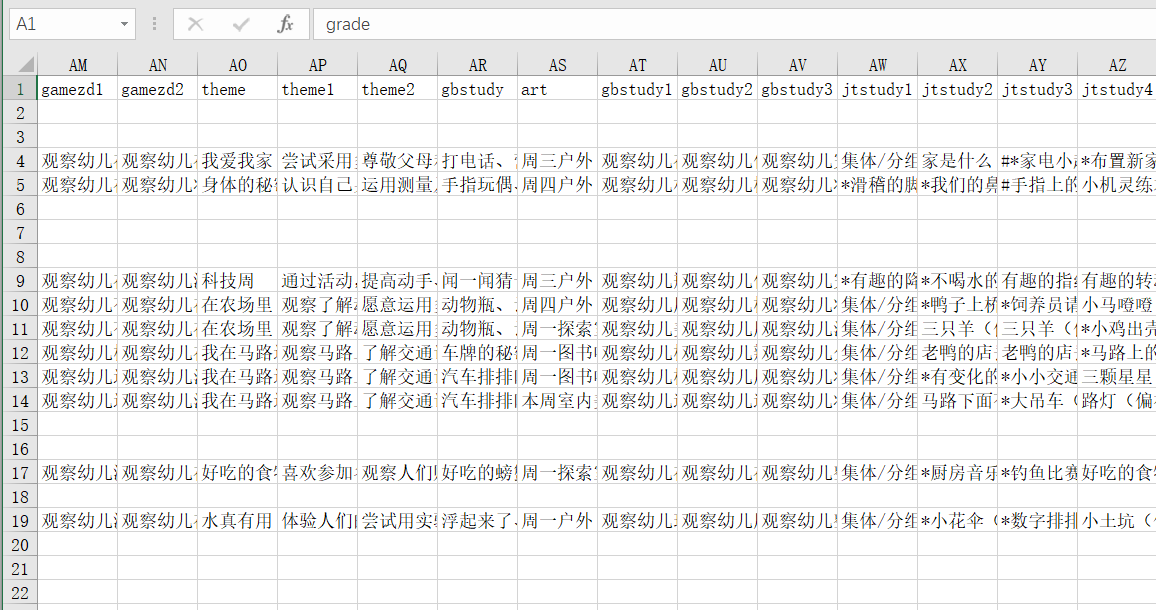
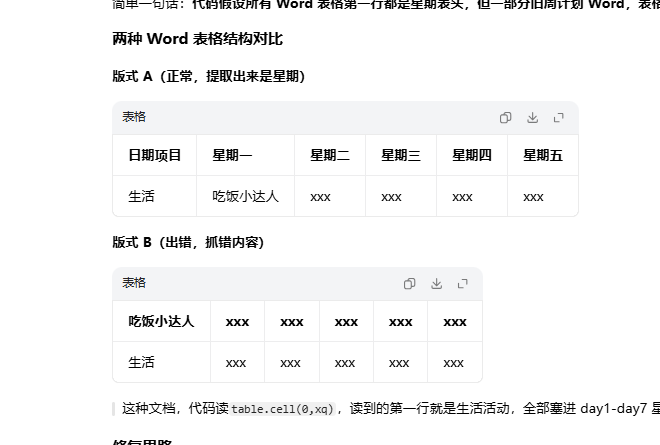
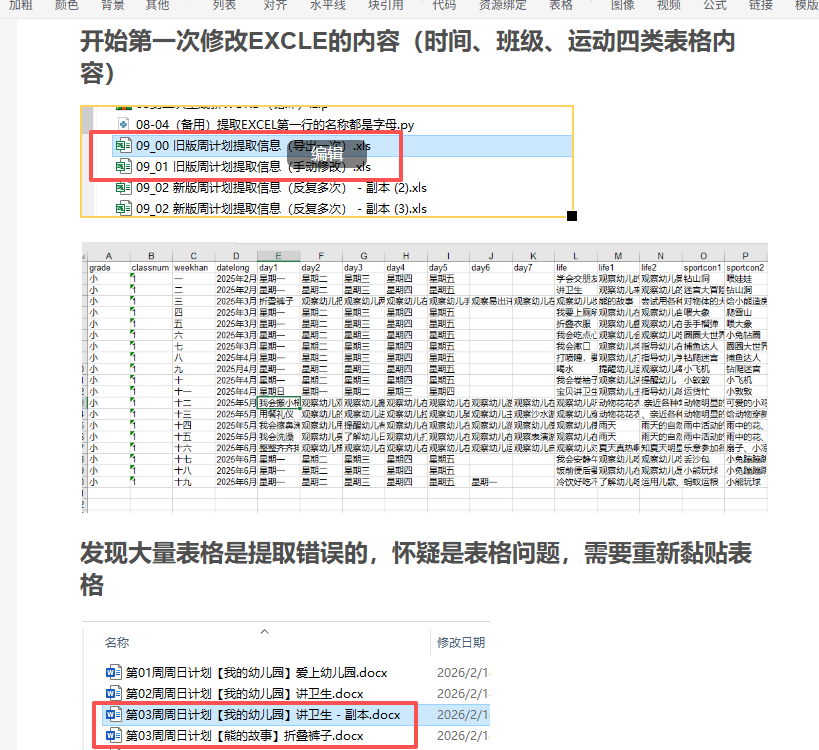 但是上次只有5周有问题,所以人工调用一个正确模版,把错误的周的内容重新黏贴。最后也顺利生成
 https://mp.csdn.net/mp_blog/creation/editor/158182738