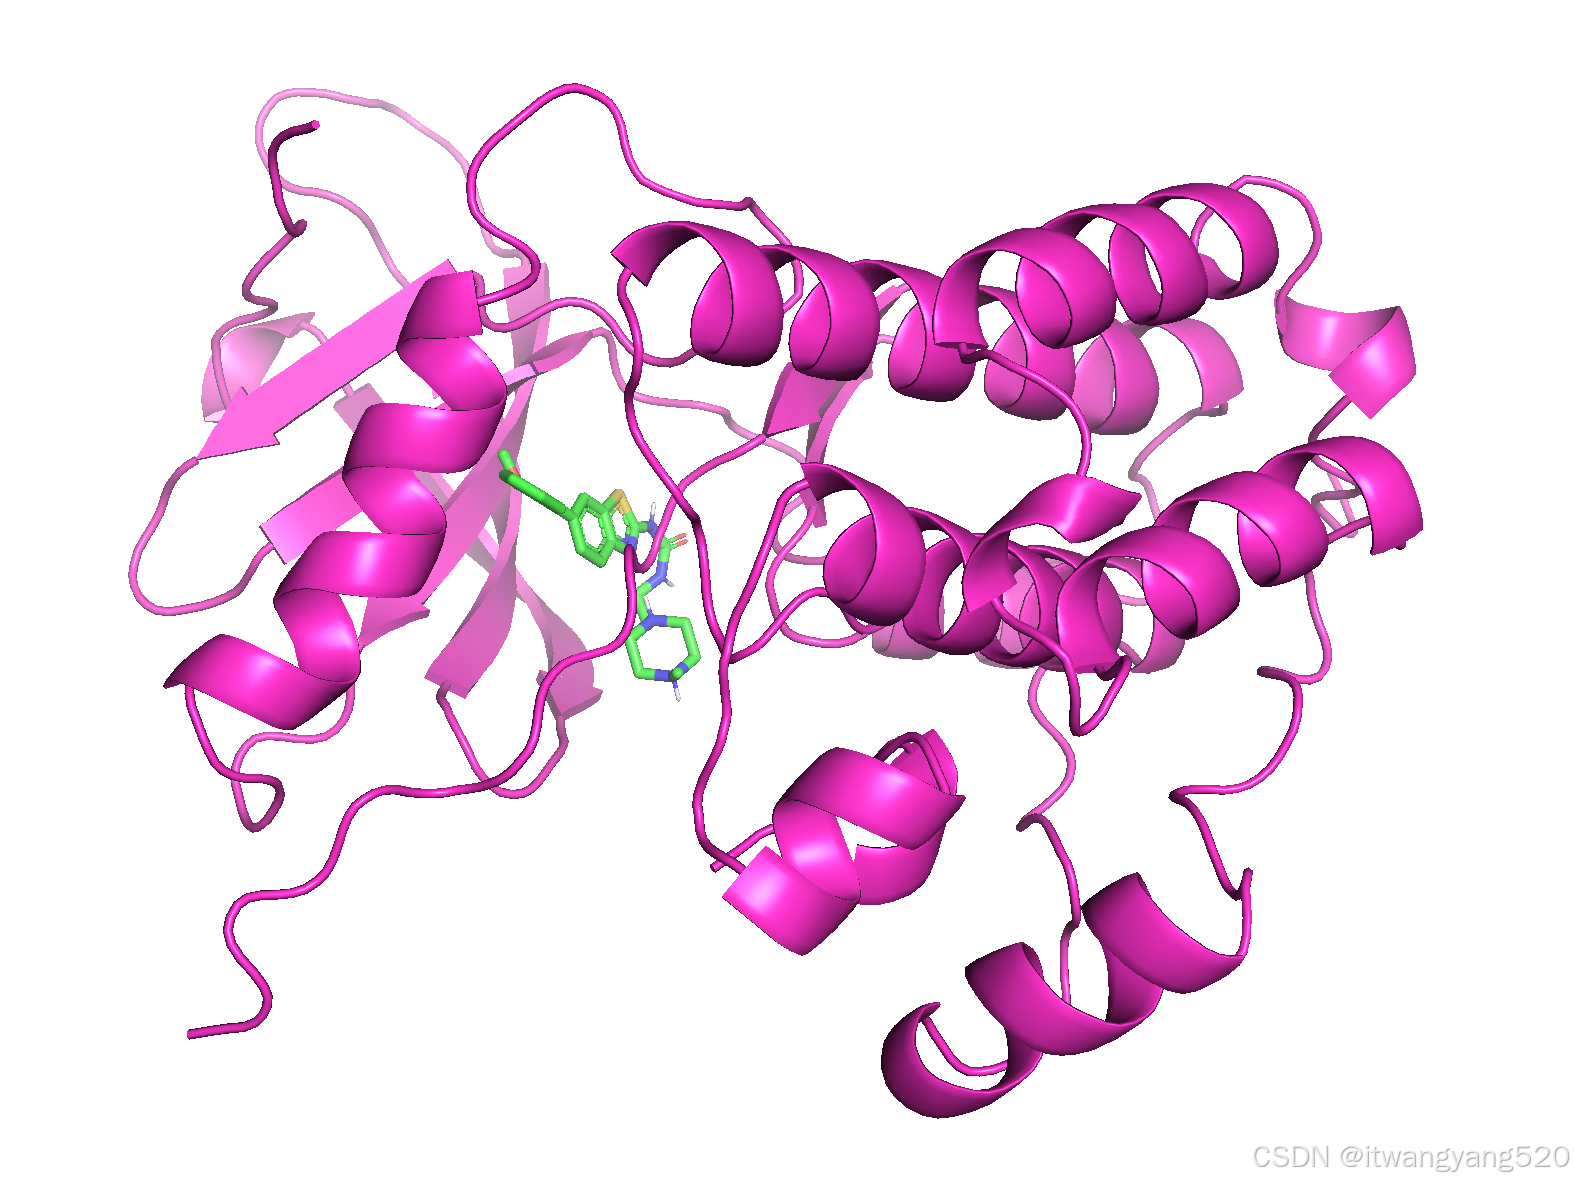
import warnings
from pathlib import Path
import subprocess
from itertools import product
import numpy as np
import pandas as pd
from MDAnalysis import Universe
from openbabel import pybel
import os
import requests  # 用于下载文件

# 清楚 warning 信息

# Filter warnings
warnings.filterwarnings("ignore")

# 设置工作目录
HERE = Path(os.getcwd())
DATA = HERE / 'data'
DATA.mkdir(parents=True, exist_ok=True)

# CSV 文件路径
RESULT_CSV = DATA / 'result_dock.csv'

# 初始化 CSV 文件
if not RESULT_CSV.exists():
    pd.DataFrame(columns=['pdb', 'ligand_resnames', 'smiles', 'dock_info']).to_csv(RESULT_CSV, index=False)


class Structure(Universe):
    """Core object to load structures with."""

    @classmethod
    def from_string(cls, pdb_path):
        """Load a structure from a local PDB file."""
        return cls(pdb_path)


def download_pdb(pdb_id, save_path):
    """从 RCSB PDB 数据库下载 PDB 文件."""
    url = f"https://files.rcsb.org/download/{pdb_id}.pdb"
    response = requests.get(url)
    if response.status_code == 200:
        with open(save_path, "wb") as file:
            file.write(response.content)
        print(f"{pdb_id} 下载成功.")
    else:
        raise ValueError(f"无法下载 {pdb_id}: {response.status_code}")


# 提取蛋白质并保存为 PDB 格式
def extract_protein_to_pdb(structure, protein_path):
    """Extract protein from structure and save it as PDB."""
    protein = structure.select_atoms("protein")
    protein.write(str(protein_path))


# 自动检测所有配体残基
def find_all_ligand_resnames(structure):
    """返回所有非蛋白质和非水分子的残基名称列表"""
    ligand_atoms = structure.select_atoms("not protein and not resname HOH")
    return list(set(ligand_atoms.resnames))


def pdb_to_pdbqt(pdb_path, pdbqt_path, pH=7.4):
    """Convert a PDB file to a PDBQT file."""
    molecule = list(pybel.readfile("pdb", str(pdb_path)))[0]
    molecule.OBMol.CorrectForPH(pH)
    molecule.addh()
    for atom in molecule.atoms:
        atom.OBAtom.GetPartialCharge()
    molecule.write("pdbqt", str(pdbqt_path), overwrite=True)


def smiles_to_pdbqt(smiles, pdbqt_path, pH=7.4):
    """Convert a SMILES string to a PDBQT file."""
    molecule = pybel.readstring("smi", smiles)
    molecule.OBMol.CorrectForPH(pH)
    molecule.addh()
    molecule.make3D(forcefield="mmff94s", steps=10000)
    for atom in molecule.atoms:
        atom.OBAtom.GetPartialCharge()
    molecule.write("pdbqt", str(pdbqt_path), overwrite=True)


def run_smina(ligand_path, protein_path, out_path, pocket_center, pocket_size):
    """Perform docking with Smina."""
    output_text = subprocess.check_output([
        "smina",
        "--receptor", str(protein_path),
        "--ligand", str(ligand_path),
        "--out", str(out_path),
        "--center_x", str(pocket_center[0]),
        "--center_y", str(pocket_center[1]),
        "--center_z", str(pocket_center[2]),
        "--size_x", str(pocket_size[0]),
        "--size_y", str(pocket_size[1]),
        "--size_z", str(pocket_size[2])
    ])
    return output_text.decode("utf-8")


def parse_dock_info(dock_output):
    """解析 Smina 输出中的对接信息"""
    dock_lines = dock_output.splitlines()
    dock_data = []
    capture = False
    for line in dock_lines:
        if "mode" in line and "affinity" in line:  # 开始捕获表格数据
            capture = True
            continue
        if capture:
            if line.strip() == "" or "Refine time" in line or "Loop time" in line:
                break
            dock_data.append(line.strip())
    return "\n".join(dock_data)


def split_sdf_file(sdf_path):
    """Split an SDF file into separate files for each molecule."""
    sdf_path = Path(sdf_path)
    stem = sdf_path.stem
    parent = sdf_path.parent
    molecules = pybel.readfile("sdf", str(sdf_path))
    for i, molecule in enumerate(molecules, 1):
        molecule.write("sdf", str(parent / f"{stem}_{i}.sdf"), overwrite=True)


pdb_list = pd.read_csv('data/pdb.csv')['pdb_id']
# 读取 data 里面的 pic50_greater_equal_9.0.csv 文件,获取其中的 SMILES,前面的 20 个
smiles_list = pd.read_csv('data/pic50_greater_equal_9.0.csv')['smiles'][:20]

# 遍历所有 PDB 和 SMILES 的笛卡尔积
for pdb_id, smiles in product(pdb_list, smiles_list):
    # 创建每个 PDB 的独立目录
    pdb_dir = DATA / f"data_{pdb_id}"
    pdb_dir.mkdir(parents=True, exist_ok=True)

    # 定义 PDB 文件路径
    pdb_path = pdb_dir / f"{pdb_id}.pdb"

    # 如果 PDB 文件不存在,则从 RCSB 下载
    if not pdb_path.exists():
        print(f"{pdb_id} 文件不存在,正在下载...")
        download_pdb(pdb_id, pdb_path)

    # 加载结构
    structure = Structure.from_string(pdb_path)

    # 提取并保存蛋白质部分
    protein_path = pdb_dir / "protein.pdb"
    extract_protein_to_pdb(structure, protein_path)

    # 转换蛋白质为 PDBQT 格式
    protein_pdbqt_path = pdb_dir / "protein.pdbqt"
    pdb_to_pdbqt(protein_path, protein_pdbqt_path)

    # 检测所有 ligand
    all_ligands = find_all_ligand_resnames(structure)

    # all_ligands[0]变为shape为(1,)的数组,方便后续循环
    # all_ligands = ["VX6"]
    print(f"{pdb_id} - Detected Ligands: {all_ligands}")

    # 对所有 ligand 进行处理
    for ligand_resname in all_ligands:
        # 创建 ligand-specific 子目录
        ligand_dir = pdb_dir / f"ligand_{ligand_resname}"
        ligand_dir.mkdir(parents=True, exist_ok=True)

        # 自动检测口袋中心和大小
        ligand = structure.select_atoms(f"resname {ligand_resname}")
        print(f"Processing {pdb_id} {smiles} {ligand_resname}")
        pocket_center = (ligand.positions.max(axis=0) + ligand.positions.min(axis=0)) / 2
        pocket_size = ligand.positions.max(axis=0) - ligand.positions.min(axis=0) + 5

        # 创建针对 SMILES 的子目录
        smiles_hash = smiles.replace("(", "").replace(")", "").replace("=", "").replace("-", "").replace("/","").replace("\\", "").replace(".", "").replace(",", "").replace(":", "")
        smiles_dir = ligand_dir / f"smiles_{smiles_hash}"
        smiles_dir.mkdir(parents=True, exist_ok=True)

        # 定义文件路径
        ligand_path = smiles_dir / "ligand.pdbqt"
        docking_out_path = smiles_dir / "ligand_docking.sdf"
        log_path = smiles_dir / "docking_log.txt"

        # 转换配体为 PDBQT 格式
        smiles_to_pdbqt(smiles, ligand_path)

        # 运行对接并保存日志
        docking_output = run_smina(ligand_path, protein_pdbqt_path, docking_out_path, pocket_center, pocket_size)
        with open(log_path, "w") as log_file:
            log_file.write(f"PDB: {pdb_id}\nSMILES: {smiles}\nLigand Resname: {ligand_resname}\n")
            log_file.write(f"Pocket Center: {pocket_center}\nPocket Size: {pocket_size}\n\nDocking Output:\n")
            log_file.write(docking_output)

        # 拆分 SDF 文件
        split_sdf_file(docking_out_path)

        # 提取对接结果并更新到 CSV
        dock_info = parse_dock_info(docking_output)
        new_row = {'pdb': pdb_id, 'ligand_resnames': ligand_resname, 'smiles': smiles, 'dock_info': dock_info}
        result_df = pd.read_csv(RESULT_CSV)
        result_df = pd.concat([result_df, pd.DataFrame([new_row])], ignore_index=True)
        # 保存更新的结果到 CSV 文件
        result_df.to_csv(RESULT_CSV, index=False)

print("Docking workflow completed successfully!")