业务场景:
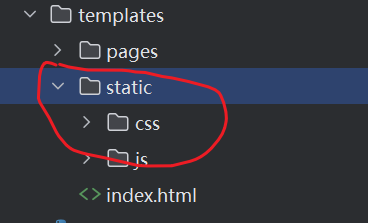
AI生成的html文件,通常会使用多个cdn资源、手动替换or下载太过麻烦、如下py程序为此而生,指定html目录自动下载并替换~
bash
import os
import requests
from bs4 import BeautifulSoup
from urllib.parse import urlparse
import hashlib

class CDNDownloader:
    def __init__(self, html_dir, static_dir='static'):
        self.html_dir = os.path.abspath(html_dir)
        self.static_dir = os.path.join(self.html_dir, static_dir)
        os.makedirs(self.static_dir, exist_ok=True)

    def process_all_html_files(self):
        """处理指定目录下的所有HTML文件"""
        for root, _, files in os.walk(self.html_dir):
            for file in files:
                if file.endswith(('.html', '.htm')):
                    file_path = os.path.join(root, file)
                    print(f"Processing {file_path}...")
                    self.process_single_html(file_path)

    def process_single_html(self, html_path):
        """处理单个HTML文件"""
        with open(html_path, 'r', encoding='utf-8') as f:
            content = f.read()

        soup = BeautifulSoup(content, 'html.parser')

        # 计算HTML文件相对于根目录的层级
        rel_path = os.path.relpath(os.path.dirname(html_path), self.html_dir)
        path_prefix = '../' * len(rel_path.split(os.sep)) if rel_path != '.' else ''

        # 处理CSS文件
        for link in soup.find_all('link', rel='stylesheet'):
            if 'href' in link.attrs:
                old_url = link['href']
                if self._is_cdn_url(old_url):
                    new_url = self.download_resource(old_url, 'css')
                    # 根据HTML文件的位置调整相对路径
                    link['href'] = f"{path_prefix}{new_url}"

        # 处理JS文件
        for script in soup.find_all('script', src=True):
            old_url = script['src']
            if self._is_cdn_url(old_url):
                new_url = self.download_resource(old_url, 'js')
                # 根据HTML文件的位置调整相对路径
                script['src'] = f"{path_prefix}{new_url}"

        # 保存修改后的HTML文件
        with open(html_path, 'w', encoding='utf-8') as f:
            f.write(str(soup))

    def _is_cdn_url(self, url):
        """判断是否为CDN URL"""
        return url.startswith(('http://', 'https://', '//'))

    def download_resource(self, url, resource_type):
        """下载资源并返回本地路径"""
        if url.startswith('//'):
            url = 'https:' + url

        try:
            response = requests.get(url, timeout=10)
            if response.status_code == 200:
                # 使用URL的最后部分作为文件名,如果没有扩展名则添加
                filename = os.path.basename(urlparse(url).path)
                if not filename:
                    # 如果URL没有文件名,使用URL的MD5作为文件名
                    filename = hashlib.md5(url.encode()).hexdigest()
                    filename = f"{filename}.{resource_type}"

                # 确保文件有正确的扩展名
                if not filename.endswith(f'.{resource_type}'):
                    filename = f"{filename}.{resource_type}"

                # 创建资源类型子目录
                resource_dir = os.path.join(self.static_dir, resource_type)
                os.makedirs(resource_dir, exist_ok=True)

                file_path = os.path.join(resource_dir, filename)
                with open(file_path, 'wb') as f:
                    f.write(response.content)

                # 返回相对于static目录的路径
                return os.path.join('static', resource_type, filename).replace('\\', '/')

        except Exception as e:
            print(f"Error downloading {url}: {str(e)}")
            return url

        return url

def process_directory(html_dir, static_dir='static'):
    """直接处理指定目录的便捷函数"""
    downloader = CDNDownloader(html_dir, static_dir)
    downloader.process_all_html_files()

def main():
    # 方式1:命令行参数
    try:
        import argparse
        parser = argparse.ArgumentParser(description='Download CDN resources from HTML files')
        parser.add_argument('html_dir', help='Directory containing HTML files')
        parser.add_argument('--static-dir', default='static', help='Directory to save downloaded resources')

        args = parser.parse_args()
        process_directory(args.html_dir, args.static_dir)

    except SystemExit:
        # 方式2:写死在代码中的路径
        html_directories = [
            "templates",  # 示例路径1
        ]

        for directory in html_directories:
            print(f"\n处理目录: {directory}")
            process_directory(directory)

    print("Done! All CDN resources have been downloaded and HTML files updated.")

if __name__ == '__main__':
    main()