CDS:gem5 中截止时间感知的多芯粒 GPU 调度器
I. 引言
向多芯粒 GPU 架构的转变,在跨分布式计算和内存资源进行任务调度方面引入了新的复杂性。此外,现代实时应用对 GPU 的低延迟执行提出了严格要求。与单芯片 GPU 不同,多芯粒设计 1--7 必须协调具有不同延迟和带宽的芯粒之间的工作,这使得现代 GPU 中使用的轮询调度 6 不足以提供实时保证。
在这项工作中,我们应用软硬件协同设计来应对这些挑战,并在未来 GPGPU 中保持性能可扩展性。现代 GPGPU 包含嵌入式 RISC 核心,称为命令处理器(CP),负责流调度和内核上下文解析。然而,当前的 CP 仅限于解析内核上下文和调度 GPU 流,将 GPU 视为一个单体单元,而不是一组芯粒。我们的核心思想是设计一个称为 CDS(跨芯粒调度器)的两级 GPU 调度器,在满足截止时间的同时协调跨芯粒的工作。我们通过增强 CP 来实现 CDS:由于 CP 与 GPU 共置,CP 可以访问细粒度、微秒级的运行时数据,同时保持跨芯粒的全局视图。
我们的调度器根据松弛度 8, 9 对待处理作业进行优先级排序,并使用基于可用资源的最差适配策略选择用于内核分派的芯粒。我们还引入下一内核预取,以消除同一流中连续内核之间的通信延迟。这项工作的一个关键贡献是增强本地和全局 CP 的能力,通过监控芯粒级计算资源和工作负载特征来智能调度内核。
II. 平台与接口
我们扩展 gem5 v21.0 以支持本地和全局 CP,并集成 CDS。实时调度需要知道截止时间。gem5 v21.0 支持 ROCm 1.6,我们修改 HIP 接口以支持每流截止时间。ROCm 将它们传递给模拟器,模拟器将其存储在表中以供调度。
III. 方法
我们调度器的关键指标是:
- 完成率:内核在截止时间之前完成的比例;
- 响应时间:内核提交后完成所需的时间;
- 芯粒利用率。
我们将 CDS 与当前 GPU 中使用的轮询策略进行比较。
我们在一组单内核和多内核工作负载 10--12 上进行评估。我们最初用一批作业填充系统,然后以受控的到达间隔(称为到达延迟)周期性提交后续批次。我们将到达率下的工作负载行为分为不同区域。我们通过将每个作业的独立运行时间按一个可调因子缩放来为每个作业分配截止时间,并在评估过程中逐步放宽该因子,直到调度器在某个区域内对稳态作业达到 100% 的按时完成率。
这些区域反映了系统争用水平以及调度器满足截止时间的相应难度。我们使用 t 检验对结果进行分类,当响应时间分布随时间变化时识别较高的到达率,当响应时间分布保持稳定时识别较低的到达率。该评估方法建立了一个稳健的框架,用于评估不同场景下的调度器,也是这项工作的一项关键贡献。
IV. 结果
图 1 显示了中等区域在到达率为 48 jobs/ms 时的稳态完成率。CDS 达到 100% 完成率,而轮询调度仅对 78% 的作业满足截止时间,GMM 评分的平均每作业截止时间为 1.4 ms。轮询调度在 1.6 ms 截止时间下达到 100% 完成。这表明,与轮询调度相比,CDS 可以处理紧得多的截止时间,同时实现接近理想的完成率。未来,我们旨在重新设计 CP 的队列调度器,使 CDS 能够动态适应变化的 GPU 条件,同时有效考虑局部性。
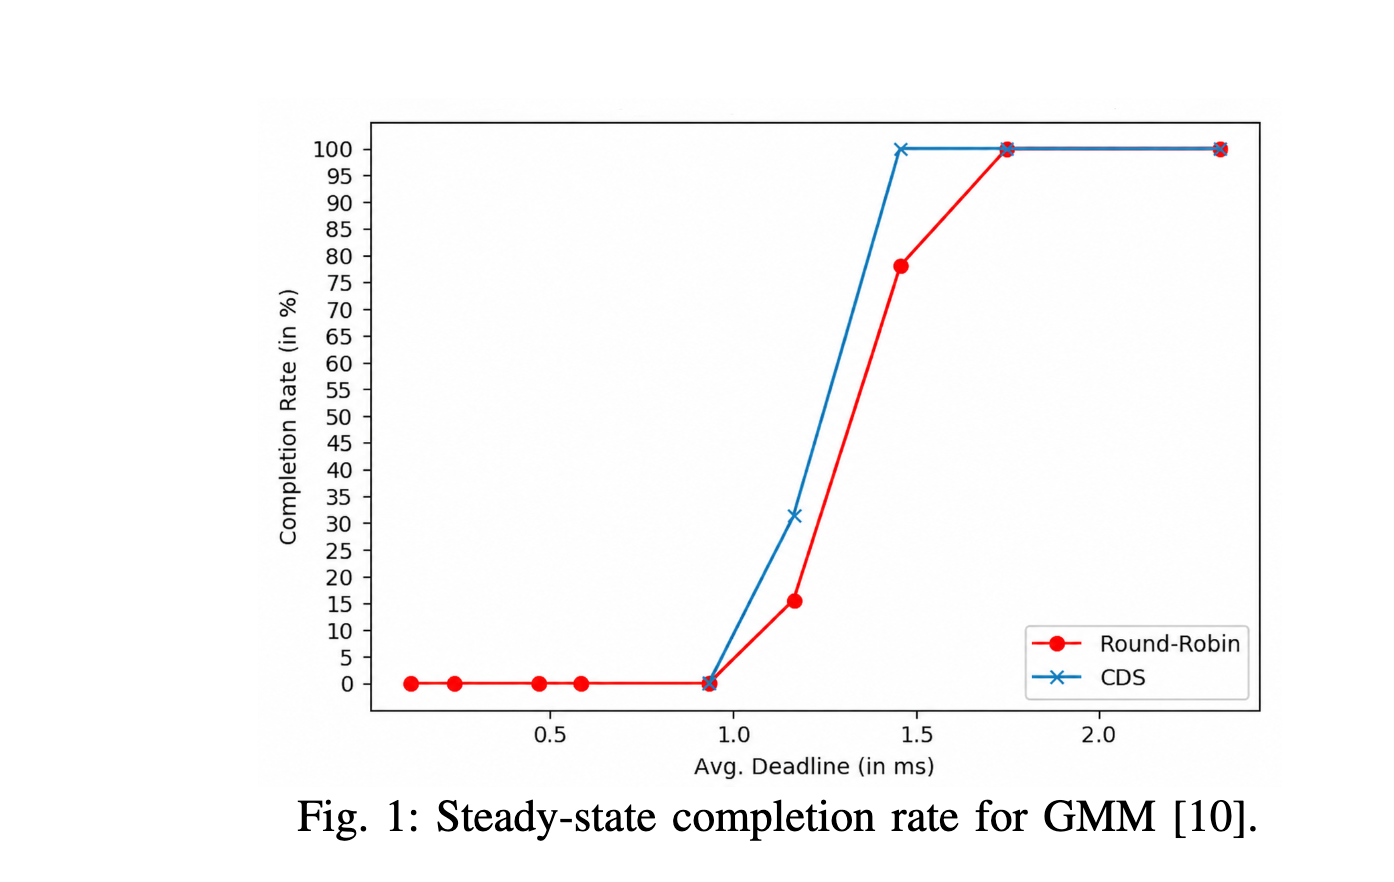
图 1:GMM 10 的稳态完成率。
图例:Round-Robin(轮询)、CDS。
横轴:平均截止时间(ms);纵轴:完成率(%)。
V. 结论
评估调度器很困难,尤其是在紧迫的截止时间或高争用下。随着工作负载变得越来越复杂,我们需要稳健、高效且低开销的策略。在这项工作中,我们介绍了我们提出的用于可靠满足实时保证的算法,概述了用于在不同场景下测试调度器的评估方法,并展示了跨一系列工作负载的结果。
致谢
本工作部分得到美国国家科学基金会 CAREER-2238608 资助的支持。
参考文献
以下条目保留原文,以便检索。
1 A. Arunkumar, E. Bolotin, B. Cho, U. Milic, E. Ebrahimi, O. Villa, A. Jaleel, C.-J. Wu, and D. Nellans, "MCM-GPU: Multi-Chip-Module GPUs for Continued Performance Scalability," in Proceedings of the 44th Annual International Symposium on Computer Architecture, ser. ISCA. New York, NY, USA: ACM, 2017, pp. 320--332. Online. Available: http://doi.acm.org/10.1145/3079856.3080231
2 A. Arunkumar, E. Bolotin, D. Nellans, and C.-J. Wu, "Understanding the Future of Energy Efficiency in Multi-Module GPUs," in 25th IEEE International Symposium on High Performance Computer Architecture, ser. HPCA. Piscataway, NJ, USA: IEEE Press, 2019, pp. 519--532.
3 P. Dalmia, R. Shashi Kumar, and M. D. Sinclair, "CPEIDE: Efficient Multi-Chiplet GPU Implicit Synchronization," in Proceedings of 57th IEEE/ACM International Symposium on Microarchitecture, ser. MICRO. Los Alamitos, CA, USA: IEEE Computer Society, 2024.
4 M. Khairy, V. Nikiforov, D. Nellans, and T. G. Rogers, "Locality-Centric Data and Threadblock Management for Massive GPUs," in 53rd Annual IEEE/ACM International Symposium on Microarchitecture, ser. MICRO. Washington, DC, USA: IEEE Computer Society, 2020, pp. 1022--1036.
5 G. H. Loh, M. J. Schulte, M. Ignatowski, V. Adhinarayanan, S. Aga, D. Aguren, V. Agrawal, A. M. Aji, J. Alsop, P. Bauman, B. M. Beckmann, M. V. Beigi, S. Blagodurov, T. Boraten, M. Boyer, W. C. Brantley, N. Chalmers, S. Chen, K. Cheng, M. L. Chu, D. Cownie, N. Curtis, J. Del Pino, N. Duong, A. Duundefinendu, Y. Eckert, C. Erb, C. Freitag, J. L. Greathouse, S. Gurumurthi, A. Gutierrez, K. Hamidouche, S. Hossamani, W. Huang, M. Islam, N. Jayasena, J. Kalamatianos, O. Kayiran, J. Kotra, A. Lee, D. Lowell, N. Madan, A. Majumdar, N. Malaya, S. Manne, S. Mashimo, D. McDougall, E. Mednick, M. Mishkin, M. Nutter, I. Paul, M. Poremba, B. Potter, K. Punniyamurthy, S. Puthoor, S. E. Raasch, K. Rao, G. Rodgers, M. Serbak, M. Seyedzadeh, J. Slice, V. Sridharan, R. van Oostrum, E. van Tassell, A. Vishnu, S. Wasmundt, M. Wilkening, N. Wolfe, M. Wyse, A. Valavarti, and D. Yudanov, "A Research Retrospective on AMD's Exascale Computing Journey," in Proceedings of the 50th Annual International Symposium on Computer Architecture, ser. ISCA. New York, NY, USA: Association for Computing Machinery, 2023. Online. Available: https://doi.org/10.1145/3579371.3589349
6 M. Osama, R. Swann, K. Sangaiah, S. Singh, G. Dasika, and R. Bhardwaj, "Deep dive into the MI300 compute and memory partition modes," https://rocm.blogs.amd.com/software-tools-optimization/compute-memory-modes/README.html, Feb 2025.
7 A. Smith, G. H. Loh, M. J. Schulte, M. Ignatowski, S. Naffziger, M. Mantor, N. Kalyanasundaram, V. Alla, N. Malaya, J. L. Greathouse, E. Chapman, and R. Swaminathan, "Realizing the AMD Exascale Heterogeneous Processor Vision: Industry Product," in 51st ACM/IEEE Annual International Symposium on Computer Architecture, ser. ISCA. Piscataway, NJ, USA: IEEE, 2024, pp. 876--889. Online. Available: https://doi.org/10.1109/ISCA59077.2024.00068
8 M. Cirinei and T. P. Baker, "EDZL scheduling analysis," in 19th Euromicro Conference on Real-Time Systems (ECRTS'07), July 2007, pp. 9--18.
9 T. T. Yeh, M. D. Sinclair, B. M. Beckmann, and T. G. Rogers, "Deadline-Aware Offloading for High-Throughput Accelerators," in 27th IEEE International Symposium on High Performance Computer Architecture, ser. HPCA. Washington, DC, USA: IEEE Computer Society, 2021, pp. 479--492.
10 J. Hauswald, M. A. Laurenzano, Y. Zhang, C. Li, A. Rovinski, A. Khurana, R. G. Dreslinski, T. Mudge, V. Petrucci, L. Tang, and J. Mars, "Sirius: An Open End-to-End Voice and Vision Personal Assistant and Its Implications for Future Warehouse Scale Computers," in Proceedings of the Twentieth International Conference on Architectural Support for Programming Languages and Operating Systems, ser. ASPLOS. New York, NY, USA: ACM, 2015, pp. 223--238. Online. Available: http://doi.acm.org/10.1145/2694344.2694347
11 S. Narang, "DeepBench," https://github.com/baidu-research/DeepBench, 2016.
12 S. Narang and G. Diamos, "An update to DeepBench with a focus on deep learning inference," https://svail.github.io/DeepBench-update/, 2017.