FastAPI 作为H5中流式输出的后端
最近大家都在玩LLM,我也凑了热闹,简单实现了一个本地LLM应用,分享给大家,百分百可以用哦~^ - ^
先介绍下我使用的三种工具:
Ollama:一个免费的开源框架,可以让大模型很容易的运行在本地电脑上
FastAPI:是一个用于构建 API 的现代、快速(高性能)的 web 框架,使用 Python 并基于标准的 Python 类型提示
React:通过组件来构建用户界面的库
简单来说就类似于LLM(数据库)+FastAPI(服务端)+React(前端)
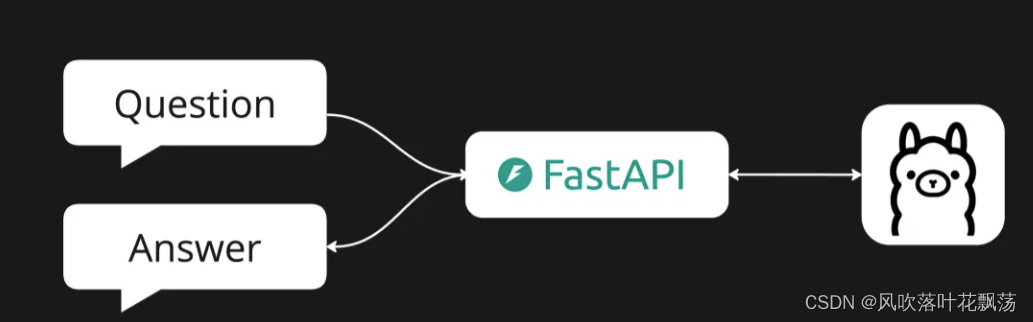
前端:
html
<!DOCTYPE html>
<html lang="en">
<head>
    <meta charset="UTF-8">
    <meta name="viewport" content="width=device-width, initial-scale=1.0">
    <title>SSE Demo with Fetch</title>
    <style>
        #events {
            height: 200px;
            border: 1px solid #ccc;
            padding: 5px;
            overflow-y: scroll;
            white-space: pre-wrap; /* 保留空格和换行 */
        }

    </style>
    <script src="./js/jquery-3.1.1.min.js"></script>
</head>
<body>

<h1>Server-Sent Events Test</h1>
<button id="start">Start Listening</button>
<label for="" >apiUrl</label>
<input type="text" name="" id="url" value="http://127.0.0.1:8563/llm_stream" >
<br>
<label> 返回内容</label>
<br>
<input type="text" name="" id="userText" value="" >
<br>
<input type="textarea" name="" id="outtext_talk" value="" style="width:400px; height: 200px;"></textarea>
<div id="events"></div>

<script>
    $("#start").click(async function() {
        console.log($("#userText").val());
        let text=$("#userText").val().trim();
        if(text==''){
            alert("用户输入不为空");
            return 0;
        }
const data={
    content:text,
    model:"gpt-3.5-turbo",
    stream:true
}

$("#outtext_talk").val('')

    const res= await fetch($('#url').val(),{
            method:"POST",
            body:JSON.stringify(data),
            headers: {
  "Content-Type": "application/json",
  }
});
        const reader=res.body?.pipeThrough(new TextDecoderStream()).getReader();
        let count=0
        const textDecoder = new TextDecoder();

        while (count<10){
            let {done,value} = await reader.read()
            if (done) {
console.log("***********************done");

break;
            }

            let parts = value.split('\r\n\r\n'); // 根据 SSE 的数据格式分割
            // 处理所有完整的消息
            console.log(parts);
            try{
                parts.slice(0,-1).forEach(part =>{

                    console.log(part);
                if(part.startsWith('data:')){
                    const data=part.replace('data:','')
                    aiText=JSON.parse(data)
                    $('#outtext_talk').val( $('#outtext_talk').val()+aiText.message)
                }

            })

            }catch(error){
                console.error("JSON解析出错",detext);
        count+=1;
            }


                }

    });
</script>

</body>
</html>
后端:
python
# -*- coding:utf-8 -*-
"""
@Author: 风吹落叶
@Contact: waitKey1@outlook.com
@Version: 1.0
@Date: 2024/6/11 22:51
@Describe:
"""
import asyncio
import json

from fastapi import FastAPI, Response
from fastapi.responses import StreamingResponse
import time
import uvicorn
from fastapi.middleware.cors import CORSMiddleware
from pydantic import BaseModel

import openai
import os
import os
from openai import OpenAI


def openai_reply(content,model="gpt-3.5-turbo"):
    client = OpenAI(
        # This is the default and can be omitted
        api_key='sk-S7KwoLDoAzi5kwOs3b3e27A66e72E6',
        base_url='https://kksj.zeabur.app/v1'
    )

    chat_completion = client.chat.completions.create(
        messages=[
            {
                "role": "user",
                "content": content,
            }
        ],
        model=model,
    )
    # print(chat_completion)
    return chat_completion.choices[0].message.content


app = FastAPI()
# 启用CORS支持
app.add_middleware(
    CORSMiddleware,
    allow_origins=["*"],
    allow_credentials=True,
    allow_methods=["*"], # 或者只列出 ["POST", "GET", "OPTIONS", ...] 等
    allow_headers=["*"],
)

class Req(BaseModel):
    text:str
    stream:bool

def event_stream(reqs):
    for _ in range(10):  # 演示用,发送10次消息后关闭连接
        yield json.dumps({'text':f"data: Server time is {time.ctime()} s {reqs.text[:2]}"})
        time.sleep(1)

@app.post("/events")
async def get_events(reqs:Req):
    return StreamingResponse(event_stream(reqs), media_type="application/json")


class LLMReq(BaseModel):
    content:str
    model:str
    stream:bool

def openai_stream(content,model='gpt-3.5-turbo'):
    client = OpenAI(
        # This is the default and can be omitted
        api_key='sk-S7KwoLDoAzi5kwOs3b3e27A64eD6e72E6',
        base_url='https://kksj.zeabur.app/v1'
    )
    stream = client.chat.completions.create(
        messages=[
            {
                "role": "user",
                "content": content,
            }
        ],  # 记忆
        model=model,
        stream=True,
    )
    return stream


from starlette.requests import Request
from sse_starlette import EventSourceResponse
@app.post("/llm_stream")
async def flush_stream(req: LLMReq):
    async def event_generator(req: LLMReq):
        stream = openai_stream(req.content, req.model)
        for chunk in stream:
            if chunk.choices[0].delta.content is not None:
                word=chunk.choices[0].delta.content
                yield json.dumps({"message": word}, ensure_ascii=False)
                await asyncio.sleep(0.001)


    return EventSourceResponse(event_generator(req))


if __name__ == '__main__':
    uvicorn.run(app,port=8563)