1、结构化输出概述
1.1 什么是结构化输出
LangChain的结构化输出(Structured Output) 指的是:
要求模型最终返回一个符合预定义结构的数据对象,例如固定字段的JSON、Pydantic 模型、 TypedDict,而不再是无格式的自然语言文本。
它的核心目标是把" 自然语言回答 "变成" 程序可以稳定消费的数据 "。
例如,不是让模型输出:
盗梦空间在2010年上映,导演是克里斯托弗·诺兰,评分9.3。
而是让它输出成类似这样的结构
{
    "title": "盗梦空间",
    "year": 2010,
    "director": "克里斯托弗·诺兰",
    "rating": 9.3
}
这样做的价值主要有三点:
- 更容易被代码处理:下游系统可以直接读字段,而不是再从自然语言里做解析。
- 结果更稳定:减少"模型说法变了但意思差不多"导致的解析失败。
- 更适合工程化:适用于表单抽取、分类、路由、调用工具参数生成、工作流状态传递等场景。
1.2 传统方式 vs 结构化输出
1、传统的几种方式(繁琐、不推荐)
# 1. 提示词要求JSON
prompt = "以JSON格式返回:{name, age, occupation}"
response = model.invoke(prompt)

# 2. 手动解析
import json
data = json.loads(response.content)

# 3. 手动验证类型
if not isinstance(data['age'], int):
    raise ValueError("age must be int")

# 4. 手动创建对象
person = Person(**data)
2、结构化输出(简洁)
# 一步到位
structured_llm = model.with_structured_output(Person)
person = structured_llm.invoke("张三是一名 30 岁的软件工程师")
# ✅ 自动解析、验证、创建对象
为什么第2种结构化输出机制这么受欢迎?
在没有 Pydantic 等结构化方案之前,开发者需要写大量的 Prompt 苦口婆心地求大模型"请返回 JSON, 不要带任何解释",然后自己写繁琐的 json.loads() 和 try...except 。
而有了 Pydantic 等结构化方案结合 .with_structured_output() 之后:
- Prompt 变干净了: 字段的 description 直接充当了 Prompt 的一部分。
- 类型安全: 编辑器能自动补全,代码运行前就能做类型检查。
- 极其稳定: 依托大模型厂商底层的 JSON 模式,输出错误率降到了极低。
1.3 结构化输出模式
目前LangChain 1.x 支持多种Schema与结构化输出方式:
- Pydantic(字段校验、描述、嵌套结构,功能最丰富)
- TypedDict(轻量类型约束)
- JSON Schema(与前后端/跨语言接口最通用)
- dataclass
模型对象可以调用 with_structured_output() 绑定输出模式(schema)。
只有 Pydantic 返回的是Schema类实例,其余三种方式返回的都是 字典 ;也只有 Pydantic 在类型不 匹配时会抛出异常。
问题:现在所有模型都支持"本章要讲解的结构化输出方式"吗?
大部分现代模型支持(通过函数调用):
- ✅ OpenAI (gpt-4, gpt-3.5-turbo)
- ✅ Anthropic (claude-3)
- ✅ Groq (llama-3)
- ❌ 某些旧模型不支持 如果不支持,LangChain 会回退到提示词 + JSON 解析
2、四种模式的使用
2.1 模式1:Pydantic
它通过在运行时强制执行类型提示,确保数据的正确性和一致性,是 生产场景首选 。
2.1.1 基本使用
需要满足的几个要素:
- 所有结构化输出的数据模型都必须继承 BaseModel
- 使用 类型提示 。Pydantic 支持丰富的字段类型:str 、int、float、Listxxx、Optionalxxx等
- 使用 Field() 添加字段默认值和描述,帮助 LLM 理解字段含义
举例1:
1)大模型的初始化
from  langchain_community.chat_models import ChatTongyi
from dotenv import load_dotenv


load_dotenv()

# api_key 与 api_base 会自动获取 .env下的 DASHSCOPE_API_KEY
model = ChatTongyi(
    model = 'qwen3.7-max',

)
2)定义 Pydantic 模型
使用清晰的字段描述;没有描述,LLM 可能格式错误
from pydantic import BaseModel, Field
class Person(BaseModel):
    """人物信息"""
    name: str = Field(description="姓名")
    age: int = Field(description="年龄")
    occupation: str = Field(description="职业")
LangChain 会要求 LLM 的输出必须能填充这些字段。
3)使用 with_structured_output 即可引导模型进行结构化输出:
response = model.invoke("张三是一名30岁的软件工程师")
# 创建结构化输出的
structured_llm = model.with_structured_output(Person)
# 调用
result = structured_llm.invoke("张三是一名 30 岁的软件工程师")
print(result)
print(type(result))
# result 是 Person 实例
print(result.name) # "张三"
print(result.age) # 30
print(result.occupation) # "软件工程师"
说明:没有描述,LLM 可能格式错误。
name='张三' age=30 occupation='软件工程师'
<class '__main__.Person'>
张三
30
软件工程师
举例2:
from pydantic import BaseModel, Field


# 定义输出结构
class SentimentAnalysis(BaseModel):
    """情感分析结果"""

    sentiment: str = Field(
        description="情感倾向:positive/negative/neutral"
    )
    confidence: float = Field(
        description="置信度,0-1之间"
    )
    keywords: list[str] = Field(
        description="关键词列表"
    )


# 创建结构化输出模型
structured_model = model.with_structured_output(SentimentAnalysis)

# 待分析文本
text = "这个课程内容很实用,学到了很多知识,强烈推荐!"

# 调用模型
result = structured_model.invoke(
    f"分析以下文本的情感:\n{text}"
)

# 输出结果
print(f"类型: {type(result)}")
print(f"情感: {result.sentiment}")
print(f"置信度: {result.confidence}")
print(f"关键词: {result.keywords}")

类型: <class '__main__.SentimentAnalysis'>
情感: positive
置信度: 0.95
关键词: ['实用', '学到了很多', '强烈推荐', '课程', '知识']
2.1.2 高级特性
情况1:可选字段 「Optional」
问题:LLM 未填充某些字段怎么办?
使用 Optional 指定字段为可选的
举例:
from typing import Optional
from pydantic import BaseModel, Field
class Person(BaseModel):
    """人物信息"""
    name: str = Field(description="姓名")
    age: Optional[str] = Field(description="年龄")
    occupation: str = Field(description="职业")

structured_llm = model.with_structured_output(Person)
structured_llm.invoke("张三是一名医生")
Person(name='张三', age='未知', occupation='医生')
情况2:默认值 「default」
LLM 未提供的信息会使用默认值。格式如下:
Field(default="默认值", description="描述")
注意:不同模型提供商对default字段的支持是不同的。
from pydantic import BaseModel, Field

class Person(BaseModel):
    """人物信息"""
    name: str = Field(description="姓名")
    age: int = Field(1, description="年龄")
    occupation: str = Field(description="职业")

structured_llm = model.with_structured_output(Person)
structured_llm.invoke("张三是一名医生")
Person(name='张三', age=1, occupation='医生')
举例2:
class Config(BaseModel):
    timeout: Optional[int] = Field(30,description="超时时间(单位秒)")
    retry: bool = Field(False,description="是否支持重试")
    max_attempts: int = Field(6,description="最大重试次数")
# 测试
structured_llm = model.with_structured_output(Config)
structured_llm.invoke("配置要求:支持重试,最多重试5次")
Config(timeout=30, retry=True, max_attempts=5)
举例3:
from typing import Optional
from pydantic import BaseModel, Field

# 假设你已经定义了 model_with_openrouter
# from your_module import model_with_openrouter

class Product(BaseModel):
    """产品信息"""
    name: str = Field(description="产品名称")
    price: float = Field(description="价格")
    description: Optional[str] = Field(description="产品描述")
    stock: int = Field(default=100, description="库存")

# 测试
structured_llm = model.with_structured_output(Product)

print("\n场景1:完整信息")
result1 = structured_llm.invoke("iPhone 15 售价 5999 元,最新款智能手机,库存50台")
print(result1)

print("\n场景2:缺少描述和库存")
result2 = structured_llm.invoke("MacBook Pro 售价 12999 元")
print(result2)
场景1:完整信息
name='iPhone 15' price=5999.0 description='最新款智能手机' stock=50
场景2:缺少描述和库存
name='MacBook Pro' price=12999.0 description=None stock=100
情况3:枚举类型 「Literal」
问题:如何限制字段的可选值? 回答:使用枚举
from enum import Enum
from typing import Optional
from pydantic import BaseModel, Field

# 定义你的优先级枚举类
class Priority(str, Enum):
    LOW = "低"
    MEDIUM = "中"
    HIGH = "高"

class CustomerInfo(BaseModel):
    """客户信息"""
    name: str = Field(description="客户姓名")
    phone: str = Field(description="电话号码")
    email: Optional[str] = Field(description="邮箱")
    issue: str = Field(description="问题描述")
    urgency: Priority = Field(description="紧急程度")

# 测试
structured_llm = model.with_structured_output(CustomerInfo)

conversation = """
客服: 您好,请问有什么可以帮助您?
客户: 我是王小明,电话 138-1234-5678,我的订单一直没发货,很着急!
客服: 好的,我帮您查一下
"""

result = structured_llm.invoke(f"从以下客服对话中提取客户信息:\n{conversation}")
print(result)
print("\n提取结果:")
print(f" 客户: {result.name}")
print(f" 电话: {result.phone}")
print(f" 邮箱: {result.email or '未提供'}")
print(f" 问题: {result.issue}")
print(f" 紧急程度: {result.urgency.value}")
如果嫌单独定义一个 Enum 类太麻烦,也可以直接导入 typing 中的 Literal ,直接在字段里把允许 的值写死。
from typing import Optional,Literal
from pydantic import BaseModel, Field


class CustomerInfo(BaseModel):
    """客户信息"""
    name: str = Field(description="客户姓名")
    phone: str = Field(description="电话号码")
    email: Optional[str] = Field(description="邮箱")
    issue: str = Field(description="问题描述")
    urgency: Literal["低","中","高"] = Field(description="紧急程度")

# 测试
structured_llm = model.with_structured_output(CustomerInfo)

conversation = """
客服: 您好,请问有什么可以帮助您?
客户: 我是王小明,电话 138-1234-5678,我的订单一直没发货,很着急!
客服: 好的,我帮您查一下
"""

result = structured_llm.invoke(f"从以下客服对话中提取客户信息:\n{conversation}")
print(result)
print("\n提取结果:")
print(f" 客户: {result.name}")
print(f" 电话: {result.phone}")
print(f" 邮箱: {result.email or '未提供'}")
print(f" 问题: {result.issue}")
print(f" 紧急程度: {result.urgency}")
应用场景:
- 自动填充 CRM 系统
- 工单自动分类
- 客服辅助
情况4:列表提取 「List」
from typing import List
from pydantic import BaseModel, Field
class Person(BaseModel):
    """人物信息"""
    name:str = Field(description="姓名")
    age:int =Field(description="年龄")

class PersonList(Person):
    people:List[Person]

structured_llm = model.with_structured_output(PersonList)
result = structured_llm.invoke("张三 30岁,李四 25岁")
print(result)
name='张三' age=30 people=Person(name='张三', age=30), Person(name='李四', age=25)
举例2:产品评论分析
class Review(BaseModel):
    """产品评论"""
    product: str
    rating: int = Field(description="评分 1-5")
    pros: List[str] = Field(description="优点列表")
    cons: List[str] = Field(description="缺点列表")
structured_llm = model.with_structured_output(Review)
review = structured_llm.invoke("""
    iPhone 17 很棒!摄像头强大,手感好。但是价格贵,没有充电器。4分。
    """)
print(review)
应用场景: 批量处理用户评论, 自动生成分析报告 ,发现产品改进点
举例3:文档信息提取
from typing import List
from pydantic import BaseModel, Field


class Invoice(BaseModel):
    """发票信息"""

    invoice_number: str = Field(description="发票号")
    date: str = Field(description="日期")
    total_amount: float = Field(description="总金额")
    items: List[str] = Field(description="商品")


# 测试
structured_llm = model.with_structured_output(Invoice)

invoice_text = """
发票号: INV-2024-001
日期: 2024-01-15
总金额: 1299.00
商品: MacBook Pro, AppleCare+
"""

invoice = structured_llm.invoke(f"提取发票信息:{invoice_text}")
print(invoice)
invoice_number='INV-2024-001' date='2024-01-15' total_amount=1299.0 items='MacBook Pro', 'AppleCare+'
应用场景: 自动化财务处理, OCR 后结构化, 数据录入
情况5:嵌套结构
from pydantic import BaseModel, Field

class Address(BaseModel):
    """地点描述"""
    city:str = Field(description="城市")
    district:str =Field(description="区域")

class Company(BaseModel):
    name:str =Field(description="公司名称")
    address:Address = Field(description="公司所在地")

structured_model = model.with_structured_output(Company)
response= structured_model.invoke("阿里巴巴在杭州的滨江区")
print(response)
name='阿里巴巴' address=Address(city='杭州', district='滨江区')
举例2:
from typing import List
from pydantic import BaseModel, Field

# 1. 定义嵌套的 Pydantic 模型
class Actor(BaseModel):
    """演员信息"""

    name: str = Field(description="演员姓名")
    role: str = Field(description="饰演的角色")


class Movie(BaseModel):
    """电影信息"""

    title: str = Field(description="电影标题")
    year: int = Field(description="上映年份")
    director: str = Field(description="导演")
    cast: List[Actor] = Field(description="演员列表")
    rating: float = Field(description="评分")


# 2. 初始化模型并绑定输出结构
structured_model = model.with_structured_output(Movie)

# 3. 调用模型,直接获取 Movie 实例
response = structured_model.invoke("请介绍电影《盗梦空间》")

# 4. 访问结构化数据
print(f"电影名: {response.title}")
print(f"上映年份: {response.year}")
print(f"导演: {response.director}")
print(f"演员列表: {response.cast}")
print(f"评分: {response.rating}")
上代码输出结果如下
电影名: 盗梦空间
上映年份: 2010
导演: 克里斯托弗·诺兰
演员列表: Actor(name='莱昂纳多·迪卡普里奥', role='柯布 (Cobb)'), Actor(name='约瑟夫·高登-莱维特', role='亚瑟 (Arthur)'), Actor(name='艾伦·佩吉', role='阿丽阿德妮 (Ariadne)'), Actor(name='汤姆·哈迪', role='伊姆斯 (Eames)'), Actor(name='渡边谦', role='斋藤 (Saito)'), Actor(name='玛丽昂·歌迪亚', role='梅尔 (Mal)')
评分: 9.3
说明:LLM 能力有限,复杂嵌套结构可能会出错。所以建议:
- 嵌套层级 ≤ 3 层
- 使用清晰的 description
- 必要时拆分成多个调用
举例3:
from typing import List
from pydantic import BaseModel, Field


# 评论维度
class Aspect(BaseModel):
    """评论维度"""

    name: str = Field(description="维度名称,如:质量、价格、服务")
    score: int = Field(description="评分,1-5")
    comment: str = Field(description="具体评价")


# 产品评论分析
class ProductReview(BaseModel):
    """产品评论分析"""

    overall_sentiment: str = Field(
        description="整体情感:positive / negative / neutral"
    )
    overall_score: int = Field(description="综合评分,1-5")
    aspects: List[Aspect] = Field(description="各维度评价")
    summary: str = Field(description="一句话总结")


# 创建结构化模型
structured_model = model.with_structured_output(ProductReview)

# 测试评论
review_text = """
这款笔记本电脑性能非常强大,运行大型软件毫无压力。
屏幕色彩鲜艳,看视频很舒服。
不过价格有点贵,而且风扇噪音较大。
客服态度很好,物流也快。
总体来说还是值得购买的。
"""

# 调用模型
result = structured_model.invoke(
    f"分析以下产品评论:\n{review_text}"
)

# 输出结果
print(f"整体情感: {result.overall_sentiment}")
print(f"综合评分: {result.overall_score}/5")

print("\n各维度评价:")
for aspect in result.aspects:
    print(f" - {aspect.name}: {aspect.score}/5 - {aspect.comment}")

print(f"\n总结:{result.summary}")
整体情感: positive
综合评分: 4/5
各维度评价:
性能: 5/5 - 性能非常强大,运行大型软件毫无压力
屏幕: 5/5 - 色彩鲜艳,看视频很舒服
价格: 3/5 - 价格有点贵,性价比一般
噪音: 2/5 - 风扇噪音较大,影响使用体验
服务: 5/5 - 客服态度很好,令人满意
物流: 5/5 - 物流速度快,配送及时
总结:性能和屏幕表现出色,服务与物流令人满意,但价格偏高且风扇噪音较大,总体仍值得购买。
情况6:限制条件
举例1:
from pydantic import BaseModel, Field
class User(BaseModel):
    name:str = Field(description="姓名",min_length=2,max_length=50)
    age:int =Field(description='年龄',le=150)
    email:str=Field(description="邮箱")


try:
    # user1=User(name="张三", age=20, email="张三@qq.com")
    user2=User(name="张三", age=200, email="张三@qq.com")
    # print(user1)
    print(user2)
except ValueError as e:
    print(f"[FAIL] 验证失败(符合预期): {e.errors()[0]['msg']}")
FAIL 验证失败(符合预期): Input should be less than or equal to 150
举例2:
from pydantic import BaseModel, Field


class Product(BaseModel):
    """产品信息(严格验证)"""

    name: str = Field(
        description="产品名称(字符串类型)",
        min_length=2,
    )
    price: float = Field(
        description="价格,数字类型",
        gt=0,  # 必须大于 0
    )
    stock: int = Field(
        description="库存,整数类型",
        ge=0,  # 必须大于等于 0
    )


# 创建结构化模型
structured_llm = model.with_structured_output(Product)

# 正常数据
# response = structured_llm.invoke(
#     "华为 Mate 80 Pro Max,价格是7999,当前库存100"
# )

# 非法数据
response = structured_llm.invoke(
    "华为 Mate 80 Pro Max,价格是-7999,当前库存-100"
)

print(response)
None
2.1.3 工作流程图解
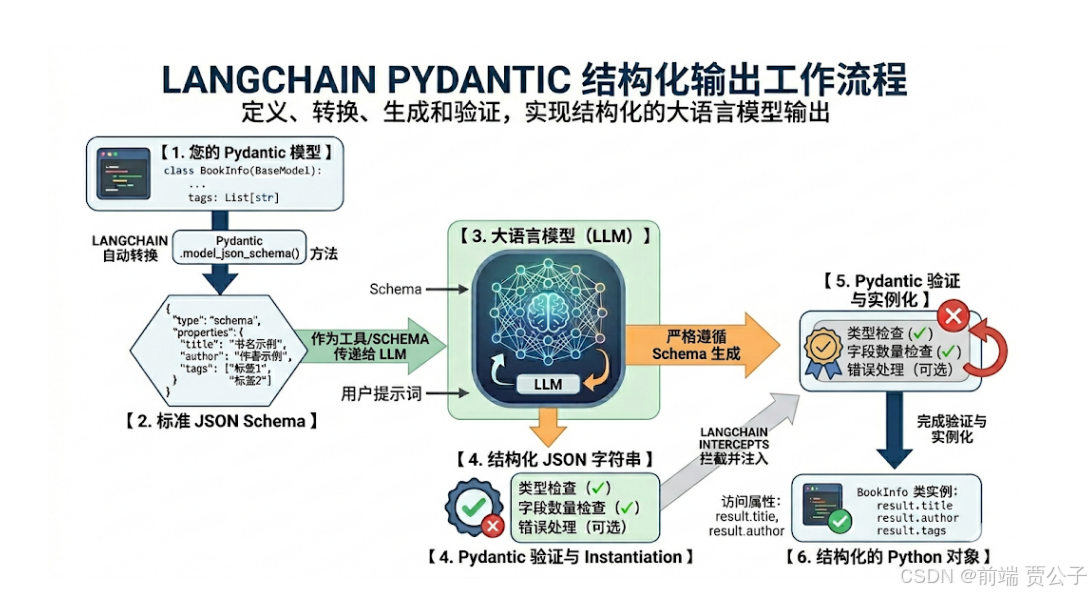
第1步:定义结构
比如:
from pydantic import BaseModel, Field
class Person(BaseModel):
    """人物信息"""
    name: str = Field(description="姓名")
    age: int = Field(description="年龄")
    occupation: str = Field(description="职业")
第2步:协议转换 LangChain
内部会调用 Pydantic 的底层方法(如 model_json_schema() ),将你写的 Python 代码自 动转换成标准的 JSON Schema。
这个 JSON Schema 是一段严格的 JSON 文本,详细描述了有哪些字段、字段类型是什么( string , array 等)以及字段的描述( description )。
第3步:模型交互与强约束
LangChain 会将这个 JSON Schema 包装进给大模型的 API 请求中。
现代方法( .with_structured_output ): 现代大模型(如 OpenAI、Anthropic、Gemini 等)普 遍支持"函数调用/工具调用(Function/Tool Calling)"或"JSON Mode"。LangChain 会把 JSON Schema 作为 Tools 传入。
大模型侧的约束: 像 OpenAI 的 strict=True 参数,会启动模型的语法采样约束(Grammarbased sampling)。大模型在解码生成 token 时,不是瞎猜,而是严格按照 JSON Schema 的语 法树进行选择,从而在模型底层级保证了输出格式绝不走样。
第4步:自动解析与验证
当大模型返回符合 JSON 规范的字符串后,LangChain 的 PydanticStructuredOutputParser (解析 器)会接管工作:
-
解析(Parsing): 将字符串解析为 Python 字典。
-
验证(Validation): 将字典喂给你的 Pydantic 模型。Pydantic 会自动检查数据类型是否正确。 如果模型漏掉了必填字段,或者类型错误,这里会直接抛出验证错误(或者触发 LangChain 的重 试机制)。
-
返回(Return): 如果通过验证,你拿到的不再是冷冰冰的字符串,而是一个直接可以点出属性 的 Python Pydantic 对象(例如 result.title )。