- 🍨 本文为🔗365天深度学习训练营 中的学习记录博客
- 🍖 原作者:K同学啊
文章目录
- [1. 简介](#1. 简介)
- [2. 环境](#2. 环境)
- [3. 代码实现](#3. 代码实现)
-
- [3.1 前期准备](#3.1 前期准备)
-
- [3.1.1 设置 GPU & 导入库](#3.1.1 设置 GPU & 导入库)
- [3.1.2 可视化样本图片](#3.1.2 可视化样本图片)
- [3.1.3 数据加载与预处理](#3.1.3 数据加载与预处理)
- [3.1.4 类别映射](#3.1.4 类别映射)
- [3.1.5 分组划分与训练集均衡](#3.1.5 分组划分与训练集均衡)
- [3.1.6 构建 DataLoader](#3.1.6 构建 DataLoader)
- [3.2 模型建立与训练](#3.2 模型建立与训练)
-
- [3.2.1 定义 ResNeXt 网络模型](#3.2.1 定义 ResNeXt 网络模型)
- [3.2.2 模型结构概览](#3.2.2 模型结构概览)
- [3.2.3 定义训练和测试函数](#3.2.3 定义训练和测试函数)
- [3.2.4 训练模型](#3.2.4 训练模型)
- [4. 模型评估](#4. 模型评估)
-
- [4.1 可视化训练过程](#4.1 可视化训练过程)
- [4.2 加载最优模型并评估](#4.2 加载最优模型并评估)
- [5. 总结](#5. 总结)
1. 简介
| 项目 | 内容 |
|---|---|
| 模型 | ResNeXt50(layers=3,4,6,3,cardinality=32,base_width=4) |
| 任务 | 三分类图像分类(Normal / Mild / Severe) |
| 数据集 | 1661 张眼底图像,按图片内容去重分组后 80/20 分层划分 |
| 训练策略 | 训练集过采样均衡 + 眼底图黑边裁剪 + 轻量数据增强 + AdamW |
| 最优性能 | 测试准确率 91.01%,测试损失 0.489 |
2. 环境
- 语言环境:Python
- 编译器:Jupyter Notebook
- 深度学习环境:PyTorch + torchvision
- 主要依赖:torch、torchvision、torchsummary、matplotlib、Pillow、numpy
3. 代码实现
3.1 前期准备
3.1.1 设置 GPU & 导入库
导入 PyTorch、torchvision 等深度学习库,配置 matplotlib 中文字体,固定随机种子,并自动选择 GPU/CPU 设备。J8 从 resnext.py 导入模型构建函数。
python
import torch
import torch.nn as nn
from torchvision import transforms, datasets
from torch.utils.data import DataLoader, Subset
import os, PIL, warnings
import torchsummary as summary
import copy
import matplotlib.pyplot as plt
from PIL import Image, ImageOps
from datetime import datetime
import random
import hashlib
import numpy as np
from collections import Counter, defaultdict

from resnext import get_resnext

warnings.filterwarnings("ignore")
plt.rcParams["figure.dpi"] = 100
plt.rcParams['font.sans-serif'] = ['SimHei']
plt.rcParams['axes.unicode_minus'] = False

seed = 42
random.seed(seed)
np.random.seed(seed)
torch.manual_seed(seed)
if torch.cuda.is_available():
    torch.cuda.manual_seed_all(seed)

try:
    torch.backends.cudnn.deterministic = True
    torch.backends.cudnn.benchmark = False
except AttributeError:
    pass

device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
device
bash
device(type='cpu')3.1.2 可视化样本图片
从 2Mild 类别中读取部分图片进行可视化,检查数据内容和图像质量。
python
image_folder = './Data/data/2Mild/'
image_files = [f for f in os.listdir(image_folder) if f.endswith((".jpg", ".png", ".jpeg"))]
fig, axes = plt.subplots(3, 8, figsize=(16, 6))

for ax, img_file in zip(axes.ravel(), image_files[:24]):
    img_path = os.path.join(image_folder, img_file)
    img = PIL.Image.open(img_path)
    ax.imshow(img)
    ax.axis('off')

plt.tight_layout()
plt.show()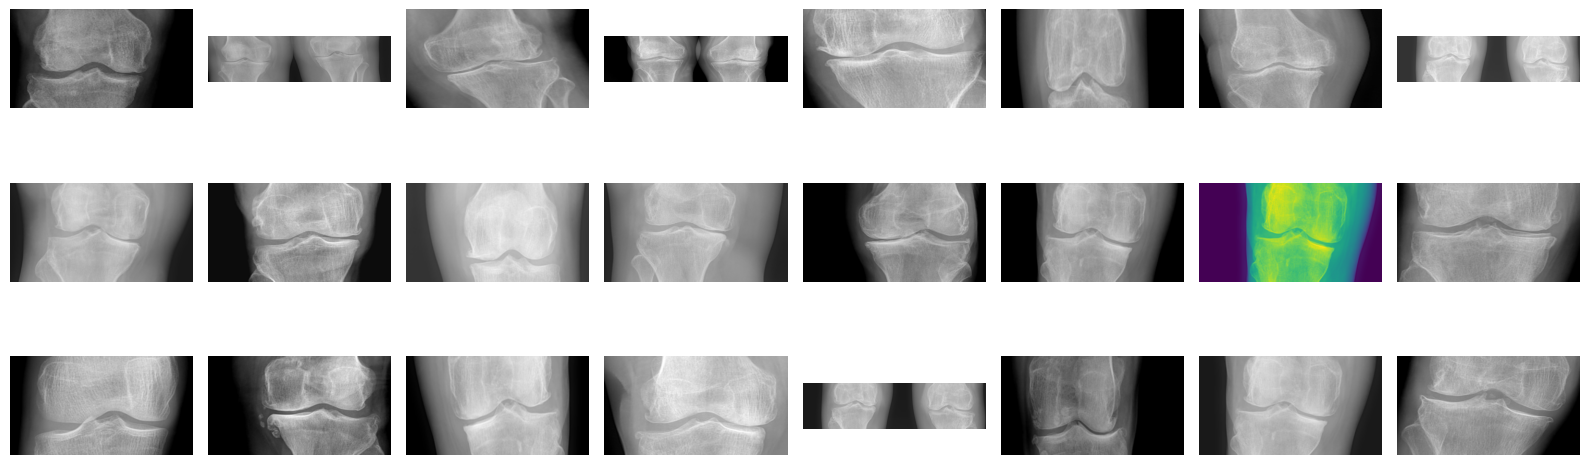
3.1.3 数据加载与预处理
J8 使用 ResNeXt50,输入尺寸设为 ResNet 系列常用的 224x224。预处理流程为:裁掉眼底黑边、自动对比度增强、Resize 到 224x224,再做归一化。训练集额外加入轻量翻转、旋转和颜色扰动。
python
data_dir = './Data/data/'
IMG_SIZE = 224

def preprocess_fundus(img, threshold=10, padding=12):
    """裁掉眼底图周围大面积黑边,并做轻量自动对比度增强。"""
    img = img.convert('RGB')
    arr = np.asarray(img)
    mask = arr.mean(axis=2) > threshold

    if mask.any():
        ys, xs = np.where(mask)
        left = max(int(xs.min()) - padding, 0)
        top = max(int(ys.min()) - padding, 0)
        right = min(int(xs.max()) + padding + 1, img.width)
        bottom = min(int(ys.max()) + padding + 1, img.height)
        img = img.crop((left, top, right, bottom))

    return ImageOps.autocontrast(img, cutoff=1)

train_transforms = transforms.Compose([
    transforms.Lambda(preprocess_fundus),
    transforms.Resize((IMG_SIZE, IMG_SIZE)),
    transforms.RandomHorizontalFlip(p=0.5),
    transforms.RandomRotation(degrees=8),
    transforms.RandomApply([
        transforms.ColorJitter(brightness=0.04, contrast=0.08, saturation=0.03)
    ], p=0.3),
    transforms.ToTensor(),
    transforms.Normalize(mean=[0.485, 0.456, 0.406], std=[0.229, 0.224, 0.225])
])

test_transforms = transforms.Compose([
    transforms.Lambda(preprocess_fundus),
    transforms.Resize((IMG_SIZE, IMG_SIZE)),
    transforms.ToTensor(),
    transforms.Normalize(mean=[0.485, 0.456, 0.406], std=[0.229, 0.224, 0.225])
])

total_data = datasets.ImageFolder(data_dir)
print(f"Raw samples: {len(total_data)}")
print(f"Classes: {total_data.class_to_idx}")
raw_counts = Counter(total_data.targets)
print("Raw class counts:", dict(zip(total_data.classes, [raw_counts[i] for i in range(len(total_data.classes))])))
bash
Raw samples: 1661
Classes: {'0Normal': 0, '2Mild': 1, '4Severe': 2}
Raw class counts: {'0Normal': 1017, '2Mild': 232, '4Severe': 412}
3.1.4 类别映射
python
total_data.class_to_idx
bash
{'0Normal': 0, '2Mild': 1, '4Severe': 2}3.1.5 分组划分与训练集均衡
按图片内容 MD5 分组,保证重复图片不会同时进入训练集和测试集;再按类别分层划分。训练集使用过采样均衡,避免模型被多数类主导。
python
assert NOTEBOOK_VERSION == 'J8_RESNEXT50_20260810_V1'
DATA_PIPELINE_VERSION = 'GROUP_SPLIT_BALANCED_OVERSAMPLING_FUNDUS_PREPROCESS_J8_RESNEXT50_V1'

def file_md5(path):
    with open(path, 'rb') as f:
        return hashlib.md5(f.read()).hexdigest()

hash_groups = defaultdict(list)
for idx, (path, label) in enumerate(total_data.samples):
    hash_groups[(file_md5(path), label)].append(idx)

groups_by_class = defaultdict(list)
for (_, label), indices in hash_groups.items():
    groups_by_class[label].append(indices)

def stratified_group_split(groups_by_class, test_ratio=0.2, seed=42):
    rng = random.Random(seed)
    train_indices, test_indices = [], []
    for label, groups in sorted(groups_by_class.items()):
        groups = groups.copy()
        rng.shuffle(groups)
        n_test = max(1, round(len(groups) * test_ratio))
        test_groups = groups[:n_test]
        train_groups = groups[n_test:]
        for group in train_groups:
            train_indices.extend(group)
        for group in test_groups:
            test_indices.append(group[0])
    rng.shuffle(train_indices)
    rng.shuffle(test_indices)
    return train_indices, test_indices

def make_balanced_indices(indices, targets, seed=42):
    rng = random.Random(seed)
    indices_by_class = defaultdict(list)
    for idx in indices:
        indices_by_class[targets[idx]].append(idx)
    max_count = max(len(v) for v in indices_by_class.values())
    balanced_indices = []
    for label, label_indices in sorted(indices_by_class.items()):
        label_indices = label_indices.copy()
        repeats = max_count // len(label_indices)
        remainder = max_count % len(label_indices)
        balanced_indices.extend(label_indices * repeats)
        balanced_indices.extend(rng.sample(label_indices, remainder))
    rng.shuffle(balanced_indices)
    return balanced_indices

train_indices_raw, test_indices = stratified_group_split(groups_by_class, test_ratio=0.2, seed=seed)
train_indices = make_balanced_indices(train_indices_raw, total_data.targets, seed=seed)
bash
Unique image groups: 946 (found 715 exact duplicates)
Unique group counts: {'0Normal': 513, '2Mild': 227, '4Severe': 206}
Raw train class counts before balancing: {'0Normal': 812, '2Mild': 184, '4Severe': 330}
Balanced train class counts: {'0Normal': 812, '2Mild': 812, '4Severe': 812}
Test class counts: {'0Normal': 103, '2Mild': 45, '4Severe': 41}
Train majority baseline after balancing: 0.333
Test majority baseline: 0.545
3.1.6 构建 DataLoader
python
train_data_full = datasets.ImageFolder(data_dir, transform=train_transforms)
test_data_full = datasets.ImageFolder(data_dir, transform=test_transforms)
train_dataset = Subset(train_data_full, train_indices)
test_dataset = Subset(test_data_full, test_indices)

batch_size = 16
train_dl = DataLoader(train_dataset, batch_size=batch_size, shuffle=True)
test_dl = DataLoader(test_dataset, batch_size=batch_size, shuffle=False)

train_targets = torch.tensor(train_targets_list)
class_counts = torch.bincount(train_targets, minlength=len(total_data.classes))
class_weights = class_counts.sum() / (len(total_data.classes) * class_counts.float())
bash
Balanced train samples: 2436
Train class counts: {'0Normal': 812, '2Mild': 812, '4Severe': 812}
Class weights: {'0Normal': 1.0, '2Mild': 1.0, '4Severe': 1.0}
Test samples: 189
Batch size: 16
Image size: 224
DATA_PIPELINE_VERSION: GROUP_SPLIT_BALANCED_OVERSAMPLING_FUNDUS_PREPROCESS_J8_RESNEXT50_V1
Shape of X [N, C, H, W]:  torch.Size([16, 3, 224, 224])
Shape of y:  torch.Size([16]) torch.int64
3.2 模型建立与训练
3.2.1 定义 ResNeXt 网络模型
ResNeXt 的核心思想是在 ResNet 瓶颈残差块中引入 cardinality,即通过分组卷积增加并行路径数量。相比单纯加深或加宽网络,ResNeXt 用更规则的多分支结构提升表达能力。
| 组件 | 作用 |
|---|---|
| ResNeXtBlock | 1x1 Conv -> 3x3 grouped Conv -> 1x1 Conv 的瓶颈残差块 |
| cardinality | 分组卷积的组数,本实验为 32 |
| base_width | 每组基础宽度,本实验为 4 |
| ResNeXt50 | 四个阶段的 block 数为 [3,4,6,3],最后接全局平均池化和 FC 分类层 |
本实验中 num_classes=3,对应三分类任务(Normal / Mild / Severe)。
python
MODEL_NAME = 'ResNeXt50'
model = get_resnext(resnext_name=MODEL_NAME, num_classes=len(total_data.classes)).to(device)
model
bash
ResNeXt(
  (conv1): Conv2d(3, 64, kernel_size=(7, 7), stride=(2, 2), padding=(3, 3), bias=False)
  (bn1): BatchNorm2d(64, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
  (maxpool): MaxPool2d(kernel_size=3, stride=2, padding=1, dilation=1, ceil_mode=False)
  (layer1): Sequential(
    (0): ResNeXtBlock(
      (conv1): Conv2d(64, 128, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn1): BatchNorm2d(128, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv2): Conv2d(128, 128, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), groups=32, bias=False)
      (bn2): BatchNorm2d(128, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv3): Conv2d(128, 256, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn3): BatchNorm2d(256, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (downsample): Sequential(
        (0): Conv2d(64, 256, kernel_size=(1, 1), stride=(1, 1), bias=False)
        (1): BatchNorm2d(256, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      )
    )
    (1): ResNeXtBlock(
      (conv1): Conv2d(256, 128, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn1): BatchNorm2d(128, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv2): Conv2d(128, 128, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), groups=32, bias=False)
      (bn2): BatchNorm2d(128, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv3): Conv2d(128, 256, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn3): BatchNorm2d(256, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
    )
    (2): ResNeXtBlock(
      (conv1): Conv2d(256, 128, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn1): BatchNorm2d(128, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv2): Conv2d(128, 128, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), groups=32, bias=False)
      (bn2): BatchNorm2d(128, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv3): Conv2d(128, 256, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn3): BatchNorm2d(256, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
    )
  )
  (layer2): Sequential(
    (0): ResNeXtBlock(
      (conv1): Conv2d(256, 256, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn1): BatchNorm2d(256, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv2): Conv2d(256, 256, kernel_size=(3, 3), stride=(2, 2), padding=(1, 1), groups=32, bias=False)
      (bn2): BatchNorm2d(256, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv3): Conv2d(256, 512, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn3): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (downsample): Sequential(
        (0): Conv2d(256, 512, kernel_size=(1, 1), stride=(2, 2), bias=False)
        (1): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      )
    )
    (1): ResNeXtBlock(
      (conv1): Conv2d(512, 256, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn1): BatchNorm2d(256, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv2): Conv2d(256, 256, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), groups=32, bias=False)
      (bn2): BatchNorm2d(256, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv3): Conv2d(256, 512, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn3): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
    )
    (2): ResNeXtBlock(
      (conv1): Conv2d(512, 256, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn1): BatchNorm2d(256, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv2): Conv2d(256, 256, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), groups=32, bias=False)
      (bn2): BatchNorm2d(256, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv3): Conv2d(256, 512, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn3): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
    )
    (3): ResNeXtBlock(
      (conv1): Conv2d(512, 256, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn1): BatchNorm2d(256, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv2): Conv2d(256, 256, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), groups=32, bias=False)
      (bn2): BatchNorm2d(256, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv3): Conv2d(256, 512, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn3): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
    )
  )
  (layer3): Sequential(
    (0): ResNeXtBlock(
      (conv1): Conv2d(512, 512, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn1): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv2): Conv2d(512, 512, kernel_size=(3, 3), stride=(2, 2), padding=(1, 1), groups=32, bias=False)
      (bn2): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv3): Conv2d(512, 1024, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn3): BatchNorm2d(1024, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (downsample): Sequential(
        (0): Conv2d(512, 1024, kernel_size=(1, 1), stride=(2, 2), bias=False)
        (1): BatchNorm2d(1024, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      )
    )
    (1): ResNeXtBlock(
      (conv1): Conv2d(1024, 512, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn1): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv2): Conv2d(512, 512, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), groups=32, bias=False)
      (bn2): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv3): Conv2d(512, 1024, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn3): BatchNorm2d(1024, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
    )
    (2): ResNeXtBlock(
      (conv1): Conv2d(1024, 512, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn1): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv2): Conv2d(512, 512, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), groups=32, bias=False)
      (bn2): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv3): Conv2d(512, 1024, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn3): BatchNorm2d(1024, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
    )
    (3): ResNeXtBlock(
      (conv1): Conv2d(1024, 512, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn1): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv2): Conv2d(512, 512, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), groups=32, bias=False)
      (bn2): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv3): Conv2d(512, 1024, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn3): BatchNorm2d(1024, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
    )
    (4): ResNeXtBlock(
      (conv1): Conv2d(1024, 512, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn1): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv2): Conv2d(512, 512, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), groups=32, bias=False)
      (bn2): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv3): Conv2d(512, 1024, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn3): BatchNorm2d(1024, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
    )
    (5): ResNeXtBlock(
      (conv1): Conv2d(1024, 512, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn1): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv2): Conv2d(512, 512, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), groups=32, bias=False)
      (bn2): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv3): Conv2d(512, 1024, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn3): BatchNorm2d(1024, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
    )
  )
  (layer4): Sequential(
    (0): ResNeXtBlock(
      (conv1): Conv2d(1024, 1024, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn1): BatchNorm2d(1024, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv2): Conv2d(1024, 1024, kernel_size=(3, 3), stride=(2, 2), padding=(1, 1), groups=32, bias=False)
      (bn2): BatchNorm2d(1024, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv3): Conv2d(1024, 2048, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn3): BatchNorm2d(2048, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (downsample): Sequential(
        (0): Conv2d(1024, 2048, kernel_size=(1, 1), stride=(2, 2), bias=False)
        (1): BatchNorm2d(2048, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      )
    )
    (1): ResNeXtBlock(
      (conv1): Conv2d(2048, 1024, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn1): BatchNorm2d(1024, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv2): Conv2d(1024, 1024, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), groups=32, bias=False)
      (bn2): BatchNorm2d(1024, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv3): Conv2d(1024, 2048, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn3): BatchNorm2d(2048, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
    )
    (2): ResNeXtBlock(
      (conv1): Conv2d(2048, 1024, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn1): BatchNorm2d(1024, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv2): Conv2d(1024, 1024, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), groups=32, bias=False)
      (bn2): BatchNorm2d(1024, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
      (conv3): Conv2d(1024, 2048, kernel_size=(1, 1), stride=(1, 1), bias=False)
      (bn3): BatchNorm2d(2048, eps=1e-05, momentum=0.1, affine=True, bias=True, track_running_stats=True)
    )
  )
  (avgpool): AdaptiveAvgPool2d(output_size=(1, 1))
  (fc): Linear(in_features=2048, out_features=3, bias=True)
)
3.2.2 模型结构概览
通过随机输入验证模型的前向传播是否正常工作:
- 输入:
(1, 3, 224, 224),1 张224x224RGB 图像 - 输出:
(1, 3),3 个类别的预测分数
python
summary.summary(model, (3, IMG_SIZE, IMG_SIZE))

x = torch.randn(1, 3, IMG_SIZE, IMG_SIZE).to(device)
out = model(x)
print(f"Input shape:  {x.shape}")
print(f"Output shape: {out.shape}")

total_params = sum(p.numel() for p in model.parameters())
trainable_params = sum(p.numel() for p in model.parameters() if p.requires_grad)
print(f"Total params:     {total_params:,}")
print(f"Trainable params: {trainable_params:,}")
bash
----------------------------------------------------------------
        Layer (type)               Output Shape         Param #
================================================================
            Conv2d-1         [-1, 64, 112, 112]           9,408
       BatchNorm2d-2         [-1, 64, 112, 112]             128
         MaxPool2d-3           [-1, 64, 56, 56]               0
            Conv2d-4          [-1, 128, 56, 56]           8,192
       BatchNorm2d-5          [-1, 128, 56, 56]             256
            Conv2d-6          [-1, 128, 56, 56]           4,608
       BatchNorm2d-7          [-1, 128, 56, 56]             256
            Conv2d-8          [-1, 256, 56, 56]          32,768
       BatchNorm2d-9          [-1, 256, 56, 56]             512
           Conv2d-10          [-1, 256, 56, 56]          16,384
      BatchNorm2d-11          [-1, 256, 56, 56]             512
     ResNeXtBlock-12          [-1, 256, 56, 56]               0
           Conv2d-13          [-1, 128, 56, 56]          32,768
      BatchNorm2d-14          [-1, 128, 56, 56]             256
           Conv2d-15          [-1, 128, 56, 56]           4,608
      BatchNorm2d-16          [-1, 128, 56, 56]             256
           Conv2d-17          [-1, 256, 56, 56]          32,768
      BatchNorm2d-18          [-1, 256, 56, 56]             512
     ResNeXtBlock-19          [-1, 256, 56, 56]               0
           Conv2d-20          [-1, 128, 56, 56]          32,768
      BatchNorm2d-21          [-1, 128, 56, 56]             256
           Conv2d-22          [-1, 128, 56, 56]           4,608
      BatchNorm2d-23          [-1, 128, 56, 56]             256
           Conv2d-24          [-1, 256, 56, 56]          32,768
      BatchNorm2d-25          [-1, 256, 56, 56]             512
     ResNeXtBlock-26          [-1, 256, 56, 56]               0
           Conv2d-27          [-1, 256, 56, 56]          65,536
      BatchNorm2d-28          [-1, 256, 56, 56]             512
           Conv2d-29          [-1, 256, 28, 28]          18,432
      BatchNorm2d-30          [-1, 256, 28, 28]             512
           Conv2d-31          [-1, 512, 28, 28]         131,072
      BatchNorm2d-32          [-1, 512, 28, 28]           1,024
           Conv2d-33          [-1, 512, 28, 28]         131,072
      BatchNorm2d-34          [-1, 512, 28, 28]           1,024
     ResNeXtBlock-35          [-1, 512, 28, 28]               0
           Conv2d-36          [-1, 256, 28, 28]         131,072
      BatchNorm2d-37          [-1, 256, 28, 28]             512
           Conv2d-38          [-1, 256, 28, 28]          18,432
      BatchNorm2d-39          [-1, 256, 28, 28]             512
           Conv2d-40          [-1, 512, 28, 28]         131,072
      BatchNorm2d-41          [-1, 512, 28, 28]           1,024
     ResNeXtBlock-42          [-1, 512, 28, 28]               0
           Conv2d-43          [-1, 256, 28, 28]         131,072
      BatchNorm2d-44          [-1, 256, 28, 28]             512
           Conv2d-45          [-1, 256, 28, 28]          18,432
      BatchNorm2d-46          [-1, 256, 28, 28]             512
           Conv2d-47          [-1, 512, 28, 28]         131,072
      BatchNorm2d-48          [-1, 512, 28, 28]           1,024
     ResNeXtBlock-49          [-1, 512, 28, 28]               0
           Conv2d-50          [-1, 256, 28, 28]         131,072
      BatchNorm2d-51          [-1, 256, 28, 28]             512
           Conv2d-52          [-1, 256, 28, 28]          18,432
      BatchNorm2d-53          [-1, 256, 28, 28]             512
           Conv2d-54          [-1, 512, 28, 28]         131,072
      BatchNorm2d-55          [-1, 512, 28, 28]           1,024
     ResNeXtBlock-56          [-1, 512, 28, 28]               0
           Conv2d-57          [-1, 512, 28, 28]         262,144
      BatchNorm2d-58          [-1, 512, 28, 28]           1,024
           Conv2d-59          [-1, 512, 14, 14]          73,728
      BatchNorm2d-60          [-1, 512, 14, 14]           1,024
           Conv2d-61         [-1, 1024, 14, 14]         524,288
      BatchNorm2d-62         [-1, 1024, 14, 14]           2,048
           Conv2d-63         [-1, 1024, 14, 14]         524,288
      BatchNorm2d-64         [-1, 1024, 14, 14]           2,048
     ResNeXtBlock-65         [-1, 1024, 14, 14]               0
           Conv2d-66          [-1, 512, 14, 14]         524,288
      BatchNorm2d-67          [-1, 512, 14, 14]           1,024
           Conv2d-68          [-1, 512, 14, 14]          73,728
      BatchNorm2d-69          [-1, 512, 14, 14]           1,024
           Conv2d-70         [-1, 1024, 14, 14]         524,288
      BatchNorm2d-71         [-1, 1024, 14, 14]           2,048
     ResNeXtBlock-72         [-1, 1024, 14, 14]               0
           Conv2d-73          [-1, 512, 14, 14]         524,288
      BatchNorm2d-74          [-1, 512, 14, 14]           1,024
           Conv2d-75          [-1, 512, 14, 14]          73,728
      BatchNorm2d-76          [-1, 512, 14, 14]           1,024
           Conv2d-77         [-1, 1024, 14, 14]         524,288
      BatchNorm2d-78         [-1, 1024, 14, 14]           2,048
     ResNeXtBlock-79         [-1, 1024, 14, 14]               0
           Conv2d-80          [-1, 512, 14, 14]         524,288
      BatchNorm2d-81          [-1, 512, 14, 14]           1,024
           Conv2d-82          [-1, 512, 14, 14]          73,728
      BatchNorm2d-83          [-1, 512, 14, 14]           1,024
           Conv2d-84         [-1, 1024, 14, 14]         524,288
      BatchNorm2d-85         [-1, 1024, 14, 14]           2,048
     ResNeXtBlock-86         [-1, 1024, 14, 14]               0
           Conv2d-87          [-1, 512, 14, 14]         524,288
      BatchNorm2d-88          [-1, 512, 14, 14]           1,024
           Conv2d-89          [-1, 512, 14, 14]          73,728
      BatchNorm2d-90          [-1, 512, 14, 14]           1,024
           Conv2d-91         [-1, 1024, 14, 14]         524,288
      BatchNorm2d-92         [-1, 1024, 14, 14]           2,048
     ResNeXtBlock-93         [-1, 1024, 14, 14]               0
           Conv2d-94          [-1, 512, 14, 14]         524,288
      BatchNorm2d-95          [-1, 512, 14, 14]           1,024
           Conv2d-96          [-1, 512, 14, 14]          73,728
      BatchNorm2d-97          [-1, 512, 14, 14]           1,024
           Conv2d-98         [-1, 1024, 14, 14]         524,288
      BatchNorm2d-99         [-1, 1024, 14, 14]           2,048
    ResNeXtBlock-100         [-1, 1024, 14, 14]               0
          Conv2d-101         [-1, 1024, 14, 14]       1,048,576
     BatchNorm2d-102         [-1, 1024, 14, 14]           2,048
          Conv2d-103           [-1, 1024, 7, 7]         294,912
     BatchNorm2d-104           [-1, 1024, 7, 7]           2,048
          Conv2d-105           [-1, 2048, 7, 7]       2,097,152
     BatchNorm2d-106           [-1, 2048, 7, 7]           4,096
          Conv2d-107           [-1, 2048, 7, 7]       2,097,152
     BatchNorm2d-108           [-1, 2048, 7, 7]           4,096
    ResNeXtBlock-109           [-1, 2048, 7, 7]               0
          Conv2d-110           [-1, 1024, 7, 7]       2,097,152
     BatchNorm2d-111           [-1, 1024, 7, 7]           2,048
          Conv2d-112           [-1, 1024, 7, 7]         294,912
     BatchNorm2d-113           [-1, 1024, 7, 7]           2,048
          Conv2d-114           [-1, 2048, 7, 7]       2,097,152
     BatchNorm2d-115           [-1, 2048, 7, 7]           4,096
    ResNeXtBlock-116           [-1, 2048, 7, 7]               0
          Conv2d-117           [-1, 1024, 7, 7]       2,097,152
     BatchNorm2d-118           [-1, 1024, 7, 7]           2,048
          Conv2d-119           [-1, 1024, 7, 7]         294,912
     BatchNorm2d-120           [-1, 1024, 7, 7]           2,048
          Conv2d-121           [-1, 2048, 7, 7]       2,097,152
     BatchNorm2d-122           [-1, 2048, 7, 7]           4,096
    ResNeXtBlock-123           [-1, 2048, 7, 7]               0
AdaptiveAvgPool2d-124           [-1, 2048, 1, 1]               0
          Linear-125                    [-1, 3]           6,147
================================================================
Total params: 22,986,051
Trainable params: 22,986,051
Non-trainable params: 0
----------------------------------------------------------------
Input size (MB): 0.57
Forward/backward pass size (MB): 263.39
Params size (MB): 87.68
Estimated Total Size (MB): 351.65
----------------------------------------------------------------
Input shape:  torch.Size([1, 3, 224, 224])
Output shape: torch.Size([1, 3])
Total params:     22,986,051
Trainable params: 22,986,051
3.2.3 定义训练和测试函数
train() 函数负责训练阶段的前向传播、损失计算、反向传播和参数更新;test() 函数在无梯度模式下评估模型;prediction_counts() 用于观察测试集预测分布。
python
def train(dataloader, model, loss_fn, optimizer):
    size = len(dataloader.dataset)
    num_batches = len(dataloader)
    train_loss, train_acc = 0, 0

    for X, y in dataloader:
        X, y = X.to(device), y.to(device)
        pred = model(X)
        loss = loss_fn(pred, y)

        optimizer.zero_grad()
        loss.backward()
        torch.nn.utils.clip_grad_norm_(model.parameters(), max_norm=5.0)
        optimizer.step()

        train_loss += loss.item()
        train_acc += (pred.argmax(1) == y).type(torch.float).sum().item()

    return train_loss / num_batches, train_acc / size

def test(dataloader, model, loss_fn):
    size = len(dataloader.dataset)
    num_batches = len(dataloader)
    test_loss, test_acc = 0, 0

    with torch.no_grad():
        for imgs, target in dataloader:
            imgs, target = imgs.to(device), target.to(device)
            target_pred = model(imgs)
            loss = loss_fn(target_pred, target)
            test_acc += (target_pred.argmax(1) == target).type(torch.float).sum().item()
            test_loss += loss.item()

    return test_loss / num_batches, test_acc / size
3.2.4 训练模型
训练配置:
- 优化器:AdamW,学习率
lr=1e-4,权重衰减1e-5 - 损失函数:CrossEntropyLoss,使用训练集类别权重
- 训练轮次:30 个 Epoch
- 最优模型保存路径:
./best_resnext50.pth
python
optimizer = torch.optim.AdamW(model.parameters(), lr=1e-4, weight_decay=1e-5)
loss_fn = nn.CrossEntropyLoss(weight=class_weights.to(device))

epochs = 30
train_loss, train_acc = [], []
test_loss, test_acc = [], []
best_acc = 0
best_model_wts = copy.deepcopy(model)

for epoch in range(epochs):
    model.train()
    train_epoch_loss, train_epoch_acc = train(train_dl, model, loss_fn, optimizer)

    model.eval()
    epoch_test_loss, epoch_test_acc = test(test_dl, model, loss_fn)

    if epoch_test_acc > best_acc:
        best_acc = epoch_test_acc
        best_model_wts = copy.deepcopy(model)

    train_acc.append(train_epoch_acc)
    train_loss.append(train_epoch_loss)
    test_acc.append(epoch_test_acc)
    test_loss.append(epoch_test_loss)

    lr = optimizer.param_groups[0]['lr']
    print(f"Epoch: {epoch+1:2d}, Train_acc: {train_epoch_acc*100:.1f}%, "
          f"Train_loss: {train_epoch_loss:.3f}, Test_acc: {epoch_test_acc*100:.1f}%, "
          f"Test_loss: {epoch_test_loss:.3f}, Lr: {lr:.2E}")

PATH = './best_resnext50.pth'
torch.save(best_model_wts.state_dict(), PATH)
print('Done.')
bash
Epoch:  1, Train_acc: 57.8%, Train_loss: 0.909, Test_acc: 67.2%, Test_loss: 0.912, Lr: 1.00E-04, Pred: {'0Normal': 140, '2Mild': 23, '4Severe': 26}
Epoch:  2, Train_acc: 66.8%, Train_loss: 0.749, Test_acc: 75.1%, Test_loss: 0.644, Lr: 1.00E-04, Pred: {'0Normal': 118, '2Mild': 16, '4Severe': 55}
Epoch:  3, Train_acc: 72.0%, Train_loss: 0.651, Test_acc: 54.5%, Test_loss: 1.158, Lr: 1.00E-04, Pred: {'0Normal': 54, '2Mild': 75, '4Severe': 60}
Epoch:  4, Train_acc: 77.6%, Train_loss: 0.549, Test_acc: 80.4%, Test_loss: 0.550, Lr: 1.00E-04, Pred: {'0Normal': 101, '2Mild': 36, '4Severe': 52}
Epoch:  5, Train_acc: 80.9%, Train_loss: 0.472, Test_acc: 82.5%, Test_loss: 0.593, Lr: 1.00E-04, Pred: {'0Normal': 100, '2Mild': 46, '4Severe': 43}
Epoch:  6, Train_acc: 84.0%, Train_loss: 0.405, Test_acc: 72.5%, Test_loss: 1.051, Lr: 1.00E-04, Pred: {'0Normal': 83, '2Mild': 22, '4Severe': 84}
Epoch:  7, Train_acc: 85.4%, Train_loss: 0.369, Test_acc: 85.7%, Test_loss: 0.433, Lr: 1.00E-04, Pred: {'0Normal': 107, '2Mild': 47, '4Severe': 35}
Epoch:  8, Train_acc: 86.9%, Train_loss: 0.319, Test_acc: 43.4%, Test_loss: 2.465, Lr: 1.00E-04, Pred: {'0Normal': 37, '2Mild': 81, '4Severe': 71}
Epoch:  9, Train_acc: 88.8%, Train_loss: 0.328, Test_acc: 82.5%, Test_loss: 0.718, Lr: 1.00E-04, Pred: {'0Normal': 112, '2Mild': 53, '4Severe': 24}
Epoch: 10, Train_acc: 92.4%, Train_loss: 0.216, Test_acc: 38.6%, Test_loss: 4.521, Lr: 1.00E-04, Pred: {'0Normal': 6, '2Mild': 133, '4Severe': 50}
Epoch: 11, Train_acc: 92.6%, Train_loss: 0.212, Test_acc: 89.4%, Test_loss: 0.547, Lr: 1.00E-04, Pred: {'0Normal': 103, '2Mild': 51, '4Severe': 35}
Epoch: 12, Train_acc: 93.3%, Train_loss: 0.170, Test_acc: 79.9%, Test_loss: 0.745, Lr: 1.00E-04, Pred: {'0Normal': 81, '2Mild': 70, '4Severe': 38}
Epoch: 13, Train_acc: 94.3%, Train_loss: 0.169, Test_acc: 84.7%, Test_loss: 0.889, Lr: 1.00E-04, Pred: {'0Normal': 109, '2Mild': 30, '4Severe': 50}
Epoch: 14, Train_acc: 93.2%, Train_loss: 0.205, Test_acc: 81.5%, Test_loss: 0.740, Lr: 1.00E-04, Pred: {'0Normal': 124, '2Mild': 24, '4Severe': 41}
Epoch: 15, Train_acc: 94.6%, Train_loss: 0.155, Test_acc: 77.8%, Test_loss: 0.947, Lr: 1.00E-04, Pred: {'0Normal': 74, '2Mild': 75, '4Severe': 40}
Epoch: 16, Train_acc: 96.1%, Train_loss: 0.125, Test_acc: 81.0%, Test_loss: 0.847, Lr: 1.00E-04, Pred: {'0Normal': 126, '2Mild': 29, '4Severe': 34}
Epoch: 17, Train_acc: 95.1%, Train_loss: 0.123, Test_acc: 82.5%, Test_loss: 0.961, Lr: 1.00E-04, Pred: {'0Normal': 92, '2Mild': 35, '4Severe': 62}
Epoch: 18, Train_acc: 95.4%, Train_loss: 0.130, Test_acc: 88.9%, Test_loss: 0.624, Lr: 1.00E-04, Pred: {'0Normal': 100, '2Mild': 49, '4Severe': 40}
Epoch: 19, Train_acc: 96.6%, Train_loss: 0.093, Test_acc: 87.8%, Test_loss: 0.666, Lr: 1.00E-04, Pred: {'0Normal': 100, '2Mild': 60, '4Severe': 29}
Epoch: 20, Train_acc: 96.8%, Train_loss: 0.080, Test_acc: 87.8%, Test_loss: 0.597, Lr: 1.00E-04, Pred: {'0Normal': 104, '2Mild': 46, '4Severe': 39}
Epoch: 21, Train_acc: 95.1%, Train_loss: 0.125, Test_acc: 87.3%, Test_loss: 0.575, Lr: 1.00E-04, Pred: {'0Normal': 101, '2Mild': 48, '4Severe': 40}
Epoch: 22, Train_acc: 97.9%, Train_loss: 0.052, Test_acc: 88.9%, Test_loss: 0.637, Lr: 1.00E-04, Pred: {'0Normal': 104, '2Mild': 50, '4Severe': 35}
Epoch: 23, Train_acc: 96.1%, Train_loss: 0.091, Test_acc: 89.4%, Test_loss: 0.462, Lr: 1.00E-04, Pred: {'0Normal': 104, '2Mild': 44, '4Severe': 41}
Epoch: 24, Train_acc: 97.1%, Train_loss: 0.073, Test_acc: 89.4%, Test_loss: 0.668, Lr: 1.00E-04, Pred: {'0Normal': 105, '2Mild': 42, '4Severe': 42}
Epoch: 25, Train_acc: 96.9%, Train_loss: 0.086, Test_acc: 84.7%, Test_loss: 0.818, Lr: 1.00E-04, Pred: {'0Normal': 90, '2Mild': 56, '4Severe': 43}
Epoch: 26, Train_acc: 96.0%, Train_loss: 0.121, Test_acc: 86.8%, Test_loss: 0.712, Lr: 1.00E-04, Pred: {'0Normal': 113, '2Mild': 39, '4Severe': 37}
Epoch: 27, Train_acc: 96.4%, Train_loss: 0.118, Test_acc: 83.6%, Test_loss: 0.500, Lr: 1.00E-04, Pred: {'0Normal': 94, '2Mild': 52, '4Severe': 43}
Epoch: 28, Train_acc: 97.9%, Train_loss: 0.052, Test_acc: 88.9%, Test_loss: 0.693, Lr: 1.00E-04, Pred: {'0Normal': 109, '2Mild': 42, '4Severe': 38}
Epoch: 29, Train_acc: 96.9%, Train_loss: 0.087, Test_acc: 91.0%, Test_loss: 0.489, Lr: 1.00E-04, Pred: {'0Normal': 101, '2Mild': 52, '4Severe': 36}
Epoch: 30, Train_acc: 97.8%, Train_loss: 0.052, Test_acc: 88.4%, Test_loss: 0.610, Lr: 1.00E-04, Pred: {'0Normal': 105, '2Mild': 43, '4Severe': 41}
Done.
最优模型出现在第 29 个 Epoch,测试准确率达到 91.01% ,测试损失为 0.489。
4. 模型评估
4.1 可视化训练过程
绘制训练和测试的准确率、损失曲线,用于观察模型是否收敛、是否存在过拟合或测试集波动。
python
current_time = datetime.now()
epochs_range = range(epochs)

plt.figure(figsize=(12, 3))
plt.subplot(1, 2, 1)
plt.plot(epochs_range, train_acc, label='Training Accuracy')
plt.plot(epochs_range, test_acc, label='Test Accuracy')
plt.legend(loc='lower right')
plt.title('Training and Validation Accuracy')
plt.xlabel(current_time)

plt.subplot(1, 2, 2)
plt.plot(epochs_range, train_loss, label='Training Loss')
plt.plot(epochs_range, test_loss, label='Test Loss')
plt.legend(loc='upper right')
plt.title('Training and Validation Loss')
plt.show()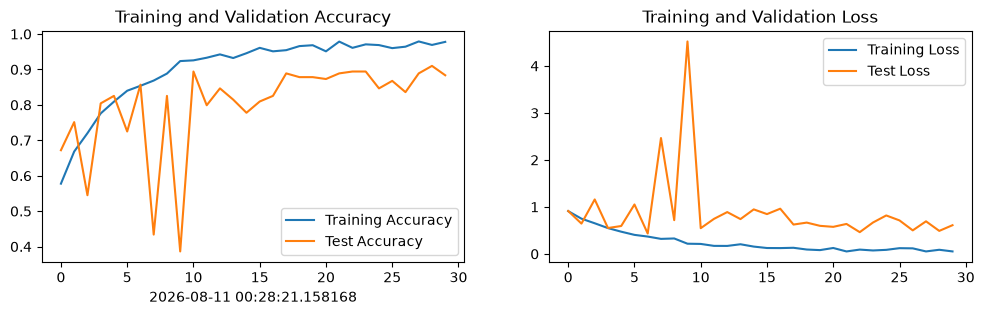
4.2 加载最优模型并评估
加载训练过程中保存的最优模型权重,在测试集上进行最终评估,输出测试准确率、损失值、混淆矩阵和各类别准确率。
python
best_model_wts.load_state_dict(torch.load(PATH, map_location=device))
test_epoch_loss, test_epoch_acc = test(test_dl, best_model_wts, loss_fn)
print(f"Best model - Test Acc: {test_epoch_acc*100:.1f}%, Test Loss: {test_epoch_loss:.3f}")
bash
Best model - Test Acc: 91.0%, Test Loss: 0.489
python
best_model_wts.eval()
confusion = torch.zeros(len(total_data.classes), len(total_data.classes), dtype=torch.int64)

with torch.no_grad():
    for imgs, target in test_dl:
        imgs = imgs.to(device)
        pred = best_model_wts(imgs).argmax(1).cpu()
        for true_label, pred_label in zip(target, pred):
            confusion[true_label, pred_label] += 1

print("Rows=true labels, columns=predicted labels")
print(total_data.classes)
print(confusion)
print("Per-class accuracy:", {
    total_data.classes[i]: (confusion[i, i].item() / confusion[i].sum().item() if confusion[i].sum().item() else 0)
    for i in range(len(total_data.classes))
})
print("Predicted counts:", dict(zip(total_data.classes, confusion.sum(dim=0).tolist())))
bash
Rows=true labels, columns=predicted labels
['0Normal', '2Mild', '4Severe']
tensor([[97,  5,  1],
        [ 1, 42,  2],
        [ 3,  5, 33]])
Per-class accuracy: {'0Normal': 0.941747572815534, '2Mild': 0.9333333333333333, '4Severe': 0.8048780487804879}
Predicted counts: {'0Normal': 101, '2Mild': 52, '4Severe': 36}
5. 总结
-
ResNeXt 取得了较好的整体表现 :本次最优测试准确率为 91.01% ,测试损失为 0.489。最优点出现在第 29 个 Epoch,说明模型在后期仍有一定收益,但测试集波动也较明显。
-
数据处理:按图片内容去重分组后再分层划分,减少重复图泄漏;训练集过采样均衡,降低类别不平衡对分类边界的影响。
-
各类别表现不完全均衡 :Normal 准确率为 94.17% ,Mild 准确率为 93.33% ,Severe 准确率为 80.49%。Severe 类仍是主要改进方向,可考虑更强的数据增强或针对难例的采样策略。
-
训练存在波动:第 8、10 个 Epoch 测试准确率明显下降,说明当前学习率和小数据集条件下泛化性能不够稳定。后续可以加入学习率调度、早停策略,或在最优权重附近做更细致的验证。