问题描述
小明所在的城市正在规划一条新的地铁线路,需要选择一个理想的位置建设火车站。城市中有多个居民区,每个居民区的位置用一个整数坐标表示。已知居民区的位置坐标中,除了一个坐标值只出现一次外,其余每个坐标值都恰好出现两次。规划部门希望火车站建在那个唯一坐标的居民区附近,以最大化覆盖独特区域的居民。
要求:
- 设计一个算法,在 O(n) 时间内找出唯一不重复的坐标位置,其中 n 是居民区的数量。
- 尽量减少额外空间的使用,以体现算法的空间效率。
测试样例
样例1:
输入:
locations = [5, 2, 3, 2, 5, 3, 9]输出:9解释:坐标 5、2、3 都出现了两次,只有 9 出现一次,是唯一不重复的位置。
样例2:
输入:
locations = [0, 10, 5, 10, 0]输出:5解释:坐标 0 和 10 都出现了两次,只有 5 出现一次。
样例3:
输入:
locations = [100, 200, 100, 300, 200, 300, 500]输出:500解释:坐标 100、200、300 都出现了两次,只有 500 出现一次。
约束条件
- 1 ≤ locations.length ≤ 1001
- 0 ≤ locationsi ≤ 1000
- 居民区数量为奇数
- 除了一个坐标值只出现一次外,其余每个坐标值都恰好出现两次
程序代码
#include <stdio.h>
int findUnique(int* locations, int locationsSize) {
int result = 0;
for (int i = 0; i < locationsSize; i++) {
result ^= locationsi;
}
return result;
}
int main() {
int locations1\[\] = {5, 2, 3, 2, 5, 3, 9};
int locations2\[\] = {0, 10, 5, 10, 0};
int locations3\[\] = {100, 200, 100, 300, 200, 300, 500};
printf("%d\n", findUnique(locations1, 7)); // 9
printf("%d\n", findUnique(locations2, 5)); // 5
printf("%d\n", findUnique(locations3, 7)); // 500
return 0;
}
cpp
#include <stdio.h>

int findUnique(int* locations, int locationsSize) {
    int result = 0;
    for (int i = 0; i < locationsSize; i++) {
        result ^= locations[i];
    }
    return result;
}

int main() {
    int locations1[] = {5, 2, 3, 2, 5, 3, 9};
    int locations2[] = {0, 10, 5, 10, 0};
    int locations3[] = {100, 200, 100, 300, 200, 300, 500};

    printf("%d\n", findUnique(locations1, 7));  // 9
    printf("%d\n", findUnique(locations2, 5));  // 5
    printf("%d\n", findUnique(locations3, 7));  // 500

    return 0;
}
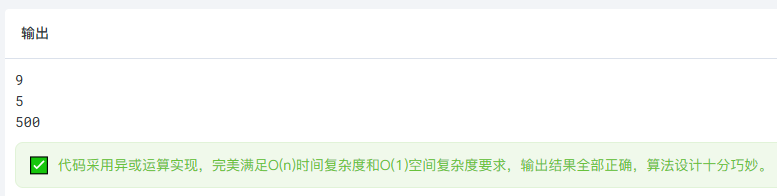
运行结果