一、项目介绍
1.1 技术栈和项目环境
技术栈: C/C++ C++11, STL, 准标准库 Boost , Jsoncpp , cppjieba , cpp-httplib
选学: html5 , css , js 、 jQuery 、 Ajax
项⽬环境: Ubuntu 云服务器, vim/gcc(g++)/Makefile , vs code
1.2 boost库
Boost库是由Boost社区开发维护的开源C++程序库集合,为C++标准库提供扩展功能。
该库涵盖网络编程、数学计算、并发控制等100余个功能模块,支持Windows、Linux、macOS等跨平台操作,大部分库仅需包含头文件即可使用,部分需额外链接库。其Context库支持单线程协同式多任务处理,Multiprecision库提供高精度数值运算功能,Odeint库用于求解常微分方程初值问题。
Boost社区成立初衷是为C++标准化工作提供参考实现,其发起的Ratio库和Chrono库被纳入C++0x标准技术报告。多个组件(如智能指针shared_ptr)通过严格代码审查后已被C++11/14/17标准库直接采用,成为C++生态中的重要工具链。
1.3 目的
本项目是为了给boost库建立一个搜索引擎,用来在boost库中查找我们想要的库文件
这是boost库的官网,当然现在boost官网其实已经有搜索引擎了,但是我们还是可以自己做一个
1.4 搜索引擎介绍
我们平时使用浏览器已经用过很多搜索引擎,比如百度的搜索引擎:
我们在这里输入一个想要搜索的东西然后点击搜索就可以找到网上与搜索的东西相关的内容
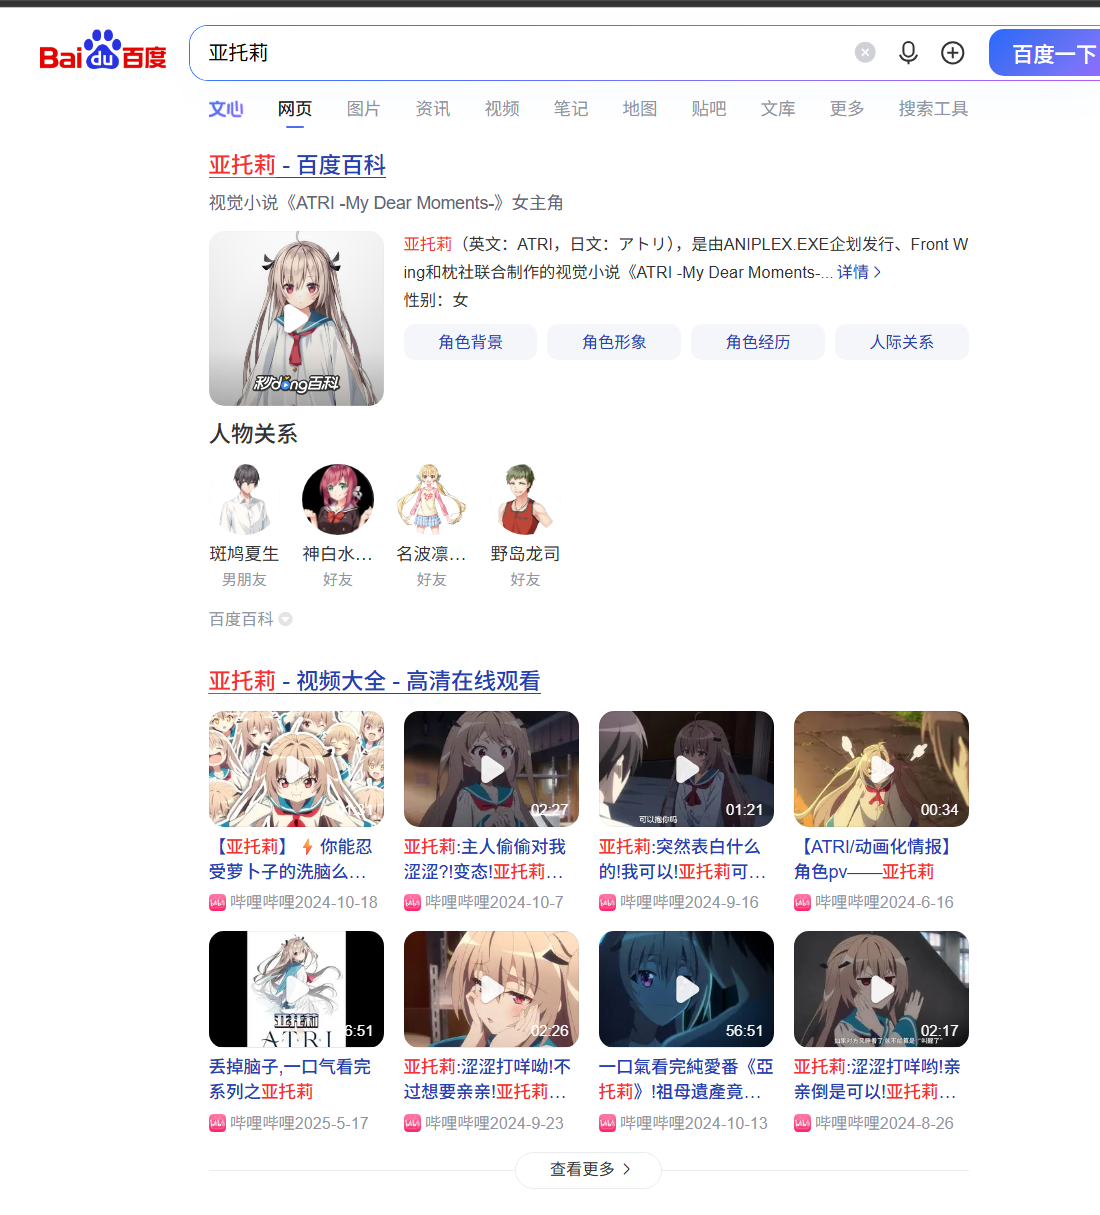
我们可以观察一下搜索出来的内容:
1.内容里都有我们搜索的词
2.内容有一定的排列规律
3.内容的预览栏从搜索的词的前面几个字开始呈现,并且有一定长度,长度不会太长
4.每个内容点击后都会跳转到另一个网页
上面这三条在我们自己实现搜索引擎的时候也要注意
二、原理
2.1 搜索引擎的相关宏观原理
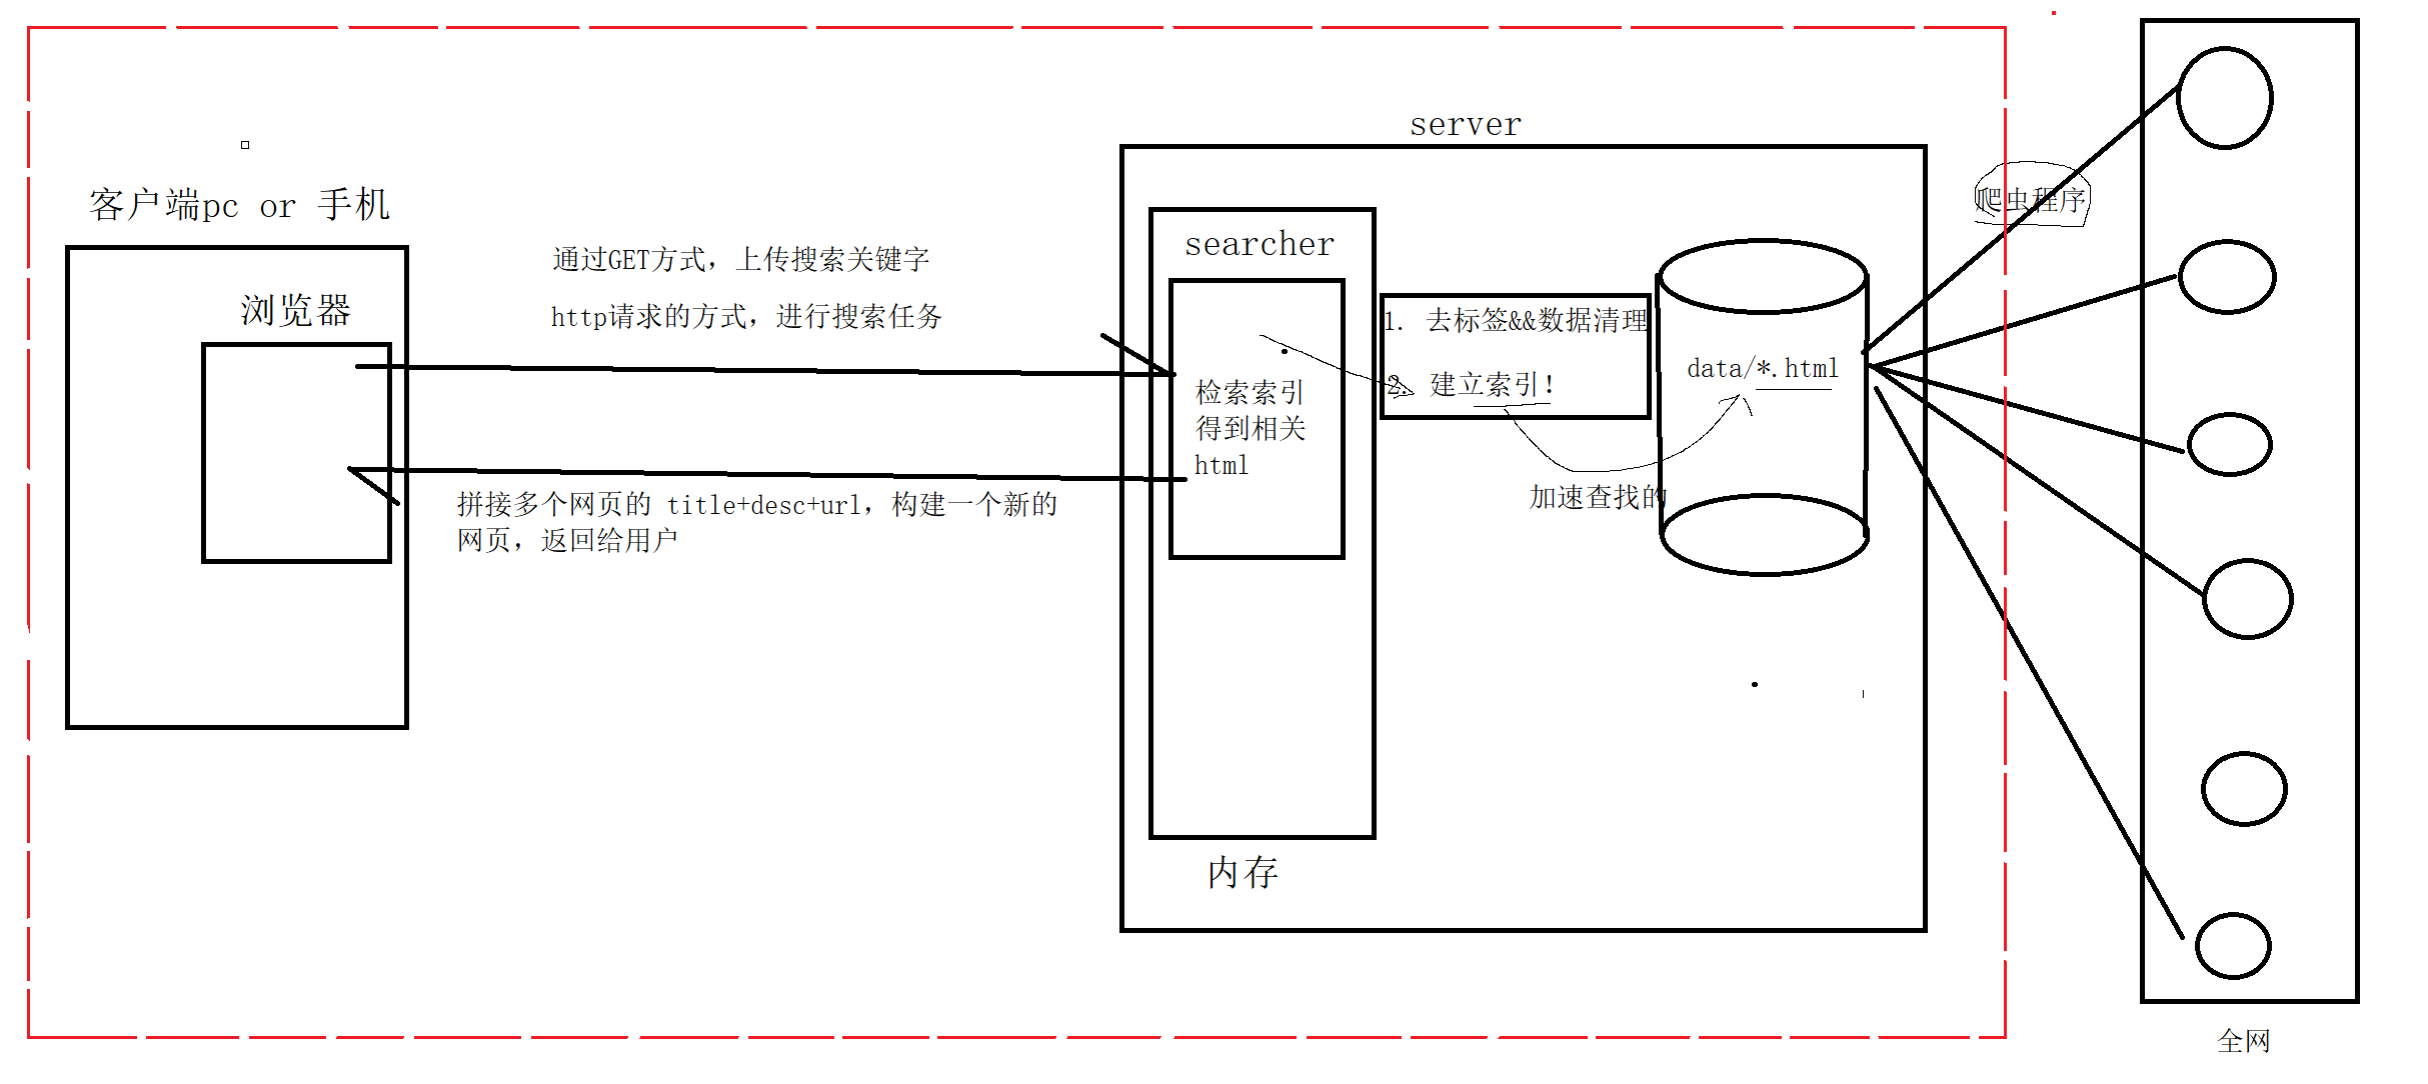
上图是搜索引擎的大致实现过程:
1.搜索引擎首先要从网络上获取数据
2.对数据进行处理,将构建的索引放到内存中
3.用户输入要搜索的内容,内容会通过网络传给服务器
4.服务器通过用户输入的内容和先前建立的索引找到相关的内容
5.服务器将所有相关内容的网址和标题等数据整合到一个网页中,将整合出的网页返回给用户
6.用户看到搜索出的内容
所以,我们实现搜索引擎,基本上就是从这几步上逐步进行实现
2.2 正倒排索引
正排索引就是用文档的ID找文档的内容,类似于字符指针数组,数组的每一项都对应着一个文档的内容的字符串,我们用文档ID当作数组下标就可以找到对应的文档
而倒排索引就是反过来,用文档的内容找文档的ID
比如我们要搜"亚托莉是高性能的",然后网络中的5号文档中有这个内容,那么我们就能获得5号文档的ID,其实也就相当于是unordered_map的key-value的对应,只不过一个key可能对应着多个value
因为网络中可能会有多个网站的内容中有这句话,所以我们会得到多个网页
而搜索引擎在搜索时,其实并不会直接用我们输入的语句进行搜索,它还会多一个步骤------分词
在搜索之前,引擎会先把我们搜索的内容拆分成几个词,然后再逐个词语地进行搜索
比如上面的搜索中,引擎可能会先把这句话拆成:
亚托莉 ,是 ,高性能, 的
也可能是
亚托莉是 , 高性能 , 的
多种情况,然后再逐个词语地进行key-value的匹配
全部词语都匹配完成后,搜索引擎会根据找到的文档的ID,再通过正排索引找到对应的文档,然后读取对应文档的内容,根据词语在文档内容中出现的次数和词语出现位置的权重对每个文档的总权重进行计算,最后排出文档的排列顺序
排出排列顺序后,就会开始构建搜索结果的网页,最后返回给用户搜索结果
2.3 去标签
我们在浏览器网页中按F12,可以打开一个浏览器的控制台,其中能看到浏览器的网页的代码结构
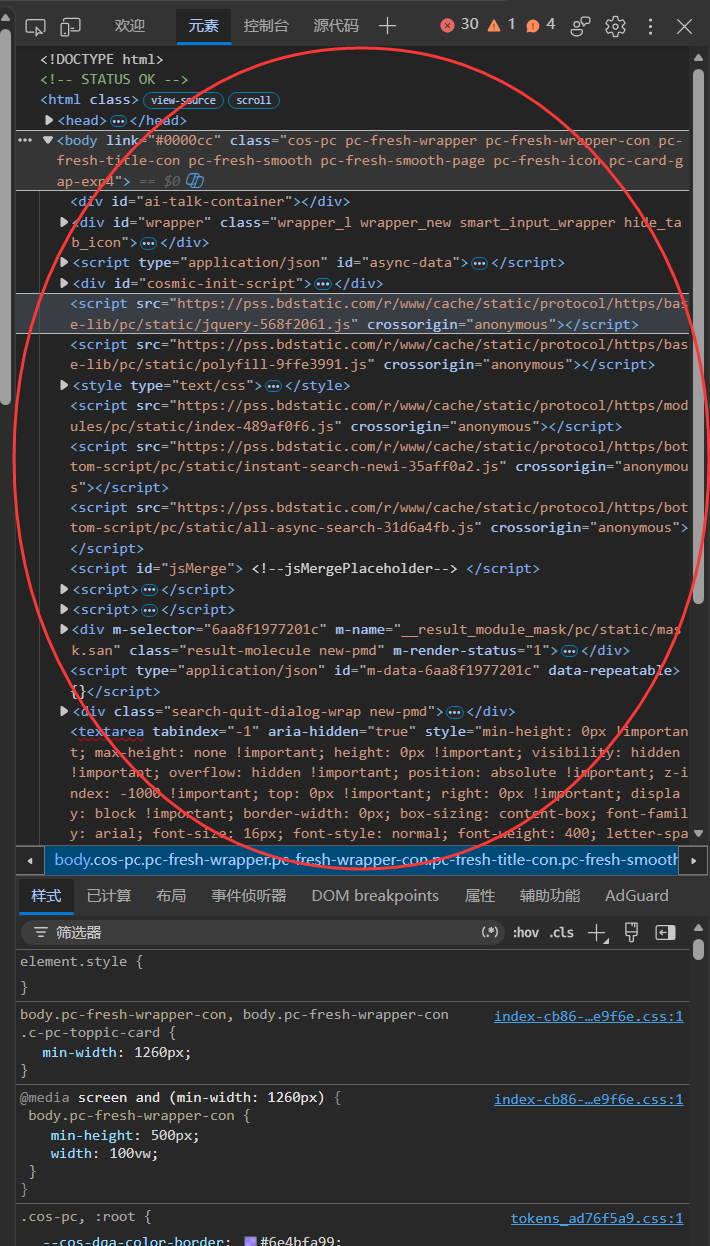
上面圈起来的内容就是浏览器网页的代码结构
我们会发现,代码中有许多<>括起来的内容,这些内容都是浏览器的标签,都是代码内容,并不是我们需要的数据内容,我们需要的所有数据内容都在两个<>之间,也就是:
<a>这是数据</a>
也就是上面的"这是数据"这一块
因为之后我们处理完的数据都要放到内存中,也为了加快构建索引的速度,所以我们需要把这部分标签内容全都去掉,只留下浏览器的数据内容,这就是去标签
2.4 boost库的安装
要做一个boost库的搜索引擎,我们需要先下载到boost库的内容,我们可以去这个网站下载:
boost库的版本不需要非常在意,我这里用的是boost1.91.0的版本
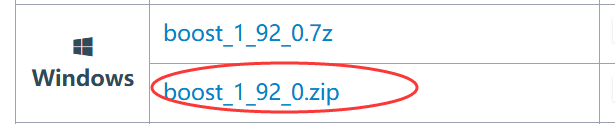
我们下载这个.zip文件
解压打开之后,我们在boost_1.92.0/boost/doc/html这个文件夹中可以看到里面有很多个html文件
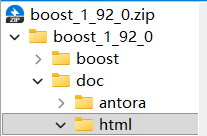
我们随便打开一个:
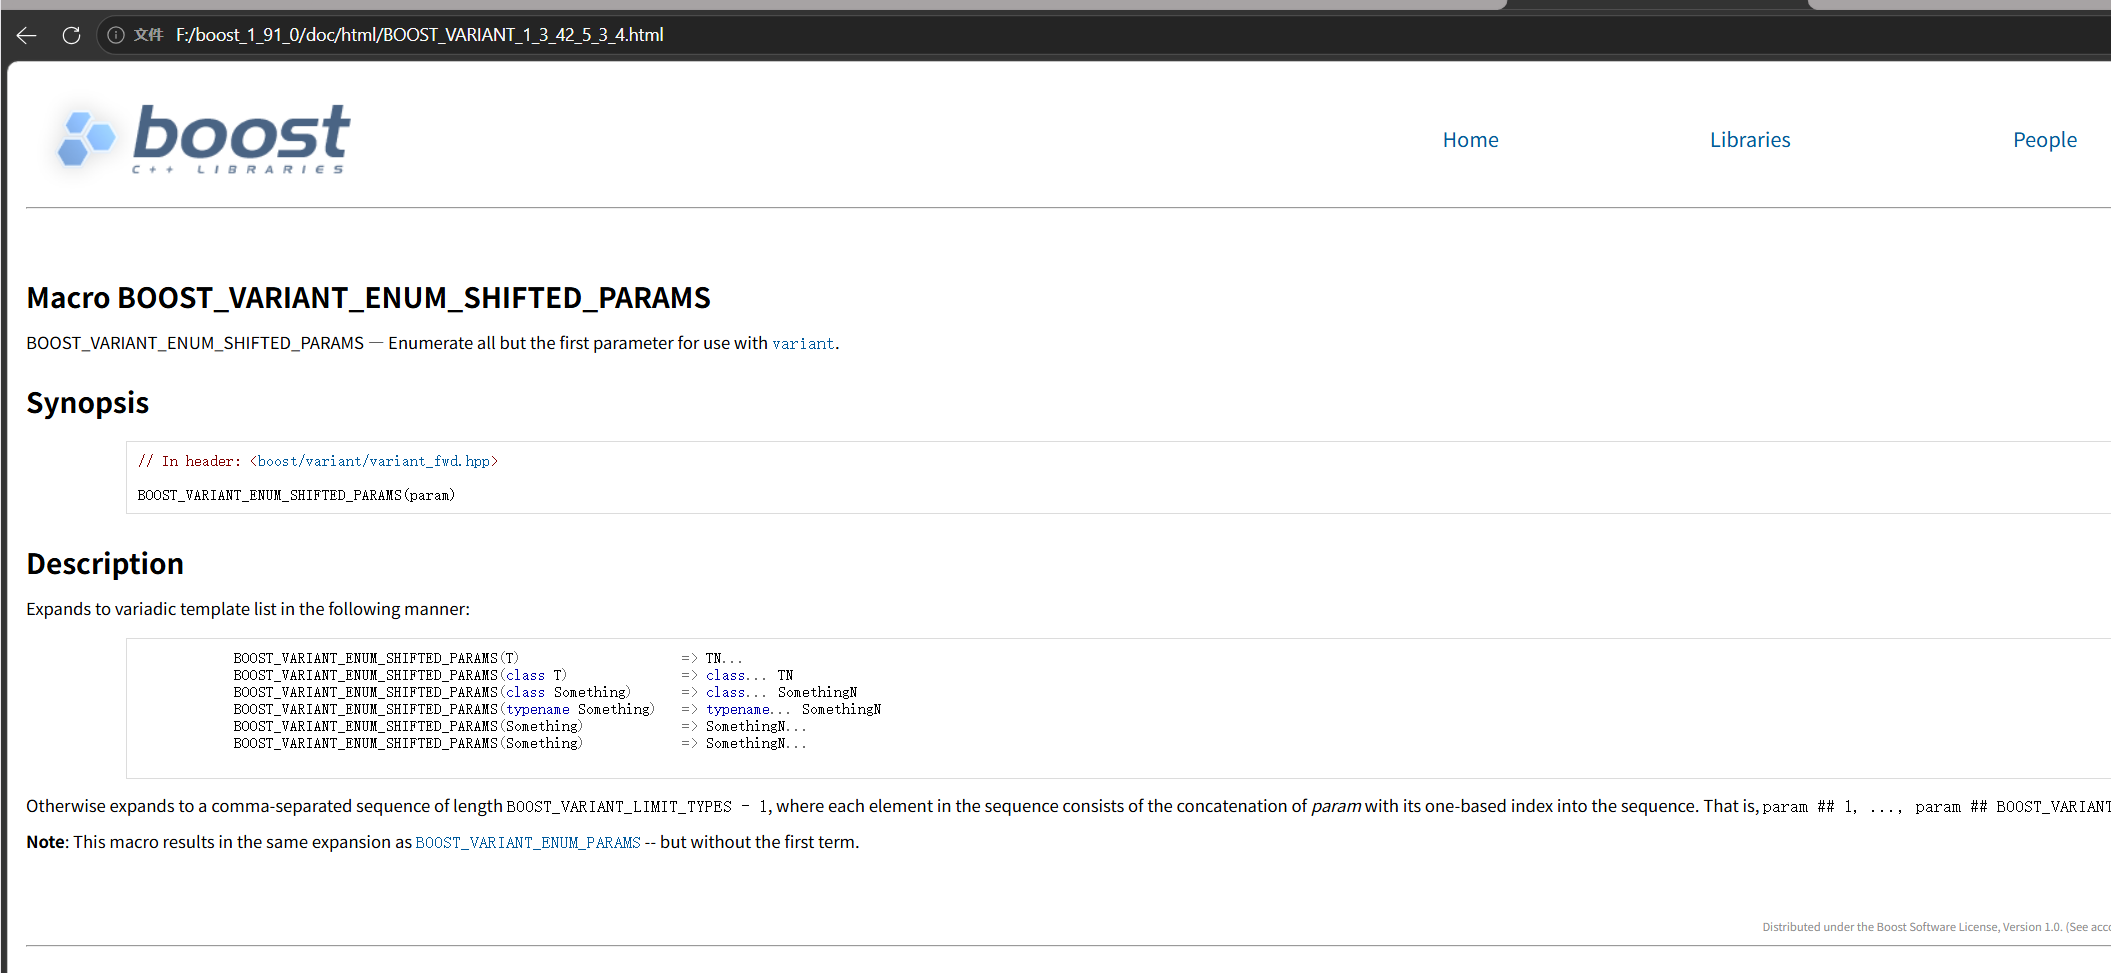
可以看到,我们直接打开了boost库的网页
接下来我们在Linux服务器中新建一个项目文件夹boost_searcher
然后把这个压缩包放到我们的项目文件夹中并解压,之后就可以删掉这个.zip文件了
这样我们就成功的把boost库下载到了Linux服务器中
三、实现
3.1 去标签的实现
前面说过,为了节省内存等原因,我们需要对boost库的网页进行去标签
那么我们应该怎么去呢?
首先,我们要知道我们想要保留什么信息:
1.标题
2.内容
3.url
为了在网页中体现出标题和内容,我们肯定是要区分开这三个东西的,所以其实网页代码中也明确的指出了标题的标签:
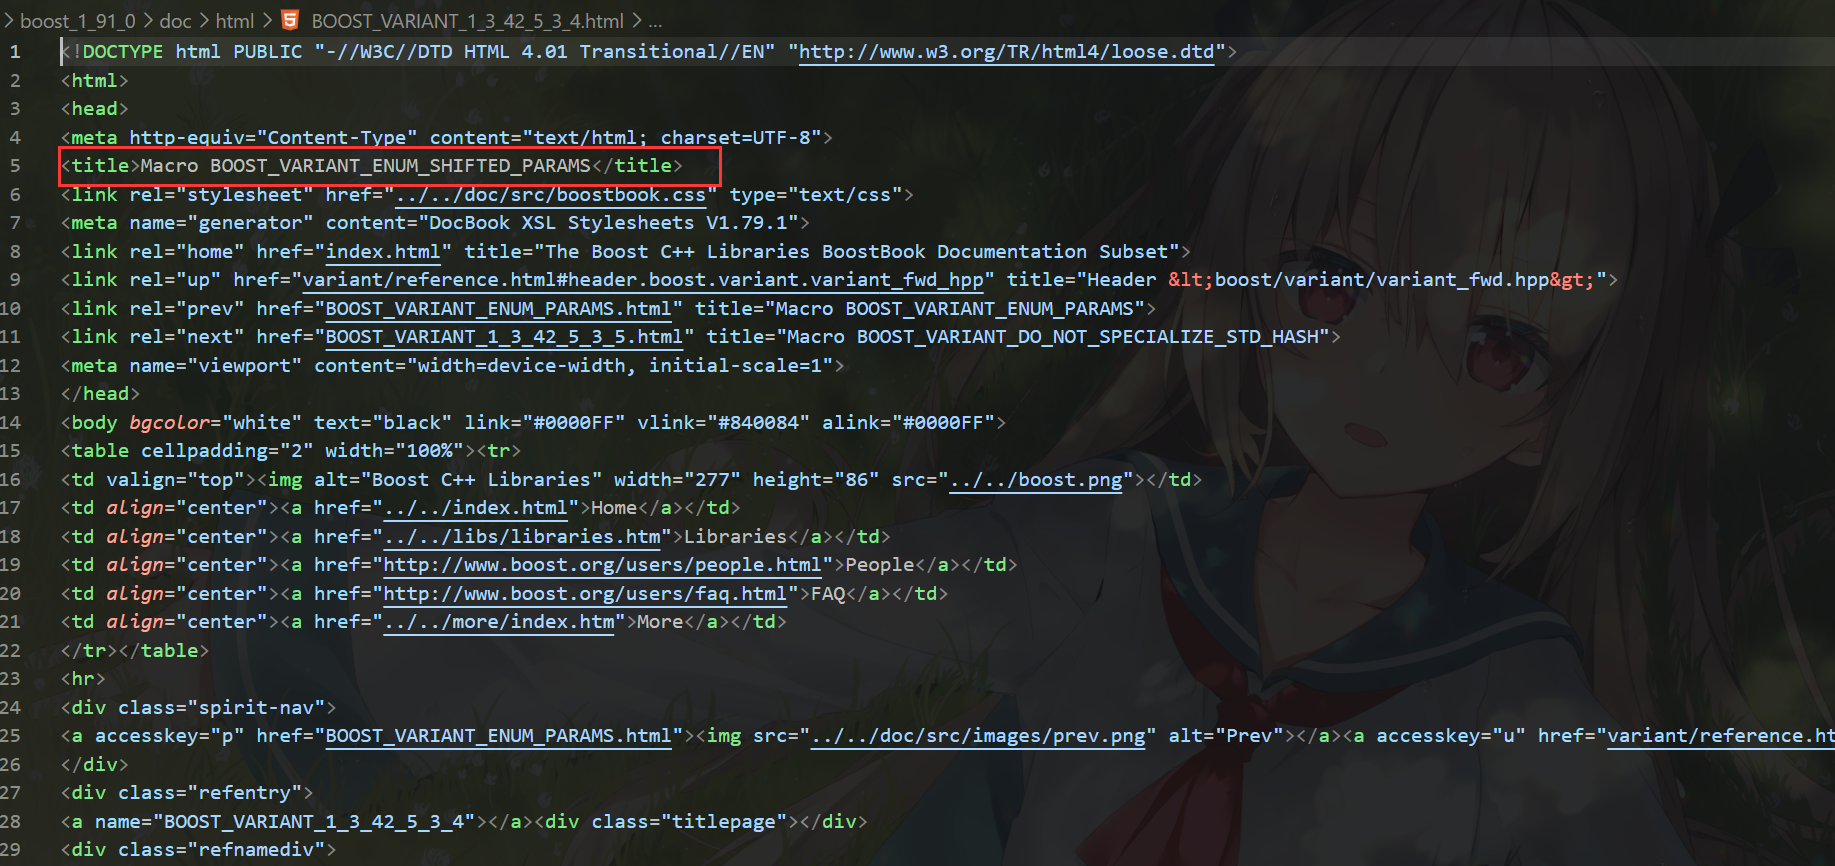
这里被<title></title>包住的内容就是我们要的标题了
所以,我们可以在去标签时,专门识别一下这个标签,并给标题和内容做出区分
并且,虽然我们自己看内容的时候分行比较好看,但是对于计算机来说,数据的排列对其读取数据并没有什么影响,所以我们可以直接把所有内容全都保存在一行,并且把所有去标签完成的文件的内容也都保存到一个文件中
而为了便于我们写代码读取数据,我们可以把一个文档分成一行,以便于直接用一句getline函数直接读取整个文档,而标题、内容和url之间用一个 /3 隔开用于区分
而在
接下来我们可以开始写代码了:
我们创建一个parser.cc文件用来写去标签代码
而处理文件也要分成三部:
1.将每个html文件名带着路径一起保存到file_list中
2.按照file_list读取每个文件的内容,并进行解析
3.把解析完毕的各个文件内容写入到output
我们新建一个data文件夹用来保存数据
再在里面新建input文件夹放置原始数据
再在data文件夹新建一个raw_html文件夹保存处理好的数据,顺便创建好raw.txt保存数据用
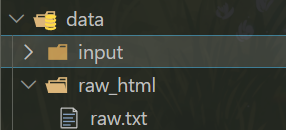
我们把boost库的整个html文件夹的内容复制到自己新建的input文件夹中
之后在代码中创建保存这两个路径的全局变量:
const std::string src_path="data/input";
const std::string output="data/raw_html/raw.txt";
下面就是对数据的处理了:
我们先写好main函数:
cpp
int main()
{
    std::vector<std::string> files_list;
    //将每个html文件名带着路径一起保存到file_list中
    if(!EnumFile(src_path,&files_list)){
        std::cerr<<"enum file name error!"<<std::endl;
        return 1;
    }

    //按照file_list读取每个文件的内容,并进行解析
    if(!ParseHtml(files_list,&results)){
        std::cerr<<"parse html error!"<<std::endl;
        return 2;
    }
    //把解析完毕的各个文件内容写入到output
    if(!SaveHtml(results,output)){
        std::cerr<<"save html error!"<<std::endl;
        return 3;
    }
    return 0;
}
1.将每个html文件名带着路径一起保存到file_list中
下面实现EnumFile函数:
cpp
bool EnumFile(const std::string &src_path,std::vector<std::string>* files_list){
    namespace fs = boost::filesystem;
    fs::path root_path(src_path);

    //判断路径是否存在
    if(!fs::exists(root_path)){
        std::cerr<<src_path<<"no exists"<<std::endl;
        return false;
    }

    fs::recursive_directory_iterator end;
    for(fs::recursive_directory_iterator iter(root_path); iter!=end;iter++){
        //判断是否是普通文件
        if(!fs::is_regular_file(*iter)){
            continue;
        }
        //判断后缀
        if(iter->path().extension()!=".html"){
            continue;
        }

       // std::cout<<"debug:"<<iter->path().string()<<std::endl;
        //当前路径是合法的,以html结束的普通网页文件
        files_list->push_back(iter->path().string());  //将所有带路径的html保存到files_list
    }
    return true;
}
这里我们用到了boost的filesystem库,我们把自己的路径转换成了boost库的专用路径,并且跨平台时也会跟着平台自动转换路径分隔符
这里我们需要包含#include<boost/algorithm/string.hpp>这个头文件,这就需要我们也把boost库放到项目目录中,或者是真正的把boost库安装到我们的系统中,直接使用下面的命令就好:
sudo apt update
安装完整boost库,头文件+所有二进制库
sudo apt install libboost-all-dev
之后先判断路径是否存在,exists()函数也是boost库函数,可以用来判断路径是否存在
下面定义一个递归目录迭代器(也是boost的)我们不给他赋值默认会创建一个默认构造的空迭代器对象,之后再for循环中再构建一个迭代器,让他从最开始的目录开始往下找,一直找到最后一个文件 如果后面没有文件了,iter++就会变成默认构造的空迭代器对象,也就是会==end,然后循环结束
循环中,先判断文件是否为普通文件,因为也有可能是文件夹,但是文件夹我们不要
之后再判断文件后缀是否为.html,我们只要html文件的内容
之后,直接把文件的路径保存到files_list中,循环结束后我们就获取了所有合法文件的路径
2.按照file_list读取每个文件的内容,并进行解析
接下来是ParseHtml函数,用来读取每个文件的内容,并进行解析
这里我们就要对文件内容进行处理了,所以我们需要保存处理的结果,也就是需要创建一个容器来保存,这里我们可以创建一个结构体来保存文件的信息:
typedef struct DocInfo{
std::string title; //文档标题
std::string content; //文档内容
std::string url; //官网urlp
}DocInfo_t;
用这个结构体来保存文档的标题、内容和url,以便于之后将处理好的信息写入raw.txt文件进行保存
在调用ParseHtml函数前先创建一个结构体的vector来用于保存数据:
std::vector<DocInfo_t> results;
而文件的处理我们也可以分为几步:
1.读取文件
2.解析文件,提取title
3.提取content
4.提取路径,构建url
最后保存好内容
所以我们再次封装几个函数来进行操作:
cpp
bool ParseHtml(std::vector<std::string>& files_list,std::vector<DocInfo_t>* results){
    for(const std::string &file :files_list){
        //读取文件
        std::string result;
        if(!ns_util::FileUtil::ReadFile(file,&result)){
            continue;
        }
        DocInfo_t doc;
        //解析文件,提取title
        if(!ParseTitle(result,&doc.title)){
            continue;
        }
        //提取content
        if(!ParseContent(result,&doc.content)){
            continue;
        }
        //提取路径,构建url
        if(!ParseUrl(file,&doc.url)){
            continue;
        }

        results->push_back(std::move(doc));

        //for debug
        //ShowDoc(doc);

    }


    return true;
}
因为也是有多个文件,所以我们使用for循环进行,而如果一个文件的处理在某一步时出错,我们就直接跳过这个文件的处理,所以直接continue,在处理完一个文件后,我们也可以先进行调试,看看写的代码是否有问题
1.读取文件
下面,我们再创建一个util.hpp文件,用来保存一些工具类的函数
我们把boost库的头文件的包含也转移到这里面
并且在里面创建一个ns_util命名空间,防止有重名函数的出现,并且放到FileUtil类中进行分类
cpp
namespace ns_util{
    class FileUtil{
        public:
            static bool ReadFile(const std::string &file_path,std::string *out){
                std::ifstream in(file_path,std::ios::in);
                if(!in.is_open()){
                    std::cerr<<"open file "<<file_path<<"error"<<std::endl;
                    return false;
                }
                std::string line;
                while(std::getline(in,line)){
                    *out += line;
                }

                in.close();
                return true;
            }
    };
}
这就是一个读取文件的函数,我们把文件的所有内容读取,读取的结果通过输出型参数返回,然后在下面的函数中继续使用,来处理文件的数据
2.解析文件,提取title
下面通过<title></title>这两个标签来找到标题(这个函数直接放在parse.cc中):
cpp
static bool ParseTitle(const std::string &file,std::string* title){
    std::size_t begin=file.find("<title>");
    if(begin == std::string::npos){
        return false;
    }
    std::size_t end=file.find("</title>");
    if(end == std::string::npos){
        return false;
    }
    begin += std::string("<title>").size();
    *title = file.substr(begin,end-begin);

    if(begin > end){
        return false;
    }
    return true;
}
直接使用find()函数寻找
依旧是使用输出型参数直接写入结构体doc.title中
3.提取content
cpp
static bool ParseContent(const std::string &file,std::string* content){
    //去标签,基于一个简易的状态机
    enum status{
        LABLE,
        CONTENT
    };

    enum status s=LABLE;
    for( char c:file){
        switch(s){
            case LABLE:
                if(c == '>') s = CONTENT;
                break;
            case CONTENT:
                if(c == '<') s=LABLE;
                else{
                    //不想要原始文件里的\n,要用\n作为html解析之后的分隔符
                    if(c == '\n') c=' ';
                    content->push_back(c);
                }
                break;
            default:
                break;
        }
    }
    return true;
}
这里使用一个简易的状态机来判断当前是否在内容中
当遇到<时,说明进入标签,当遇到>时,说明出标签范围,在出标签后,遇到的除<之外的字符就都是我们想要的数据内容了
4.提取路径,构建url
我们打开一个boost官网的库的介绍:
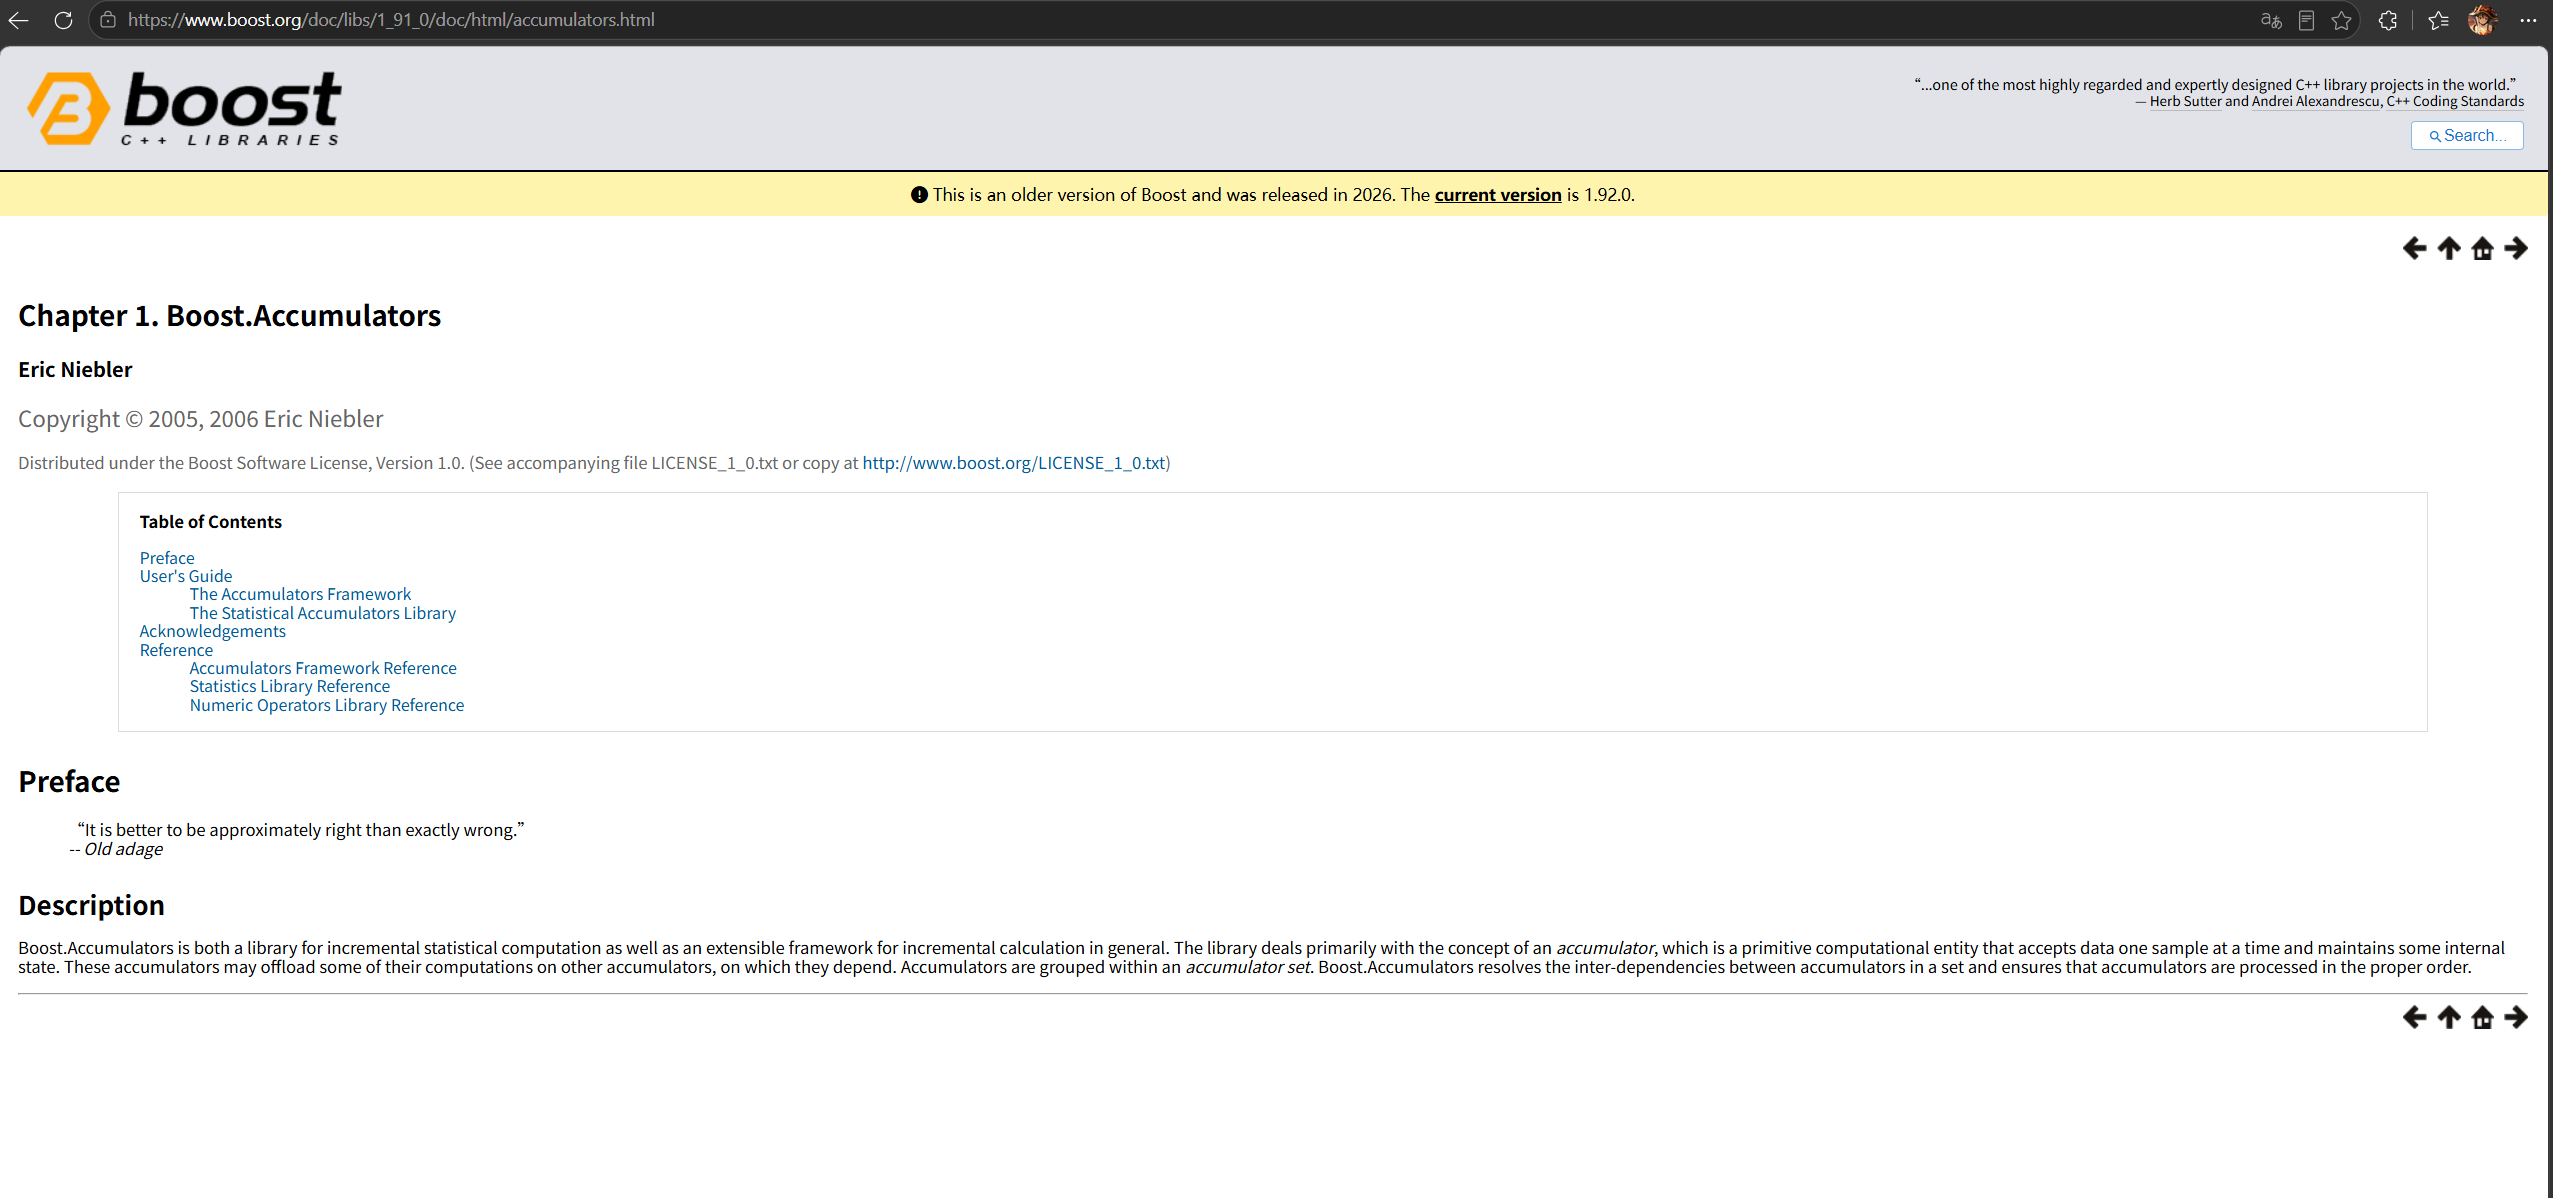
可以看到,这个网站的路径是https://www.boost.org/doc/libs/1_91_0/doc/html/库的名字.html
所以,我们的url就可以通过这个规律来进行构建:
cpp
static bool ParseUrl(const std::string &file_path ,std::string *url){
    std::string url_head = "https://www.boost.org/doc/libs/1_91_0/doc/html";
    std::string url_tail = file_path.substr(src_path.size());

    *url = url_head + url_tail;
    return true;
}
5.保存内容
这样,我们就完成了一个库文件的处理,然后,接下来只要:
results->push_back(std::move(doc));
就能把处理的完的文件暂时保存到内存中的vector中了
之后for循环完成所有的文件就完成了所有文件的处理
3.把解析完毕的各个文件内容写入到output
完成了文件的处理,为了之后构建索引的工作,我们需要把处理完的内容从内存中保存到硬盘中,以便于之后的数据读取
并且,我们需要按照前面说的格式进行保存,才能方便我们之后的读取:
1.文件之间用\n间隔
2.标题、内容和url之间用 \3 间隔
cpp
bool SaveHtml(std::vector<DocInfo_t>& results,const std::string& output){
#define SEP '\3'
     //二进制方式进行写入
    std::ofstream out(output,std::ios::out | std::ios::binary);
    if(!out.is_open()){
        std::cerr<<"open "<<output<<" failed"<<std::endl;
        return false;
    }

    //文件写入
    for(auto &item : results){
        std::string out_string;
        out_string = item.title;
        out_string += SEP;
        out_string += item.content;
        out_string += SEP;
        out_string += item.url;
        out_string += '\n';

        out.write(out_string.c_str(),out_string.size());
    }
    out.close();
    return true;

}
因为正常的文本模式可能会出问题:
- 文本模式(不加 binary) :C++ 标准库会做换行符自动转换
- Windows:写
'\n'(0x0A) → 自动变成\r\n(0x0D 0x0A)两个字节。
- Windows:写
- 二进制模式 (
ios::binary) :原样字节输出,完全不做任何字符转义、换行替换,字节是什么就写什么到磁盘。
所以我们要用二进制方式进行写入
4.总结
这样,我们就完成了整个去标签的流程,接下来我们该进行的是索引模块的编写
parse.cc完整代码:
cpp
#include <iostream>
#include <fstream>
#include <string>
#include <vector>
#include <boost/filesystem.hpp>
#include "util.hpp"

//放着所有html网页的目录
const std::string  src_path="data/input";
const std::string output="data/raw_html/raw.txt";

typedef struct DocInfo{
    std::string title; //文档标题
    std::string content; //文档内容
    std::string url;   //官网urlp
}DocInfo_t;

bool EnumFile(const std::string &src_path,std::vector<std::string>* list);
bool ParseHtml(std::vector<std::string>& files_list,std::vector<DocInfo_t>* results);
bool SaveHtml(std::vector<DocInfo_t>& results,const std::string& output);

int main()
{
    std::vector<std::string> files_list;
    //将每个html文件名带着路径一起保存到file_list中
    if(!EnumFile(src_path,&files_list)){
        std::cerr<<"enum file name error!"<<std::endl;
        return 1;
    }

    //按照file_list读取每个文件的内容,并进行解析
    std::vector<DocInfo_t> results;
    if(!ParseHtml(files_list,&results)){
        std::cerr<<"parse html error!"<<std::endl;
        return 2;
    }
    //把解析完毕的各个文件内容写入到output
    if(!SaveHtml(results,output)){
        std::cerr<<"save html error!"<<std::endl;
        return 3;
    }
    return 0;
}

bool EnumFile(const std::string &src_path,std::vector<std::string>* files_list){
    namespace fs = boost::filesystem;
    fs::path root_path(src_path);

    //判断路径是否存在
    if(!fs::exists(root_path)){
        std::cerr<<src_path<<"no exists"<<std::endl;
        return false;
    }

    fs::recursive_directory_iterator end;
    for(fs::recursive_directory_iterator iter(root_path); iter!=end;iter++){
        //判断是否是普通文件
        if(!fs::is_regular_file(*iter)){
            continue;
        }
        //判断后缀
        if(iter->path().extension()!=".html"){
            continue;
        }

       // std::cout<<"debug:"<<iter->path().string()<<std::endl;
        //当前路径是合法的,以html结束的普通网页文件
        files_list->push_back(iter->path().string());  //将所有带路径的html保存到files_list
    }
    return true;
}


static bool ParseTitle(const std::string &file,std::string* title){
    std::size_t begin=file.find("<title>");
    if(begin == std::string::npos){
        return false;
    }
    std::size_t end=file.find("</title>");
    if(end == std::string::npos){
        return false;
    }
    begin += std::string("<title>").size();
    *title = file.substr(begin,end-begin);

    if(begin > end){
        return false;
    }
    return true;
}
static bool ParseContent(const std::string &file,std::string* content){
    //去标签,基于一个简易的状态机
    enum status{
        LABLE,
        CONTENT
    };

    enum status s=LABLE;
    for( char c:file){
        switch(s){
            case LABLE:
                if(c == '>') s = CONTENT;
                break;
            case CONTENT:
                if(c == '<') s=LABLE;
                else{
                    //不想要原始文件里的\n,要用\n作为html解析之后的分隔符
                    if(c == '\n') c=' ';
                    content->push_back(c);
                }
                break;
            default:
                break;
        }
    }
    return true;
}
static bool ParseUrl(const std::string &file_path ,std::string *url){
    std::string url_head = "https://www.boost.org/doc/libs/1_91_0/doc/html";
    std::string url_tail = file_path.substr(src_path.size());

    *url = url_head + url_tail;
    return true;
}


//for debug
// void ShowDoc(const DocInfo_t &doc)
// {
//     std::cout<<"title: "<< doc.title << std::endl;
//     std::cout << "content: "<<doc.content << std::endl;
//     std::cout << "url: "<<doc.url << std::endl;
// }


bool ParseHtml(std::vector<std::string>& files_list,std::vector<DocInfo_t>* results){
    for(const std::string &file :files_list){
        //读取文件
        std::string result;
        if(!ns_util::FileUtil::ReadFile(file,&result)){
            continue;
        }
        DocInfo_t doc;
        //解析文件,提取title
        if(!ParseTitle(result,&doc.title)){
            continue;
        }
        //提取content
        if(!ParseContent(result,&doc.content)){
            continue;
        }
        //提取路径,构建url
        if(!ParseUrl(file,&doc.url)){
            continue;
        }

        results->push_back(std::move(doc));

        //for debug
        //ShowDoc(doc);
    }


    return true;
}

bool SaveHtml(std::vector<DocInfo_t>& results,const std::string& output){
#define SEP '\3'
     //二进制方式进行写入
    std::ofstream out(output,std::ios::out | std::ios::binary);
    if(!out.is_open()){
        std::cerr<<"open "<<output<<" failed"<<std::endl;
        return false;
    }

    //文件写入
    for(auto &item : results){
        std::string out_string;
        out_string = item.title;
        out_string += SEP;
        out_string += item.content;
        out_string += SEP;
        out_string += item.url;
        out_string += '\n';

        out.write(out_string.c_str(),out_string.size());
    }
    out.close();
    return true;

}
3.2 编写建⽴索引的模块 Index
3.2.1 正排索引
我们先创建index.hpp文件来写代码
首先,我们需要先对要索引的数据进行获取,也就是读取我们之前保存的raw.txt中已经处理好的数据
而为了保存读取到的数据,我们要定义一个结构体来保存我们的数据:
namespace ns_index{
struct DocInfo{
std::string title; //标题
std::string content; //去标签内容
std::string url; //官网文档url
uint64_t doc_id; //文档的ID
};
}
我们最终的目的肯定是要构建倒排索引,但是在这之前,我们需要先构建出正排索引,之后再用正排索引构建倒排索引
从这里也可以看出,正排索引的构建其实并不需要我们自己调用,他只是构建倒排索引的一步,所以这个函数可以直接写成私有成员函数:
cpp
 class Index{
 private:
            std::vector<DocInfo> forward_index;
            DocInfo* BuildForwardIndex(const std::string &line){
                //解析line,字符串切分
                //line-> 3个string:title content url
                const std::string sep = "\3";
                std::vector<std::string> results;
                ns_util::StringUtil::Split(line , &results,sep);
                if(results.size() != 3){
                    return nullptr;
                }

                //字符串进行填充到DocInfo
                DocInfo doc;
                doc.title = results[0]; //title
                doc.content = results[1];//content
                doc.url = results[2];   //url
                doc.doc_id = forward_index.size(); //先保存id再插入,对应id就是当前doc在vector中的下标
                //插入到正排索引的vector
                forward_index.push_back(std::move(doc));
                return &forward_index.back();  返回新建好的元素用来创建倒排索引
            }
};
这里有需要在util.hpp中封装一个对字符串处理的工具函数:
cpp
class StringUtil{
        public:
            static void Split(const std::string& target,std::vector<std::string>* out,const std::string& sep){
                //boost split
                boost::split(*out , target, boost::is_any_of(sep),boost::token_compress_on);

            }
这个boost函数可以用指定的字符切分字符串
这样,我们就创建好了正排索引
3.2.2 倒排索引
接下来就是倒排索引了
因为一个词可能会找到多个对应的文档,所以我们需要给一个词构建一个单独的结构体来存储其对应的所有文档,这个结构体就叫倒排拉链
struct InvertedElem{
uint64_t doc_id; //文档编号
std::string word; //对应的关键词
int weight; //总权重
};
typedef std::vector<InvertedElem> InvertedList;
当我们创建好每一个词的倒排拉链,再把这些倒排拉链和词用一个unordered_map一一对应起来,我们就构建好了倒排索引
std::unordered_map<std::string,InvertedList> inverted_index;
下面我们就要通过这两个结构体和上面构建的正排索引来构建倒排索引:
cpp
bool BuildIndex(const std::string &input){
            //打开文件
            std::ifstream in(input, std::ios::in | std::ios::binary);
            if(!in.is_open()){
                std::cerr<<"sorry, "<<input<<" open error!"<<std::endl;
                return false;
            }

            //读取文档内容
            std::string line;
            int count = 0;
            while(std::getline(in,line)){
                //构建正排索引
                DocInfo* doc = BuildForwardIndex(line);
                if(doc == nullptr){
                    std::cerr<<"build "<<line<<" error!" <<std::endl;
                    continue;
                }
                //构建倒排索引
                BuildInvertedIndex(*doc);
                 ++count;
                if(count %100 == 0){
                    //std::cout<<"当前已经建立的索引文档"<<count<<std::endl;
                    LOG(NORMAL, "当前已经建立的索引文档"+std::to_string(count));
                }
            }

            return true;
        }
这里我们先打开文件,然后读取一行内容,也就是一个文档的内容
先去构建正排索引,然后再通过正排索引用BuildInvertedIndex函数构建出倒排索引
接下来我们来编写BuildInvertedIndex函数:
首先,为了之后给文档的显示顺序排序,我们需要获取文档的权重
但是我们现在获取的文档只是一长串字符串,所以我们首先要对文档进行分词
这里我们可以使用cppjieba库的分词函数,接下来我们了解一下怎么下载jieba库:
其实我们只要在服务器里输入git命令:
git clone https://github.com/yanyiwu/cppjieba.git
就能下载到jieba库了,但是服务器可能因为网络问题下不下来,那么我们就需要自己去下载:
我们去github的这个链接:GitHub - yanyiwu/cppjieba: "结巴"中文分词的C++版本 · GitHub
点开code按钮后点击Download ZIP
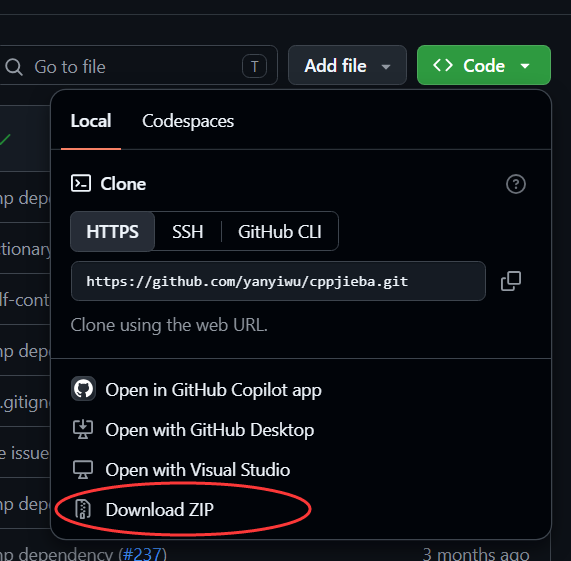
浏览器就会开始下载这个.zip文件了,下载完成后,使用和前面下载boost库同样的方法就可以把jieba库下载到我们的服务器中了,我们这里建立一个软连接到项目目录中,当然也可以直接把cppjieba这个文件夹放到项目目录中
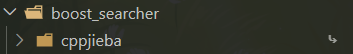
接下来我们在util.hpp中引入#include"cppjieba/Jieba.hpp"这个库,并封装一层函数用来实现我们需要的分词功能:
cpp
const char* const DICT_PATH = "./dict/jieba.dict.utf8";
    const char* const HMM_PATH = "./dict/hmm_model.utf8";
    const char* const USER_DICT_PATH = "./dict/user.dict.utf8";
    const char* const IDF_PATH = "./dict/idf.utf8";
    const char* const STOP_WORD_PATH = "./dict/stop_words.utf8";
class JiebaUtil{
        private:
            static cppjieba::Jieba jieba;
        public:
            static void CutString(const std::string &src, std::vector<std::string> *out){
                jieba.CutForSearch(src,*out);
            }
    };
    cppjieba::Jieba JiebaUtil::jieba(DICT_PATH,
                HMM_PATH,
                USER_DICT_PATH,
                IDF_PATH,
                STOP_WORD_PATH);
这里下面的初始化内容是给jieba一些参数:
调用 cppjieba::Jieba 的多参数构造函数,传入 5 个词典文件路径,初始化分词器
DICT_PATH:主词典HMM_PATH:隐马尔可夫模型文件(识别未登录新词)USER_DICT_PATH:用户自定义词典IDF_PATH:idf 词典(用于关键词提取)STOP_WORD_PATH:停用词词典
下面,我们回到index.hpp
为了计算权重,我们需要创建两个变量来保存关键词出现的次数:
struct word_cnt{
int title_cnt;
int content_cnt;
word_cnt():title_cnt(0),content_cnt(0){}
};
std::unordered_map<std::string, word_cnt> word_map;//暂存词频的映射表
分为标题和内容两个,因为标题的优先级一定是大于内容的
当然,这个规则是我们自己决定的,所以也可以自己更改
我们把词语对应的词频统计放到一个unordered_map中,方便之后统一对权重进行计算
下面就是分别对标题和内容的分词和词频统计了:
//title的分词
std::vector<std::string> title_words;
ns_util::JiebaUtil::CutString(doc.title,&title_words);
//title的词频统计
for(auto &s: title_words){
boost::to_lower(s); //分词统一转换成小写
word_maps.title_cnt++;
}
在统计词频时,我们需要把所有大写字母都转换成小写来统计,便于之后的权重计算,这里也可以用boost库中的一个函数进行转换
//对content的分词
std::vector<std::string> content_words;
ns_util::JiebaUtil::CutString(doc.content,&content_words);
//content的词频统计
for(auto &s : content_words){
boost::to_lower(s); ////分词统一转换成小写
word_maps.content_cnt++;
}
统计好词频信息,我们就要真正开始构建倒排索引了:
首先,我们要创建好倒排拉链的一个元素,也就是一个词和其对应文档的关系
我们从前面创建的word_map中取一个词进行构建 item:
for(auto &word_pair :word_map){
InvertedElem item;
item.doc_id = doc.doc_id;
item.word = word_pair.first;
item.weight = X*word_pair.second.title_cnt + Y*word_pair.second.content_cnt;
}
之后,我们直接用这个词去构建倒排拉链,也就是:
//创建倒排拉链
InvertedList &inverted_list = inverted_indexword_pair.first;
inverted_list.push_back(std::move(item));
当我把word_pair.first传入inverted_index中时,如果这个哈希表中原来没有这个词的索引,那么就会创建这个索引并返回key-value中value值的引用
如果已经有了这个元素,那么就直接返回value的引用
我们拿到的这个引用就是倒排索引中的一个倒排拉链了
之后我们只要直接在这个拉链中插入一个item,因为倒排索引是对象的私有成员变量,所以这个item,也就是词和文档的对应关系就被保存到了倒排索引中,比如:
这里我word_pair的key-value是:亚托莉-title = 1 ;content = 2;
那么我们的word_pair.first就是亚托莉,
当我们执行 inverted_indexword_pair.first;时,就是 inverted_index亚托莉;
如果inverted_index中原来还没有亚托莉这个key,那么就会创建一个key-value的映射关系:
亚托莉-std::vector<InvertedElem>
并且返回这个std::vector<InvertedElem>的引用
我们拿到这个引用之后,向这个std::vector<InvertedElem>中插入我们前面已经创建好的InvertedElem对象
又因为已经创建好的inverted_index是一个成员变量,所以就直接向当前对象的成员变量的倒排拉链中添加了一个元素
因为我们是逐个文档一次构建倒排索引的:
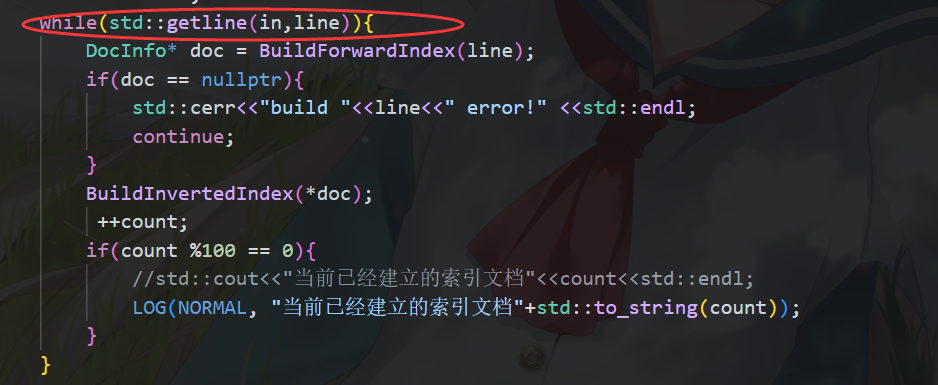
所以等到下个文档,如果再次出现了"亚托莉"这个关键词,
就又会重复一次上面的过程,只不过这次不需要创建倒排拉链了,因为上一次已经创建好,这次我们直接获得"亚托莉"这个关键词的倒排拉链,直接向里面插入InvertedElem对象就好了
知道所有文档全部循环完,也就是while循环结束,所有文档的倒排索引就构建完成了
BuildInvertedIndex完整代码:
cpp
bool BuildInvertedIndex(const DocInfo& doc){
                //word->倒排拉链
                struct word_cnt{
                    int title_cnt;
                    int content_cnt;

                    word_cnt():title_cnt(0),content_cnt(0){}
                };
                std::unordered_map<std::string, word_cnt> word_map;//暂存词频的映射表

                //title的分词
                std::vector<std::string> title_words;
                ns_util::JiebaUtil::CutString(doc.title,&title_words);
                //title的词频统计
                for(auto &s: title_words){
                    boost::to_lower(s);  //分词统一转换成小写
                    word_map[s].title_cnt++;
                }

                //对content的分词
                std::vector<std::string> content_words;
                ns_util::JiebaUtil::CutString(doc.content,&content_words);
                //content的词频统计
                for(auto &s : content_words){
                    boost::to_lower(s);  ////分词统一转换成小写
                    word_map[s].content_cnt++;
                }

#define X 10
#define Y 1
                for(auto &word_pair :word_map){
                    InvertedElem item;
                    item.doc_id = doc.doc_id;
                    item.word = word_pair.first;
                    item.weight = X*word_pair.second.title_cnt + Y*word_pair.second.content_cnt;
                     //创建倒排拉链
                    InvertedList &inverted_list = inverted_index[word_pair.first];
                    inverted_list.push_back(std::move(item));
                }
                return true;
            }
3.3 编写搜索引擎模块 Searcher并完善index.hpp
3.3.1 代码框架
构建完倒排索引,我们来进行搜索引擎模块的编写
我们刚才只是编写完成了文档的查找部分,但是搜索引擎不止有查找这一个部分需要完成,我们还需要编写搜索引擎获取搜索字符串、处理字符串、对文档进行排序等代码
我们先来完成一个基础的代码框架:
#include "index.hpp"
namespace ns_searcher
{
class Searcher
{
private:
ns_index::Index *index; // 供系统进⾏查找的索引
public:
Searcher() {}
~Searcher() {}
public:
void InitSearcher(const std::string &input) 12
{
//1. 获取或者创建index对象
// 2. 根据index对象建⽴索引
}
//query: 搜索关键字
// json_string: 返回给⽤⼾浏览器的搜索结果
void Search(const std::string &query, std::string *json_string)
{
// 1.分词:对我们的query进⾏按照searcher的要求进⾏分词
// 2.触发:就是根据分词的各个"词",进⾏index查找
// 3.合并排序:汇总查找结果,按照相关性(weight)降序排序
// 4.构建:根据查找出来的结果,构建json串 -- jsoncpp
}
};
}
3.3.2 初始化Searcher对象
首先,我们要创建出index对象来构建我们的倒排索引
index = ns_index::Index::GetInstance();
// std::cout<<"获取index单例成功"<<std::endl;
static Index* GetInstance(){
if(nullptr == instance){
mtx.lock();
if(nullptr == instance){
instance = new Index();
}
mtx.unlock();
}
return instance;
}
因为我们的Searcher的私有成员变量ns_index::Index *index;只是一个指针,并不会开辟内存空间,所以我们要再写一个函数开辟index的内存空间,也相当于是真正的创建Index对象
这里加锁是为了避免多线程时多次调用GetInstance函数并多次new Index,两次if判断也是:
- 外层 if :
instance != nullptr,直接跳过锁,无锁返回实例。绝大多数情况走这里,避免每次都加锁,提升性能。 - 当
instance == nullptr,进入,加互斥锁mtx.lock()。 - 内层 if(关键!双重检查) :拿到锁以后,再次判断
instance == nullptr。
多线程场景:线程 A、B 同时通过外层 if。A 拿到锁,new 出对象;B 阻塞在 lock。A 释放锁后,B 拿到锁,如果没有内层 if,B 会再次执行
new Index(),就会创建多个对象,破坏单例。内层 if 防止重复 new。
- new 对象,赋值给静态指针
instance,解锁,返回实例。
创建好Index,接下来我们调用BuildIndex函数来构建倒排索引:
index->BuildIndex(input);
// std::cout<<"建立正排和倒排索引成功"<<std::endl;
完整的InitSearcher函数:
cpp
void InitSearcher(const std::string& input){
                //1.获取或者创建index对象
                index = ns_index::Index::GetInstance();
                // std::cout<<"获取index单例成功"<<std::endl;
                LOG(NORMAL,"获取index单例成");
                //2.根据index对象建立索引
                index->BuildIndex(input);
                // std::cout<<"建立正排和倒排索引成功"<<std::endl;
                LOG(NORMAL,"建立正排和倒排索引成功");

            }
3.3.3 搜索函数
接下来,就是Searcher函数了
这个函数要分成四部分进行编写:
1.分词:对我们的query进⾏按照searcher的要求进⾏分词
因为构建索引的时候我们是分词来构建的,为了我们搜索的内容能匹配的上我们构建的索引,我们也必须通过同样的分词规则来处理我们搜索的字符串
std::vector<std::string> words;
ns_util::JiebaUtil::CutString(query,&words);
我们把分出来的词都存到一个vector里,等待之后使用
2.触发:就是根据分词的各个"词",进⾏index查找
先创建一个vector来存储全部的搜索结果:
std::vector<InvertedElemPrint> inverted_list_all;
并且,如果直接用分出来的词去搜索文档,很可能会搜出重复的文档 ,为了防止出现重复文档,我们可以再构建一个unordered_map来解决这个问题:
std::unordered_map<uint64_t,InvertedElemPrint> tokens_map;
下面,我们直接用范围for来对words进行循环,来逐个关键词地查找文档:
for(std::string word :words){
boost::to_lower(word);
ns_index::InvertedList *inverted_list = index->GetInvertedList(word);
if(nullptr == inverted_list){
continue;
}
其中,GetInvertedList是根据关键字string获得倒排拉链的函数:
cpp
InvertedList* GetInvertedList(const std::string &word){
            auto iter = inverted_index.find(word);
            if(iter == inverted_index.end()){
                std::cerr<<word<<" have no InvertedList"<<std::endl;
                return nullptr;
            }
            return &(iter->second);
        }
找到后我们直接返回item,如果没有找到,我们直接continue去搜索下一个关键词
下面,我们可以用和构建倒排索引时类似的原理来避免出现重复文档:
for(const auto& elem : *inverted_list){
auto& item = tokens_mapelem.doc_id; //存在直接返回这个对象,不存在则新建
//item一定是doc_id相同的print节点
item.doc_id =elem.doc_id;
item.weight +=elem.weight;
item.words.push_back(elem.word);
}
我们直接用搜索到的item的文档id来构建tokens_map这个unordered_map
这样就算搜索到了重复文档,保存搜索到的文档的对象也都只会有一个,并且我们在这里直接+=weight,就可以直接把第二个词的权重也加上
push_back(elem.word),直接把文档命中的关键词记录下来
item.weight += elem.weight;权重累加
elem.weight:单个词在该文档里的权重(TF‑IDF)- 如果文档命中查询中多个检索词,相关性就越高,分数就要叠加。
举例子:
c++在 doc10 权重 = 40网络编程在 doc10 权重 = 35
- 处理词
c++:tokens_map[10].weight = 40- 处理词
网络编程:tokens_map[10].weight +=35→ 最终 weight = 75✅含义:这篇文档命中用户 2 个搜索词,总分 75,排序的时候排到前面。
如果写成直接赋值
item.weight = elem.weight;那后面的词会直接覆盖前面分数,doc10 最后只有 35 分,丢失多词命中的增益,相关性排序完全错误。检索核心规则:文档命中查询里的词越多,权重分数应该越高,排名越靠前。
item.words.push_back(elem.word);记录命中哪些查询词
words是std::vector<std::string>,保存该文档命中了用户查询中的哪些关键词。上面例子 doc10: 第一次循环 push
"c++"→ words =["c++"]第二次循环 push"网络编程"→ words =["c++","网络编程"]
最后,我们把得到的tokens_map中的所有元素都放到inverted_list_all中,就得到了文档的列表:
for(const auto &item : tokens_map){
inverted_list_all.push_back(std::move(item.second));
}
cpp
std::vector<InvertedElemPrint> inverted_list_all;

                std::unordered_map<uint64_t,InvertedElemPrint> tokens_map;

                for(std::string word :words){
                    boost::to_lower(word);
                    ns_index::InvertedList *inverted_list = index->GetInvertedList(word);
                    if(nullptr == inverted_list){
                        continue;
                    }
                    //会有重复搜索结果
                    //inverted_list_all.insert(inverted_list_all.end(),inverted_list->begin(),inverted_list->end());
                    //解决方案
                    for(const auto& elem : *inverted_list){
                        auto& item = tokens_map[elem.doc_id]; //存在直接返回这个对象,不存在则新建
                        //item一定是doc_id相同的print节点
                        item.doc_id =elem.doc_id;
                        item.weight +=elem.weight;
                        item.words.push_back(elem.word);
                    }
                }
                for(const auto &item : tokens_map){
                    inverted_list_all.push_back(std::move(item.second));
}3.合并排序:汇总查找结果,按照相关性(weight)降序排序
得到了所有文档的列表后,我们需要对文档的展示顺序进行排序,把权重高的文档放在前面
这里我们可以直接使用sort函数加上lambda表达式进行排序:
cpp
std::sort(inverted_list_all.begin(),inverted_list_all.end(),[](const InvertedElemPrint& e1,const InvertedElemPrint& e2){
                    return e1.weight > e2.weight;
                });
4.构建:根据查找出来的结果,构建json串 -- jsoncpp
现在,我们完成了对文档列表的构建和排序
接下来,我们需要构建json来实现前后端的交互
json的作用就是:后端 C++ 生成 JSON 字符串,通过 HTTP 返回给浏览器;前端 JS 解析这份 JSON 数据,动态渲染网页
也就是说,我们在后端用代码生成完成了文档的结构后,需要把这个结构转换成json串传给前端,前端需要根据这个json串来生成我们想要的网页
当然,我们并不需要自己写这个生成json的逻辑,我们直接使用json库来生成
首先,我们需要下载json库:
sudo apt-get install libjsoncpp-dev
然后包含json库的头文件:#include <jsoncpp/json/json.h>
这样我们就可以使用这个json库了
我们需要先创建一个Value对象来存储之后构建出来的内容
Json::Value root;
之后我们直接使用范围for来对每一个文档进行序列化
(序列化:把内存里活的对象 → 转成一段可以存储 / 网络传输的字符串 / 字节流)
for(auto& item: inverted_list_all){
ns_index::DocInfo* doc = index->GetForwardIndex(item.doc_id); //正排索引通过id获取文档
if(doc == nullptr){
continue;
}
//使用json库来进行序列化
Json::Value elem;
elem"title" = doc->title;
elem"desc" = GetDesc(doc->content,item.words0);
elem"url" = doc->url;
root.append(elem);//序列化完毕,我们就可以直接把对象插入到root对象里等待之后统一转换为json串了
}
这里在处理摘要内容时,我们还需要设置一些特殊逻辑,因为我们不能直接把整个文档的内容全都放到摘要中,这样太长了,但是也不能随便截一段内容,这样体现不出我们搜索的关键词
所以我们要写一段函数来构建摘要的内容:
我们就设置摘要是显示从关键词开始往前50字节,往后100字节的内容:
const int prev_step = 50;
const int next_step = 100;
接下来,我们需要找到关键词在文档中首次出现的位置:
auto iter = std::search(html_content.begin(),html_content.end(),word.begin(),word.end(),\[\](int x,int y){
return (std::tolower(x) == std::tolower(y));
});
if(iter == html_content.end()){
return "None1"; //没有出现的情况理论上来说是不可能的,但是我们还是写一下
}
std::size_t pos = std::distance(html_content.begin(),iter);
找到位置后,我们更新摘要在文档中开始和结束的位置:
int start = 0;
int end = html_content.size();
//如果之前有50+字符,就更新开始位置
if(pos > start + prev_step){
start = pos - prev_step;
}
if(pos < end - next_step){
end = pos + next_step;
}
if(start >= end){
return "None2";
}
然后截取字符串并返回:
std::string desc = html_content.substr(start,end-start);
desc += "..."; //最后加上...表示后面还有内容
return desc;
cpp
std::string GetDesc(const std::string &html_content , const std::string word){
                //找到word在html_content中的首次出现
                //往前找50字节(没有五十个就从begin开始),往后找100字节
                const int prev_step = 50;
                const int next_step = 100;
                //1.找到首次出现
                auto iter = std::search(html_content.begin(),html_content.end(),word.begin(),word.end(),[](int x,int y){
                    return (std::tolower(x) == std::tolower(y));
                });
                if(iter == html_content.end()){
                    return "None1";
                }
                std::size_t pos = std::distance(html_content.begin(),iter);

                //2.获取start,end
                int start = 0;
                int end = html_content.size();
                //如果之前有50+字符,就更新开始位置
                if(pos > start + prev_step){
                    start = pos - prev_step;
                }
                if(pos < end - next_step){
                    end = pos + next_step;
                }
                if(start >= end){
                    return "None2";
                }
                //3.截取字串,return
                std::string desc = html_content.substr(start,end-start);
                desc += "...";
                return desc;
            }
全部文档处理序列化并且保存到root中后,我们把他们统一转换成json串:
Json::FastWriter writer;
*json_string = writer.write(root);
cpp
 Json::Value root;
                for(auto& item: inverted_list_all){
                     ns_index::DocInfo* doc = index->GetForwardIndex(item.doc_id);
                     if(doc == nullptr){
                        continue;
                     }
                     //使用json库来进行序列化
                    Json::Value elem;
                    elem["title"] = doc->title;
                    elem["desc"] = GetDesc(doc->content,item.words[0]);
                    elem["url"] = doc->url;

                    root.append(elem);
                }

                //Json::StyledWriter writer;
                Json::FastWriter writer;
                *json_string = writer.write(root);
5.总结
完成上面的过程,我们就实现了从搜索字符串到构建出json对象的过程,之后我们只要完成前端代码,把这个json串传给前端,就能实现整个搜索引擎了
Searcher函数完整代码
cpp
void Search(const std::string& query,std::string* json_string){

                //1.分词:对query进行按照searcher的要求进行分词
                std::vector<std::string> words;
                ns_util::JiebaUtil::CutString(query,&words);
                //2.触发:根据分词的各个词,进行index查找
                //ns_index::InvertedList inverted_list_all;
                std::vector<InvertedElemPrint> inverted_list_all;

                std::unordered_map<uint64_t,InvertedElemPrint> tokens_map;

                for(std::string word :words){
                    boost::to_lower(word);
                    ns_index::InvertedList *inverted_list = index->GetInvertedList(word);
                    if(nullptr == inverted_list){
                        continue;
                    }
                    //会有重复搜索结果
                    //inverted_list_all.insert(inverted_list_all.end(),inverted_list->begin(),inverted_list->end());
                    //解决方案
                    for(const auto& elem : *inverted_list){
                        auto& item = tokens_map[elem.doc_id]; //存在直接返回这个对象,不存在则新建
                        //item一定是doc_id相同的print节点
                        item.doc_id =elem.doc_id;
                        item.weight +=elem.weight;
                        item.words.push_back(elem.word);
                    }
                }
                for(const auto &item : tokens_map){
                    inverted_list_all.push_back(std::move(item.second));
                }
                //3.合并排序:汇总查找结果,按照相关性(weight)进行降序排序
                // std::sort(inverted_list_all.begin(),inverted_list_all.end(),\
                // [](const ns_index::InvertedElem& e1,\
                //    const ns_index::InvertedElem& e2){
                //     return e1.weight>e2.weight;
                // });
                std::sort(inverted_list_all.begin(),inverted_list_all.end(),[](const InvertedElemPrint& e1,const InvertedElemPrint& e2){
                    return e1.weight > e2.weight;
                });

                //4.构建:根据查找结果构建json串------jsoncpp
                Json::Value root;
                for(auto& item: inverted_list_all){
                     ns_index::DocInfo* doc = index->GetForwardIndex(item.doc_id);
                     if(doc == nullptr){
                        continue;
                     }
                     //使用json库来进行序列化
                    Json::Value elem;
                    elem["title"] = doc->title;
                    elem["desc"] = GetDesc(doc->content,item.words[0]);
                    elem["url"] = doc->url;

                    root.append(elem);
                }

                //Json::StyledWriter writer;
                Json::FastWriter writer;
                *json_string = writer.write(root);
            }
3.3.4 总结
现在,就完成了整个Searcher.hpp的编写,并且完善了Index.hpp,下一步就是编写http_server模块实现前后端的交互了
Searcher.hpp完整代码:
cpp
#pragma once
#include<algorithm>
#include<unordered_map>
#include"index.hpp"
#include "util.hpp"
#include <jsoncpp/json/json.h>
#include "log.hpp"
namespace ns_searcher{
    struct InvertedElemPrint{
        uint64_t doc_id;
        int weight;
        std::vector<std::string> words;
        InvertedElemPrint():doc_id(0),weight(0){}
    };
    class Searcher{
        private:
            ns_index::Index *index;
        public:
            Searcher(){}
            ~Searcher(){}

            void InitSearcher(const std::string& input){
                //1.获取或者创建index对象
                index = ns_index::Index::GetInstance();
                // std::cout<<"获取index单例成功"<<std::endl;
                LOG(NORMAL,"获取index单例成");
                //2.根据index对象建立索引
                index->BuildIndex(input);
                // std::cout<<"建立正排和倒排索引成功"<<std::endl;
                LOG(NORMAL,"建立正排和倒排索引成功");

            }
            //quer::搜索关键字
            //json_string:返回给用户浏览器的搜索结果
            void Search(const std::string& query,std::string* json_string){

                //1.分词:对query进行按照searcher的要求进行分词
                std::vector<std::string> words;
                ns_util::JiebaUtil::CutString(query,&words);
                //2.触发:根据分词的各个词,进行index查找
                //ns_index::InvertedList inverted_list_all;
                std::vector<InvertedElemPrint> inverted_list_all;

                std::unordered_map<uint64_t,InvertedElemPrint> tokens_map;

                for(std::string word :words){
                    boost::to_lower(word);
                    ns_index::InvertedList *inverted_list = index->GetInvertedList(word);
                    if(nullptr == inverted_list){
                        continue;
                    }
                    //会有重复搜索结果
                    //inverted_list_all.insert(inverted_list_all.end(),inverted_list->begin(),inverted_list->end());
                    //解决方案
                    for(const auto& elem : *inverted_list){
                        auto& item = tokens_map[elem.doc_id]; //存在直接返回这个对象,不存在则新建
                        //item一定是doc_id相同的print节点
                        item.doc_id =elem.doc_id;
                        item.weight +=elem.weight;
                        item.words.push_back(elem.word);
                    }
                }
                for(const auto &item : tokens_map){
                    inverted_list_all.push_back(std::move(item.second));
                }
                //3.合并排序:汇总查找结果,按照相关性(weight)进行降序排序
                // std::sort(inverted_list_all.begin(),inverted_list_all.end(),\
                // [](const ns_index::InvertedElem& e1,\
                //    const ns_index::InvertedElem& e2){
                //     return e1.weight>e2.weight;
                // });
                std::sort(inverted_list_all.begin(),inverted_list_all.end(),[](const InvertedElemPrint& e1,const InvertedElemPrint& e2){
                    return e1.weight > e2.weight;
                });

                //4.构建:根据查找结果构建json串------jsoncpp
                Json::Value root;
                for(auto& item: inverted_list_all){
                     ns_index::DocInfo* doc = index->GetForwardIndex(item.doc_id);
                     if(doc == nullptr){
                        continue;
                     }
                     //使用json库来进行序列化
                    Json::Value elem;
                    elem["title"] = doc->title;
                    elem["desc"] = GetDesc(doc->content,item.words[0]);
                    elem["url"] = doc->url;

                    root.append(elem);
                }

                //Json::StyledWriter writer;
                Json::FastWriter writer;
                *json_string = writer.write(root);
            }
            std::string GetDesc(const std::string &html_content , const std::string word){
                //找到word在html_content中的首次出现
                //往前找50字节(没有五十个就从begin开始),往后找100字节
                const int prev_step = 50;
                const int next_step = 100;
                //1.找到首次出现
                auto iter = std::search(html_content.begin(),html_content.end(),word.begin(),word.end(),[](int x,int y){
                    return (std::tolower(x) == std::tolower(y));
                });
                if(iter == html_content.end()){
                    return "None1";
                }
                std::size_t pos = std::distance(html_content.begin(),iter);

                //2.获取start,end
                int start = 0;
                int end = html_content.size();
                //如果之前有50+字符,就更新开始位置
                if(pos > start + prev_step){
                    start = pos - prev_step;
                }
                if(pos < end - next_step){
                    end = pos + next_step;
                }
                if(start >= end){
                    return "None2";
                }
                //3.截取字串,return
                std::string desc = html_content.substr(start,end-start);
                desc += "...";
                return desc;
            }
    };
}
Index.hpp完整代码:
cpp
#pragma once
#include <iostream>
#include <string>
#include <vector>
#include <fstream>
#include <mutex>
#include <unordered_map>
#include"util.hpp"
#include "log.hpp"
namespace ns_index{
    struct DocInfo{
        std::string title;   //标题
        std::string content; //去标签内容
        std::string url;     //官网文档url
        uint64_t doc_id;          //文档的ID
    };
    struct InvertedElem{
        uint64_t doc_id;
        std::string word;
        int weight;
    };

    //倒排拉链
    typedef std::vector<InvertedElem> InvertedList;

    class Index{
    private:
    //正排索引
        std::vector<DocInfo> forward_index;
    //倒排索引一定是一个关键字和一组(个)InvertedElem对应
        std::unordered_map<std::string,InvertedList> inverted_index;
    private:
        Index(){};
        Index(const Index&) = delete;
        Index& operator=(const Index&) =delete;

        static std::mutex mtx;
        static Index* instance;
    public:
        ~Index(){}
        static Index* GetInstance(){

            if(nullptr == instance){
                mtx.lock();
            if(nullptr == instance){

                instance = new Index();
            }
            mtx.unlock();
        }
            return instance;
        }
        //根据doc_id找到文档内容
        DocInfo* GetForwardIndex(uint64_t doc_id){
            if(doc_id >= forward_index.size()){
                std::cerr<<"doc_id out of range,error!"<<std::endl;
                return nullptr;
            }
            return &forward_index[doc_id];
        }
        //根据关键字string获得倒排拉链
        InvertedList* GetInvertedList(const std::string &word){
            auto iter = inverted_index.find(word);
            if(iter == inverted_index.end()){
                std::cerr<<word<<" have no InvertedList"<<std::endl;
                return nullptr;
            }
            return &(iter->second);
        }
        //根据去标签格式化之后的文档构建正排和倒排索引
        bool BuildIndex(const std::string &input){
            std::ifstream in(input, std::ios::in | std::ios::binary);
            if(!in.is_open()){
                std::cerr<<"sorry, "<<input<<" open error!"<<std::endl;
                return false;
            }

            std::string line;
            int count = 0;
            while(std::getline(in,line)){
                DocInfo* doc = BuildForwardIndex(line);
                if(doc == nullptr){
                    std::cerr<<"build "<<line<<" error!" <<std::endl;
                    continue;
                }
                BuildInvertedIndex(*doc);
                 ++count;
                if(count %100 == 0){
                    //std::cout<<"当前已经建立的索引文档"<<count<<std::endl;
                    LOG(NORMAL, "当前已经建立的索引文档"+std::to_string(count));
                }
            }

            return true;
        }
        private:
            DocInfo* BuildForwardIndex(const std::string &line){
                //解析line,字符串切分
                //line-> 3个string:title content url
                const std::string sep = "\3";
                std::vector<std::string> results;
                ns_util::StringUtil::Split(line , &results,sep);
                if(results.size() != 3){
                    return nullptr;
                }

                //字符串进行填充到DocInfo
                DocInfo doc;
                doc.title = results[0]; //title
                doc.content = results[1];//content
                doc.url = results[2];   //url
                doc.doc_id = forward_index.size(); //先保存id再插入,对应id就是当前doc在vector中的下标
                //插入到正排索引的vector
                forward_index.push_back(std::move(doc));
                return &forward_index.back();
            }
            bool BuildInvertedIndex(const DocInfo& doc){
                //word->倒排拉链
                struct word_cnt{
                    int title_cnt;
                    int content_cnt;

                    word_cnt():title_cnt(0),content_cnt(0){}
                };
                std::unordered_map<std::string, word_cnt> word_map;//暂存词频的映射表

                //title的分词
                std::vector<std::string> title_words;
                ns_util::JiebaUtil::CutString(doc.title,&title_words);
                //title的词频统计
                for(auto &s: title_words){
                    boost::to_lower(s);  //分词统一转换成小写
                    word_map[s].title_cnt++;
                }

                //对content的分词
                std::vector<std::string> content_words;
                ns_util::JiebaUtil::CutString(doc.content,&content_words);
                //content的词频统计
                for(auto &s : content_words){
                    boost::to_lower(s);  ////分词统一转换成小写
                    word_map[s].content_cnt++;
                }

#define X 10
#define Y 1
                for(auto &word_pair :word_map){
                    InvertedElem item;
                    item.doc_id = doc.doc_id;
                    item.word = word_pair.first;
                    item.weight = X*word_pair.second.title_cnt + Y*word_pair.second.content_cnt;
                     //创建倒排拉链
                    InvertedList &inverted_list = inverted_index[word_pair.first];
                    inverted_list.push_back(std::move(item));
                }
                return true;
            }
    };
    std::mutex Index::mtx;
    Index* Index::instance =nullptr;
}
3.4 编写 http_server 模块
前面我们完成了后端代码的编写,下面我们就要写前后端交互的代码了,其实也就是main函数,我们在main函数中调用后端代码给前端使用
首先,我们需要先下载一个c++的网络库------cpp-httplib
我们前往这个网址:Releases · yhirose/cpp-httplib
滑到页面的下面下载.zip文件,下载的版本不用完全一样
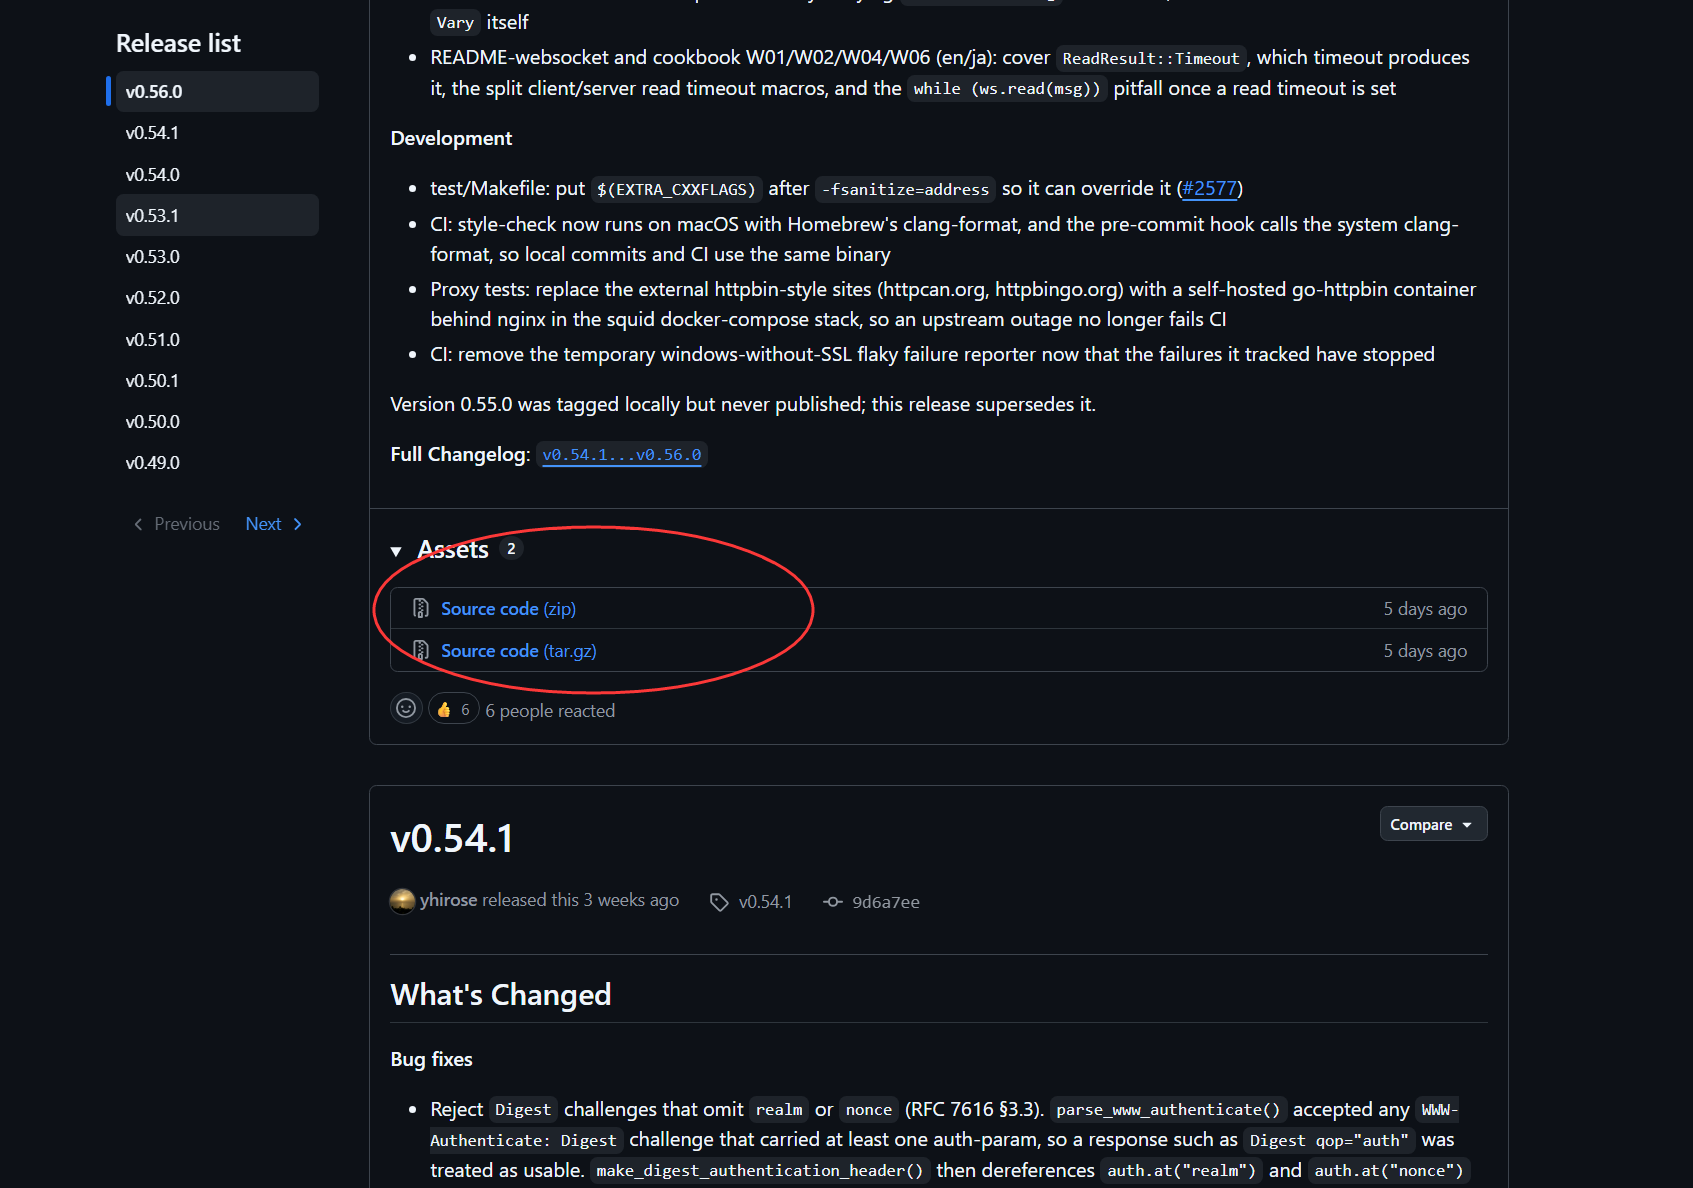
我们只需要把这个.zip里的httplib.h放到我们的项目目录中就好了
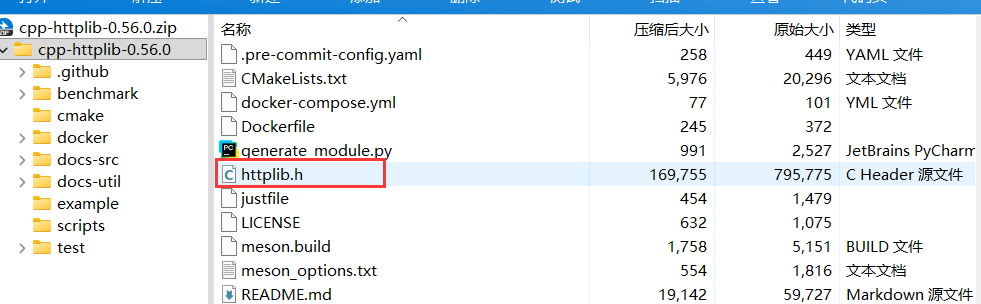
方法和前面导入boost库相似
下面讲一下这个库的基本使用方法:
cpp
#include "cpp-httplib/httplib.h"

int main()
{
httplib::Server svr;

svr.Get("/hi", [](const httplib::Request &req, httplib::Response &rsp){
 rsp.set_content("你好,世界!", "text/plain; charset=utf-8");
 });

 svr.listen("0.0.0.0", 8081);
 return 0;
 }
我们首先要创建一个对象:httplib::Server svr;
然后用其中的Get函数设置网页的url
而Get的第一个参数就是设置一个网页的地址url路径(路由路径)为hi,然后把这个路径和后面lambda表达式的内容写道一个登记表里
当我们访问这个地址时,其实是浏览器先向我们的服务器发送请求,如果匹配到了我们用Get设置的这个地址,那么才会给我们构建网页,也就是执行后面lambda表达式的内容
这里是svr.set_content就是设置网页里的内容为 你好,世界
而下面的svr.listen就是开始监听,也就是开始接受外部发送过来的请求
就相当于是设置我们的网页链接为:0.0.0.0:8081/hi
而这里的0.0.0.0的意思是使用服务器自身的网络监听地址
而我的地址是82.156.191.135,所以我创建的网页就是82.156.191.135:8081/hi
我们现在访问一下这个链接:
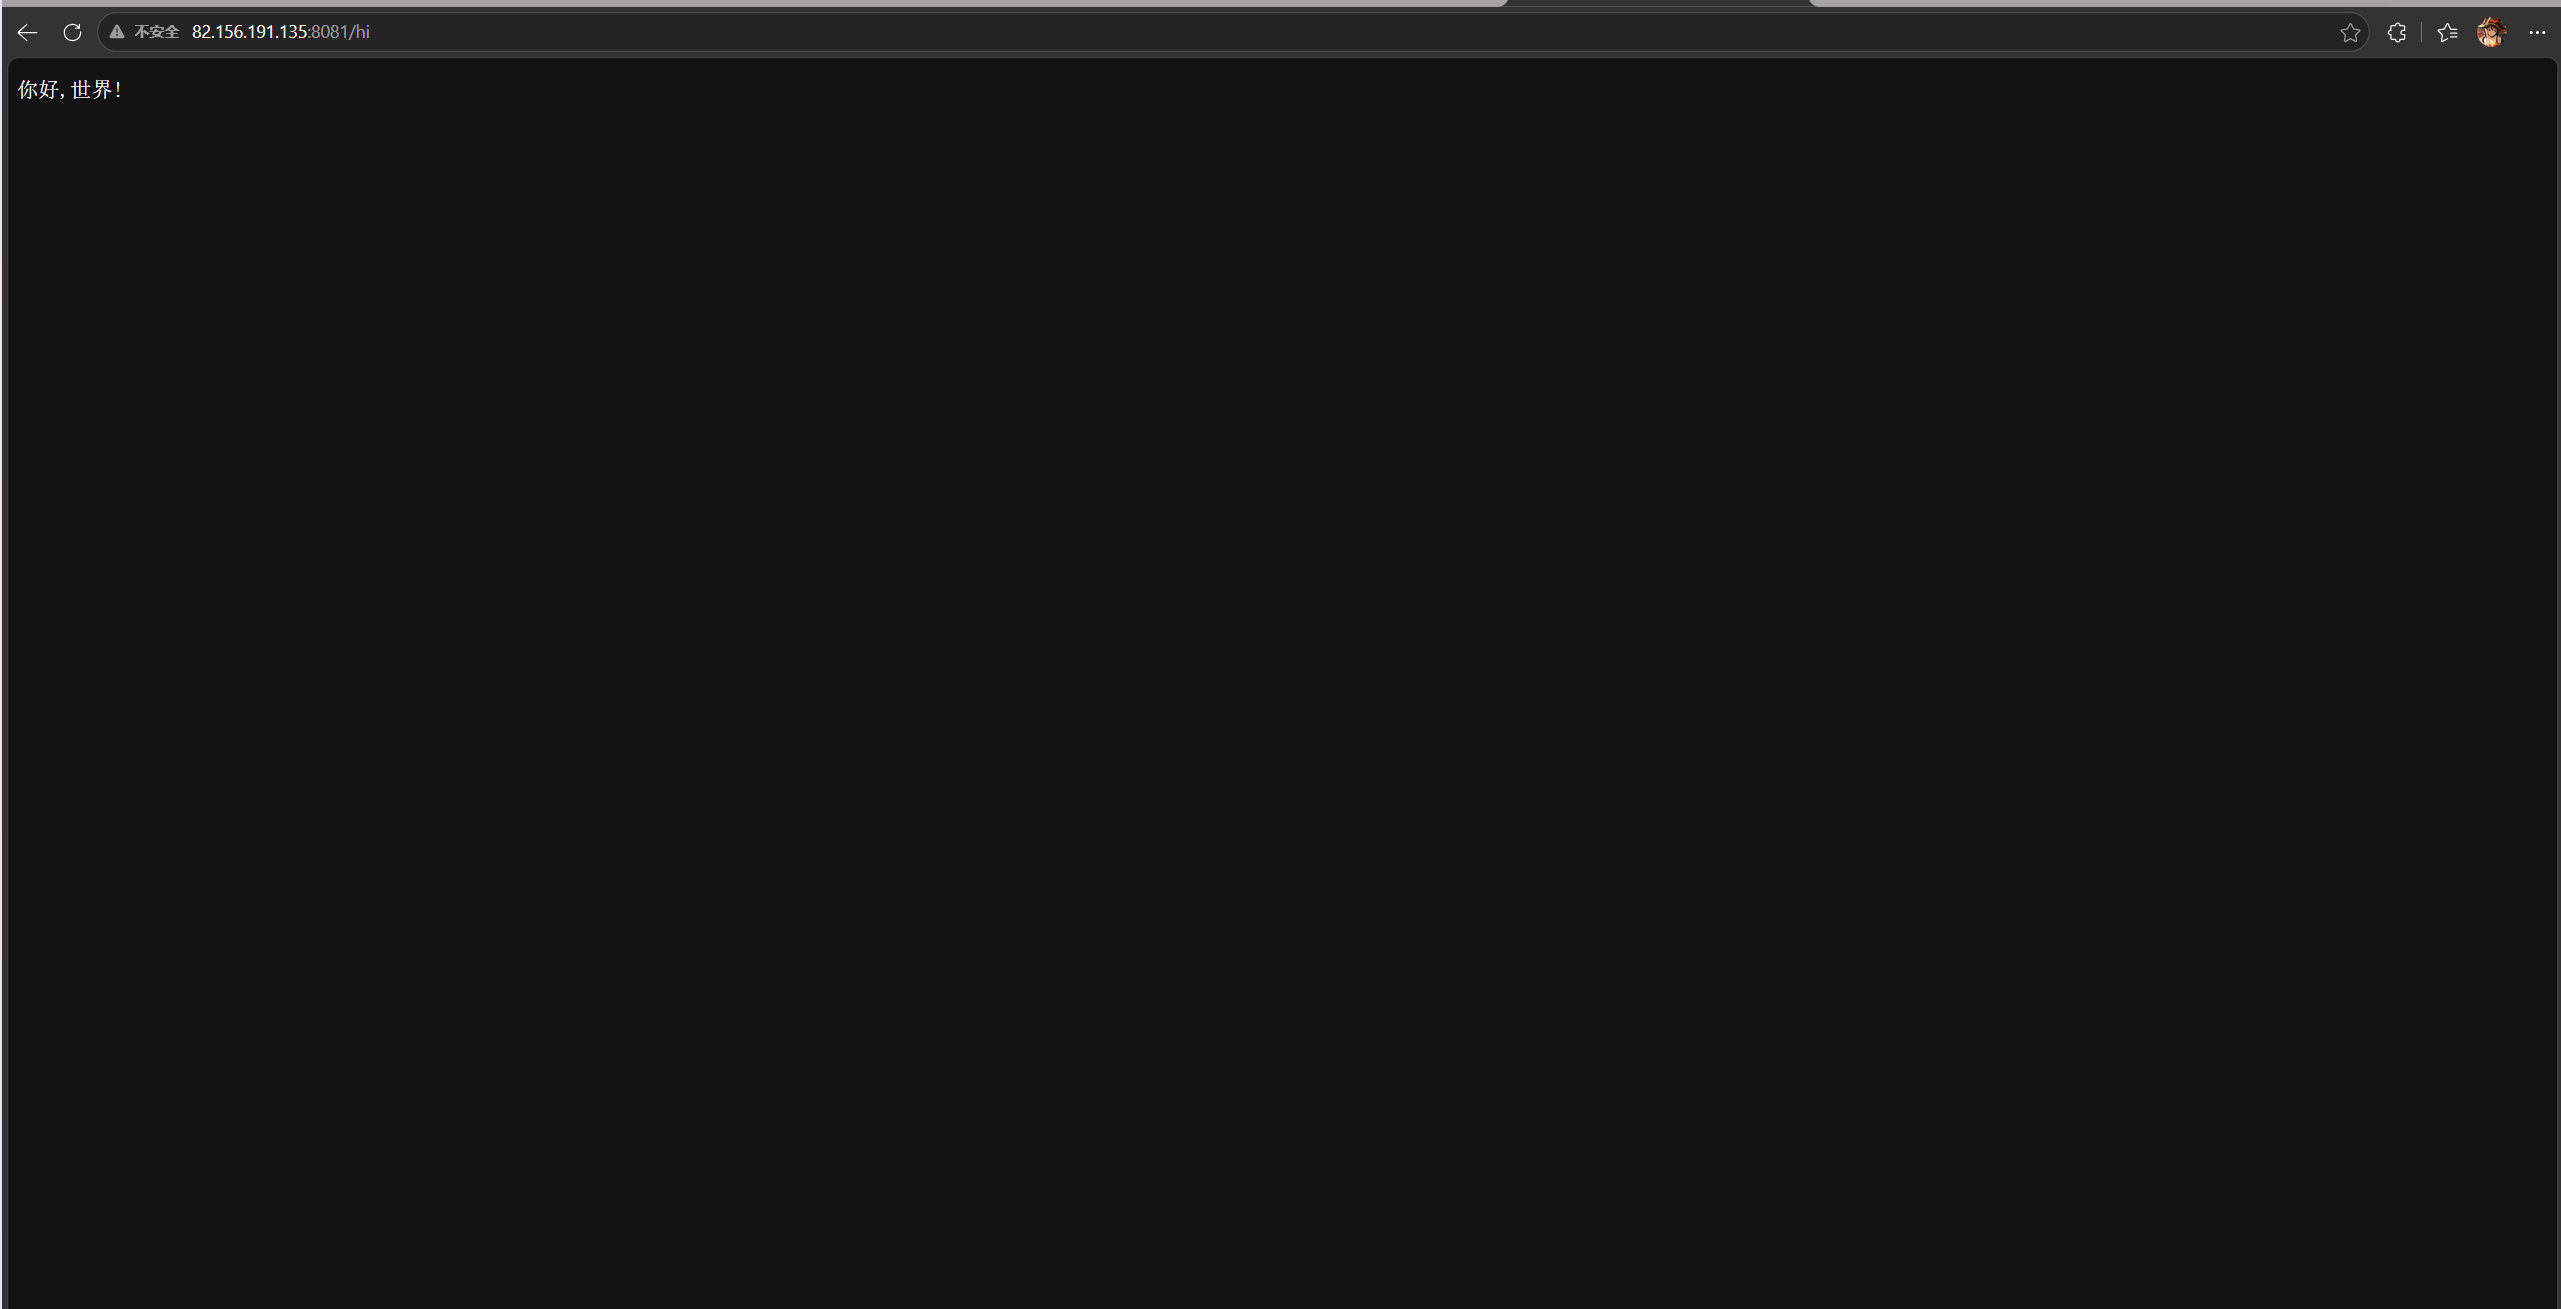
可以看到,这个网页中就有一个"你好,世界"的字符串了
所以,我们就可以用类似的方法来构建我们的搜索引擎页面
但是,我们直接在这里设置网页内容是很麻烦的,我们可以用html代码来编写网页,然后把我们写的网页传给网络库,再让网络库去显示我们写的网页
所以我们就需要再创建一个.html文件来构建我们的网页了
我们先创建一个wwwroot文件夹,然后在里面创建一个index.html文件,之后我们可以先不用管这个文件,之后再写网页代码,我们先把main函数写完
首先,我们需要先创建出Searcher对象,并用我们的数据对这个对象进行初始化:
ns_searcher::Searcher search;
search.InitSearcher(input);
我们可以把input这个路径定义成全局变量:
const std::string input = "data/raw_html/raw.txt";
之后,创建Sever对象,并设置我们的svr对象之后要返回给浏览器的网页:
httplib::Server svr;
svr.set_base_dir(root_path.c_str());
svr.listen("0.0.0.0",8081);
const std::string root_path = "./wwwroot";//这里也要定义成全局变量
现在,其实我们已经能访问网页了,访问82.156.191.135:8081这个地址之后,后端会返回给浏览器我们自己写的index.html这个网页,只不过我们现在还没有写
但是,为了实现搜索逻辑,并让网页动态变化,我们需要用Get函数设置一个登记表,当我们搜索关键词时,会调用Get中的代码,并返回json字符串给网页代码来动态构建搜索出的网页:
svr.Get("/s", \&search(const httplib::Request& req, httplib::Response& rsp){
if(!req.has_param("word")){
rsp.set_content("必须要有搜索关键字","text/plain; charset=utf-8");
return;
}
std::string word = req.get_param_value("word");
std::cout<<"用户正在搜索:"<<word<<std::endl;
std::string json_string;
search.Search(word,&json_string);
rsp.set_content(json_string,"application/json");
//rsp.set_content("hello world","text/plain; charset=utf-8");
});
这样,我们就完成了http_server.cc的编写
完整代码:
cpp
#include "searcher.hpp"
#include "httplib.h"

const std::string root_path = "./wwwroot";
const std::string input = "data/raw_html/raw.txt";
int main(){

    ns_searcher::Searcher search;
    search.InitSearcher(input);


    httplib::Server svr;
    svr.set_base_dir(root_path.c_str());
    svr.Get("/s", [&search](const httplib::Request& req, httplib::Response& rsp){
            if(!req.has_param("word")){
                rsp.set_content("必须要有搜索关键字","text/plain; charset=utf-8");
                return;
            }
            std::string word = req.get_param_value("word");
            std::cout<<"用户正在搜索:"<<word<<std::endl;
            LOG(NORMAL,"用户正在搜索:"+word);
            std::string json_string;
            search.Search(word,&json_string);
            rsp.set_content(json_string,"application/json");
            //rsp.set_content("hello world","text/plain; charset=utf-8");
            });

    svr.listen("0.0.0.0",8081);
    return 0;
}
3.5 html网页的编写
现在,我们需要编写前端html网页的代码了
首先,我们需要写一个html5文档的声明,告诉浏览器:当前这份网页,使用 HTML5 标准 来解析渲染
<!DOCTYPE html>
然后还要添加一条根标签,所有网页内容全部写在这个标签里面:
<html lang="en">
之后在head区域里添加三条meta标签,并设置网页标题:
<head>
<meta charset="UTF-8">
<meta http-equiv="X-UA-Compatible" content="IE=edge">
<meta name="viewport" content="width=device-width, initial-scale=1.0">
<title>boost 搜索引擎</title>
</head>
三条meta标签的作用:
<meta charset="UTF-8">设置网页字符编码为 UTF‑8
- 告诉浏览器:这个网页的文字是 UTF‑8 编码。
- 中文网页必须写,不写会出现中文乱码(问号、方块、奇怪符号)。
<meta http‑equiv="X‑UA‑Compatible" content="IE=edge">专门针对旧版 IE 浏览器(现在基本没人用 IE 了)
- 强制 IE 浏览器使用它最高版本内核渲染页面,不要用老旧兼容模式。
- 现代 Chrome、Edge、Firefox 完全忽略这条;如果你的项目不需要兼容古董 IE,可以直接删掉。
###3.
<meta name="viewport" content="width=device-width, initial‑scale=1.0">移动端适配标签(手机浏览器)
width=device‑width:页面宽度等于手机屏幕物理宽度,不把电脑网页缩小塞进手机屏幕。initial‑scale=1.0:页面初始缩放倍数 = 1,打开网页不放大、不缩小。不写这条:手机上打开网页会整体缩小,字特别小,需要手动放大。
接下来我们写一下网页的主题结构:
cpp
<body>
<div class="container">
    <div class="search">
        <input type="text" value="输⼊搜索关键字...">
        <button>搜索⼀下</button>
    </div>
    <div class="result">
        <div class="item">
            <a href="#">这是标题</a>
            <p>这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要</p>
            <i>https://search.gitee.com/?skin=rec&type=repository&q=cpp‑httplib</i>
        </div>
        <div class="item">
            <a href="#">这是标题</a>
            <p>这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要</p>
            <i>https://search.gitee.com/?skin=rec&type=repository&q=cpp‑httplib</i>
        </div>
        <div class="item">
            <a href="#">这是标题</a>
            <p>这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要</p>
            <i>https://search.gitee.com/?skin=rec&type=repository&q=cpp‑httplib</i>
        </div>
        <div class="item">
            <a href="#">这是标题</a>
            <p>这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要</p>
            <i>https://search.gitee.com/?skin=rec&type=repository&q=cpp‑httplib</i>
        </div>
        <div class="item">
            <a href="#">这是标题</a>
            <p>这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要这是摘要</p>
            <i>https://search.gitee.com/?skin=rec&type=repository&q=cpp‑httplib</i>
        </div>
    </div>
</div>
</body>
</html>
这样我们就写出了一个静态的网页,里面有我们的搜索框和搜索出来的内容
但是,现在的网页还不美观,我们再在<head>中设置一下网页的结构:
cpp
<style>
        /* 去掉网页中所以的默认内外边距 */
        *{
            /* 设置外边距 */
            margin: 0;
            /* 设置内边距 */
            padding: 0;
        }
        /* 将body内容100%和html的呈现吻合 */
        html,
        body{
            height: 100%;
        }
        /* 类选择器.container */
        .container{
            display: block;
            /* 设置div的宽度 */
            width: 800px;
            /* 通过设置外边距达到居中对齐的目的 */
            margin: 0px auto;
            /* 设置外边距的上边距,保持元素和网页的上部距离 */
            margin-top: 15px;
        }
        /* 复合选择器,选中container中的search */
        .container .search{
            display: block;
            /* 宽度与父标签保持一致 */
            width: 100%;
            /* 高度设置为52px(像素点) */
            height: 52px;
        }
        /* 先选中input标签,直接设置标签的属性,先要选中,input:标签选择器 */
        /* input在进行高度设置的时候没有考虑边框的问题 */
        .container .search input{
            display: block;
            float: left;
            width: 600px;
            height: 50px;
            /* 设置边框属性:边框宽度,样式,颜色 */
            border:1px solid black;
            /* 去掉右边框 */
            border-right: none;
            /* 设置内边距 */
            padding-left: 10px;
            /* 设置字的颜色和大小 */
            color: #000;
            font-size: 18px;
            font-family: Georgia, 'Times New Roman', Times, serif;
        }
        .container .search input::placeholder{
            color: #ccc;
        }
        .container .search input::-webkit-input-placeholder{
            color: #ccc;
        }
        .container .search input::-moz-placeholder{
            color: #ccc;
        }
        /* 先选中button标签,直接设置标签的属性,先要选中,input:标签选择器 */
        .container .search button{
            display: block;
            float: left;
            width: 150px;
            height: 52px;
            /* 设置button的背景颜色,#4e6ef2 */
            background-color: #4e6ef2;
            border:1px solid #4e6ef2;
            /* 设置字体颜色 */
            color: #FFF;
            /* 设置字体大小 */
            font-size: 19px;
            font-family: Georgia, 'Times New Roman', Times, serif;
        }
        .container .result{
            width: 100%;
        }
        .container .result .item{
            margin-top: 15px;
            position: relative;
        }
        .container .result .item a{
            /* 设为块级元素(单独占一行) */
            display: block;
            /* 去下划线 */
            text-decoration: none;
            font-size: 25px;
            color:green;
            font-family: 'Courier New', Courier, monospace;
        }
        .container .result .item a:hover{
            text-decoration: underline;
        }
        .container .result .item p{
            margin-top: 6px;
            font-size: 17px;
            font-family: 'Courier New', Courier, monospace;
        }
        .container .result .item i{
            display: block;
            color: #4e6ef2;
            font-size: 17px;
            font-family: 'Courier New', Courier, monospace;
        }

    </style>
这样,网页的结构就美观一些了
下面,因为我们要动态生成网页,所以还要编写js代码:
我们要现在<head>中添加js的meta标签:
<script src="https://www.tenpay.com/v4/static/js/jquery-1.9.1.min.js"></script>
下面,把我们的网页内容改成动态生成:
cpp
<body>
    <div class="container">
     <div class="search">
        <input type="text" placeholder="输入搜索关键字">
        <button onclick="Search()">搜索一下</button>
     </div>
     <div class="result">
        <div class="item">
            <!-- 动态生成网页内容 -->
     </div>
    </div>
    <script>
        // 回车键触发搜索
        $(".container .search input").keydown(function(e){
            // e.keyCode === 13 代表按下回车键
            if(e.keyCode === 13){
             Search();
         }
        });

        function Search(){
            // alert("hello js");
            // $就是JQuery的别称
            let query =$(".container .search input").val();
            console.log("query = "+ query);

            //2.发起http请求
            $.ajax({
                type: "GET",
                url:"/s?word=" + query,
                success: function(data){
                    console.log(data);
                    BuildHtml(data);
                }
            });
        }

        function BuildHtml(data){
            // 获取html中的reslut标签
            let result_lable = $(".container .result");
            // 清空历史搜索结果
            result_lable.empty();

            // data为null/undefined 或者不是数组,直接终止循环
            if(data === null || data === undefined || !Array.isArray(data)){
                return;
            }

            for(let elem of data){
                // console.log(elem.title);
                // console.log(elem.url);
                let a_lable = $("<a>",{
                    text: elem.title,
                    href: elem.url,
                    // 跳转到新的页面
                    target:"_blank"
                });
                let p_lable = $("<p>",{
                    text: elem.desc
                });
                let i_lable = $("<i>",{
                    text: elem.url
                });
                let div_lable = $("<div>",{
                    class:"item"
                });
            }
        }
这样,我们就完成了对html网页的编写,下面编译完成就可以开始运行网页了:
Makefile:
cpp
PARSER := parser
DUG := debug
HTTP_SERVER=http_server
CC := g++
# 通用编译标准
STD := -std=c++11
# boost链接参数
BOOST_LIB := -lboost_system -lboost_filesystem
# cppjieba头文件路径
CPPJIEBA_INC := -I./cppjieba/include

.PHONY: all clean
all: $(PARSER) $(DUG) $(HTTP_SERVER)

# 编译网页解析程序parser
$(PARSER):parser.cc
	$(CC) -o $@ $^ $(STD) $(BOOST_LIB)

# 编译搜索服务程序search_server
$(DUG):debug.cc
	$(CC) -o $@ $^ $(STD) $(CPPJIEBA_INC) $(BOOST_LIB) -ljsoncpp

# 编译搜索服务程序http_server
$(HTTP_SERVER):http_server.cc
	$(CC) -o $@ $^ $(STD) $(CPPJIEBA_INC) $(BOOST_LIB) -ljsoncpp -lpthread -DCPPHTTPLIB_OPENSSL_SUPPORT -lssl -lcrypto

# 清理所有可执行文件
clean:
	rm -f $(PARSER) $(DUG) $(HTTP_SERVER)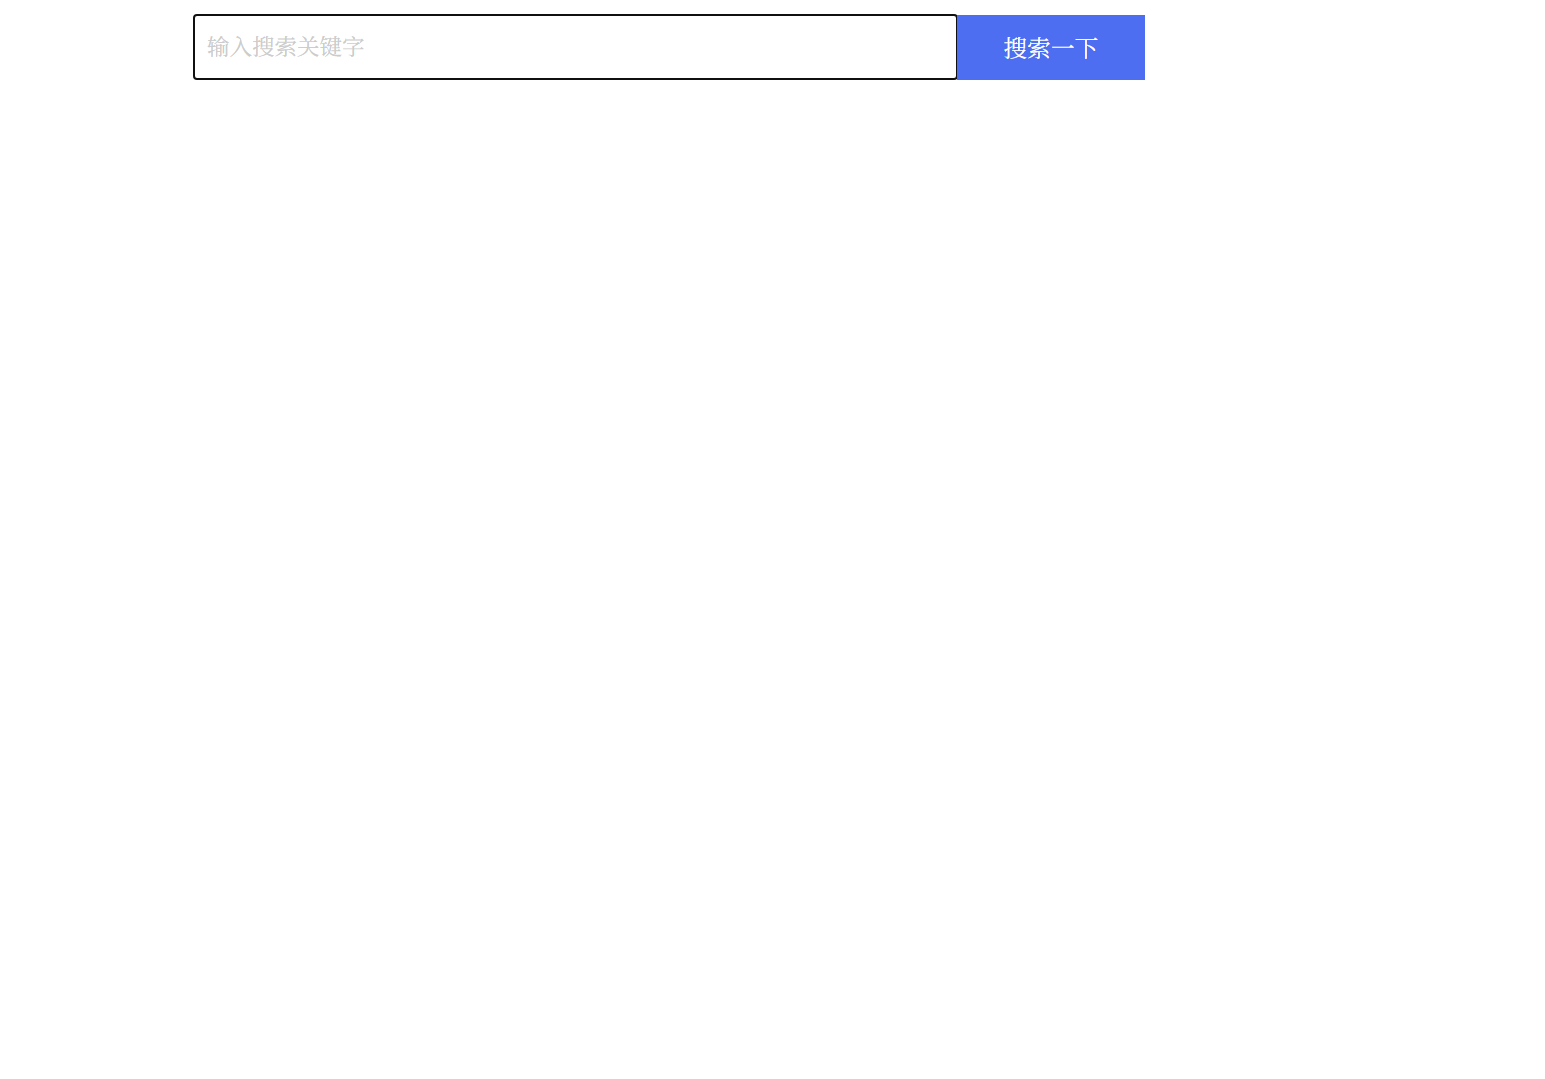
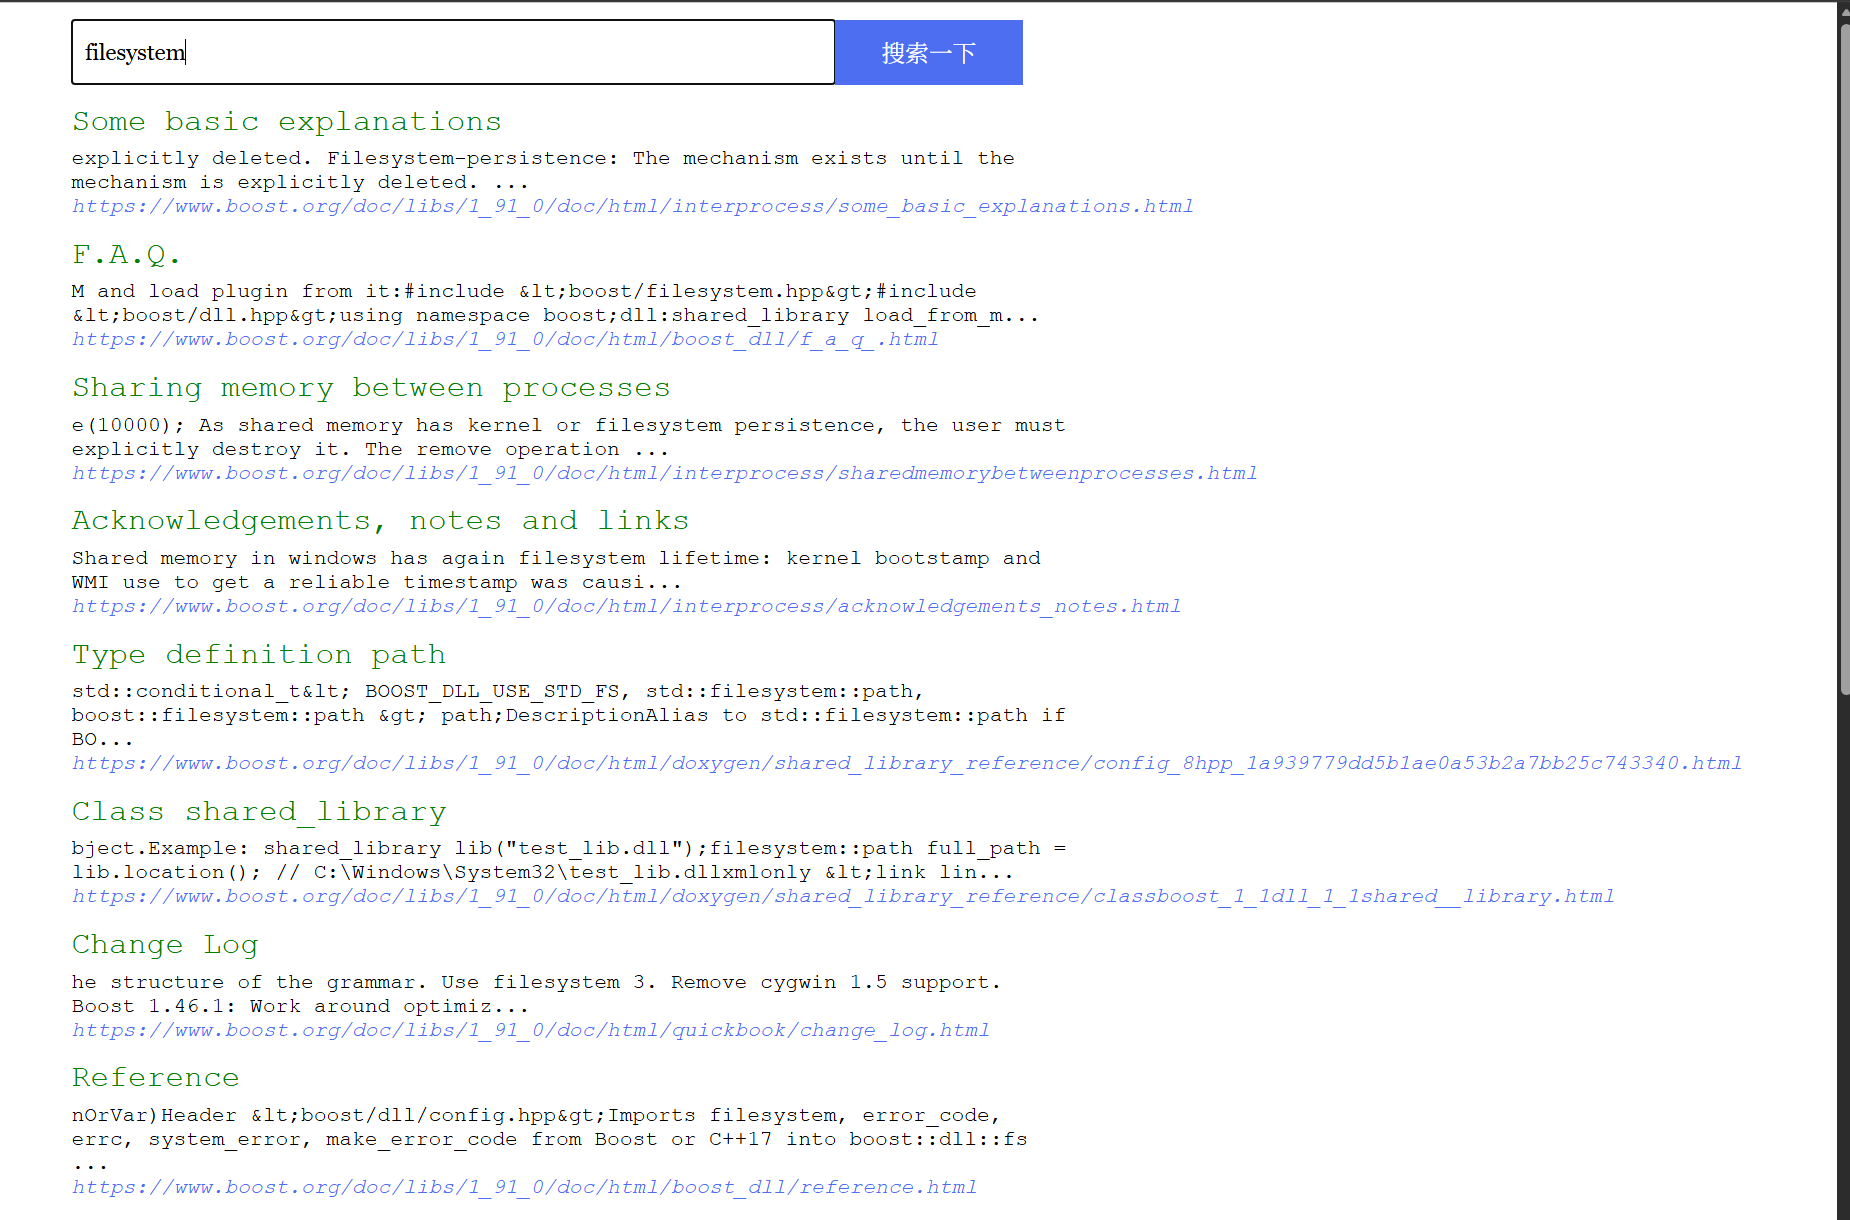
不过我们也还可以进行一些优化,比如加上一个日志功能
log.hpp:
cpp
#pragma once

#include <iostream>
#include <string>
#include <ctime>

#define NORMAL  1
#define WARNING 2
#define DEBUG   3
#define FATAL   4

#define LOG(LEVEL, MESSAGE) log(#LEVEL, MESSAGE, __FILE__, __LINE__)

void log(std::string level, std::string message, std::string file, int line)
{
    std::cout << "[" << level << "]" << "[" << time(nullptr) << "]" << "[" << message << "]" << "[" << file << " : " << line << "]" << std::endl;
}
四、总结
到这里,整个项目就已经完成了,下面是后续的一些扩展方向:
- 建⽴整站搜索
- 设计⼀个在线更新的⽅案,信号,爬⾍,完成整个服务器的设计
- 不使⽤组件,⽽是⾃⼰设计⼀下对应的各种⽅案
- 在我们的搜索引擎中,添加竞价排名
- 热次统计,智能显⽰搜索关键词(字典树,优先级队列)
- 设置登陆注册,引⼊对 mysql 的使⽤
- 引入AI分析库的功能
下面是整个项目的代码的Github链接,并且实现了AI分析库的功能这个功能,加上了LOG功能的使用: