目标:
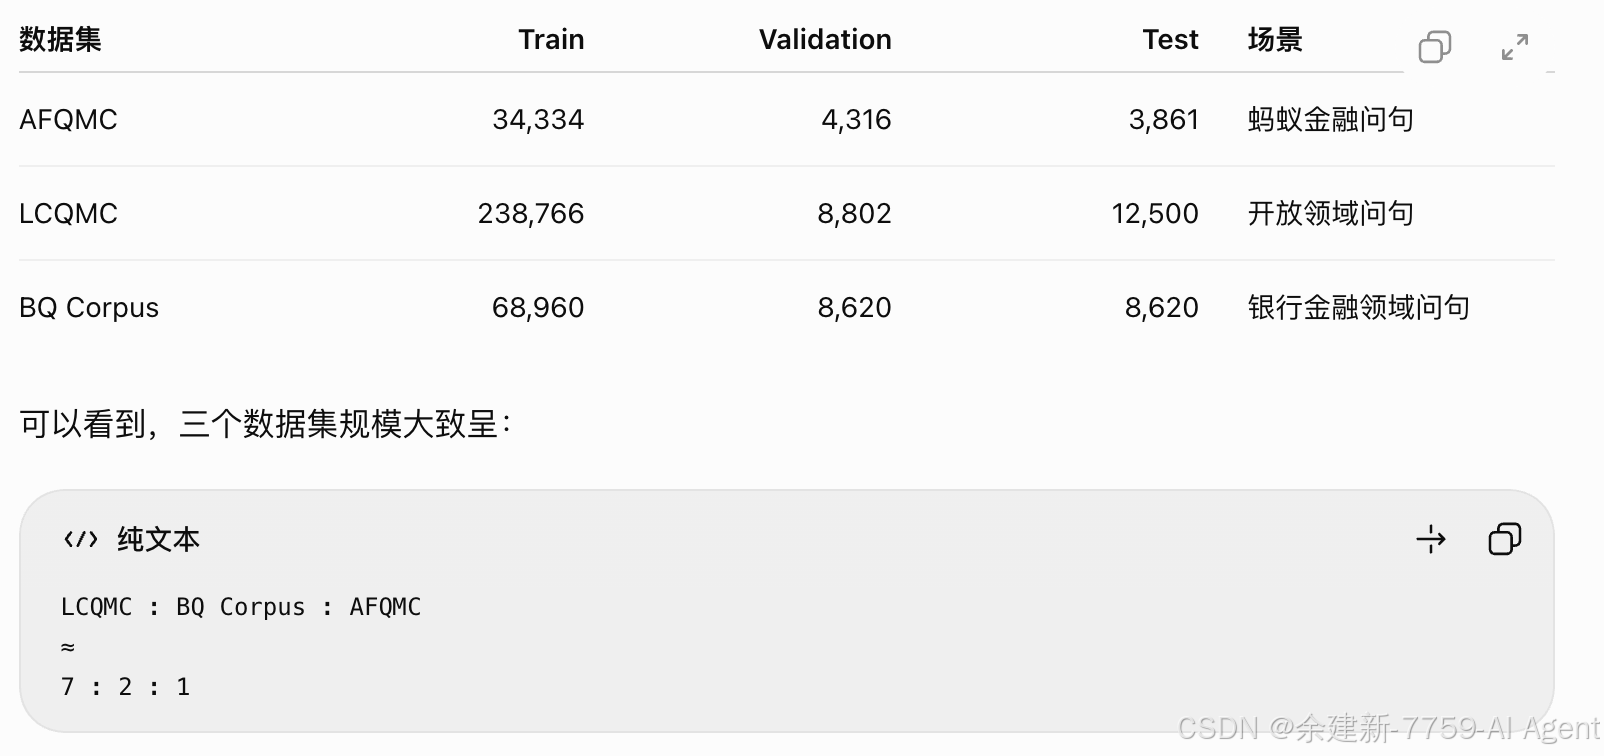
在另外两个文本匹配数据集试验不同方法效果。
解读:
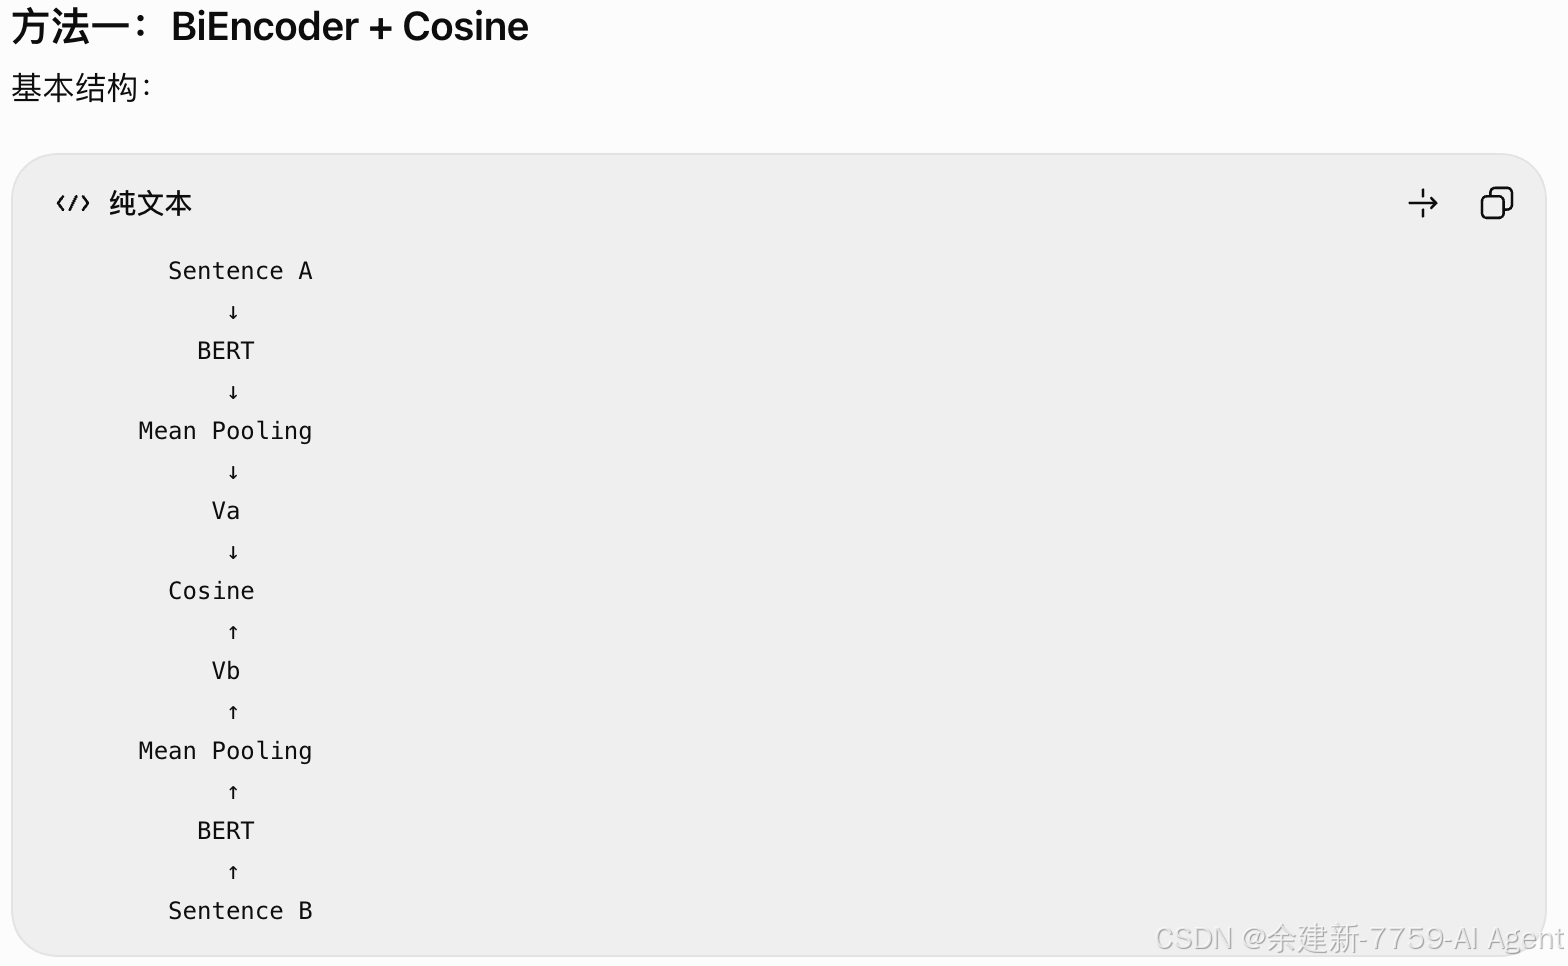
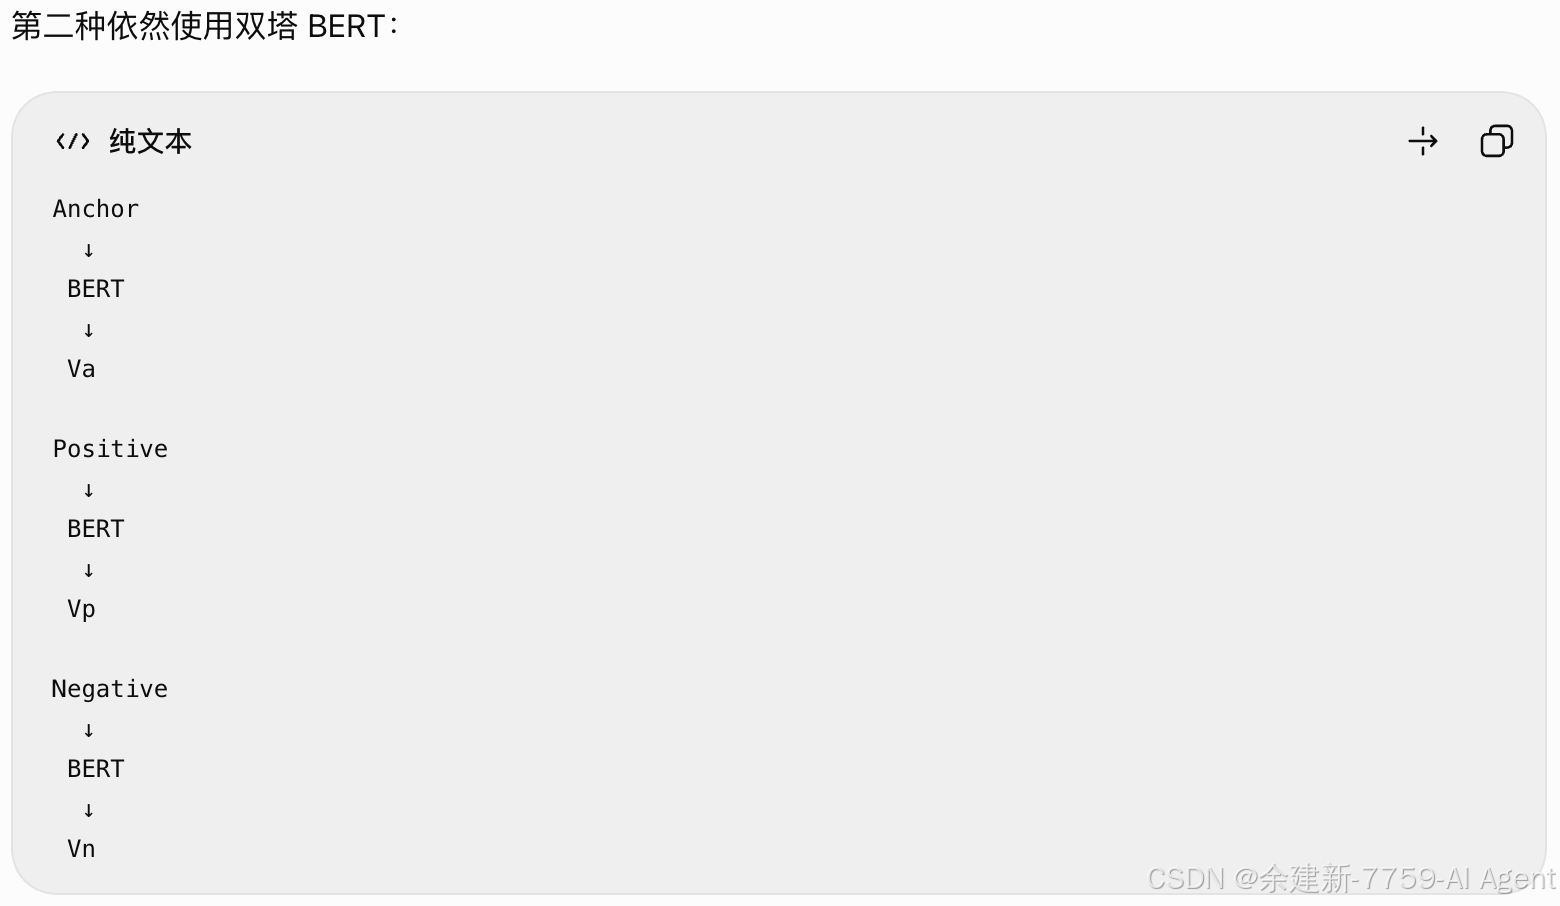
在已有 AFQMC 文本匹配实验基础上,保持模型、超参数和训练流程基本不变,将相同的 3 种方法迁移到 LCQMC 和 BQ Corpus 两个数据集上,比较不同文本匹配方法在不同数据分布下的效果。
本次实验的方法:
内容:
python
pip install torch transformers scikit-learn pandas tqdm

1. BiEncoder
import torch
import torch.nn as nn
import torch.nn.functional as F

from transformers import AutoModel


class BiEncoder(nn.Module):

    def __init__(
        self,
        model_name="bert-base-chinese"
    ):
        super().__init__()

        self.bert = AutoModel.from_pretrained(
            model_name
        )

    def mean_pooling(
        self,
        hidden,
        attention_mask
    ):
        mask = attention_mask.unsqueeze(-1)

        hidden = hidden * mask

        return hidden.sum(dim=1) / mask.sum(
            dim=1
        ).clamp(min=1e-9)

    def encode(
        self,
        input_ids,
        attention_mask
    ):

        output = self.bert(
            input_ids=input_ids,
            attention_mask=attention_mask
        )

        embedding = self.mean_pooling(
            output.last_hidden_state,
            attention_mask
        )

        # L2 Normalization
        embedding = F.normalize(
            embedding,
            p=2,
            dim=1
        )

        return embedding

    def forward(
        self,
        input_ids_a,
        attention_mask_a,
        input_ids_b,
        attention_mask_b
    ):

        va = self.encode(
            input_ids_a,
            attention_mask_a
        )

        vb = self.encode(
            input_ids_b,
            attention_mask_b
        )

        return va, vb


2. CrossEncoder
import torch.nn as nn

from transformers import AutoModel


class CrossEncoder(nn.Module):

    def __init__(
        self,
        model_name="bert-base-chinese"
    ):
        super().__init__()

        self.bert = AutoModel.from_pretrained(
            model_name
        )

        hidden_size = (
            self.bert.config.hidden_size
        )

        self.dropout = nn.Dropout(0.1)

        self.classifier = nn.Linear(
            hidden_size,
            2
        )

    def forward(
        self,
        input_ids,
        attention_mask,
        token_type_ids=None
    ):

        output = self.bert(
            input_ids=input_ids,
            attention_mask=attention_mask,
            token_type_ids=token_type_ids
        )

        cls = output.last_hidden_state[:, 0]

        cls = self.dropout(cls)

        logits = self.classifier(cls)

        return logits