作者:来自 Elastic David Pilato
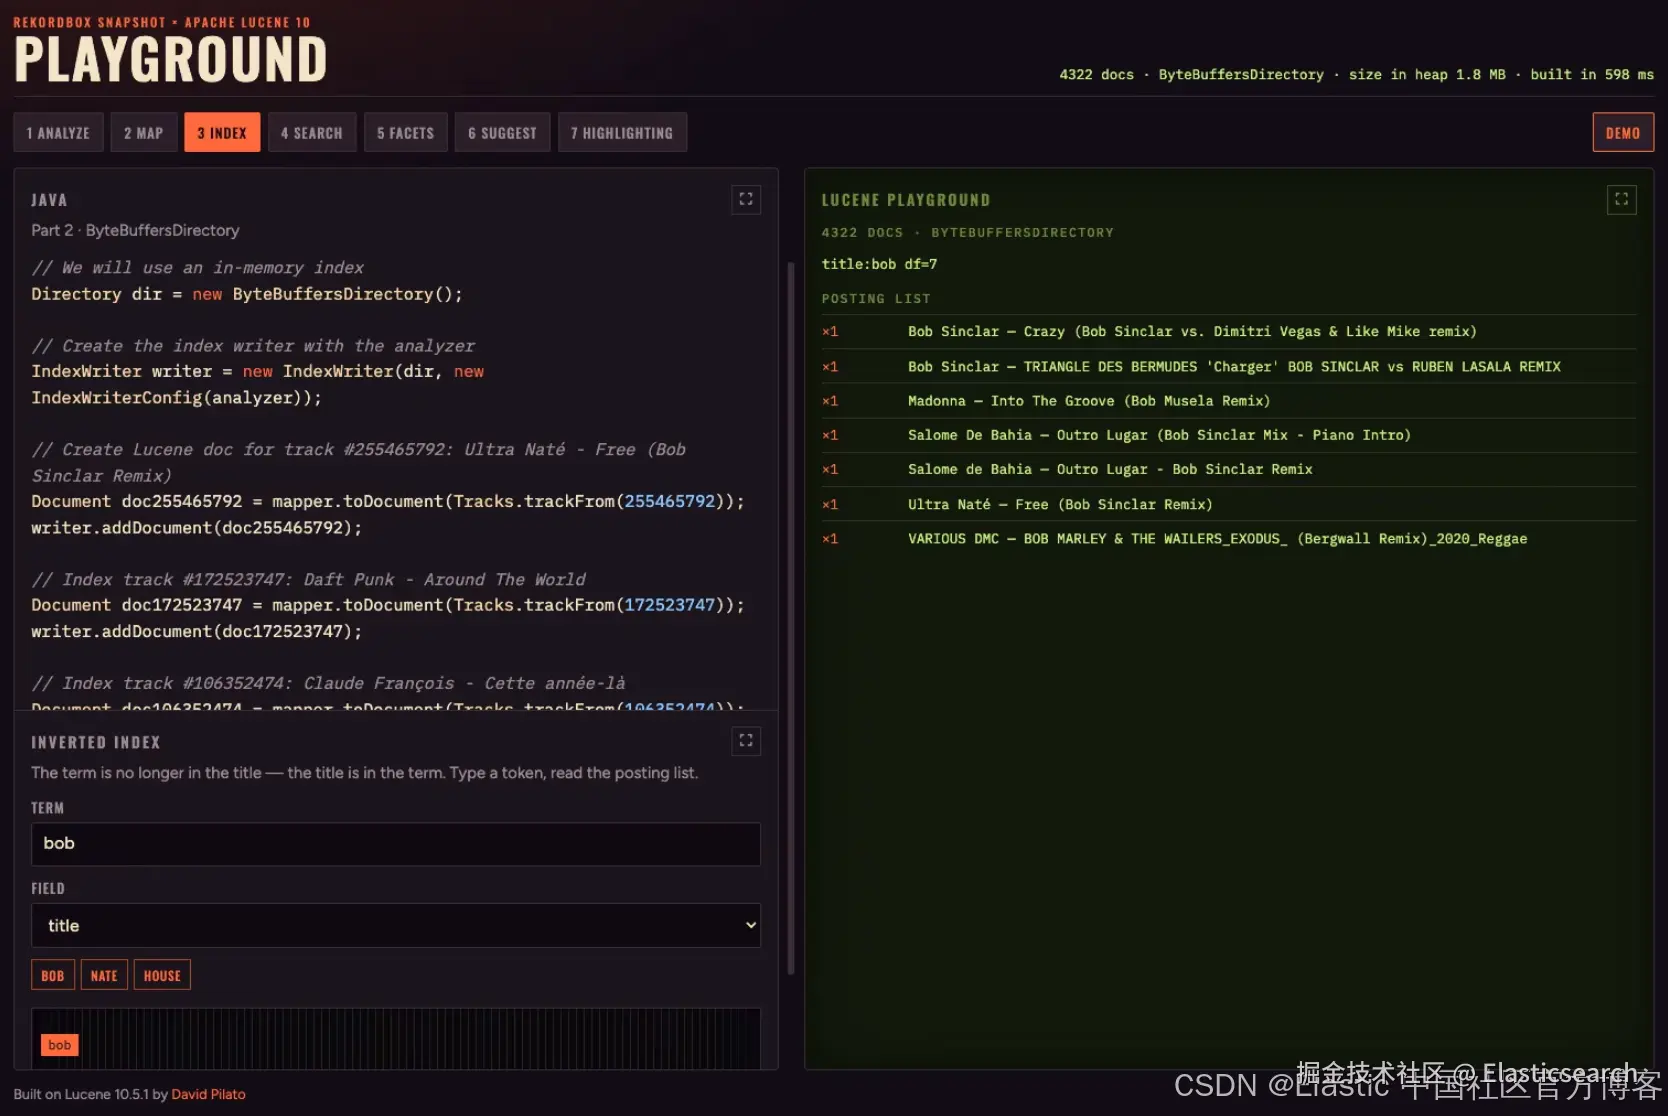
在**上一篇文章中,我们将 Lucene 添加到了 Maven 中,选择了一个 analyzer,并将 Track Bean 映射为一个 可用于搜索的** Lucene Document。这只是故事的一半:你仍然需要一个用于管理 索引的小型 类 --- --- 同时,你还应该了解,对于像 bob 这样的 token 来说,"倒排"究竟意味着什么。
管理索引生命周期
将 Lucene 的底层类型封装在一个专门用于你的 Bean 的类中。创建 directory 和 writer,重新构建索引或进行修改,并在进程关闭时关闭所有资源。这个 playground 也使用内存中的 ByteBuffersDirectory 来完成相同的操作 --- --- 直接使用 addDocument(doc),暂时还不进行 facet 重写:
ini
`
1. Directory dir = new ByteBuffersDirectory();
3. // Create the index writer with the analyzer
4. IndexWriter writer = new IndexWriter(dir, new IndexWriterConfig(analyzer));
6. // Create Lucene doc for track #255465792: Ultra Naté - Free (Bob Sinclar Remix)
7. Document doc255465792 = mapper.toDocument(Tracks.trackFrom(255465792));
8. writer.addDocument(doc255465792);
10. // Index track #172523747: Daft Punk - Around The World
11. Document doc172523747 = mapper.toDocument(Tracks.trackFrom(172523747));
12. writer.addDocument(doc172523747);
14. // Index track #106352474: Claude François - Cette année-là
15. Document doc106352474 = mapper.toDocument(Tracks.trackFrom(106352474));
16. writer.addDocument(doc106352474);
18. // Commit all the documents that have been indexed so far
19. writer.commit();
`AI写代码对于完整的库,在一个写锁下清空并重新加载:
markdown
`

1.  public void rebuild(List<Track> tracks) throws IOException {
2.      synchronized (writeLock) {
3.          writer.deleteAll();
4.          for (Track track : tracks) {
5.              writer.addDocument(TrackDocumentMapper.toDocument(track));
6.          }
7.          writer.commit();
8.      }
9.  }

`AI写代码
ByteBuffersDirectory 将整个索引保存在堆中------非常适合在进程启动时重新构建本地库。如果需要在重启后保留数据,则可以换成 FSDirectory.open(path)。
按 id 执行 Upsert / 删除
markdown
`
1. public void upsert(Track track) throws IOException {
2. synchronized (writeLock) {
3. writer.updateDocument(
4. new Term(TrackDocumentMapper.ID, track.id()),
5. TrackDocumentMapper.toDocument(track));
6. writer.commit();
7. }
8. }
10. public void deleteById(String trackId) throws IOException {
11. synchronized (writeLock) {
12. writer.deleteDocuments(new Term(TrackDocumentMapper.ID, trackId));
13. writer.commit();
14. }
15. }
`AI写代码Close
scss
`

1.  writer.close();
2.  directory.close(); // order matters --- writer first

`AI写代码
如果索引由多个请求线程共享,请使用锁来串行化 mutation。
保持索引处于热状态并保持一致
在启动时从事实来源重新构建一次。对于单行编辑,优先使用按 id 执行 upsert / delete ;对于批量操作或同步失败,则使用完整重建。永远不要将 Lucene 视为 权威数据 源。
实际数据(~4k 条 track)
在一个包含 4,322 条 track 的本地音乐库中(使用内存中的 ByteBuffersDirectory),一次完整重建的情况如下:
| 指标 | 值 |
|---|---|
| 文档数 | 4,322 |
| 耗时 | ~400 ms |
| 使用的内存 | ~1.1 MB |
因此,对于几千个 Bean 来说,完整重建的成本足够低,可以在启动时执行 --- --- 即使增量同步失败,也可以将其作为回退方案。(如果稍后添加 suggest dictionary,它会存放在自己的 Directory 中,并额外占用少量 RAM。)
倒排索引
统一技术术语和中英文格式修正双破折号的排版格式
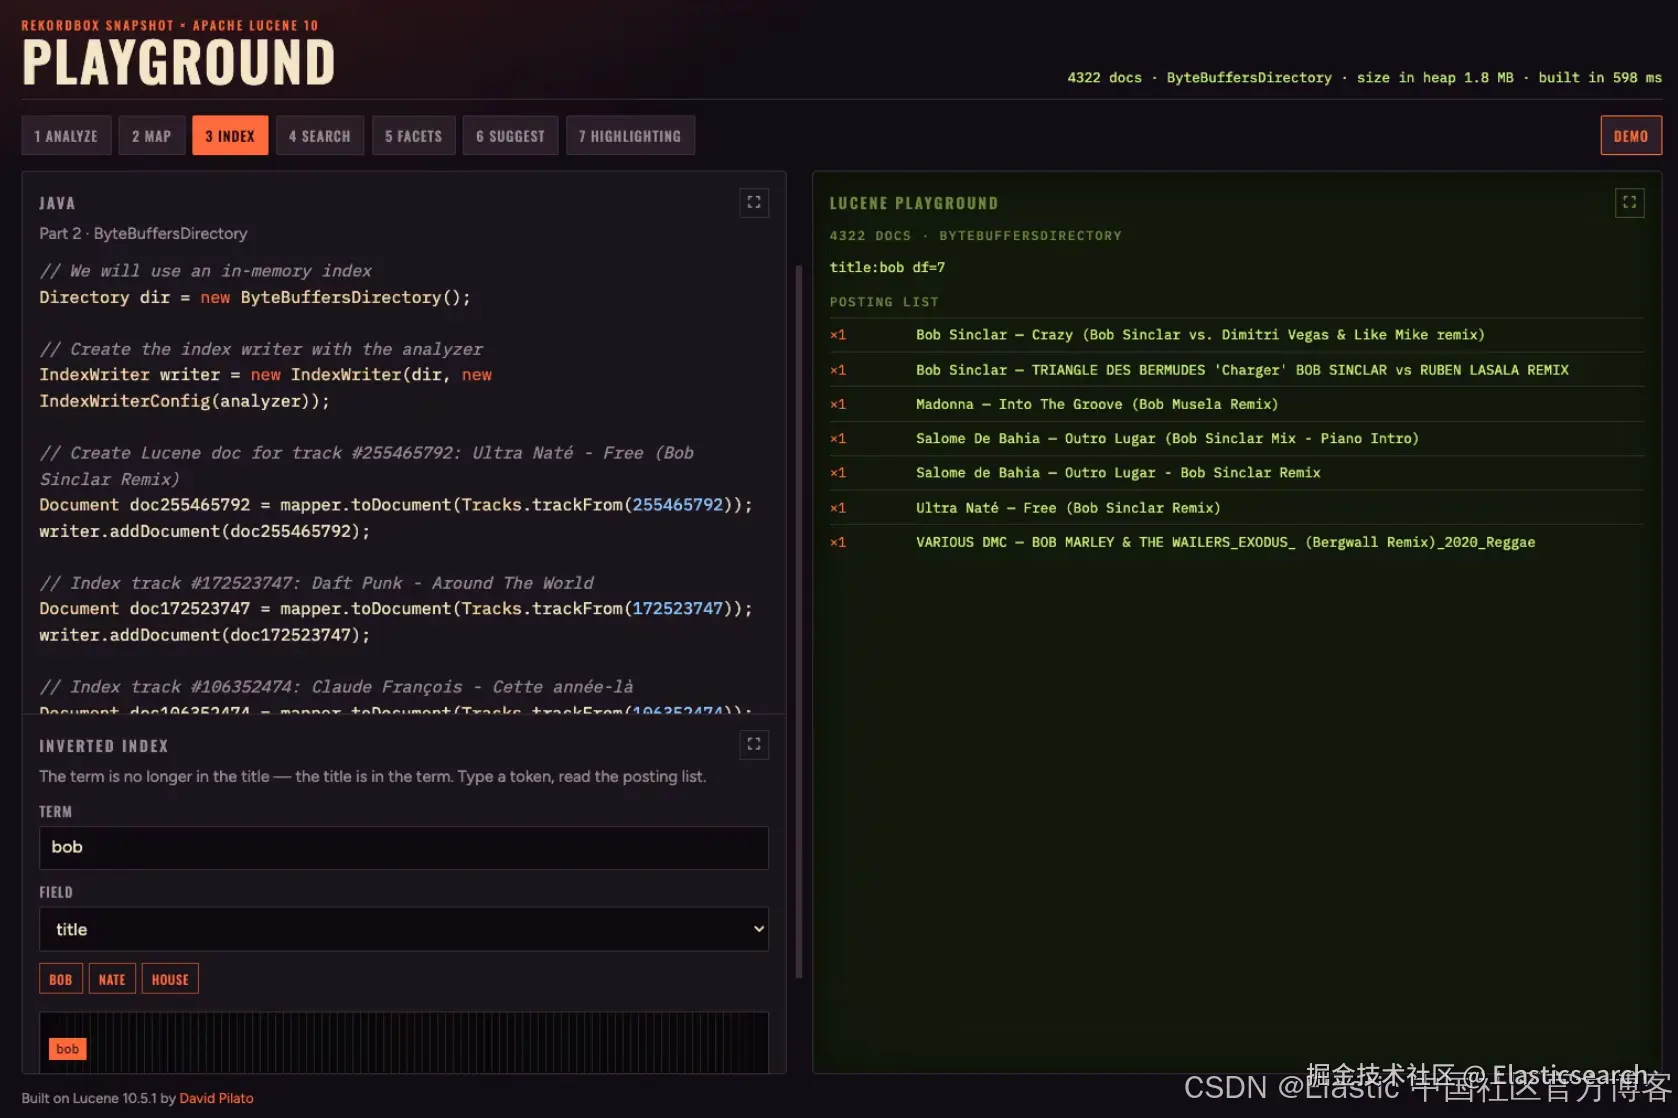
字段 title 上的 term bob:包含该 token 的文档的 posting list。
提交后,Lucene 不会 在每个文档中保存一个单词集合。它保存的是一个倒排 映射:term → 文档(posting list)。在 title 上输入 bob,你会读取每个标题 token 化为 bob 的 track --- --- 包括 Free (Bob Sinclar Remix)。
artist 上也是同样的原理。经过分析后,6 个 track 对应 4 个不同的名称:
| 文档 | Artist(存储值) |
|---|---|
| 1、3 | Bob Sinclar |
| 2 | Bob Marley |
| 4、5 | Claude François |
| 6 | François Valery |
Lucene 不会存储这张表。它存储的是排序后的 倒排映射 --- --- 转换为小写并进行 ASCII 折叠(François → francois):
markdown
`

1.  artist:bob       →  1, 2, 3
2.  artist:claude    →  4, 5
3.  artist:francois  →  4, 5, 6
4.  artist:marley    →  2
5.  artist:sinclar   →  1, 3
6.  artist:valery    →  6

`AI写代码
这个 posting list 就是你进行搜索时所使用的内容。我们将在下一篇文章中详细介绍这一点。
完整演示代码位于 GitHub:lucene-search-tracks。