运行成功的记录
平台:带有GPU的服务器
运行的命令
bash
git clone https://github.com/hiyouga/LLaMA-Factory.git
cd LLaMA-Factory/
conda create -n py310 python=3.10
conda activate py310
由于服务器不能直接从huggingface上下载Qwen1.5-0.5B,但本地可以,所以是直接上传的方式
然后执行如下命令,则执行成功
CUDA_VISIBLE_DEVICES=0,1 llamafactory-cli chat --model_name_or_path ./Qwen1.5-0.5B --template "qwen"
// 这个--template是怎么选择呢,/Users/wangfeng/code/LLaMA-Factory/src/llamafactory/data/template.py,在这个当中有进行规定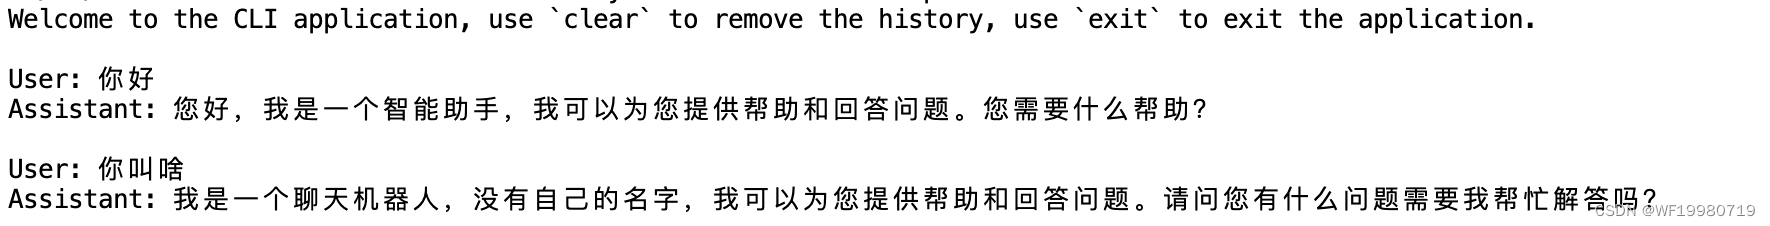
以下的记录整个思考过程
参考资料
教程:https://articles.zsxq.com/id_zdtwnsam9vbw.html
v0.6.1 版本:https://github.com/hiyouga/LLaMA-Factory/blob/v0.6.1/README_zh.md
在Mac上的情况
history 20
bash
  672  conda create -n py310 python=3.10
  673  conda activate py310
  674  pip install -r requirements.txt -i https://pypi.tuna.tsinghua.edu.cn/simple --ignore-installed
  675  ls
  676  git lfs install
  677  history -10
  678  brew install git-lfs
  679  git lfs install
  680  git clone git@hf.co:Qwen/Qwen1.5-0.5B
  (py310) (myenv) ➜  LLaMA-Factory git:(main) git clone https://huggingface.co/Qwen/Qwen1.5-0.5B
Cloning into 'Qwen1.5-0.5B'...
remote: Enumerating objects: 76, done.
remote: Counting objects: 100% (9/9), done.
remote: Compressing objects: 100% (9/9), done.
remote: Total 76 (delta 2), reused 0 (delta 0), pack-reused 67 (from 1)
Unpacking objects: 100% (76/76), 3.62 MiB | 542.00 KiB/s, done.
Downloading model.safetensors (1.2 GB)
Error downloading object: model.safetensors (a88bcf4): Smudge error: Error downloading model.safetensors (a88bcf41b3fa9a20031b6b598abc11f694e35e0b5684d6e14dbe7e894ebbb080): batch response: Post "https://huggingface.co/Qwen/Qwen1.5-0.5B.git/info/lfs/objects/batch": dial tcp: lookup huggingface.co: no such host

Errors logged to '/Users/wangfeng/code/LLaMA-Factory/Qwen1.5-0.5B/.git/lfs/logs/20240601T165753.939959.log'.
Use `git lfs logs last` to view the log.
error: external filter 'git-lfs filter-process' failed
fatal: model.safetensors: smudge filter lfs failed
warning: Clone succeeded, but checkout failed.
You can inspect what was checked out with 'git status'
and retry with 'git restore --source=HEAD :/'
  681  git clone https://huggingface.co/Qwen/Qwen1.5-0.5B
  682* CUDA_VISIBLE_DEVICES=0 python src/cli_demo.py \\n    --model_name_or_path path_to_llama_model \\n    --adapter_name_or_path path_to_checkpoint \\n    --template default \\n    --finetuning_type lora
  // 这个是v0.6.1的命令,但直接git的时候是最新版本的,所以这里失败
  683  git clone https://huggingface.co/Qwen/Qwen1.5-0.5B
  684* pwd
  685* CUDA_VISIBLE_DEVICES=0 llamafactory-cli chat examples/inference/llama3_lora_sft.yaml
  // llama3没有权限进行访问
  686* conda env list
  687* pip install -e .[torch,metrics]
  688* ls
  689* pip install -e '.[torch,metrics]'
  690* CUDA_VISIBLE_DEVICES=0 llamafactory-cli chat examples/inference/llama3_lora_sft.yaml
  691* llamafactory-cli help
  692* llamafactory-cli chat -h
  693  ls -al Qwen1.5-0.5B
  694  llamafactory-cli chat --model_name_or_path ./Qwen1.5-0.5B --template default
在本地的mac上运行llamafactory-cli chat --model_name_or_path ./Qwen1.5-0.5B --template default,出现如下错误:说明其不能在苹果的芯片上进行推理
bash
Traceback (most recent call last):
  File "/opt/miniconda3/envs/py310/lib/python3.10/threading.py", line 1016, in _bootstrap_inner
    self.run()
  File "/opt/miniconda3/envs/py310/lib/python3.10/threading.py", line 953, in run
    self._target(*self._args, **self._kwargs)
  File "/opt/miniconda3/envs/py310/lib/python3.10/site-packages/torch/utils/_contextlib.py", line 115, in decorate_context
    return func(*args, **kwargs)
  File "/opt/miniconda3/envs/py310/lib/python3.10/site-packages/transformers/generation/utils.py", line 1591, in generate
    model_kwargs["attention_mask"] = self._prepare_attention_mask_for_generation(
  File "/opt/miniconda3/envs/py310/lib/python3.10/site-packages/transformers/generation/utils.py", line 468, in _prepare_attention_mask_for_generation
    raise ValueError(
ValueError: Can't infer missing attention mask on `mps` device. Please provide an `attention_mask` or use a different device.