加权CE_loss和BCE_loss稍有不同
1.标签为long类型,BCE标签为float类型
2.当reduction为mean时计算每个像素点的损失的平均,BCE除以像素数得到平均值,CE除以像素对应的权重之和得到平均值。
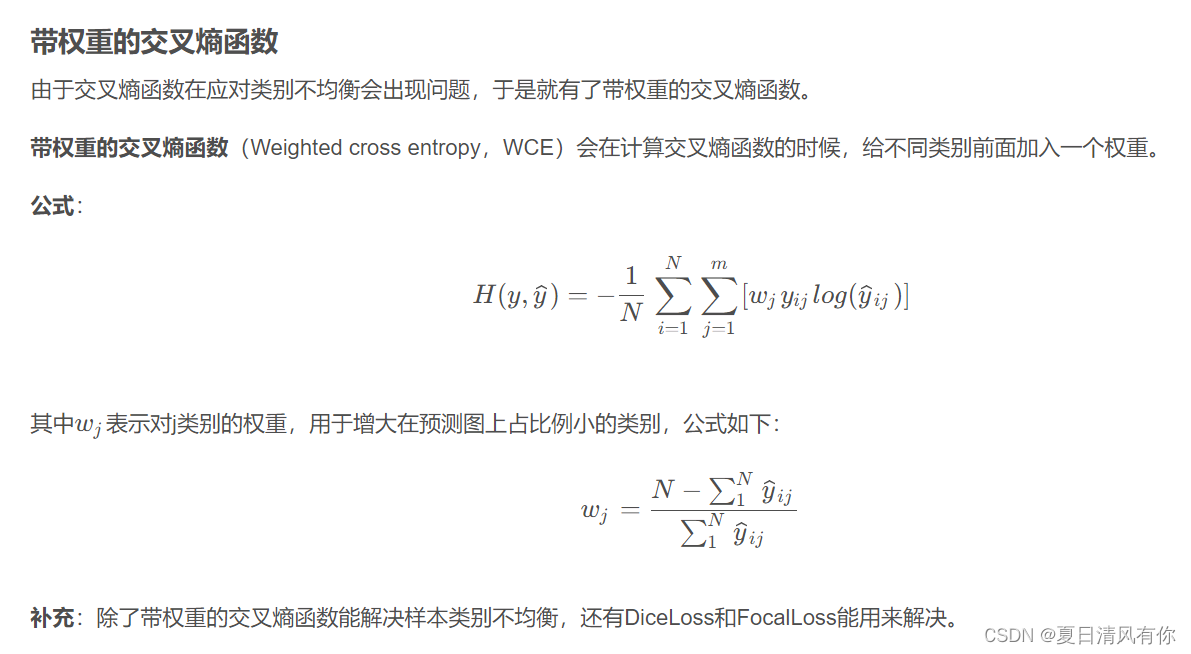
参数配置torch.nn.CrossEntropyLoss(weight=None,size_average=None,ignore_index=-100,reduce=None,reduction='mean',label_smoothing=0.0)
增加加权的CE_loss代码实现
python
# 总之, CrossEntropyLoss() = softmax + log + NLLLoss() = log_softmax + NLLLoss(), 具体等价应用如下:
import torch
import torch.nn as nn
import torch.nn.functional as F
import random
import numpy as np

class CrossEntropyLoss2d(nn.Module):
    def __init__(self, weight=None):
      super(CrossEntropyLoss2d, self).__init__()
       self.nll_loss = nn.CrossEntropyLoss(weight, reduction='mean')
    def forward(self, preds, targets):
        return self.nll_loss(preds, targets)
语义分割类别计算
python
class CE_w_loss(nn.Module):
    def __init__(self,ignore_index=255):
        super(CE_w_loss, self).__init__()
        self.ignore_index = ignore_index
        # self.CE = nn.CrossEntropyLoss(ignore_index=self.ignore_index)
    def forward(self, outputs, targets):
        class_num = outputs.shape[1]
        # print("class_num :",class_num )
        # # 计算每个类别在整个 batch 中的像素数占比
        class_pixel_counts = torch.bincount(targets.flatten(), minlength=class_num)  # 假设有class_num个类别
        class_pixel_proportions = class_pixel_counts.float() / torch.numel(targets)
        # # 根据类别占比计算权重
        class_weights = 1.0 / (torch.log(1.02 + class_pixel_proportions)).double()  # 使用对数变换平衡权重
        # # print("class_weights :",class_weights)
        #
        # 定义交叉熵损失函数,并使用动态计算的类别权重
        criterion = nn.CrossEntropyLoss(ignore_index=self.ignore_index,weight= class_weights)

        # 计算损失
        loss = criterion(outputs, targets)
        print(loss.item())  # 打印损失值
        return loss

    np.random.seed(666)
    pred = np.ones((2, 5, 256,256))
    seg = np.ones((2, 5, 256, 256)) # 灰度
    label = np.ones((2, 256, 256))  # 灰度

    pred = torch.from_numpy(pred)
    seg = torch.from_numpy(seg).int()  # 灰度
    label = torch.from_numpy(label).long()
     ce = CE_w_loss()
    loss = ce(pred, label)
    print("loss:",loss.item())
报错
Weight=torch.from_numpy(np.array(0.1, 0.8, 1.0, 1.0)).float() 报错
Weight=torch.from_numpy(np.array(0.1, 0.8, 1.0, 1.0)).double() 正确
参考:1https://blog.csdn.net/CSDN_of_ding/article/details/111515226
2 https://blog.csdn.net/qq_40306845/article/details/137651442
3 https://www.zhihu.com/question/400443029/answer/2477658229