1.环境
conda create -n techgpt python=3.10
conda activate techgpt
2.安装依赖
pip install transformers
pip install torch
pip install accelerate
3.克隆项目
开一下学术加速,然后克隆。
source /etc/network_turbo
git clone https://github.com/neukg/TechGPT-2.0.git
4.登录 Hugging Face 账户
pip install huggingface_hub
huggingface-cli login
5.下载模型到本地
python
from huggingface_hub import snapshot_download

snapshot_download(
    repo_id="neukg/TechGPT-2.0-Qwen1.5-7b",
    local_dir="/root/autodl-tmp/TechGPT-2.0-Qwen1.5-7b",
    resume_download=True,
    local_dir_use_symlinks=False
)
6.运行
python
from transformers import AutoTokenizer, AutoModelForCausalLM, GenerationConfig
import torch

# ✅ Qwen 的系统提示语(支持中英)
DEFAULT_SYSTEM_PROMPT = "You are a helpful assistant."

# ✅ Qwen 默认不使用 Alpaca 的 [INST] 模板,直接使用自然语言 prompt
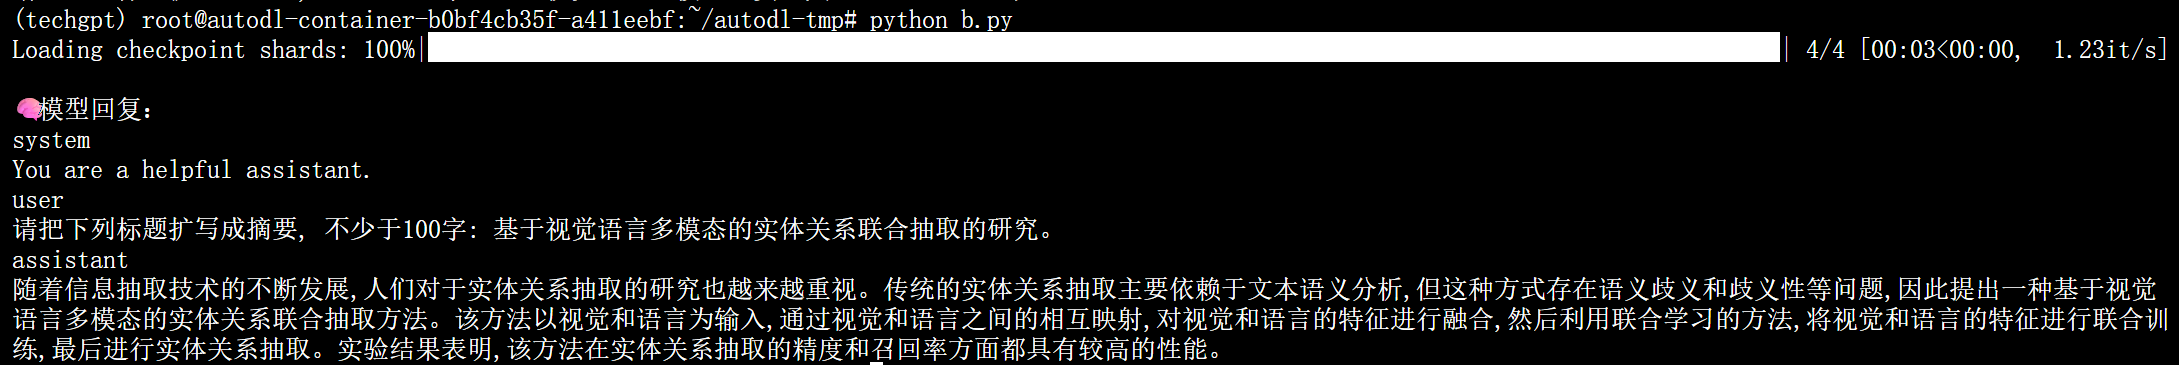
example = "请把下列标题扩写成摘要, 不少于100字: 基于视觉语言多模态的实体关系联合抽取的研究。"

# ✅ 模型路径(改为你的 Qwen 模型保存目录)
ckpt_path = "/root/autodl-tmp/TechGPT-2.0-Qwen1.5-7b"

# ✅ 加载模型与 tokenizer(注意 trust_remote_code)
tokenizer = AutoTokenizer.from_pretrained(ckpt_path, trust_remote_code=True)
model = AutoModelForCausalLM.from_pretrained(
    ckpt_path,
    device_map="auto",                  # 自动选择 GPU
    torch_dtype=torch.float16,
    trust_remote_code=True
)
model.eval()

# ✅ Qwen 推荐使用的生成配置
generation_config = GenerationConfig(
    temperature=0.8,
    top_p=0.8,
    top_k=40,
    num_beams=1,
    do_sample=True,
    eos_token_id=tokenizer.eos_token_id,
    pad_token_id=tokenizer.pad_token_id,
    max_new_tokens=256,
)

# ✅ 构造输入
example = "请把下列标题扩写成摘要, 不少于100字: 基于视觉语言多模态的实体关系联合抽取的研究。"

prompt = f"<|im_start|>system\n{DEFAULT_SYSTEM_PROMPT}<|im_end|>\n<|im_start|>user\n{example}<|im_end|>\n<|im_start|>assistant\n"

inputs = tokenizer(prompt, return_tensors="pt").to(model.device)


# ✅ 生成回复
with torch.no_grad():
    generation_output = model.generate(
        **inputs,
        generation_config=generation_config,
        return_dict_in_generate=True,
        output_scores=True
    )
    output = generation_output.sequences[0]
    output_text = tokenizer.decode(output, skip_special_tokens=True)

# ✅ 打印结果
print("\n🧠 模型回复:")
print(output_text)
7.效果