######################################################################################################################
import torch
import torchvision
from torch import nn
from torch.nn import functional as F
import os
import random
import numpy as np
import torchvision.models as models
from torch.utils.data import DataLoader
import matplotlib.pyplot as plt
from tqdm import tqdm
from torchvision import datasets,transforms
from sklearn.metrics import accuracy_score
import warnings
from datetime import datetime
warnings.filterwarnings("ignore")
###########################################################################################################################################
def set_stable_seed(seed=42):
    #固定一下随机数种子保证结果可以复现:seed=42
    random.seed(seed)
    os.environ['PYTHONHASHSEED'] = str(seed)
    np.random.seed(seed)
    torch.manual_seed(seed)
    torch.backends.cudnn.benchmark = False
    torch.backends.cudnn.deterministic = True
    torch.use_deterministic_algorithms(False)
    os.environ['CUBLAS_WORKSPACE_CONFIG'] = ':4096:8'
###########################################################################################################################################
###########################################################################################################################################
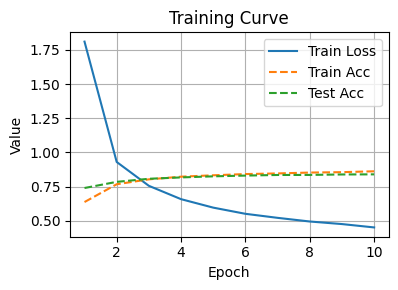
def plot_metrics(train_loss_list, train_acc_list, test_acc_list, title='Training Curve'):
    epochs = range(1, len(train_loss_list) + 1)
    time=datetime.now().strftime("%d-%H-%M-%S")
    plt.figure(figsize=(4, 3))
    plt.plot(epochs, train_loss_list, label='Train Loss')
    plt.plot(epochs, train_acc_list, label='Train Acc',linestyle='--')
    plt.plot(epochs, test_acc_list, label='Test Acc', linestyle='--')
    plt.xlabel('Epoch')
    plt.ylabel('Value')
    plt.title(title)
    plt.legend()
    plt.grid(True)
    plt.tight_layout()
    plt.savefig(f"pascal-voc-21-result-{time}.png",dpi=300)
    #plt.show()
def train_model(model,train_data,test_data,num_epochs,criterion,optimizer):
    train_loss_list = []
    train_acc_list = []
    test_acc_list = []
    for epoch in range(num_epochs):
        total_loss=0
        total_acc_sample=0
        total_samples=0
        loop1=tqdm(train_data,desc=f"EPOCHS[{epoch+1}/{num_epochs}]")
        for X,y in loop1:
            #print(X.shape)
            #X=X.reshape(X.shape[0],-1)
            #print(X.shape)
            X=X.to(device)
            y = torch.tensor(y).to(device)
            y_hat=model(X)
            loss=criterion(y_hat,y)
            optimizer.zero_grad()
            loss.backward()
            optimizer.step()
            #loss累加
            total_loss+=loss.item()*X.shape[0]
            y_pred = y_hat.argmax(dim=1).detach().cpu().numpy().flatten()  # 扁平化为一维
            y_true = y.detach().cpu().numpy().flatten()  # 扁平化为一维
            total_acc_sample += accuracy_score(y_true, y_pred) * X.shape[0]
            total_samples+=X.shape[0]
        test_acc_samples=0
        test_samples=0
        loop2=tqdm(test_data,desc=f"EPOCHS[{epoch+1}/{num_epochs}]")
        for X,y in loop2:
            X=X.to(device)
            y = torch.tensor(y).to(device)
            #X=X.reshape(X.shape[0],-1)
            y_hat=model(X)
            y_pred = y_hat.argmax(dim=1).detach().cpu().numpy().flatten()  # 扁平化为一维
            y_true = y.detach().cpu().numpy().flatten()  # 扁平化为一维
            test_acc_samples+=accuracy_score(y_pred,y_true)*X.shape[0]#保存样本数
            test_samples+=X.shape[0]
        avg_train_loss=total_loss/total_samples
        avg_train_acc=total_acc_sample/total_samples
        avg_test_acc=test_acc_samples/test_samples
        train_loss_list.append(avg_train_loss)
        train_acc_list.append(avg_train_acc)
        test_acc_list.append(avg_test_acc)
        print(f"Epoch {epoch+1}: Train Loss: {avg_train_loss:.4f},Trian Accuracy: {avg_train_acc:.4f},test Accuracy: {avg_test_acc:.4f}")
    plot_metrics(train_loss_list, train_acc_list, test_acc_list)
    #return model
###########################################################################################################################################
######################################################################################################################
#类别参数以及映射:
VOC_COLORMAP = [[0, 0, 0], [128, 0, 0], [0, 128, 0], [128, 128, 0],
                [0, 0, 128], [128, 0, 128], [0, 128, 128], [128, 128, 128],
                [64, 0, 0], [192, 0, 0], [64, 128, 0], [192, 128, 0],
                [64, 0, 128], [192, 0, 128], [64, 128, 128], [192, 128, 128],
                [0, 64, 0], [128, 64, 0], [0, 192, 0], [128, 192, 0],
                [0, 64, 128]]
VOC_CLASSES = ['background', 'aeroplane', 'bicycle', 'bird', 'boat',
               'bottle', 'bus', 'car', 'cat', 'chair', 'cow',
               'diningtable', 'dog', 'horse', 'motorbike', 'person',
               'potted plant', 'sheep', 'sofa', 'train', 'tv/monitor']
######################################################################################################################
#用双线性插值来初始化卷积层:
def bilinear_kernel(in_channels, out_channels, kernel_size):
    factor = (kernel_size + 1) // 2
    if kernel_size % 2 == 1:
        center = factor - 1
    else:
        center = factor - 0.5
    og = (torch.arange(kernel_size).reshape(-1, 1),
          torch.arange(kernel_size).reshape(1, -1))
    filt = (1 - torch.abs(og[0] - center) / factor) * \
           (1 - torch.abs(og[1] - center) / factor)
    weight = torch.zeros((in_channels, out_channels,
                          kernel_size, kernel_size))
    weight[range(in_channels), range(out_channels), :, :] = filt
    return weight
######################################################################################################################
def read_voc_images(voc_dir, is_train=True):
    """读取所有VOC图像并标注"""
    txt_fname = os.path.join(voc_dir, 'ImageSets', 'Segmentation',
                             'train.txt' if is_train else 'val.txt')
    mode = torchvision.io.image.ImageReadMode.RGB
    with open(txt_fname, 'r') as f:
        images = f.read().split()
    features, labels = [], []
    for i, fname in enumerate(images):
        features.append(torchvision.io.read_image(os.path.join(
            voc_dir, 'JPEGImages', f'{fname}.jpg')))
        labels.append(torchvision.io.read_image(os.path.join(
            voc_dir, 'SegmentationClass' ,f'{fname}.png'), mode))
    return features, labels
def voc_colormap2label():
    """构建从RGB到VOC类别索引的映射"""
    colormap2label = torch.zeros(256 ** 3, dtype=torch.long)
    for i, colormap in enumerate(VOC_COLORMAP):
        colormap2label[
            (colormap[0] * 256 + colormap[1]) * 256 + colormap[2]] = i
    return colormap2label
#@save
def voc_label_indices(colormap, colormap2label):
    """将VOC标签中的RGB值映射到它们的类别索引"""
    colormap = colormap.permute(1, 2, 0).numpy().astype('int32')
    idx = ((colormap[:, :, 0] * 256 + colormap[:, :, 1]) * 256
           + colormap[:, :, 2])
    return colormap2label[idx]
def voc_rand_crop(feature, label, height, width):
    """随机裁剪特征和标签图像"""
    rect = torchvision.transforms.RandomCrop.get_params(
        feature, (height, width))
    feature = torchvision.transforms.functional.crop(feature, *rect)
    label = torchvision.transforms.functional.crop(label, *rect)
    return feature, label
class VOCSegDataset(torch.utils.data.Dataset):
    """一个用于加载VOC数据集的自定义数据集"""
    def __init__(self, is_train, crop_size, voc_dir):
        self.transform = torchvision.transforms.Normalize(
            mean=[0.485, 0.456, 0.406], std=[0.229, 0.224, 0.225])
        self.crop_size = crop_size
        features, labels = read_voc_images(voc_dir, is_train=is_train)
        self.features = [self.normalize_image(feature)
                         for feature in self.filter(features)]
        self.labels = self.filter(labels)
        self.colormap2label = voc_colormap2label()
        print('read ' + str(len(self.features)) + ' examples')

    def normalize_image(self, img):
        return self.transform(img.float() / 255)
    #这里需要过滤一下低于crop size的小图片:
    def filter(self, imgs):
        return [img for img in imgs if (
            img.shape[1] >= self.crop_size[0] and
            img.shape[2] >= self.crop_size[1])]

    def __getitem__(self, idx):
        feature, label = voc_rand_crop(self.features[idx], self.labels[idx],
                                       *self.crop_size)
        return (feature, voc_label_indices(label, self.colormap2label))

    def __len__(self):
        return len(self.features)
def load_data_voc(batch_size, crop_size):
    """加载VOC语义分割数据集"""
    voc_dir=r"/data/Public/Datasets/d2l-limu/VOCdevkit/VOC2012/"
    num_workers = 32
    train_iter = torch.utils.data.DataLoader(
        VOCSegDataset(True, crop_size, voc_dir), batch_size,
        shuffle=True, drop_last=True, num_workers=num_workers)
    test_iter = torch.utils.data.DataLoader(
        VOCSegDataset(False, crop_size, voc_dir), batch_size,
        drop_last=True, num_workers=num_workers)
    return train_iter, test_iter
######################################################################################################################
#训练的过程中loss需要变化一下:
class SegLoss(nn.Module):
    def __init__(self):
        super(SegLoss, self).__init__()

    def forward(self, inputs, targets):
        return F.cross_entropy(inputs, targets)
######################################################################################################################
if __name__=='__main__':
    set_stable_seed(seed=42)
    pretrained_net = torchvision.models.resnet18(pretrained=True)
    net = nn.Sequential(*list(pretrained_net.children())[:-2])
    num_classes = 21
    net.add_module('final_conv', nn.Conv2d(512, num_classes, kernel_size=1))
    net.add_module('transpose_conv', nn.ConvTranspose2d(num_classes, num_classes,kernel_size=64, padding=16, stride=32))
    W = bilinear_kernel(num_classes, num_classes, 64)#效果会好一些
    net.transpose_conv.weight.data.copy_(W)
    device=torch.device('cuda' if torch.cuda.is_available() else 'cpu')
    net.to(device)
    criterion=SegLoss()
    batch_size, crop_size = 32, (320, 480)
    train_iter, test_iter = load_data_voc(batch_size, crop_size)
    optimizer=torch.optim.SGD(net.parameters(),lr=0.001,momentum=0.9)
    train_model(net,train_iter,test_iter,num_epochs=10,criterion=criterion,optimizer=optimizer)