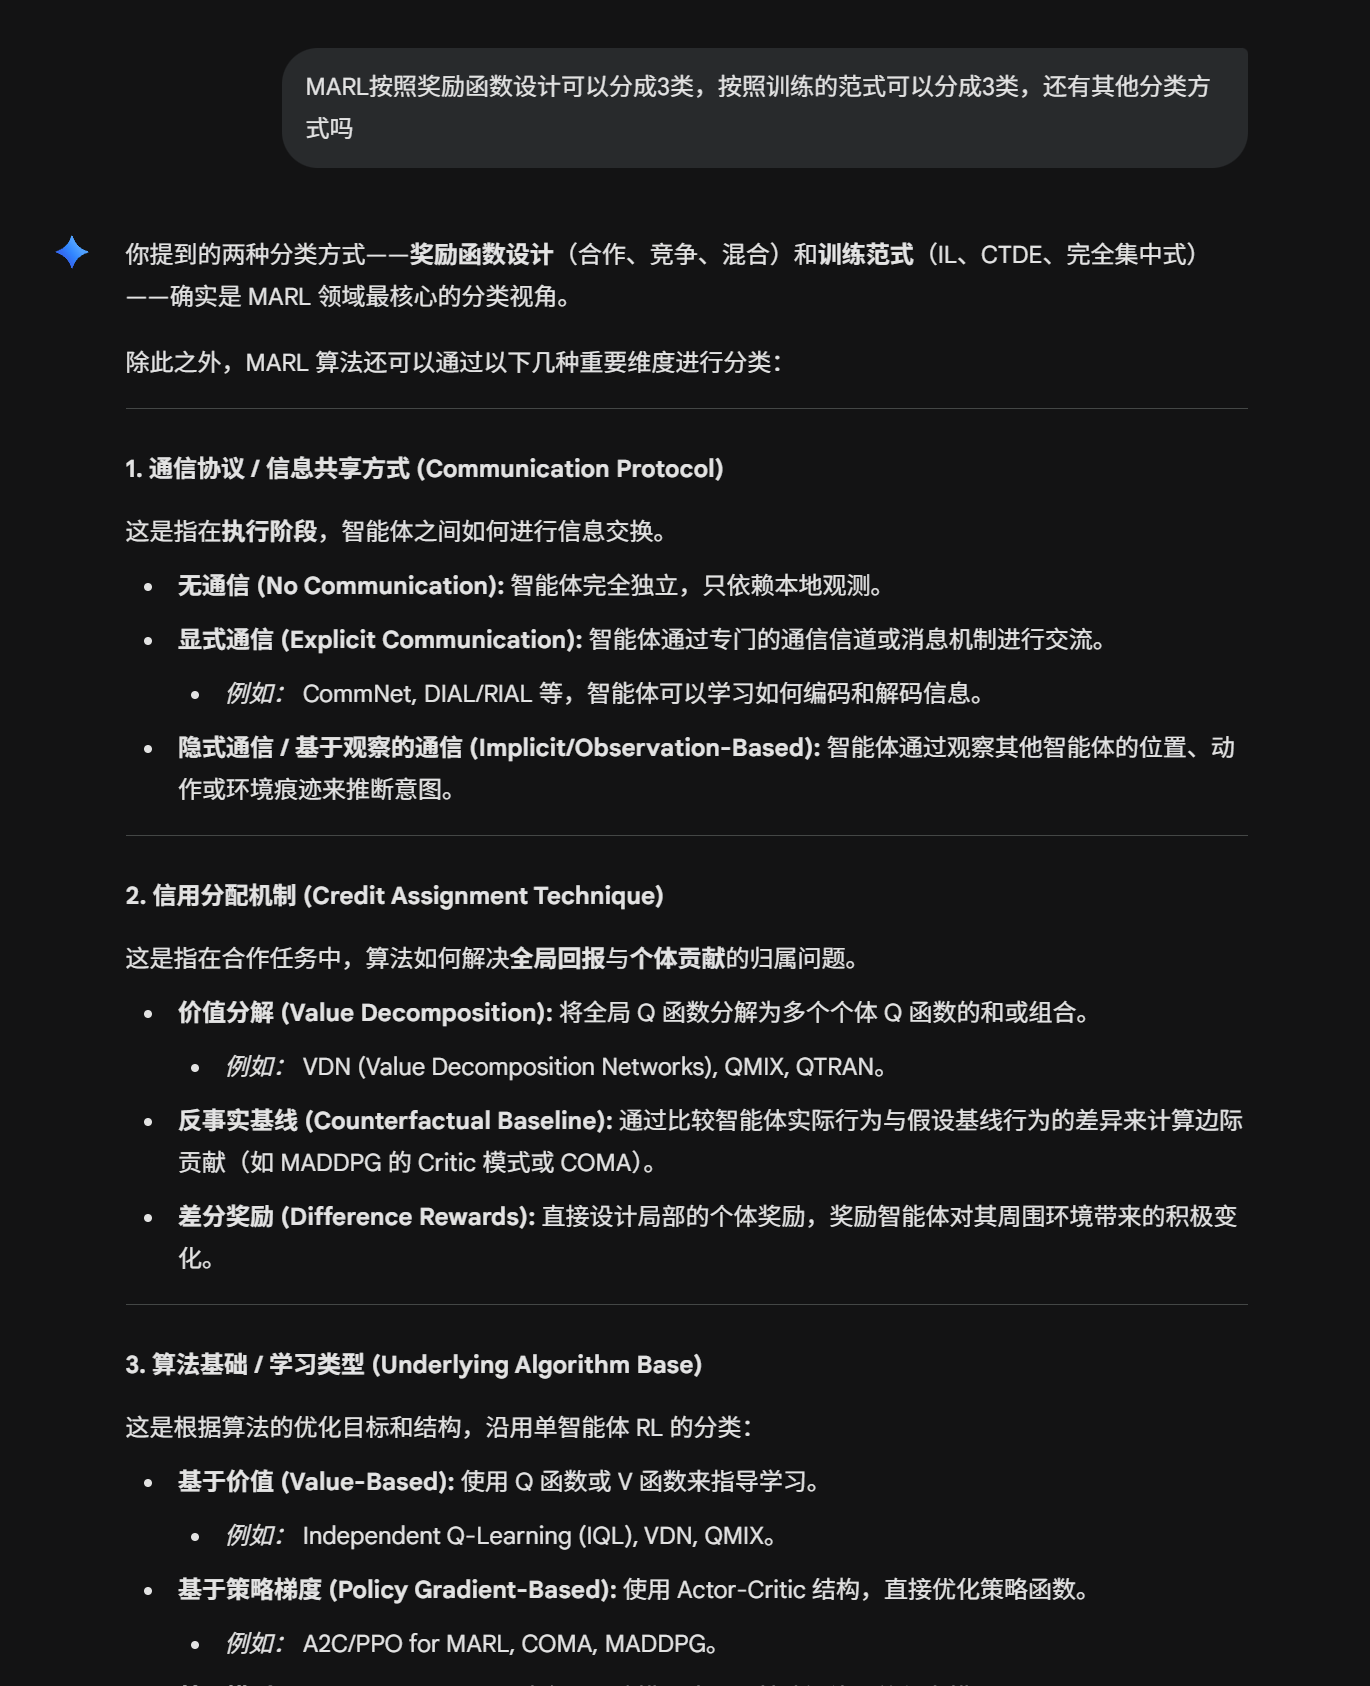
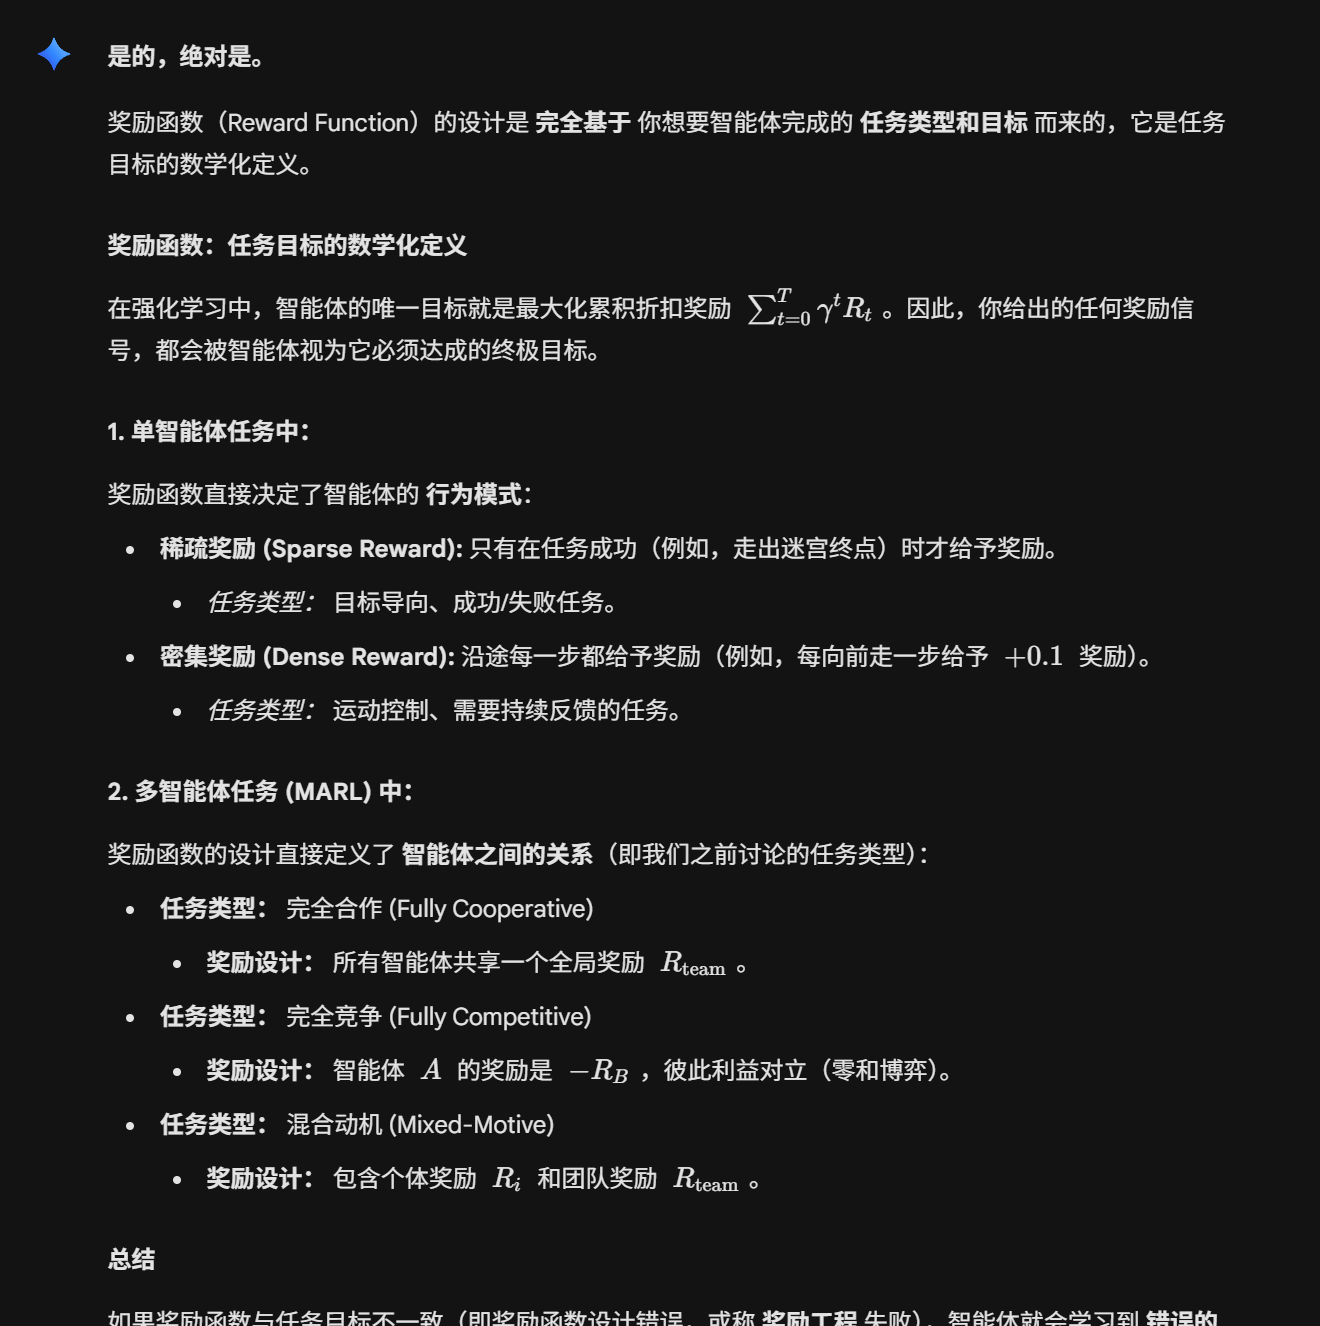
MARL
MPE
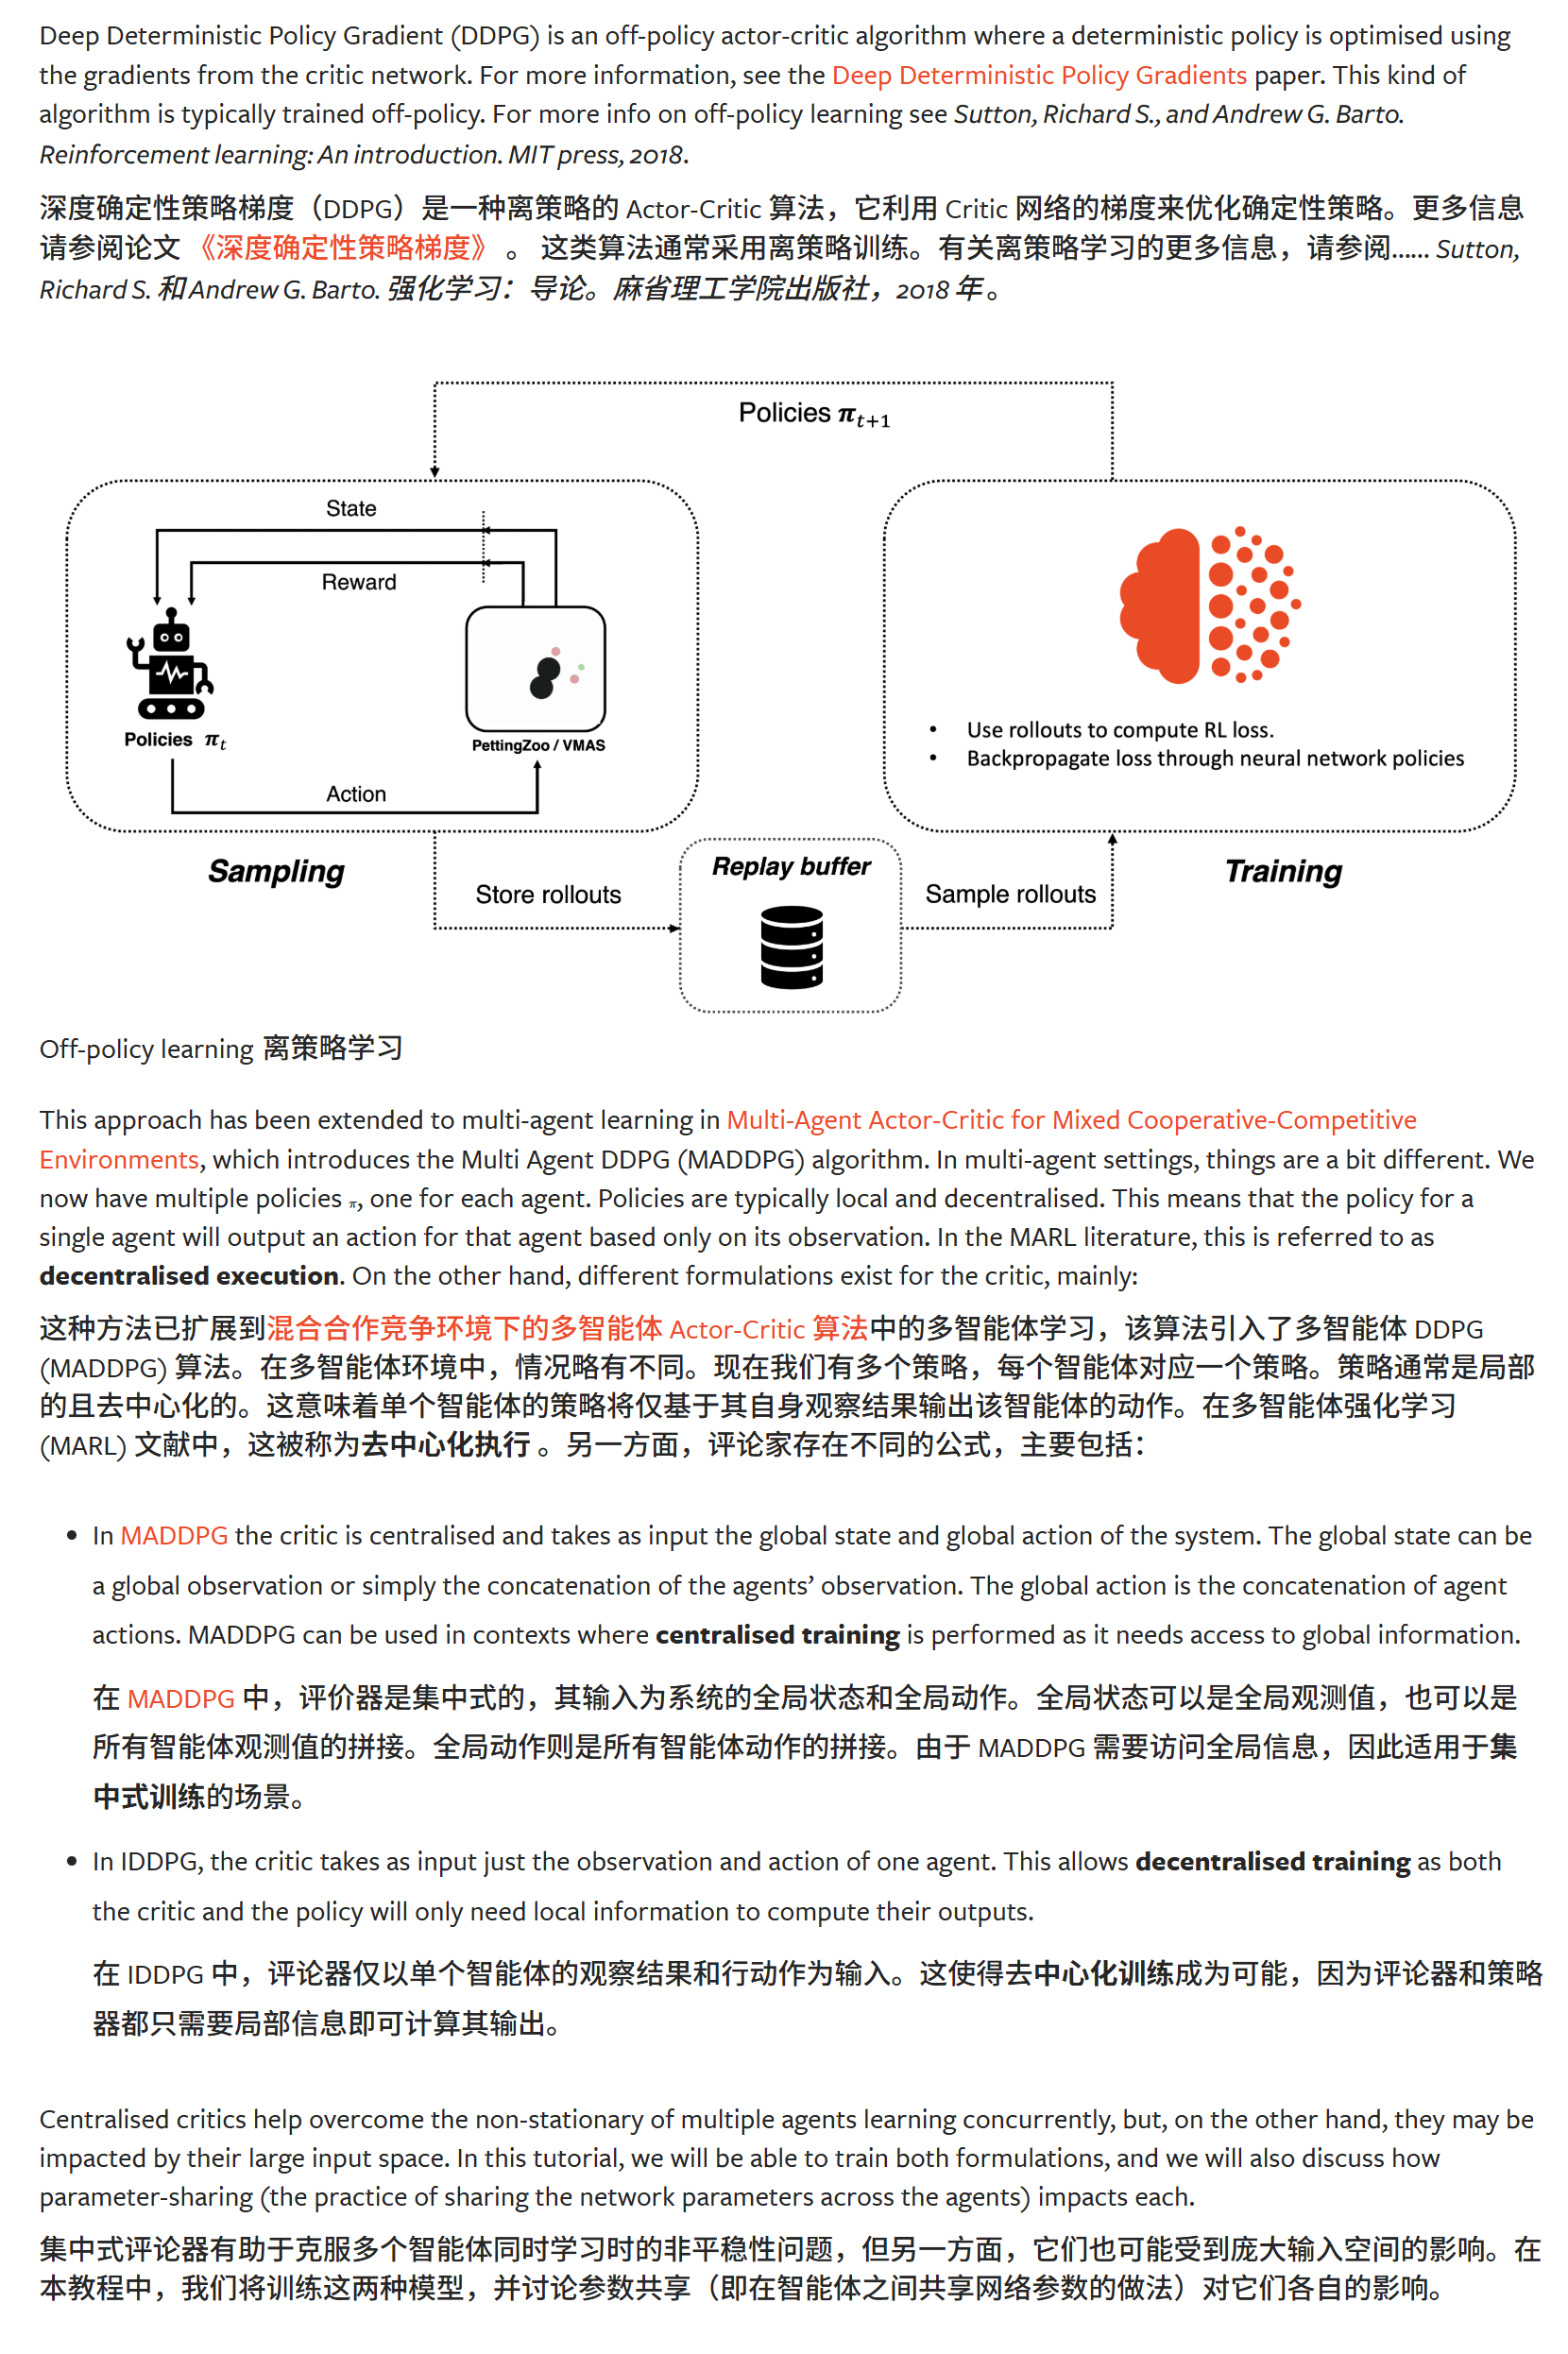
MADDPG
off-policy
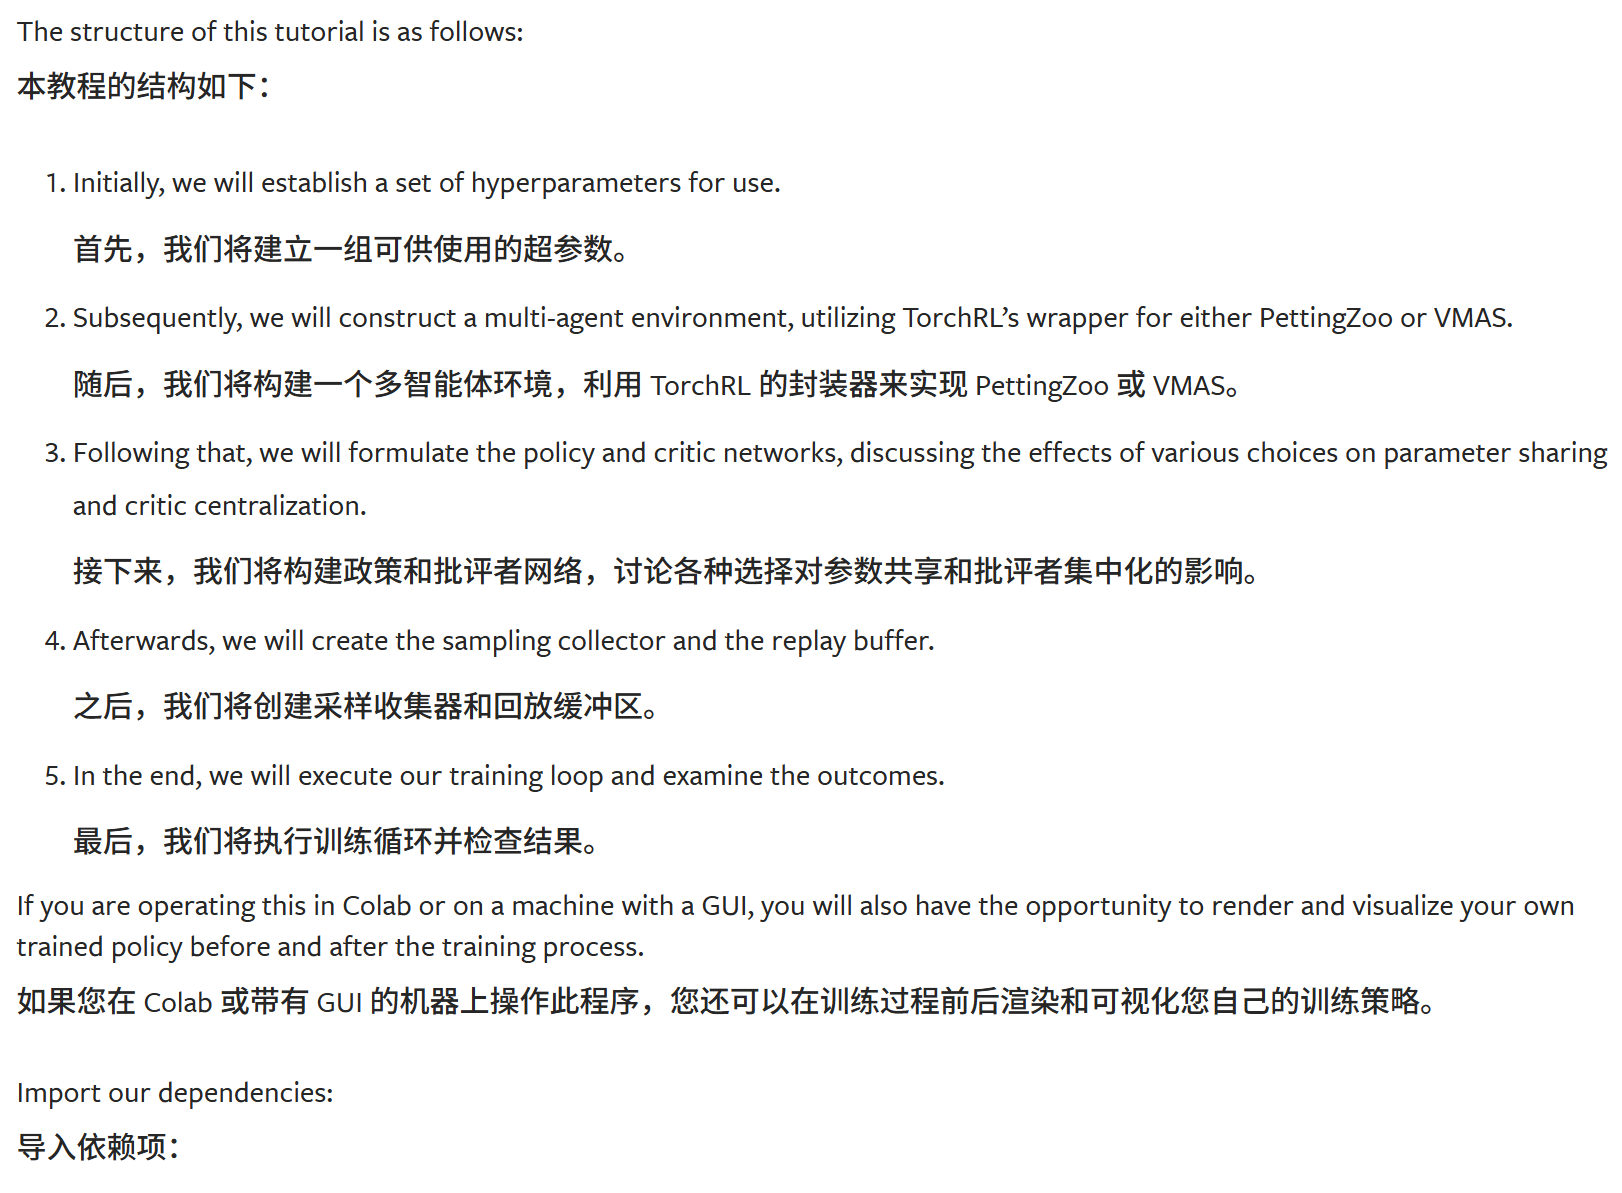
教程
流程还是一样;
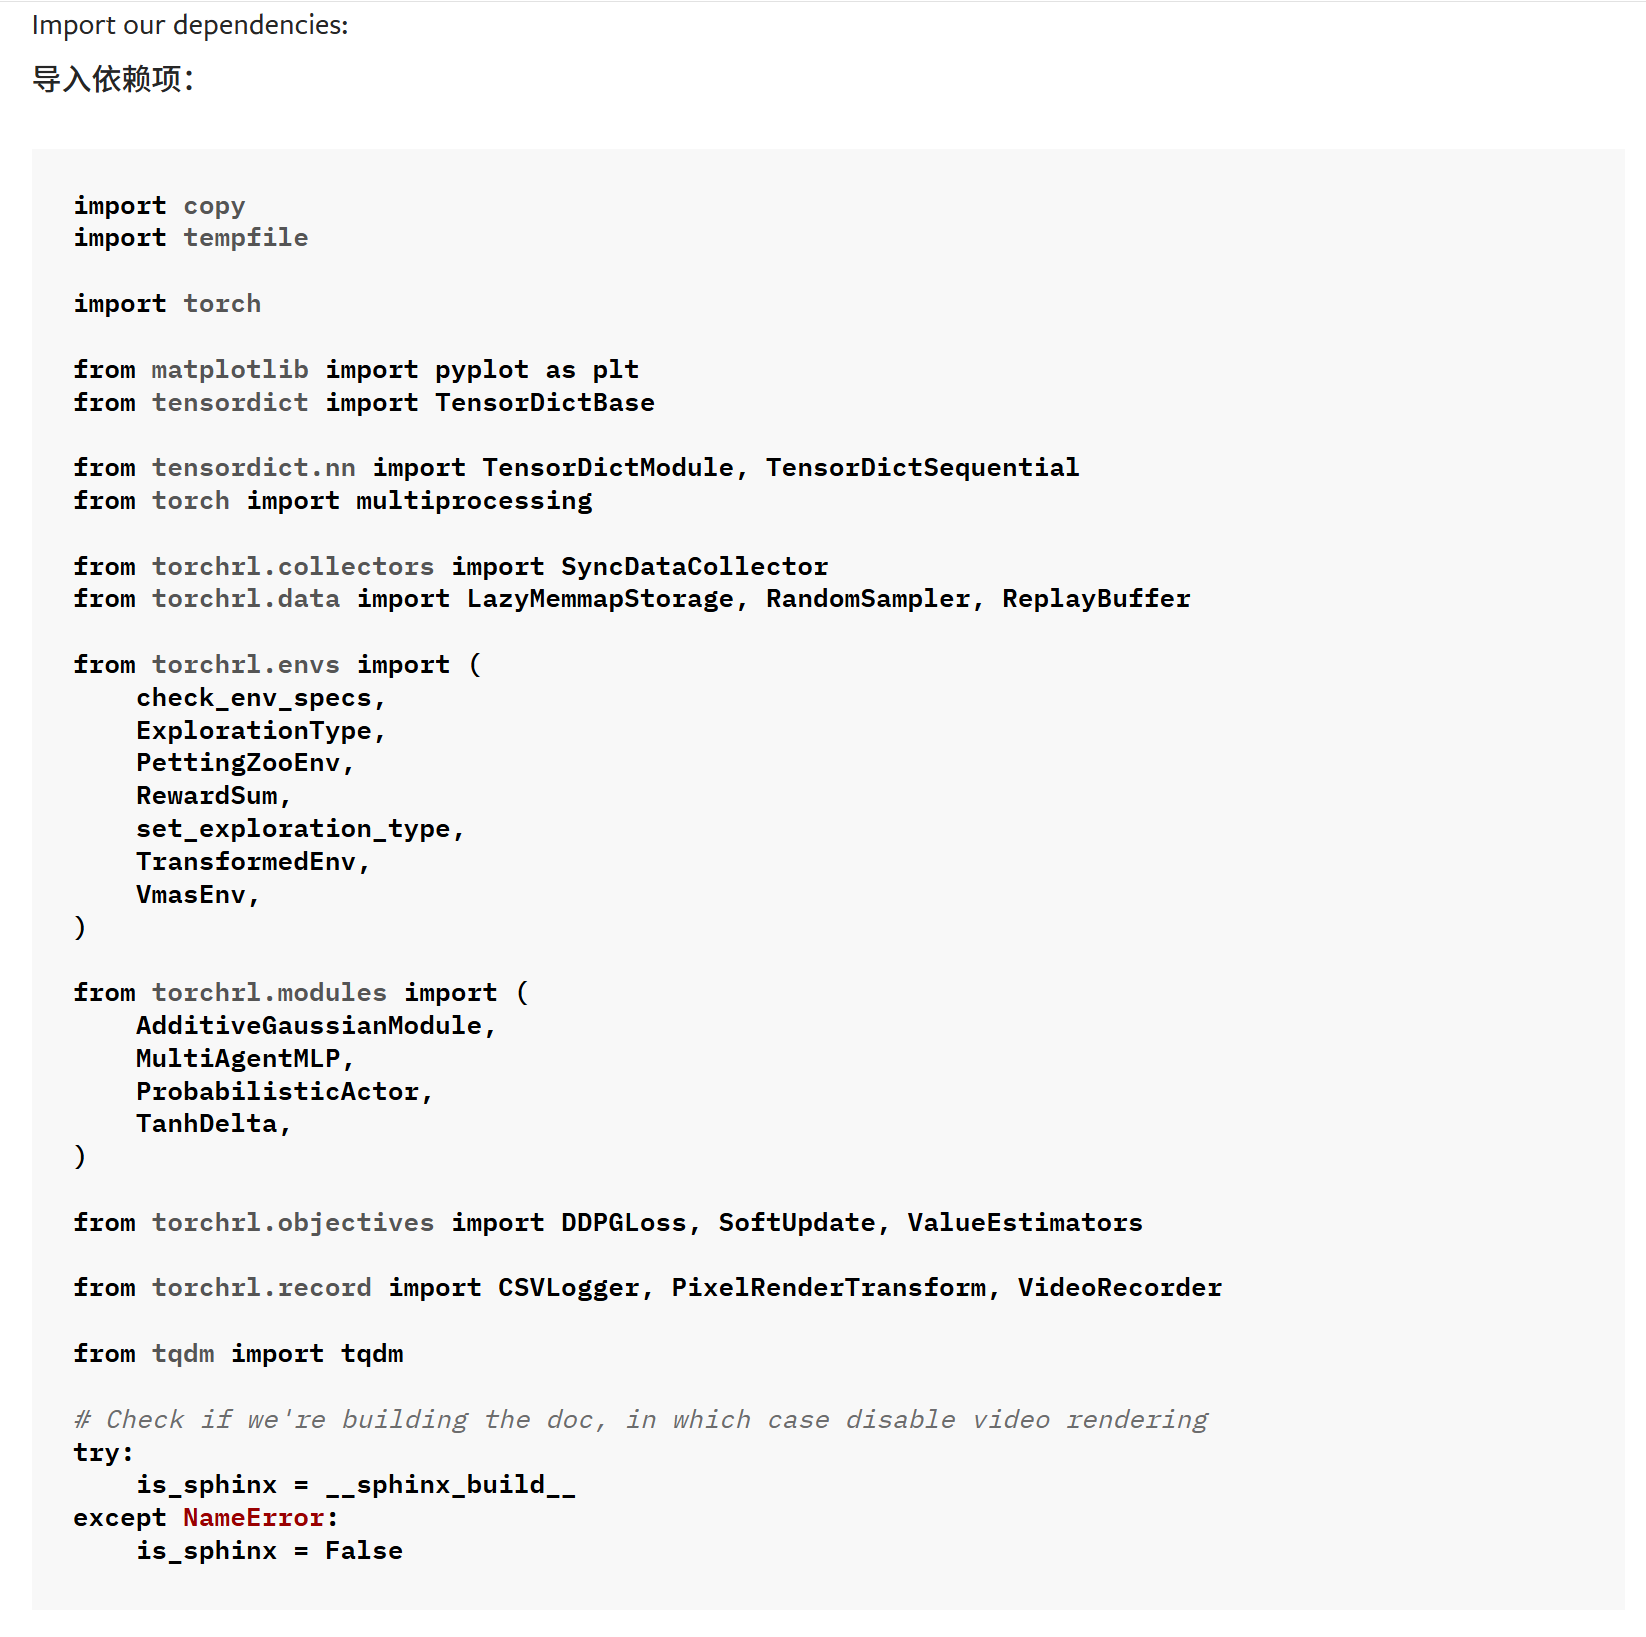
1.依赖项
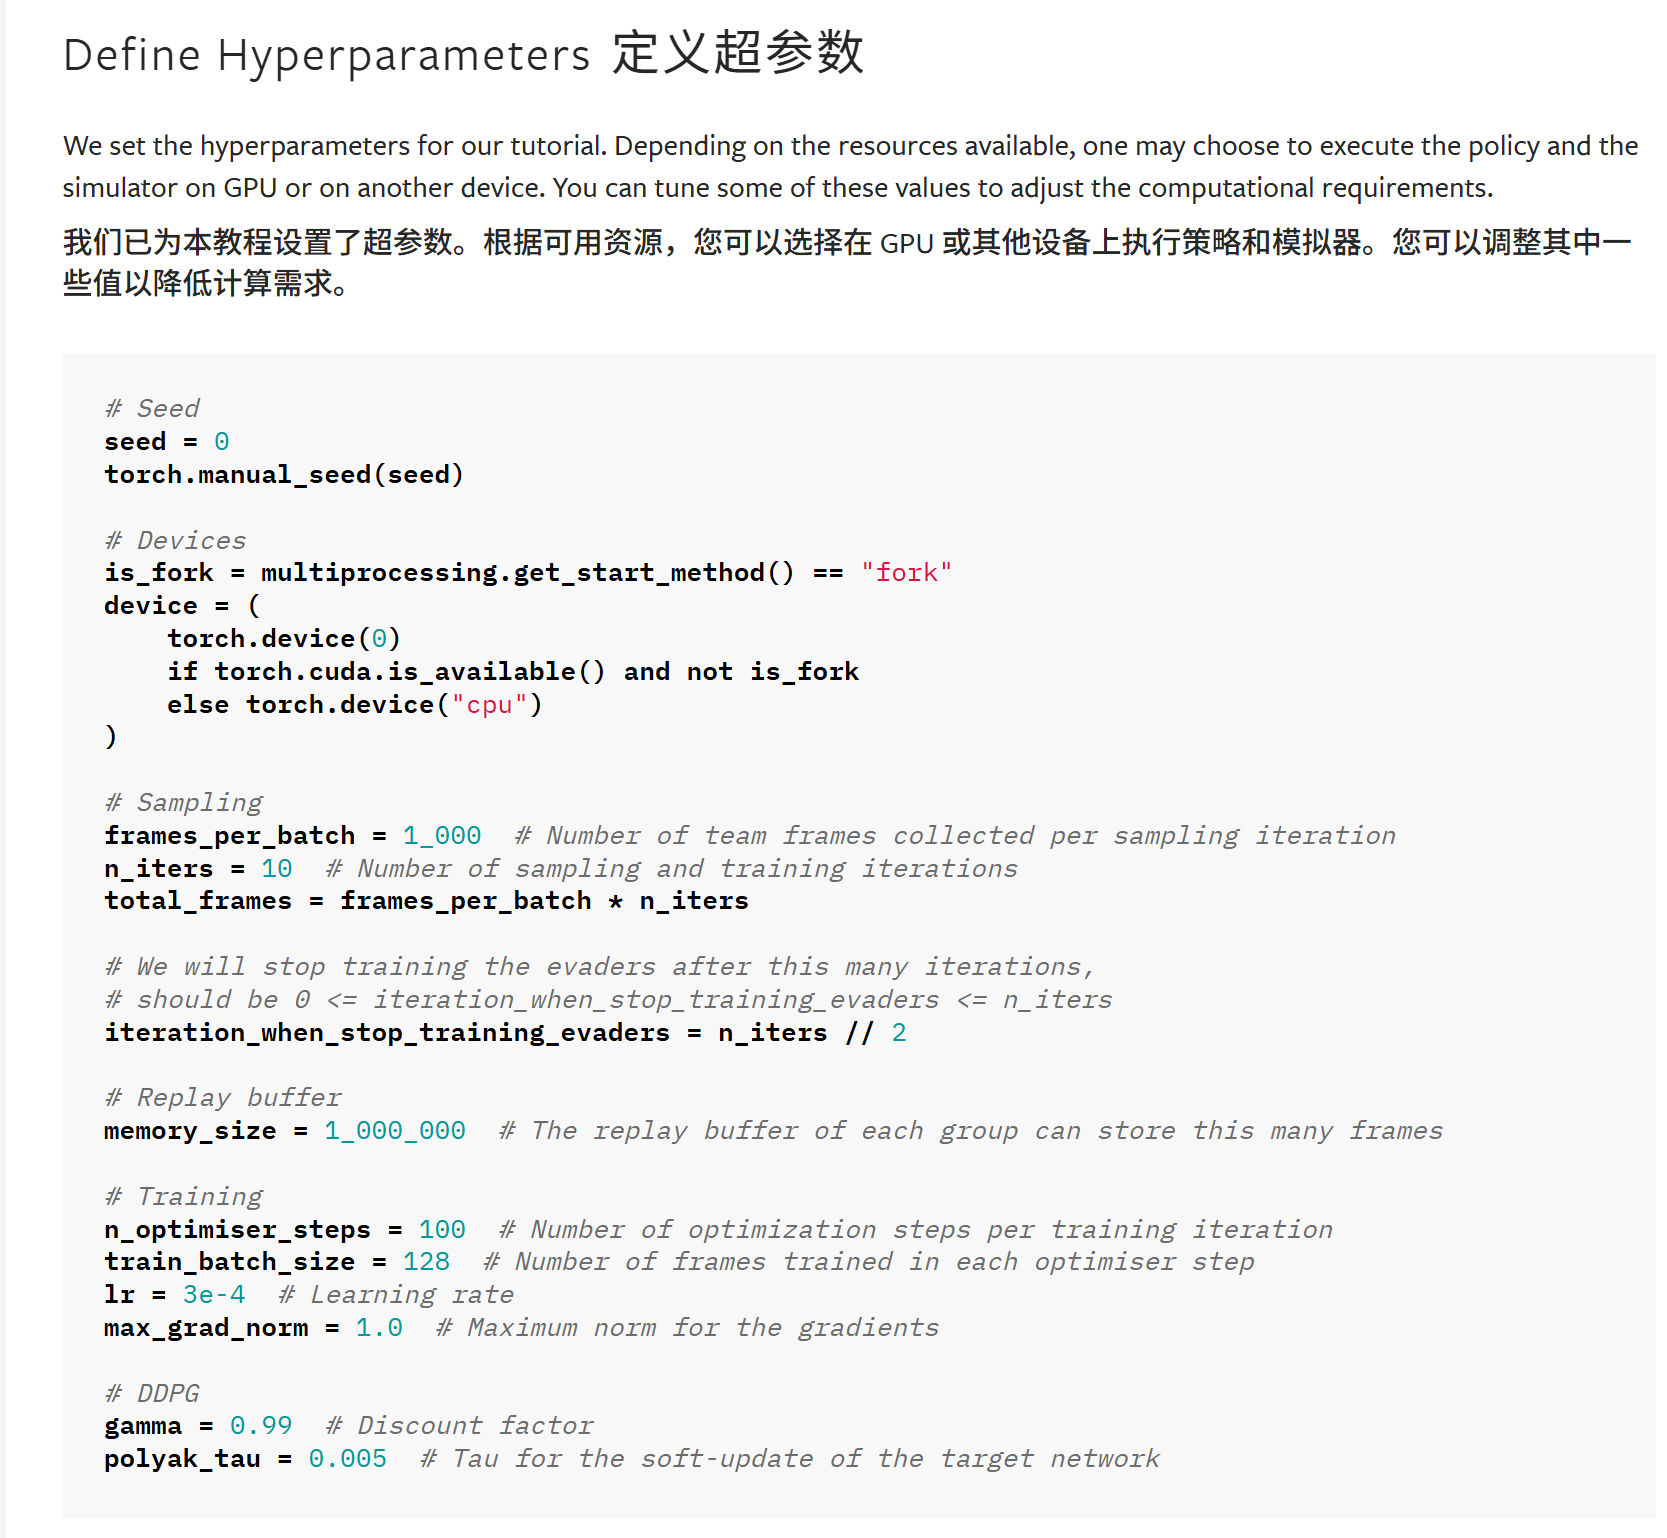
2.超参数
3.环境
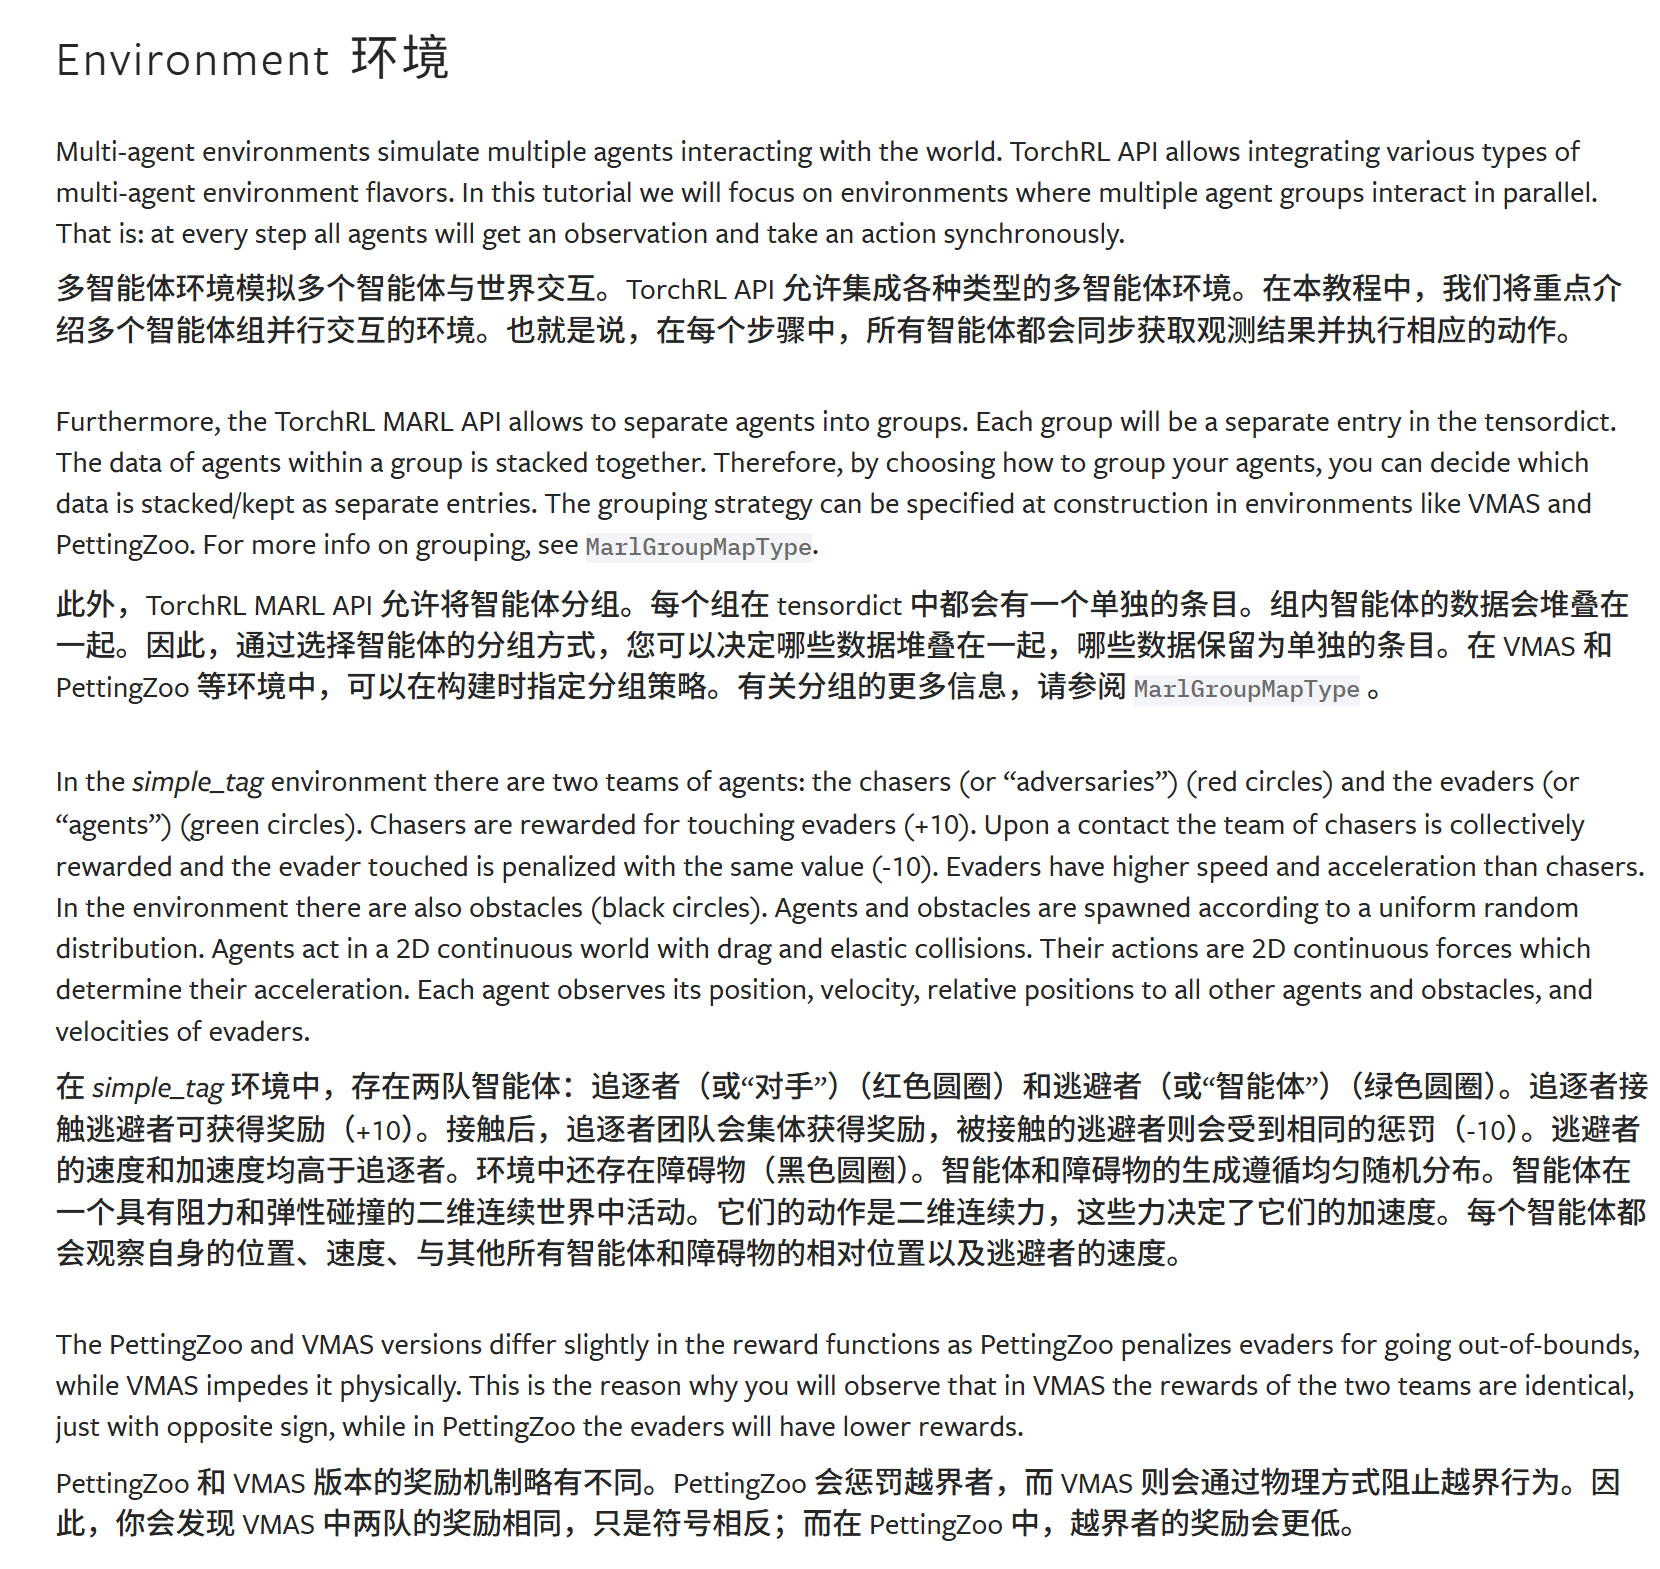
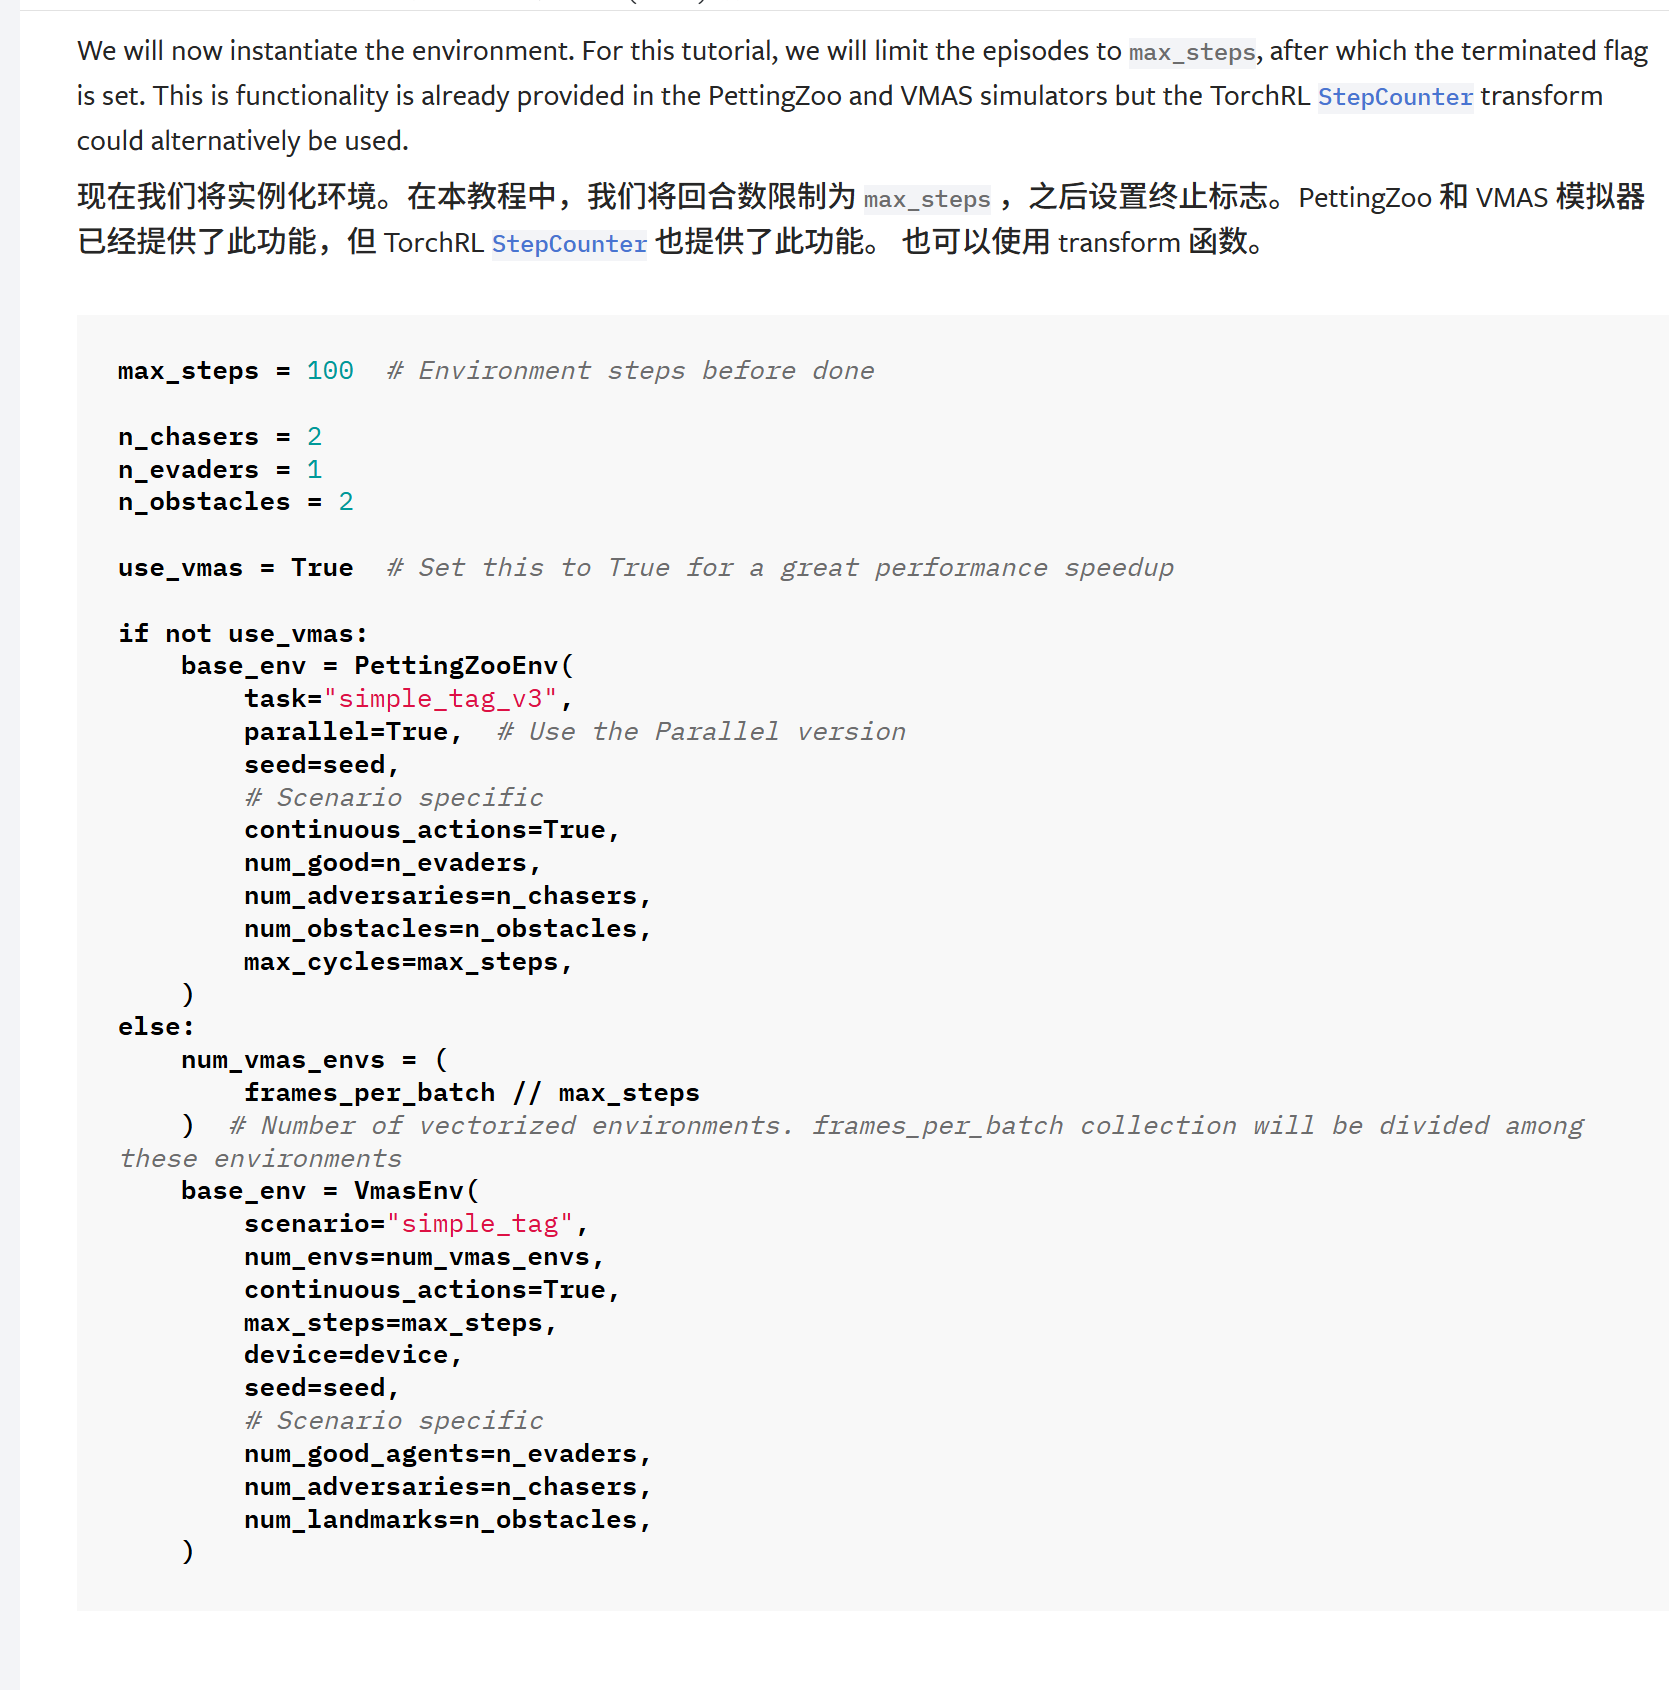
就是说智能体被分组了;
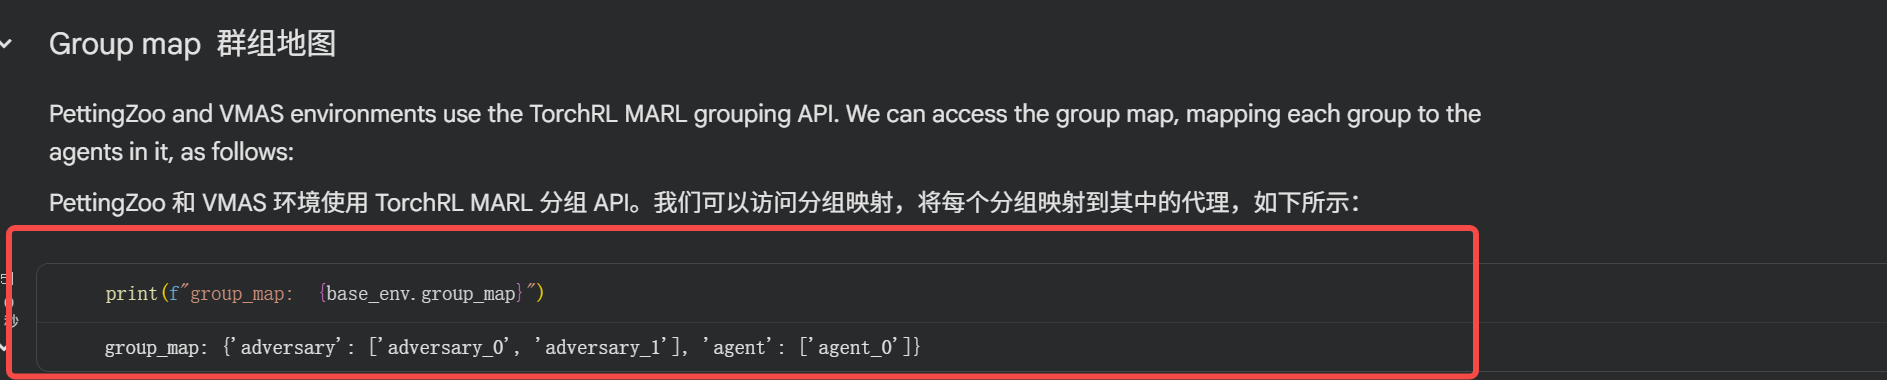
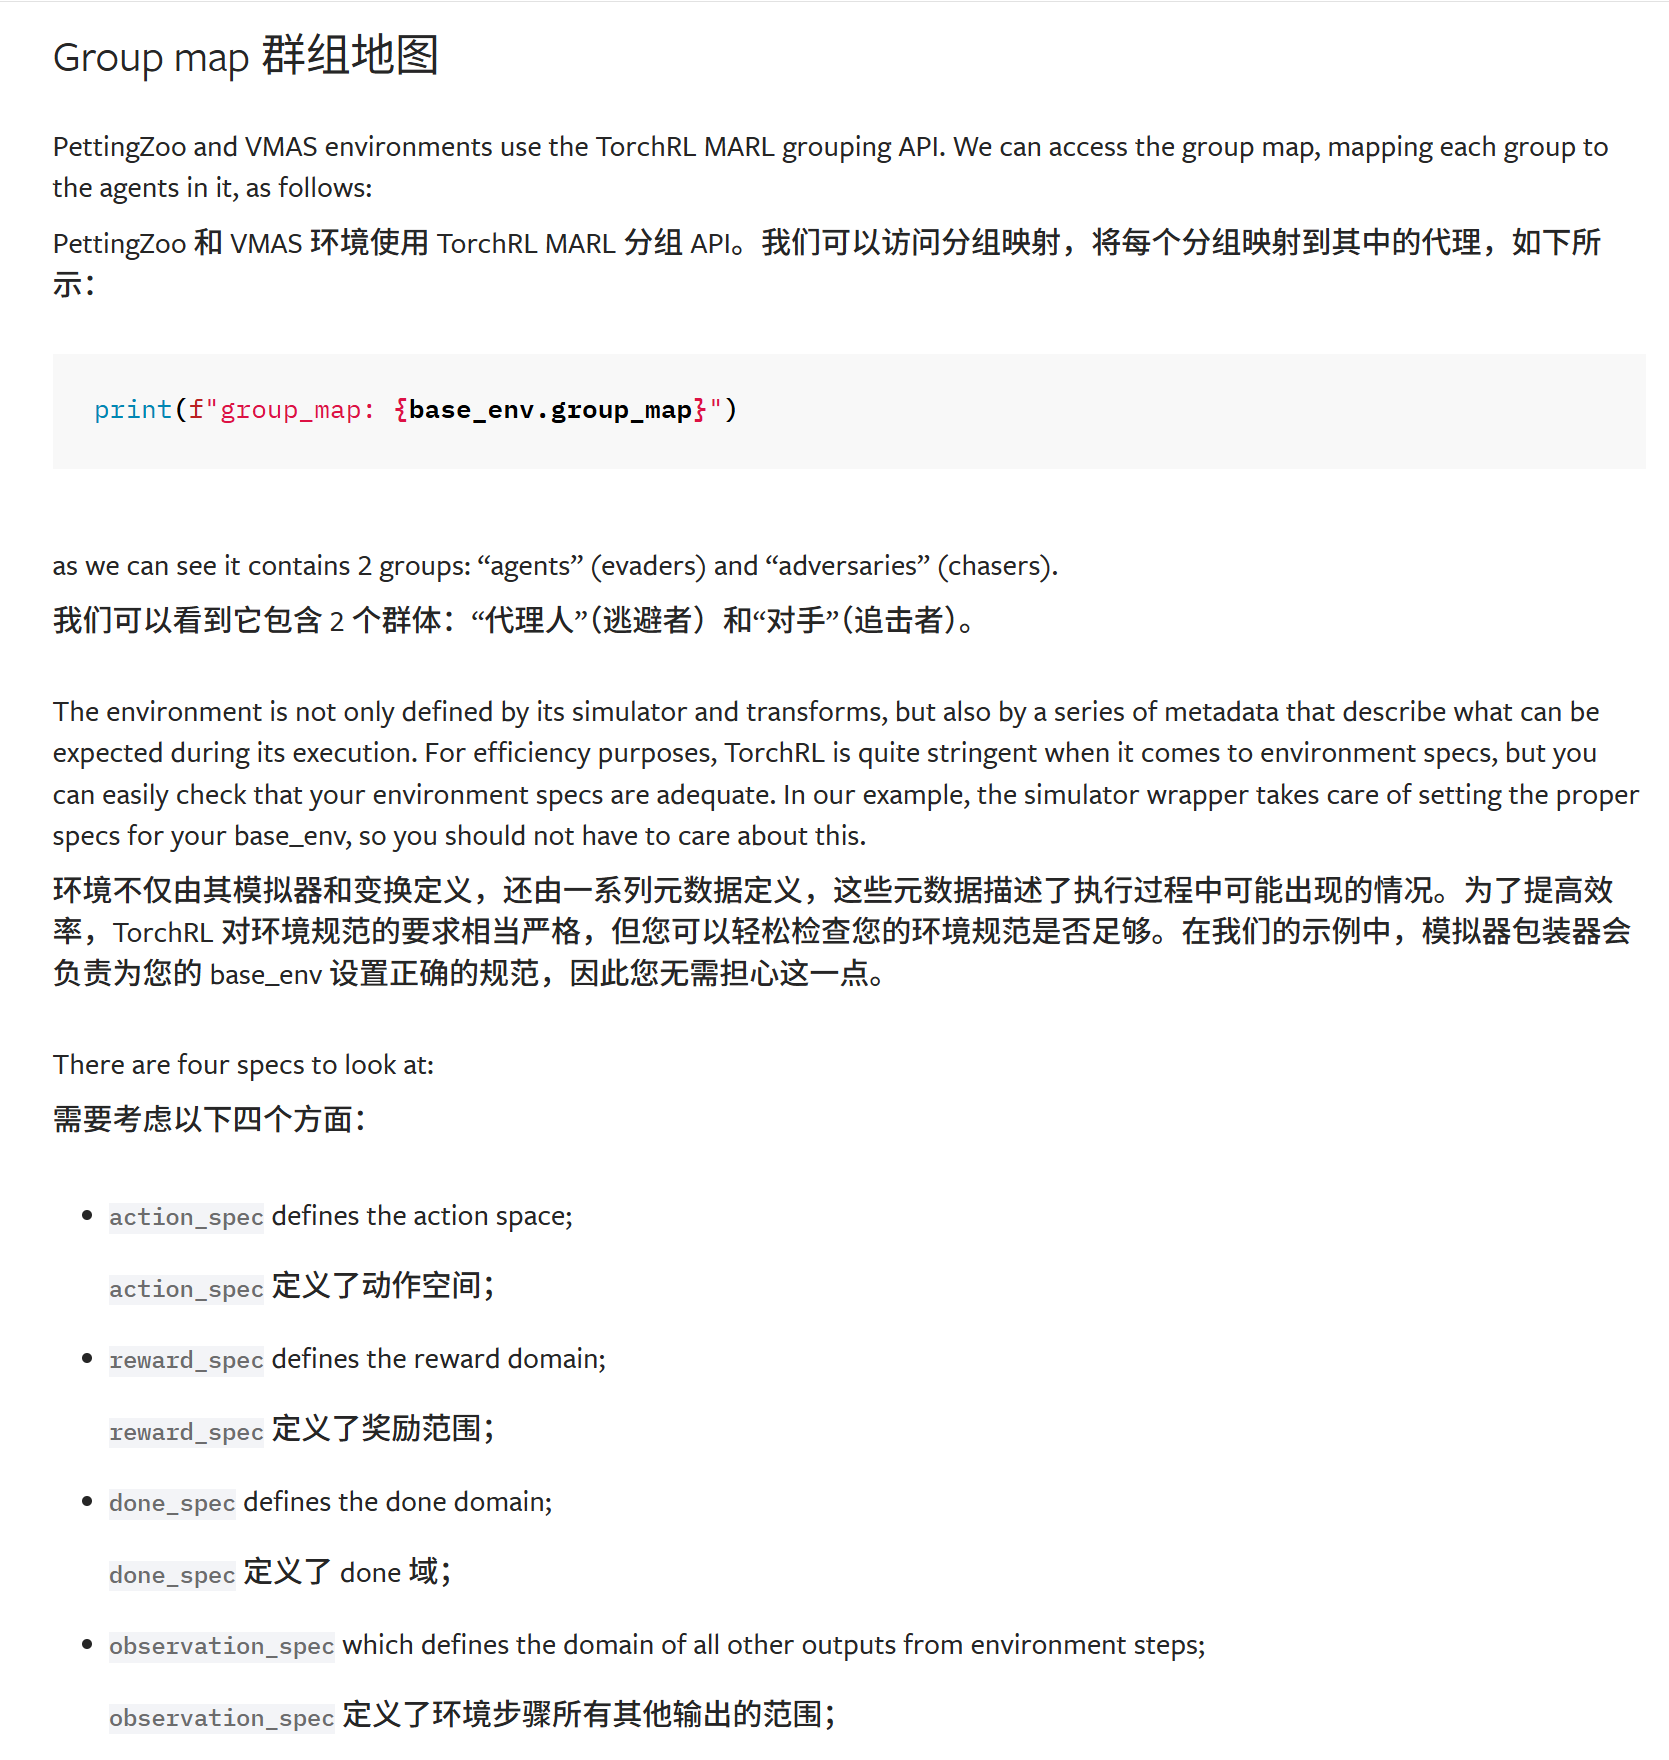
可以看到分组的map;
此外,还跟以前一样,说明ENV不仅包括了基本simulator和transforms,这些元数据描述了执行过程中可能出现的情况。为了提高效率,TorchRL 对环境规范的要求相当严格,但您可以轻松检查您的环境规范是否足够。
python
action_spec: Composite(
    adversary: Composite(
        action: BoundedContinuous(
            shape=torch.Size([10, 2, 2]),
            space=ContinuousBox(
                low=Tensor(shape=torch.Size([10, 2, 2]), device=cuda:0, dtype=torch.float32, contiguous=True),
                high=Tensor(shape=torch.Size([10, 2, 2]), device=cuda:0, dtype=torch.float32, contiguous=True)),
            device=cuda:0,
            dtype=torch.float32,
            domain=continuous),
        device=cuda:0,
        shape=torch.Size([10, 2]),
        data_cls=None),
    agent: Composite(
        action: BoundedContinuous(
            shape=torch.Size([10, 1, 2]),
            space=ContinuousBox(
                low=Tensor(shape=torch.Size([10, 1, 2]), device=cuda:0, dtype=torch.float32, contiguous=True),
                high=Tensor(shape=torch.Size([10, 1, 2]), device=cuda:0, dtype=torch.float32, contiguous=True)),
            device=cuda:0,
            dtype=torch.float32,
            domain=continuous),
        device=cuda:0,
        shape=torch.Size([10, 1]),
        data_cls=None),
    device=cuda:0,
    shape=torch.Size([10]),
    data_cls=None)
reward_spec: Composite(
    adversary: Composite(
        reward: UnboundedContinuous(
            shape=torch.Size([10, 2, 1]),
            space=ContinuousBox(
                low=Tensor(shape=torch.Size([10, 2, 1]), device=cuda:0, dtype=torch.float32, contiguous=True),
                high=Tensor(shape=torch.Size([10, 2, 1]), device=cuda:0, dtype=torch.float32, contiguous=True)),
            device=cuda:0,
            dtype=torch.float32,
            domain=continuous),
        device=cuda:0,
        shape=torch.Size([10, 2]),
        data_cls=None),
    agent: Composite(
        reward: UnboundedContinuous(
            shape=torch.Size([10, 1, 1]),
            space=ContinuousBox(
                low=Tensor(shape=torch.Size([10, 1, 1]), device=cuda:0, dtype=torch.float32, contiguous=True),
                high=Tensor(shape=torch.Size([10, 1, 1]), device=cuda:0, dtype=torch.float32, contiguous=True)),
            device=cuda:0,
            dtype=torch.float32,
            domain=continuous),
        device=cuda:0,
        shape=torch.Size([10, 1]),
        data_cls=None),
    device=cuda:0,
    shape=torch.Size([10]),
    data_cls=None)
done_spec: Composite(
    done: Categorical(
        shape=torch.Size([10, 1]),
        space=CategoricalBox(n=2),
        device=cuda:0,
        dtype=torch.bool,
        domain=discrete),
    terminated: Categorical(
        shape=torch.Size([10, 1]),
        space=CategoricalBox(n=2),
        device=cuda:0,
        dtype=torch.bool,
        domain=discrete),
    device=cuda:0,
    shape=torch.Size([10]),
    data_cls=None)
observation_spec: Composite(
    adversary: Composite(
        observation: UnboundedContinuous(
            shape=torch.Size([10, 2, 14]),
            space=ContinuousBox(
                low=Tensor(shape=torch.Size([10, 2, 14]), device=cuda:0, dtype=torch.float32, contiguous=True),
                high=Tensor(shape=torch.Size([10, 2, 14]), device=cuda:0, dtype=torch.float32, contiguous=True)),
            device=cuda:0,
            dtype=torch.float32,
            domain=continuous),
        device=cuda:0,
        shape=torch.Size([10, 2]),
        data_cls=None),
    agent: Composite(
        observation: UnboundedContinuous(
            shape=torch.Size([10, 1, 12]),
            space=ContinuousBox(
                low=Tensor(shape=torch.Size([10, 1, 12]), device=cuda:0, dtype=torch.float32, contiguous=True),
                high=Tensor(shape=torch.Size([10, 1, 12]), device=cuda:0, dtype=torch.float32, contiguous=True)),
            device=cuda:0,
            dtype=torch.float32,
            domain=continuous),
        device=cuda:0,
        shape=torch.Size([10, 1]),
        data_cls=None),
    device=cuda:0,
    shape=torch.Size([10]),
    data_cls=None)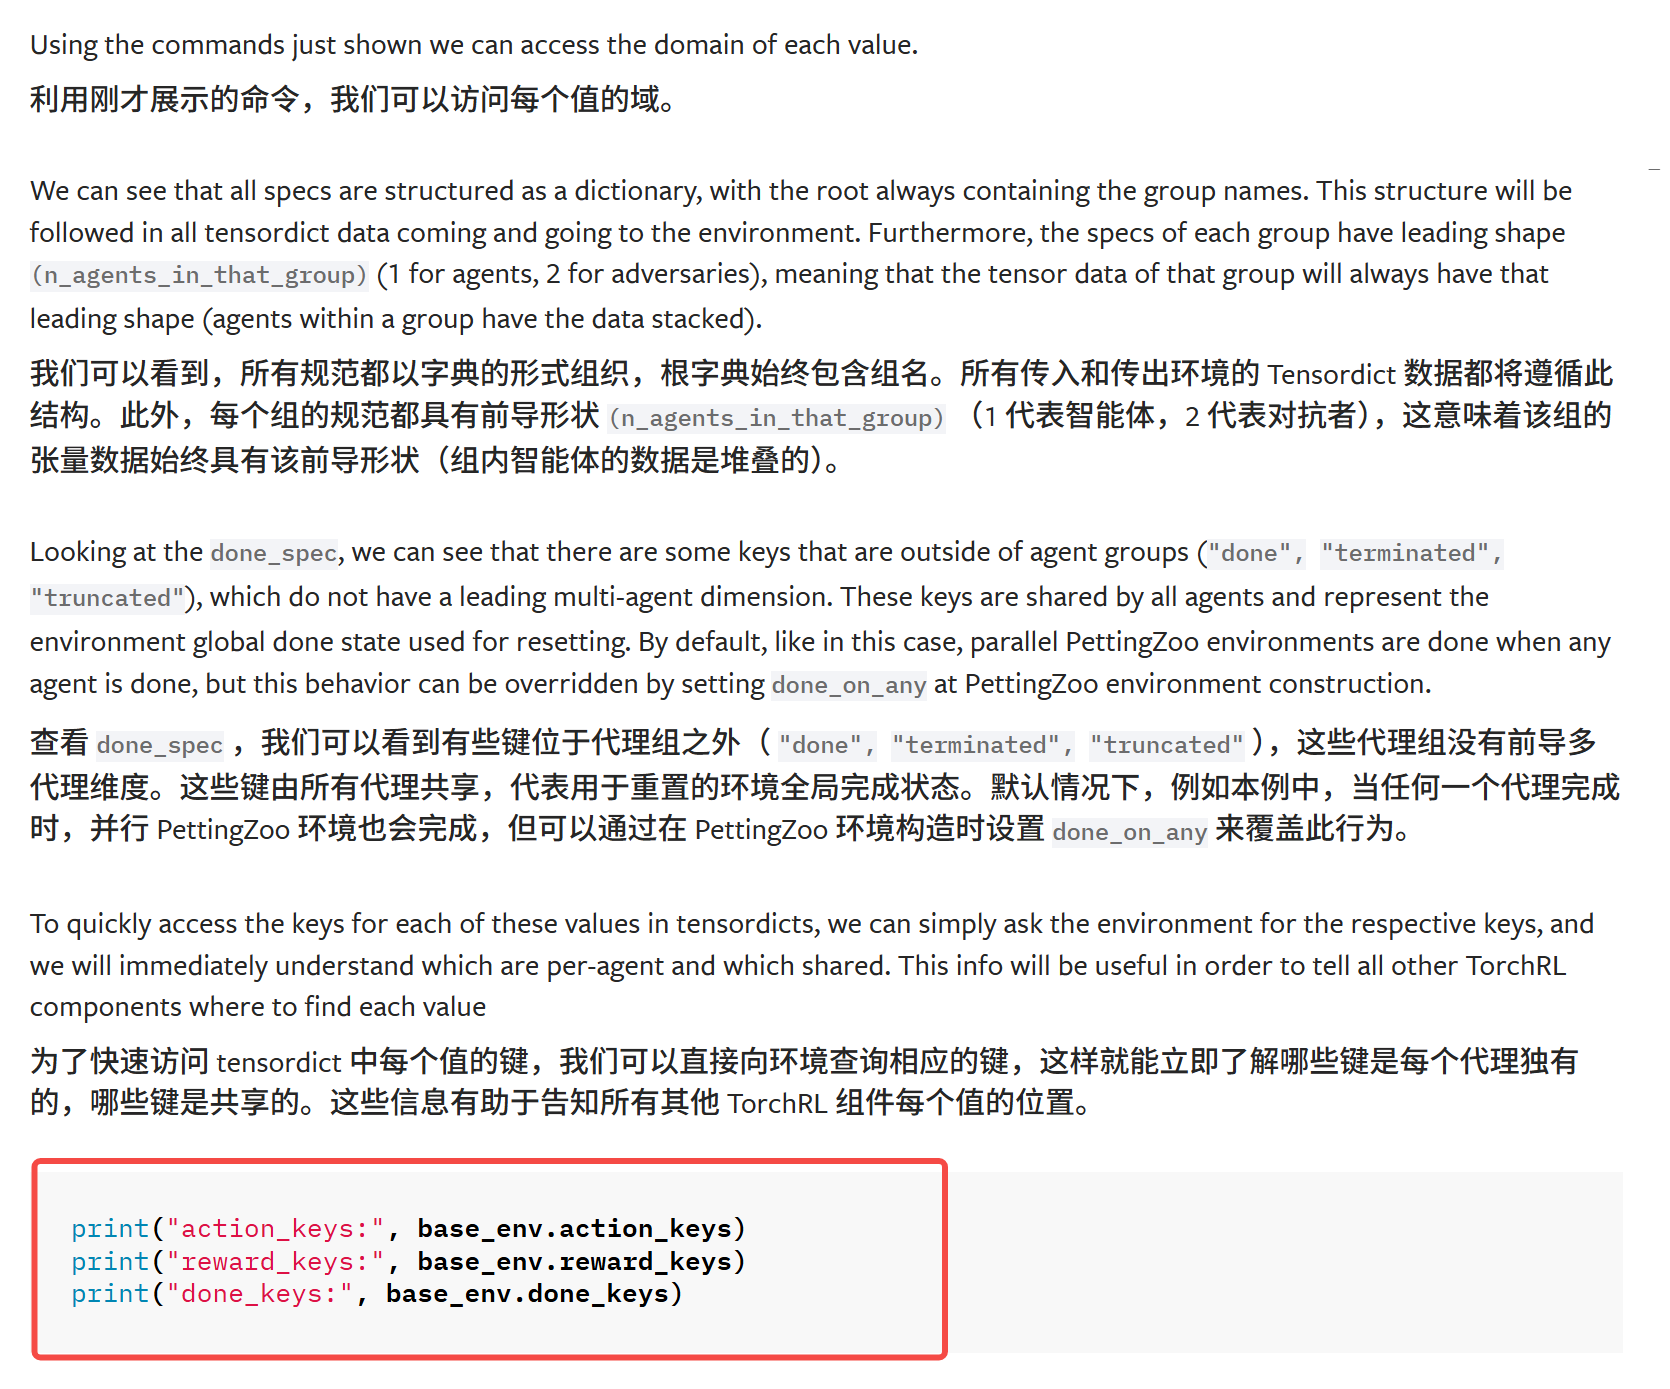
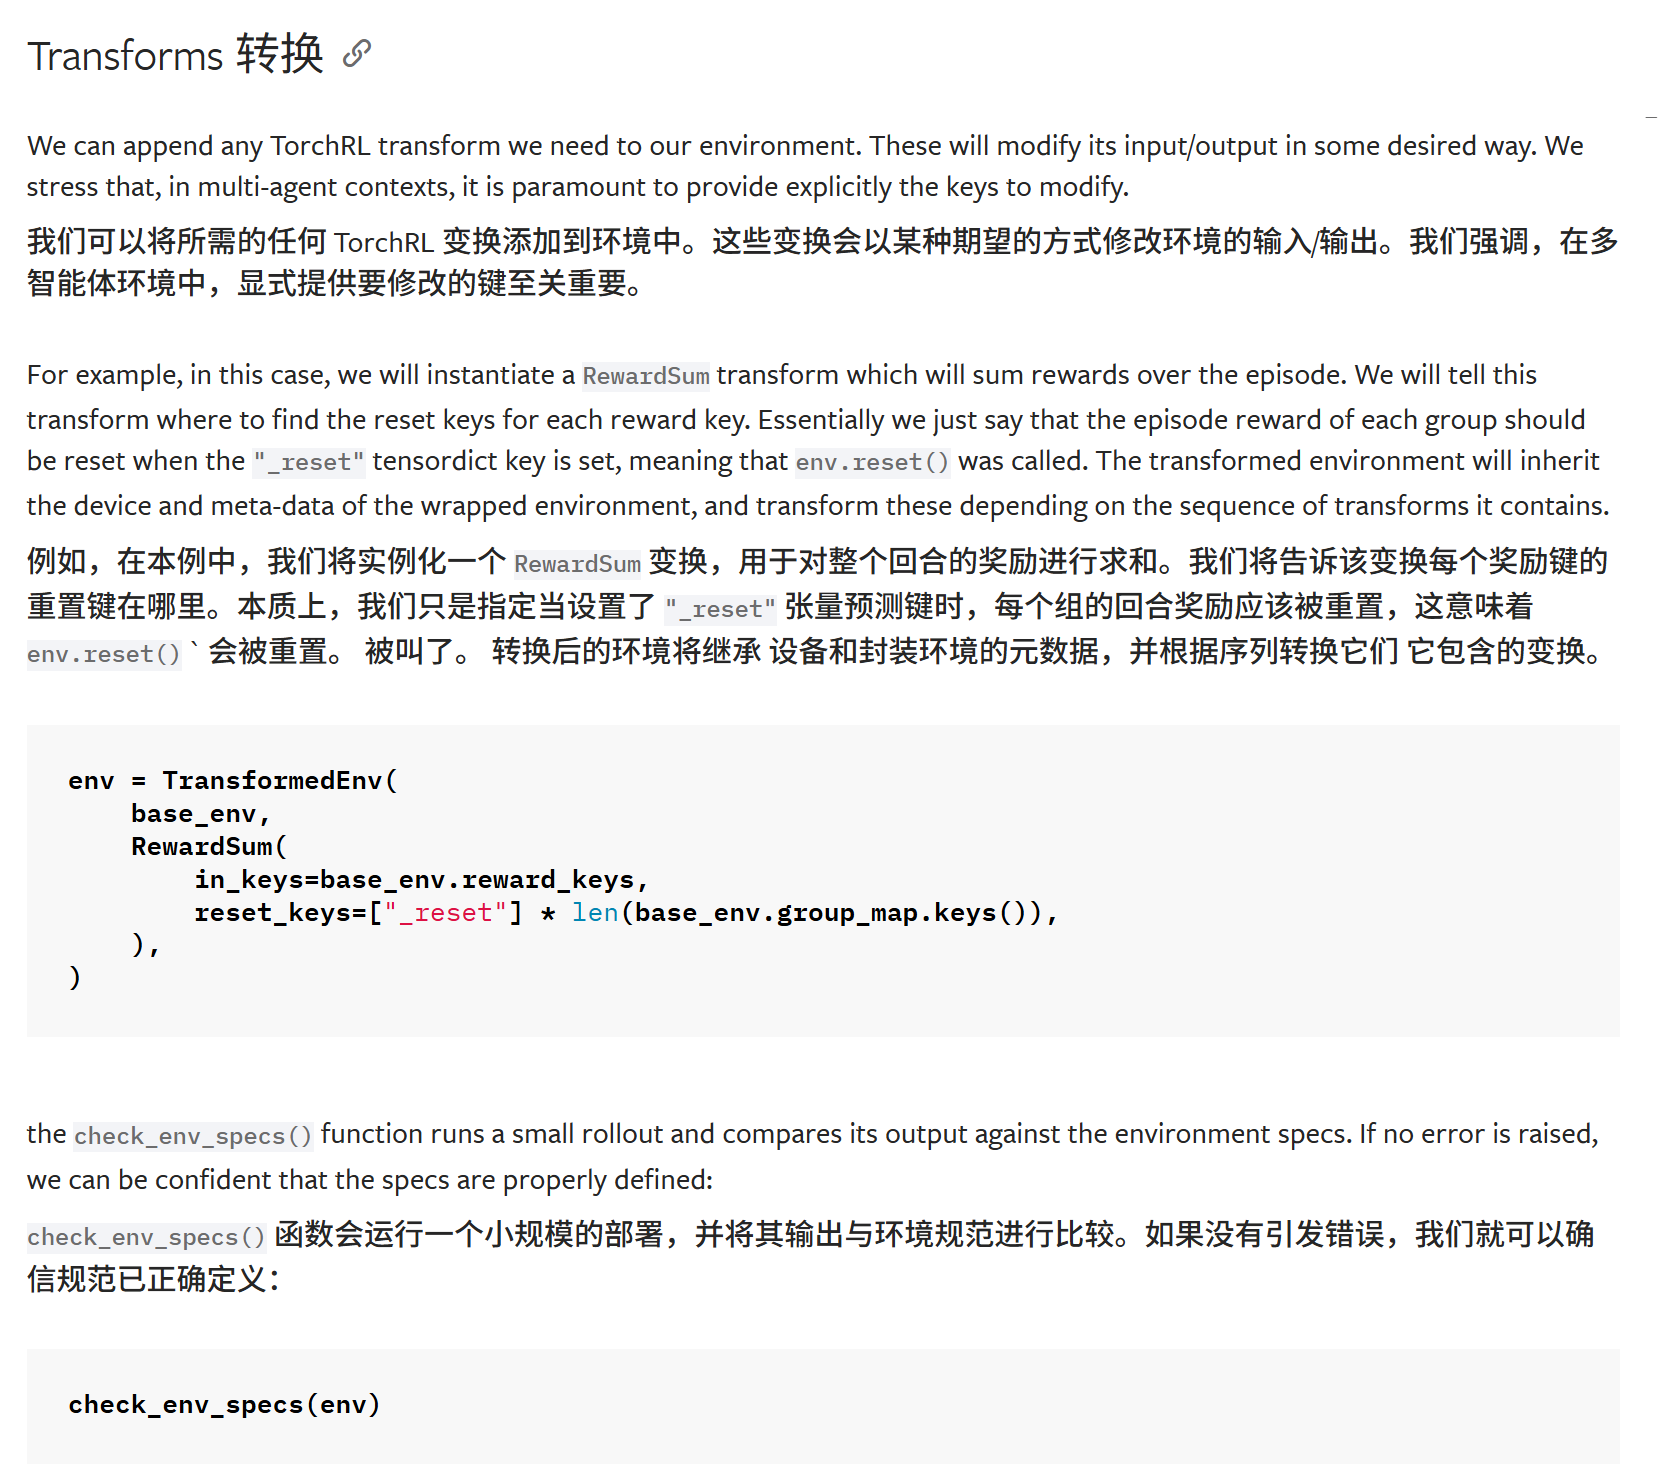
其实就是对环境做上层的包装
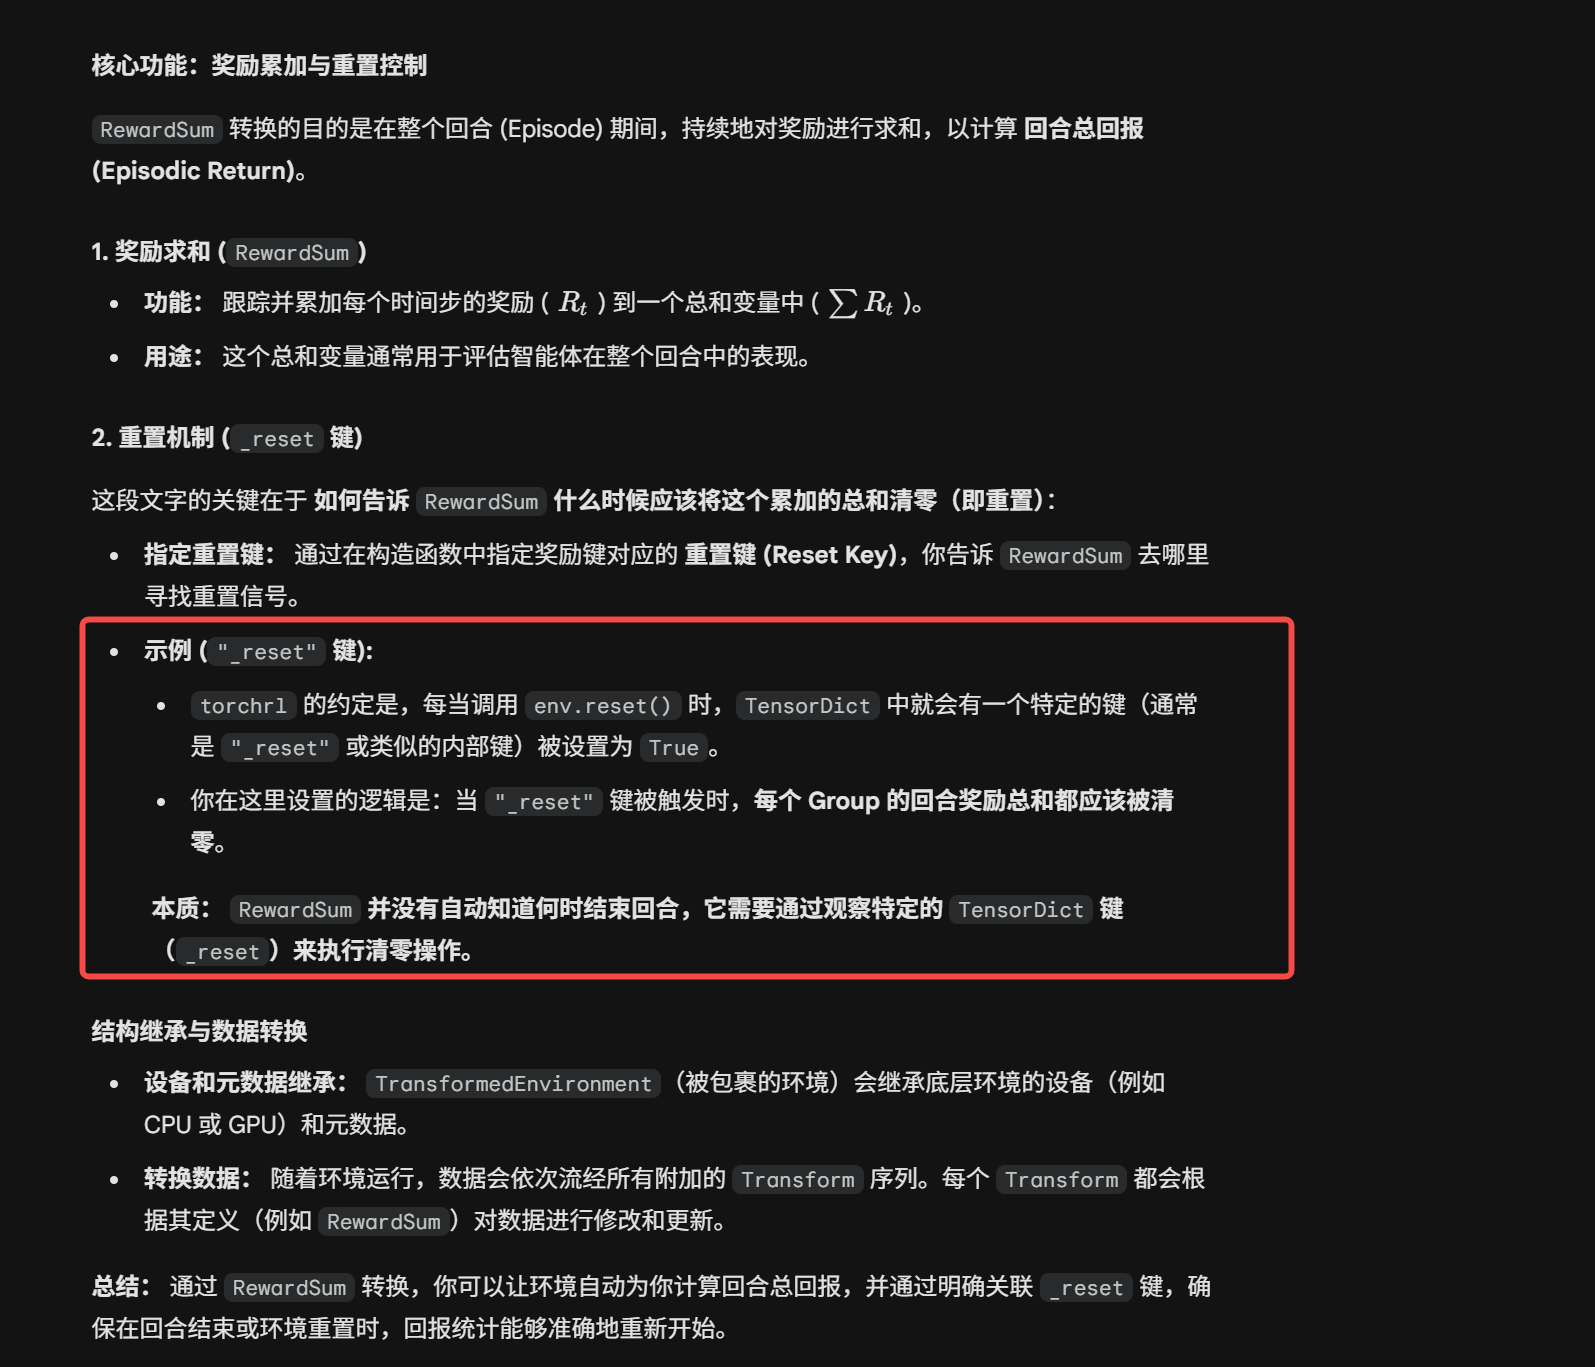
这段和之前的描述无区别
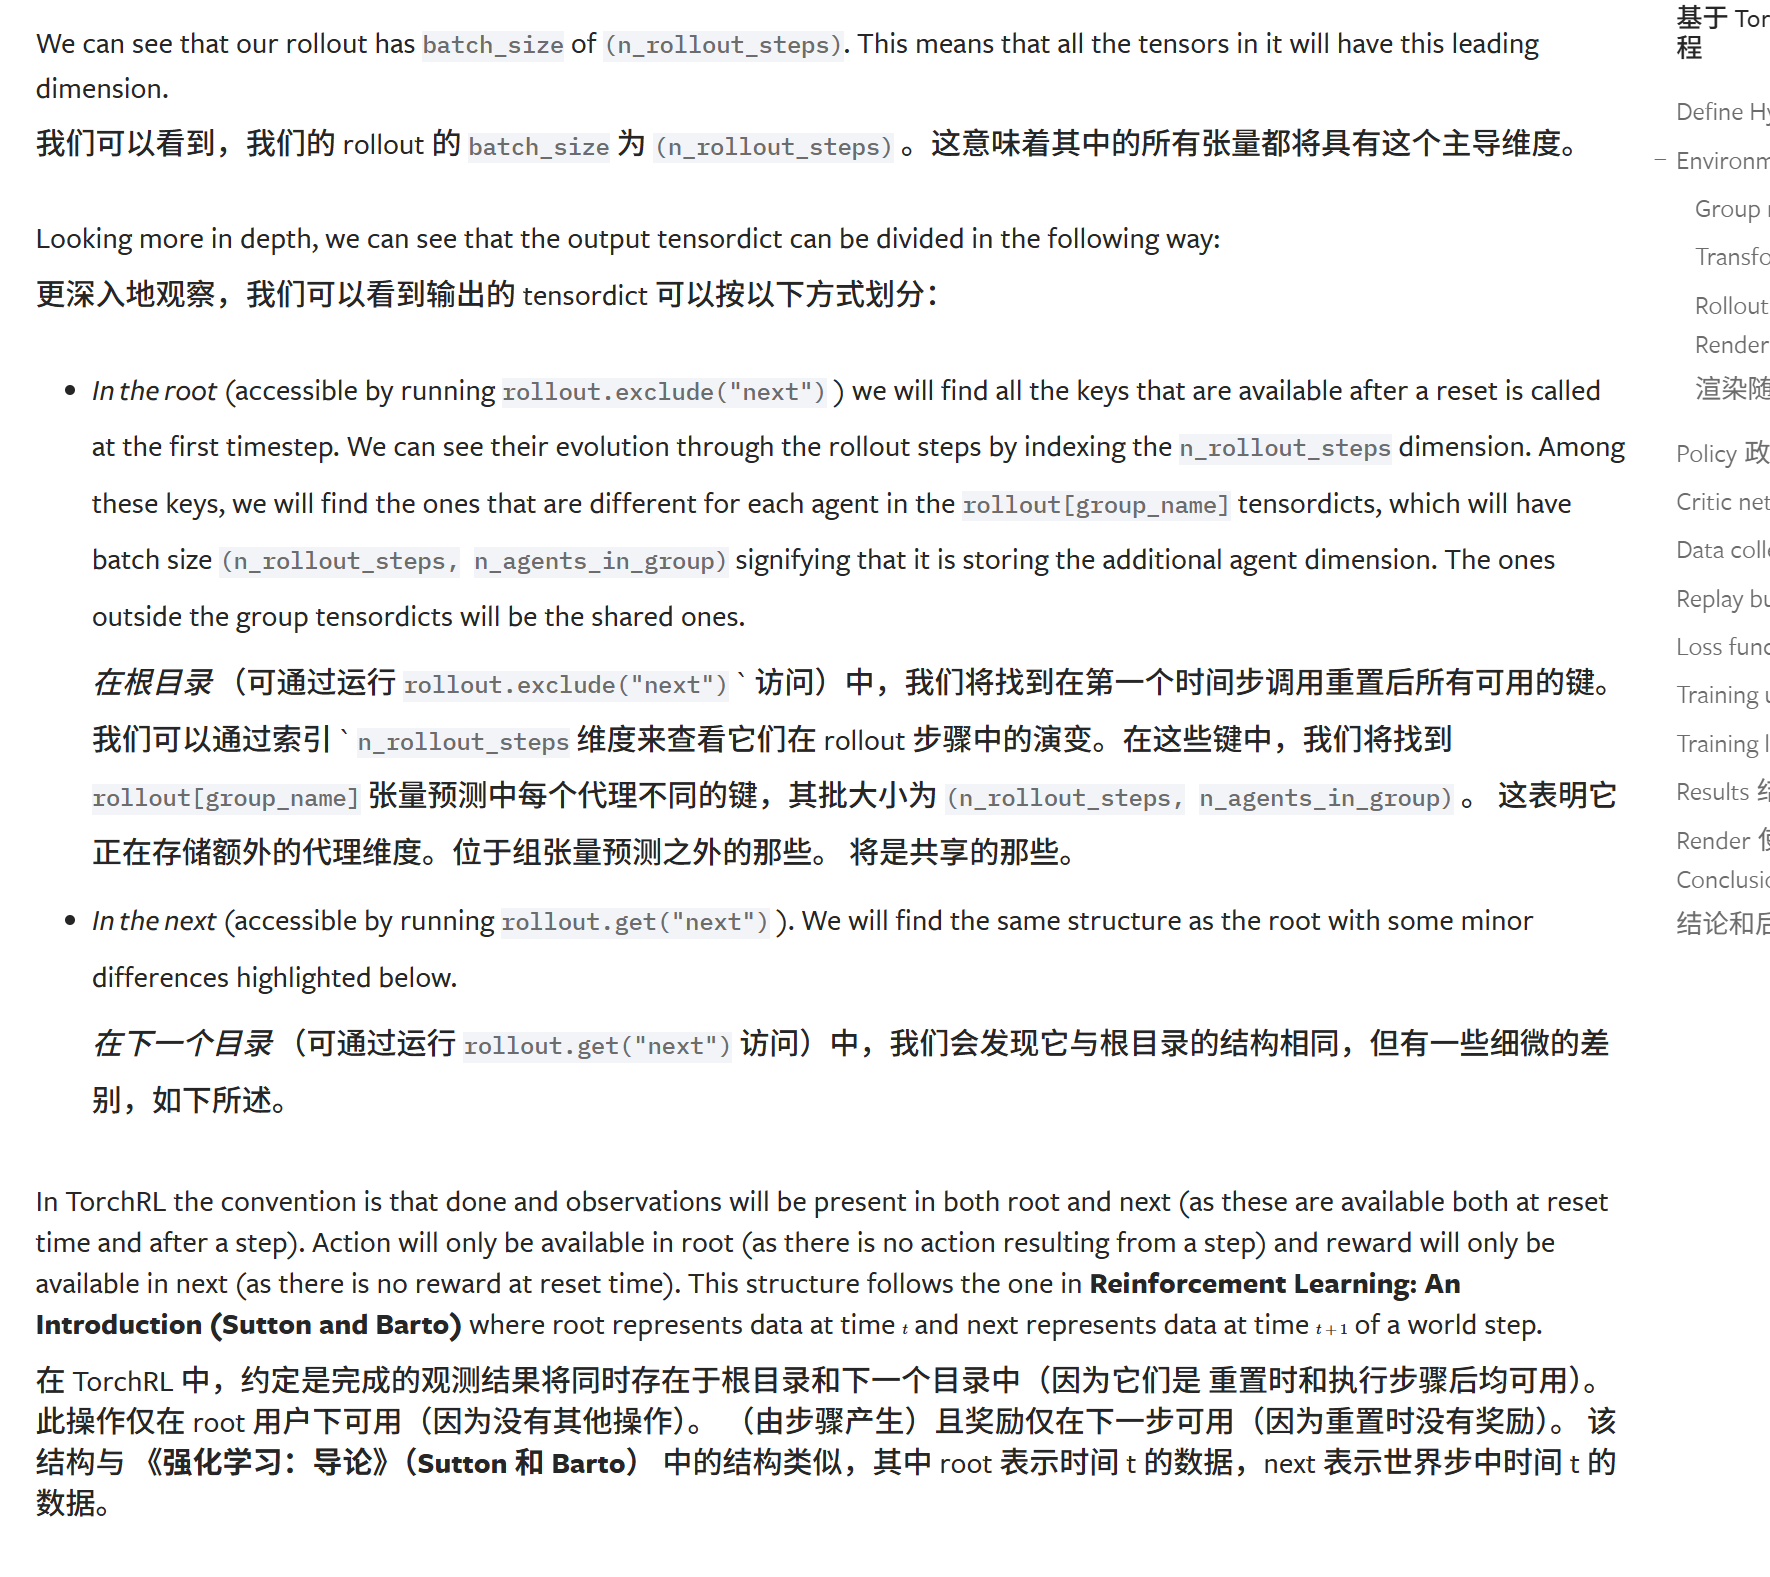
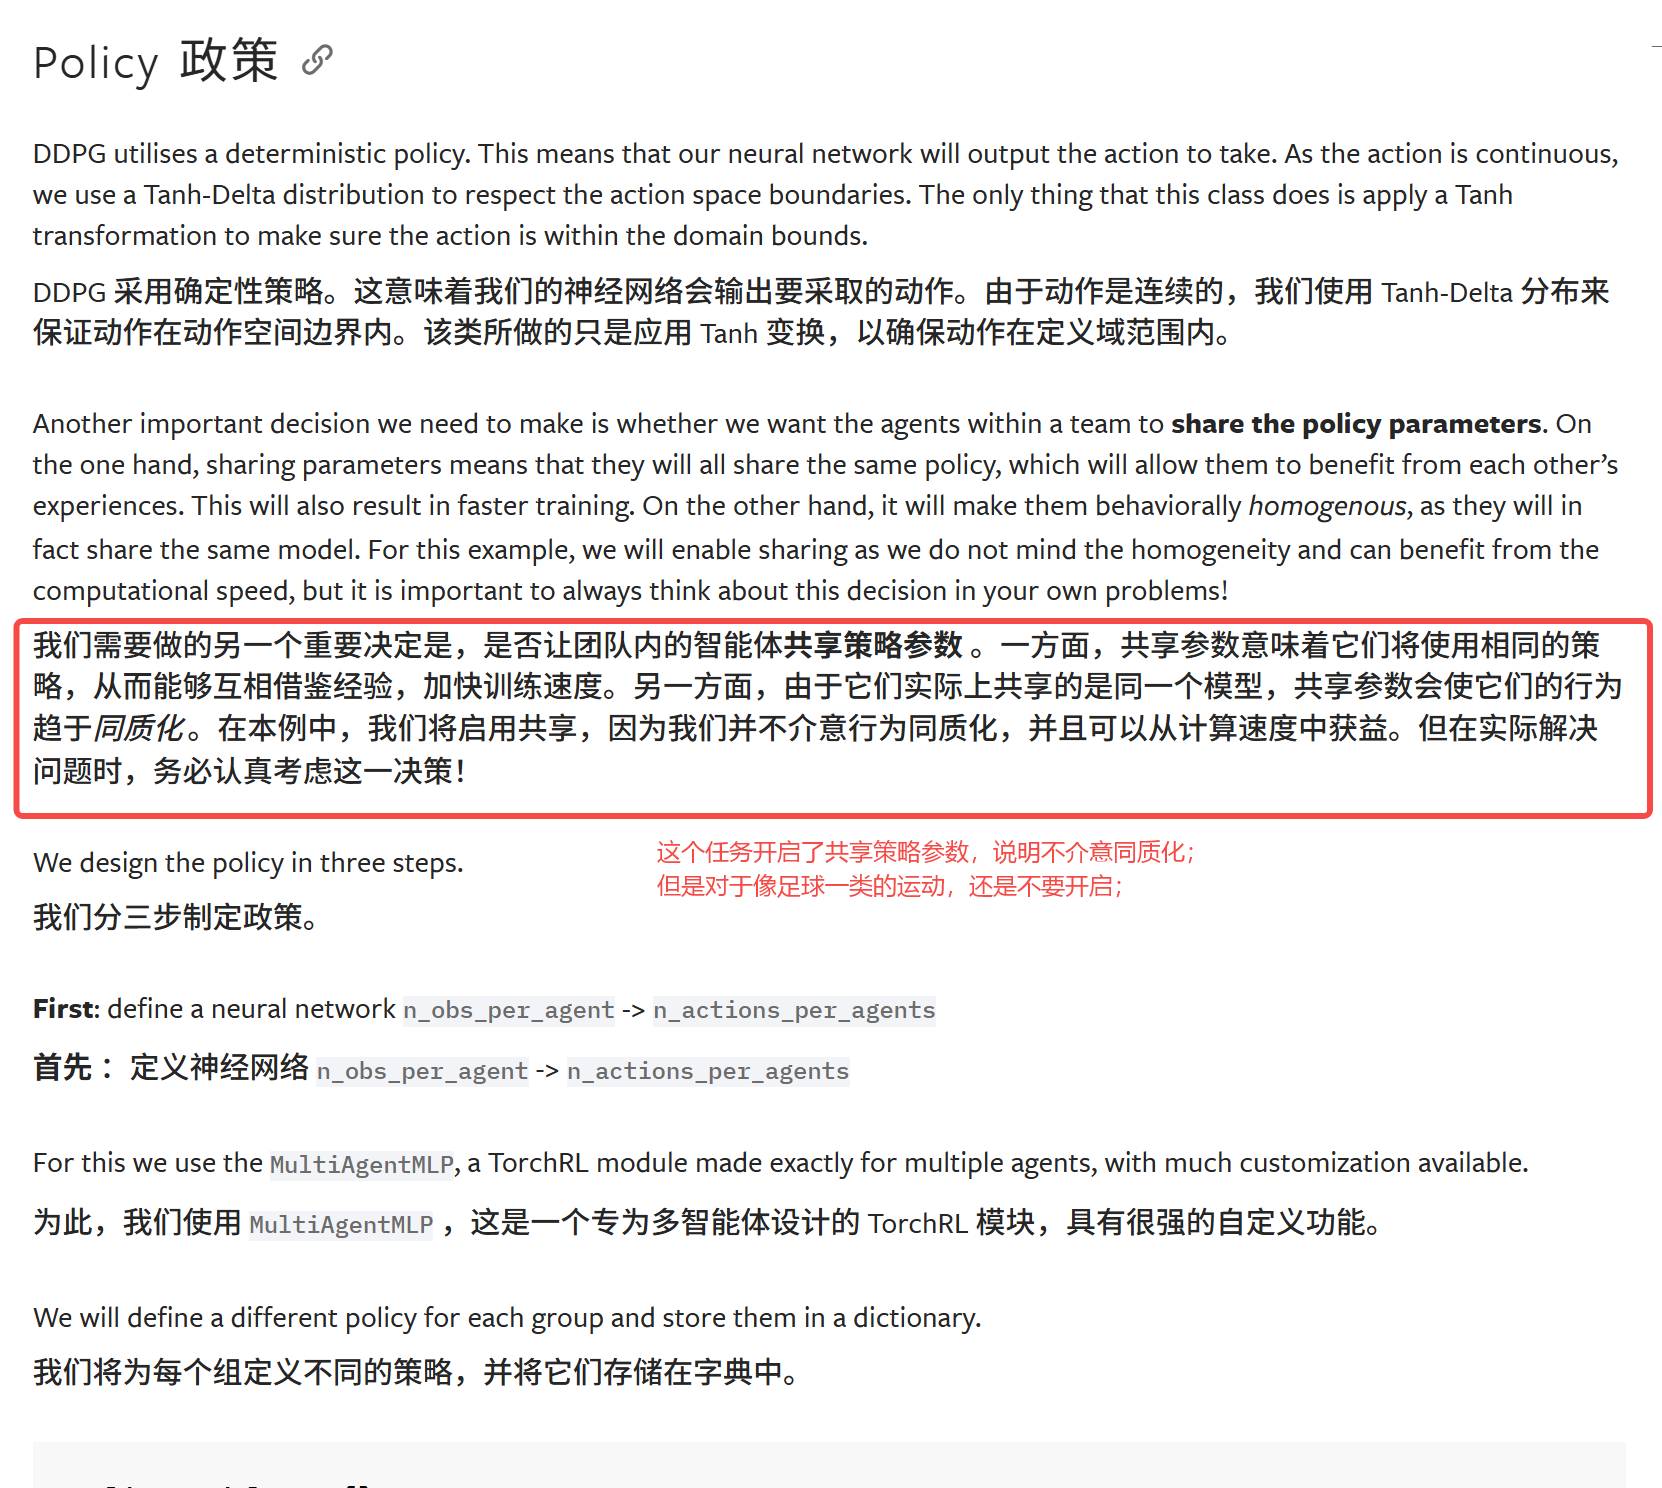
4.Policy
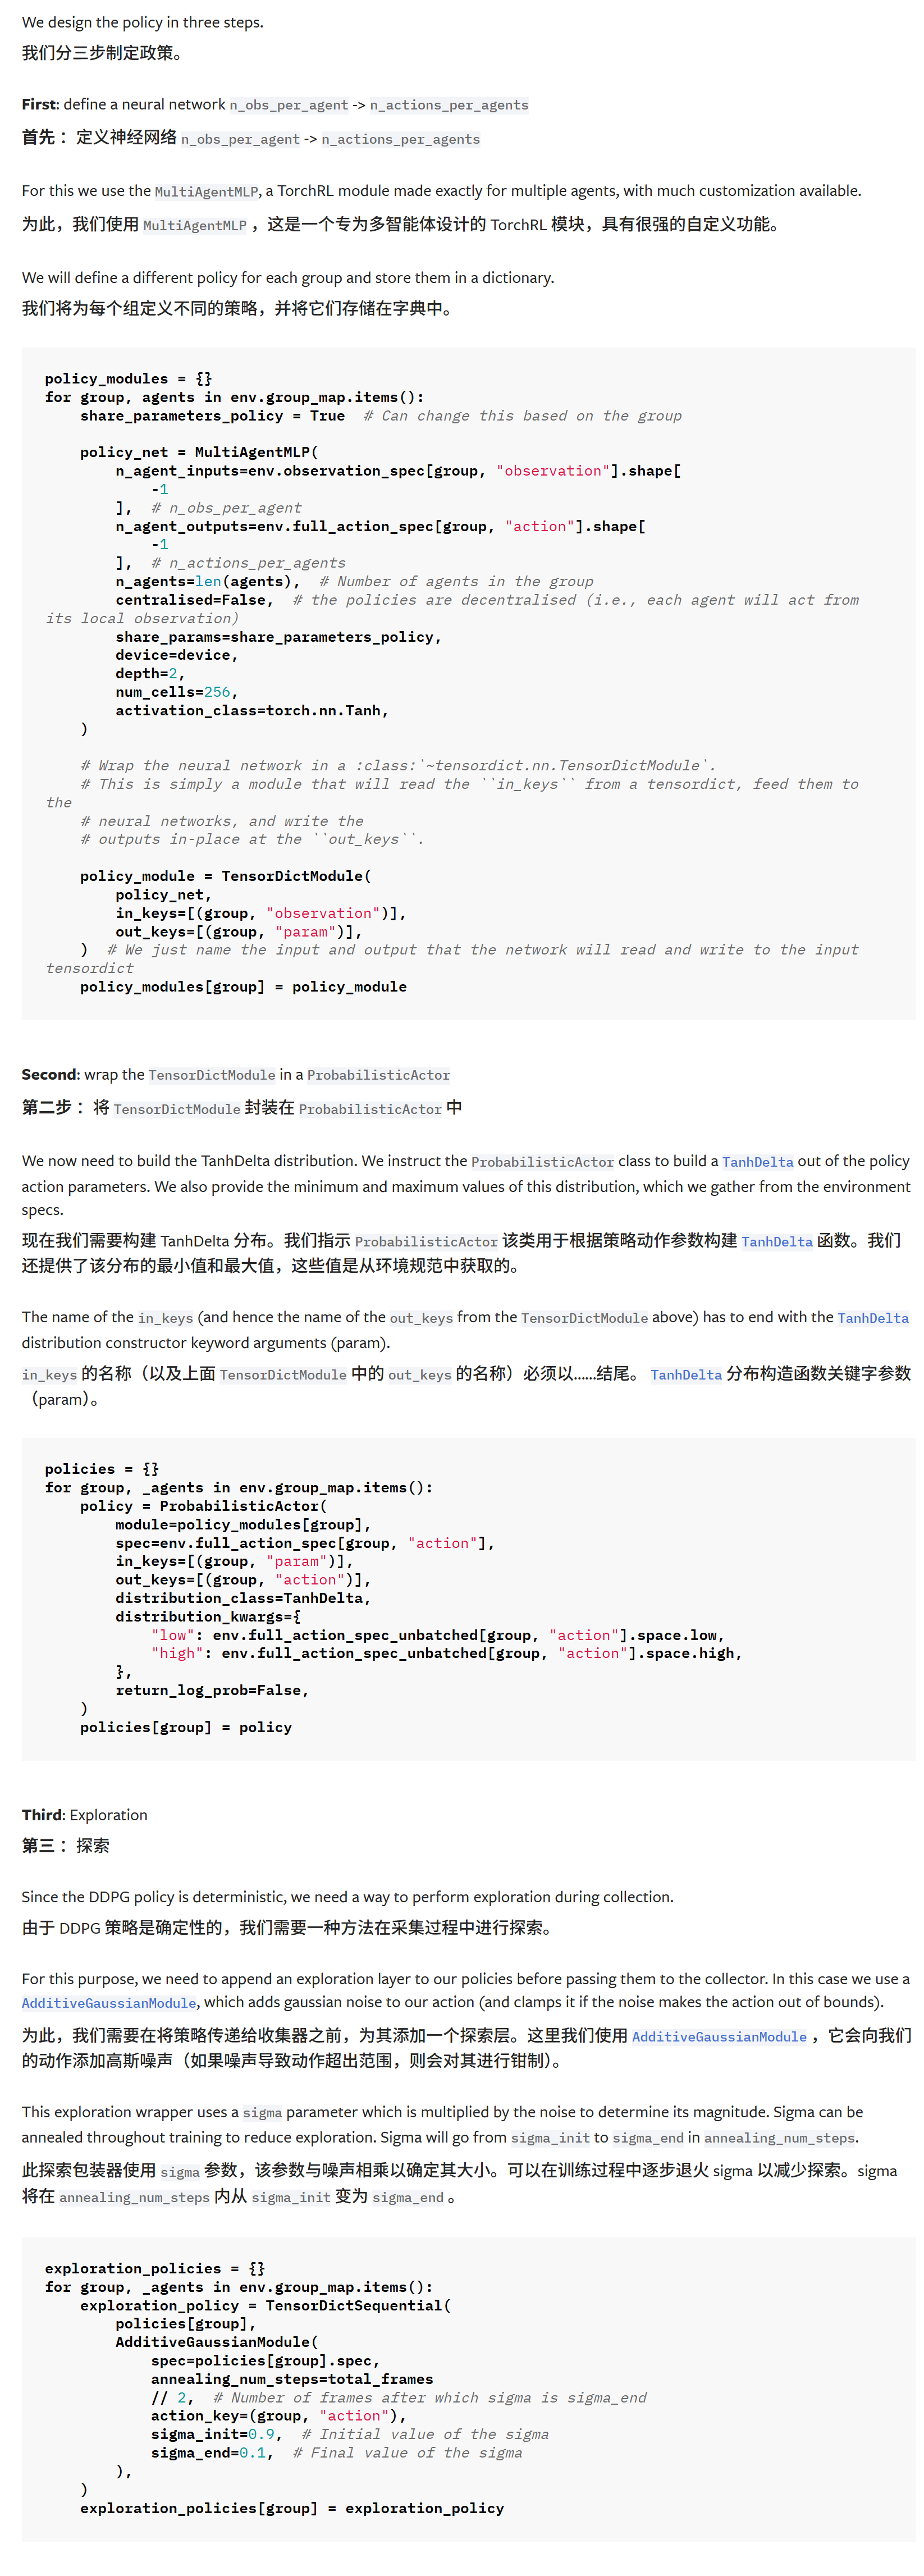
流程:
构造原始网络得到分布参数
根据参数构造分布,采样动作
add噪声,增加探索;
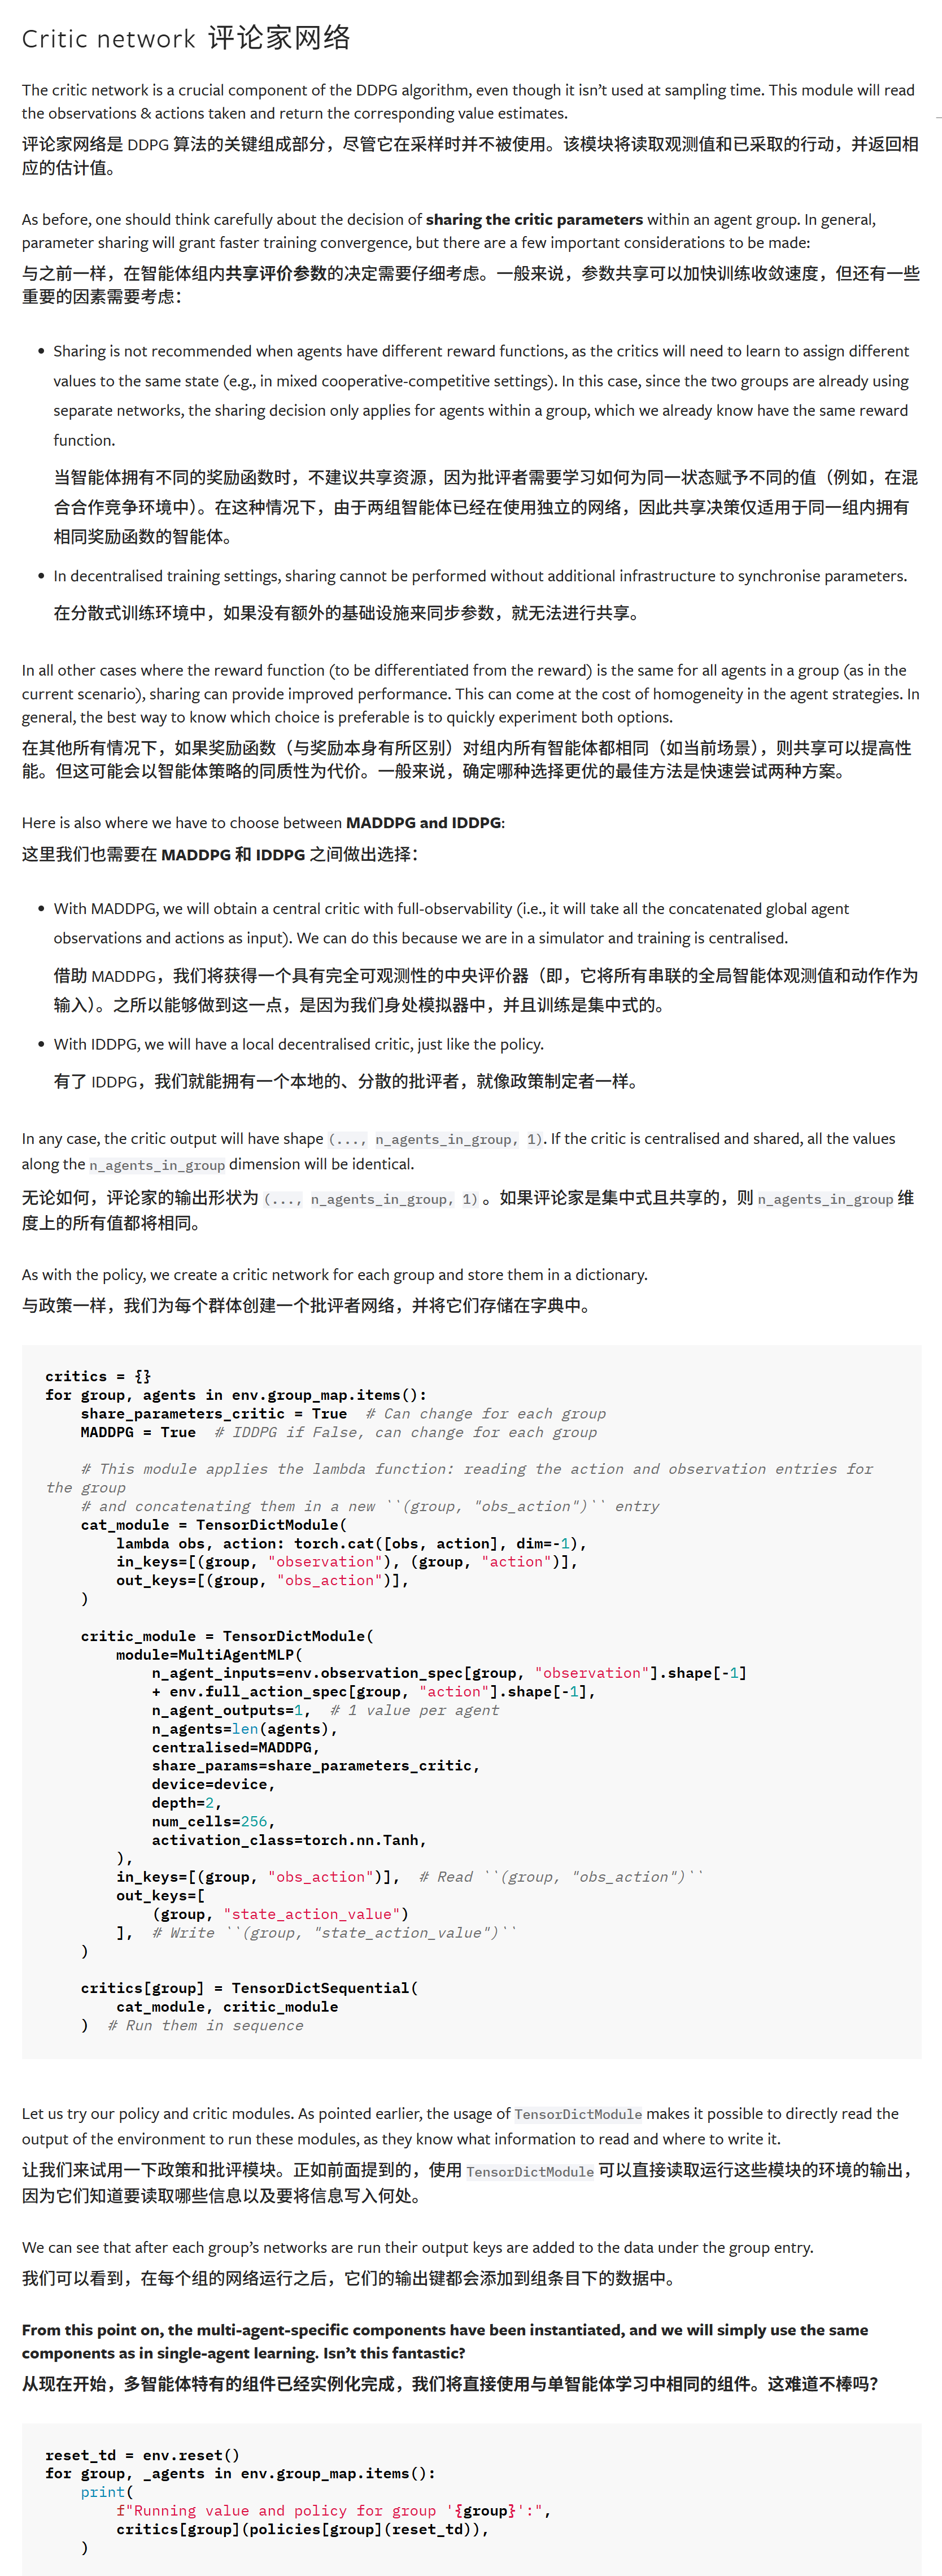
5.Critic
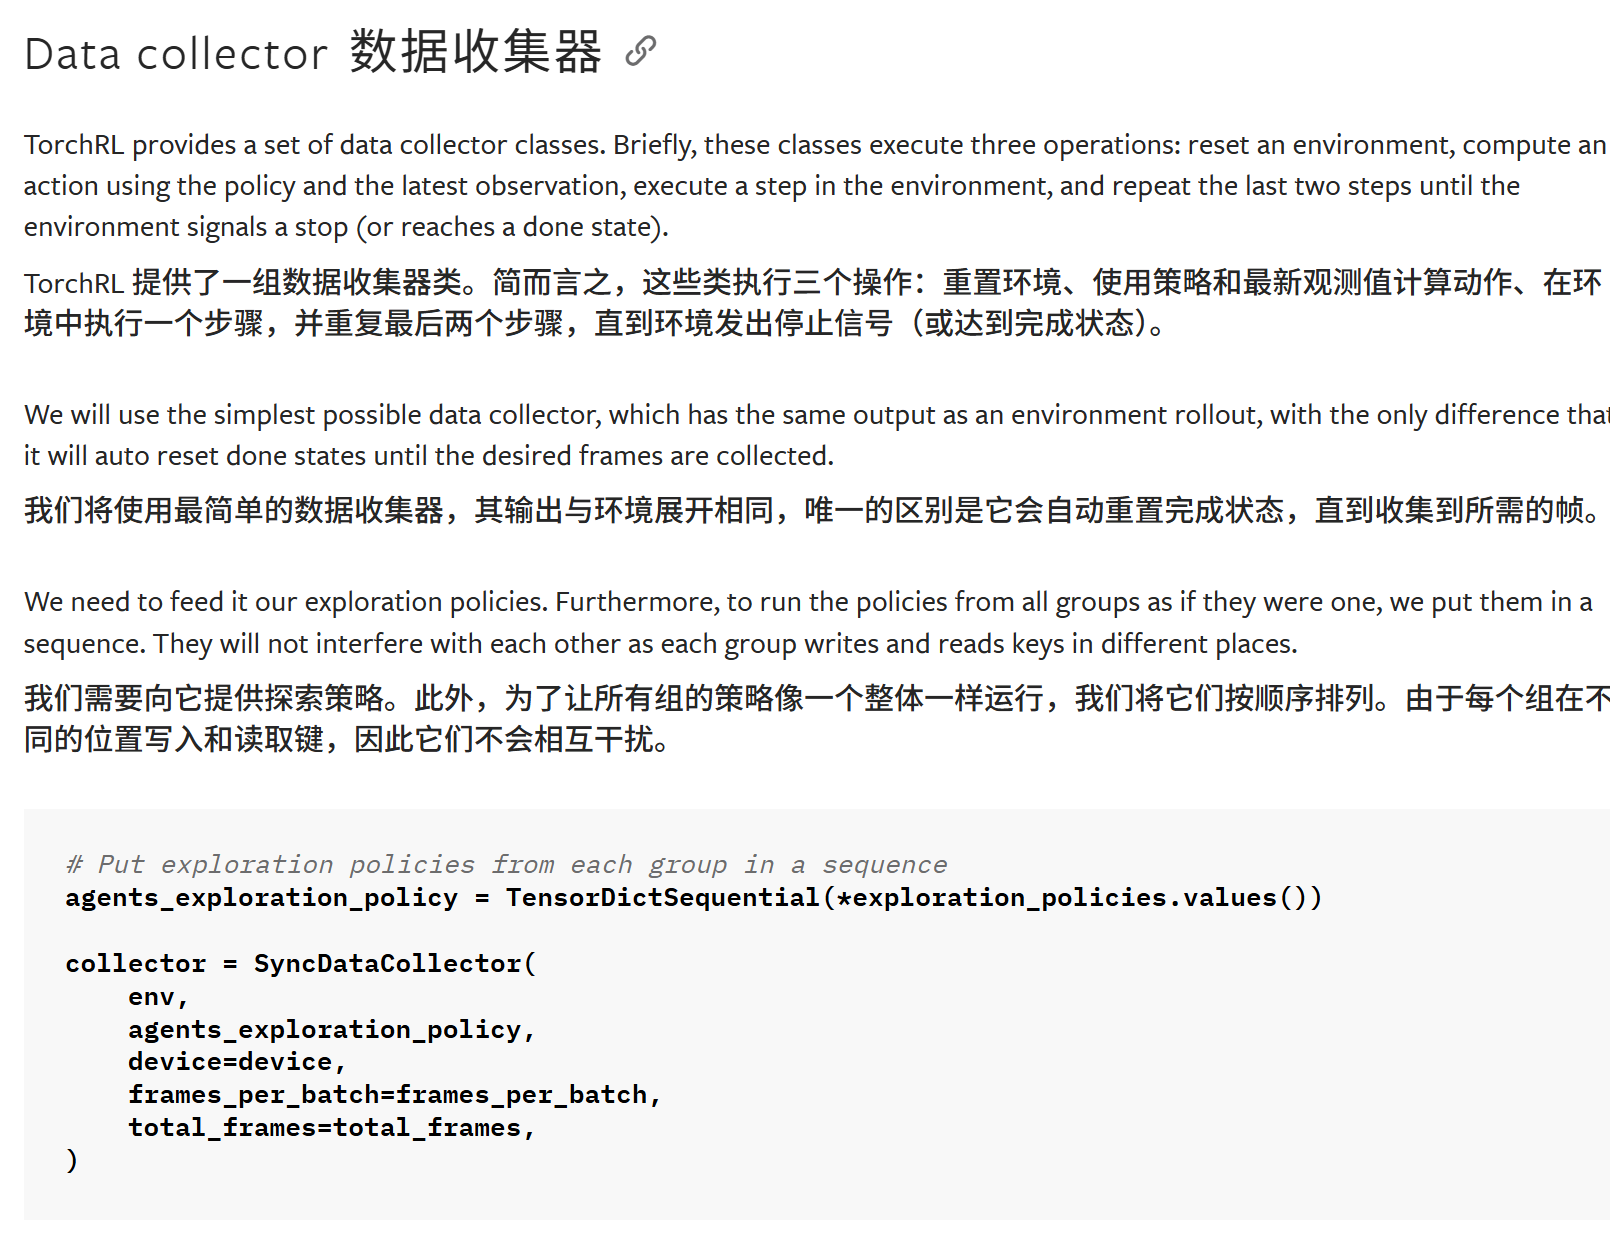
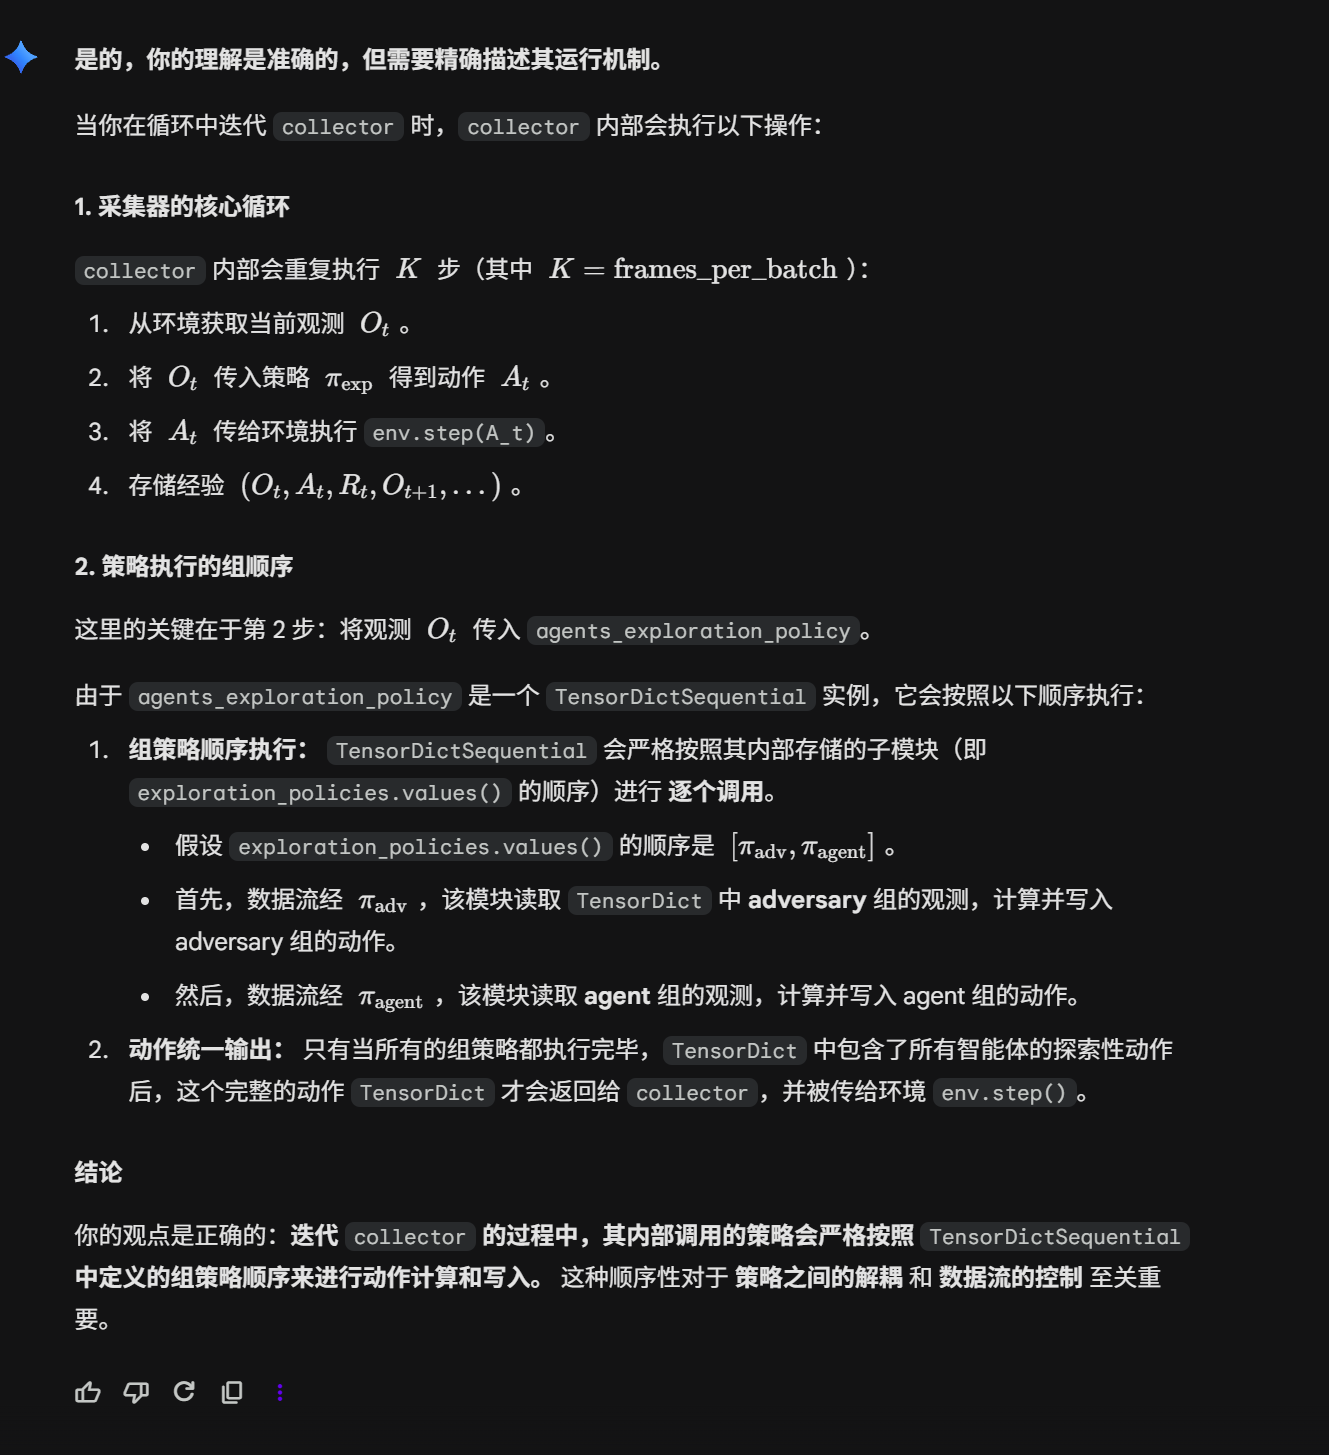
6.Collector
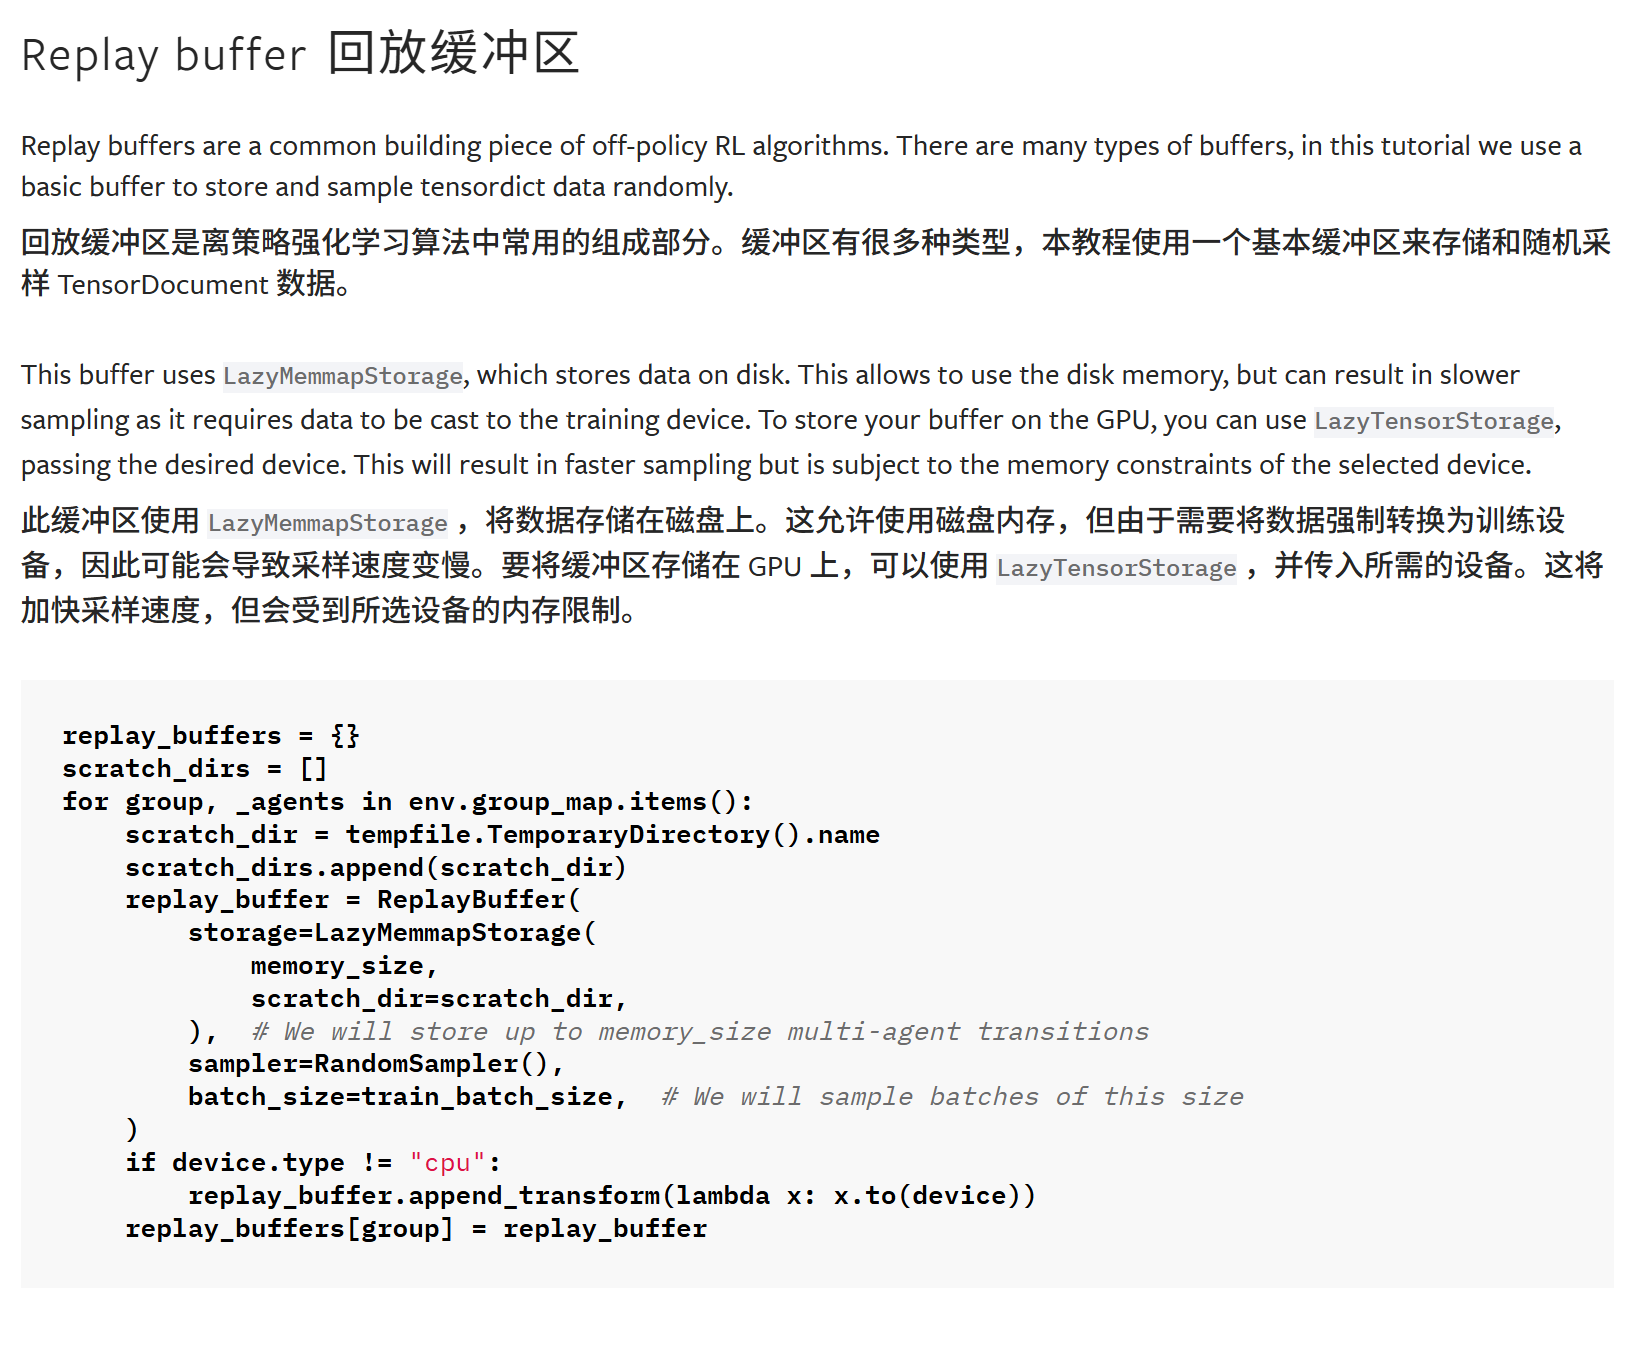
7.Replybuffer
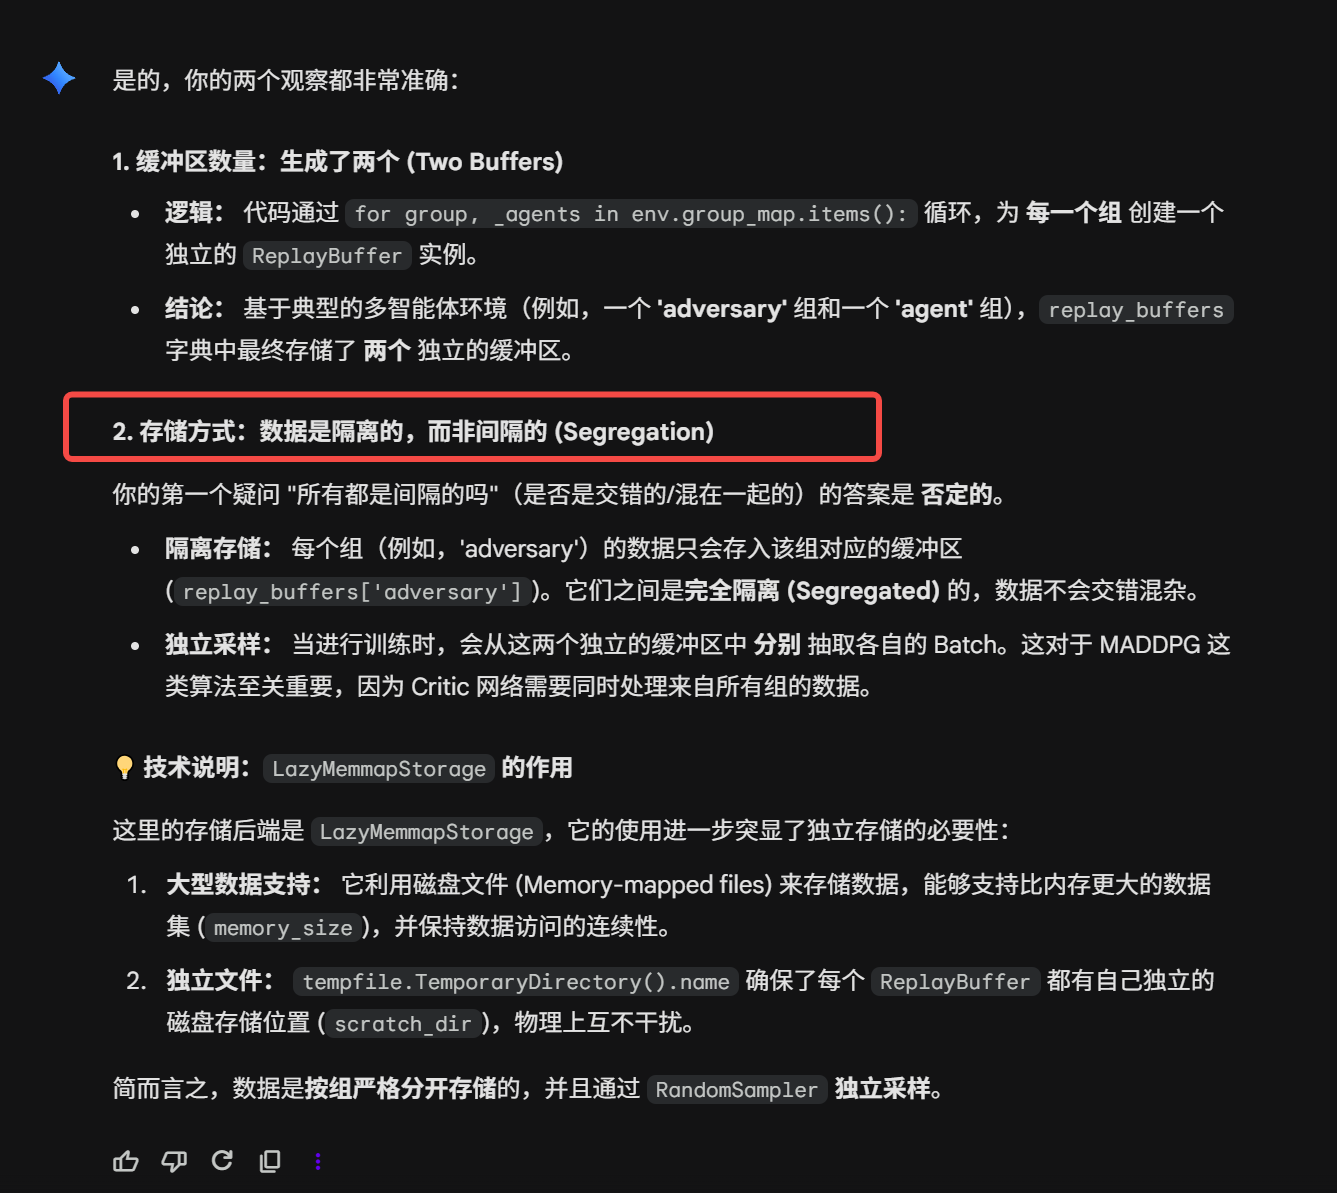
严格分离
8.utils
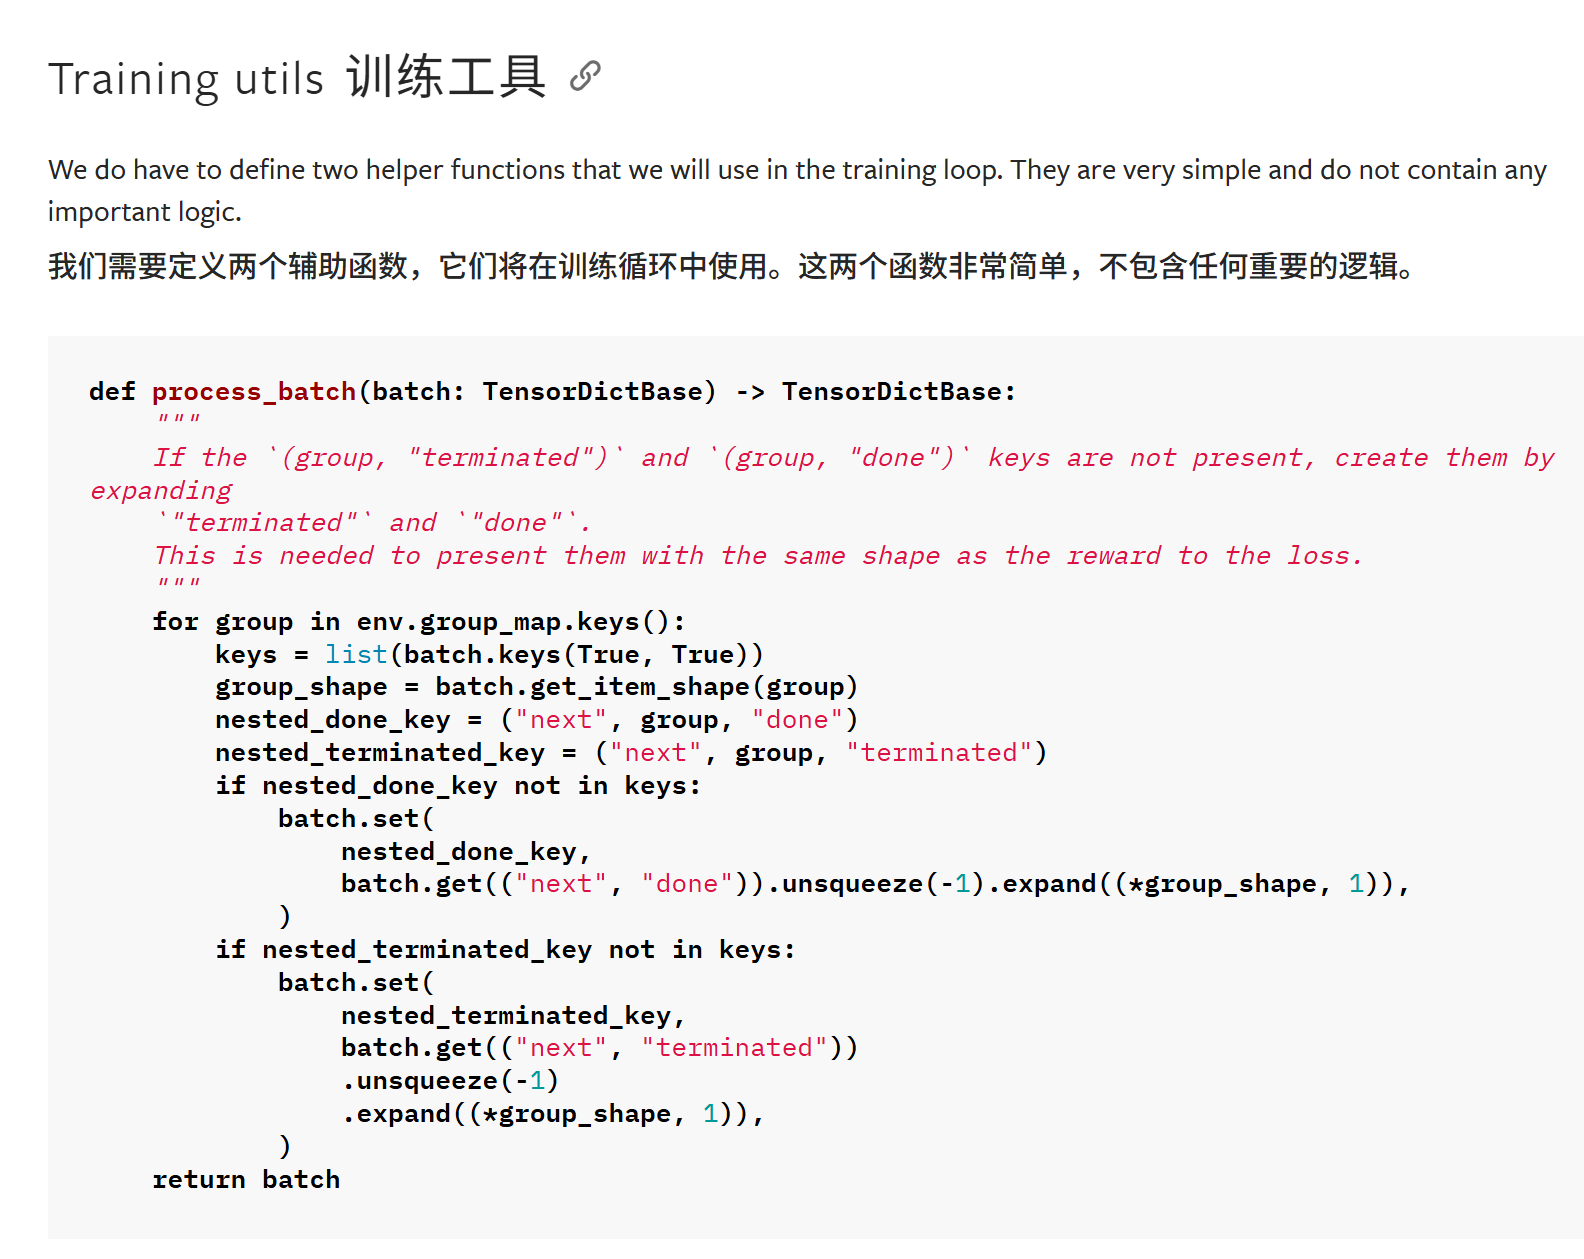
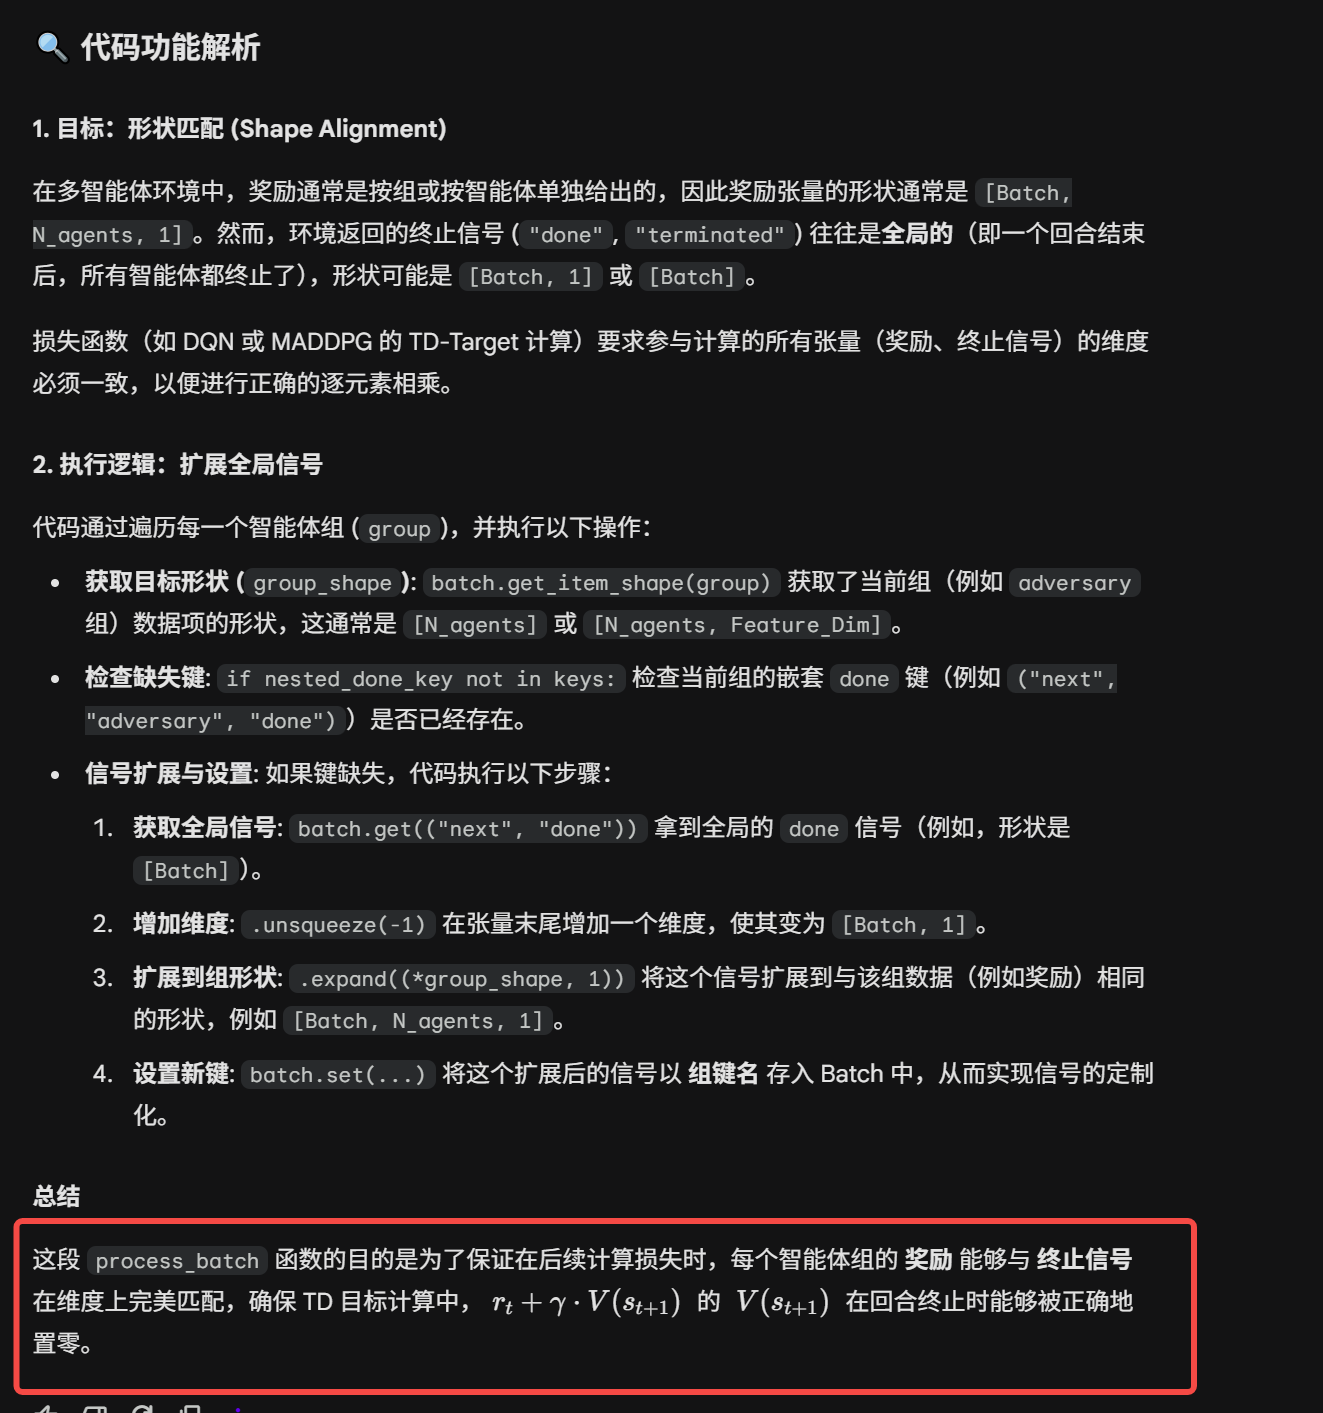
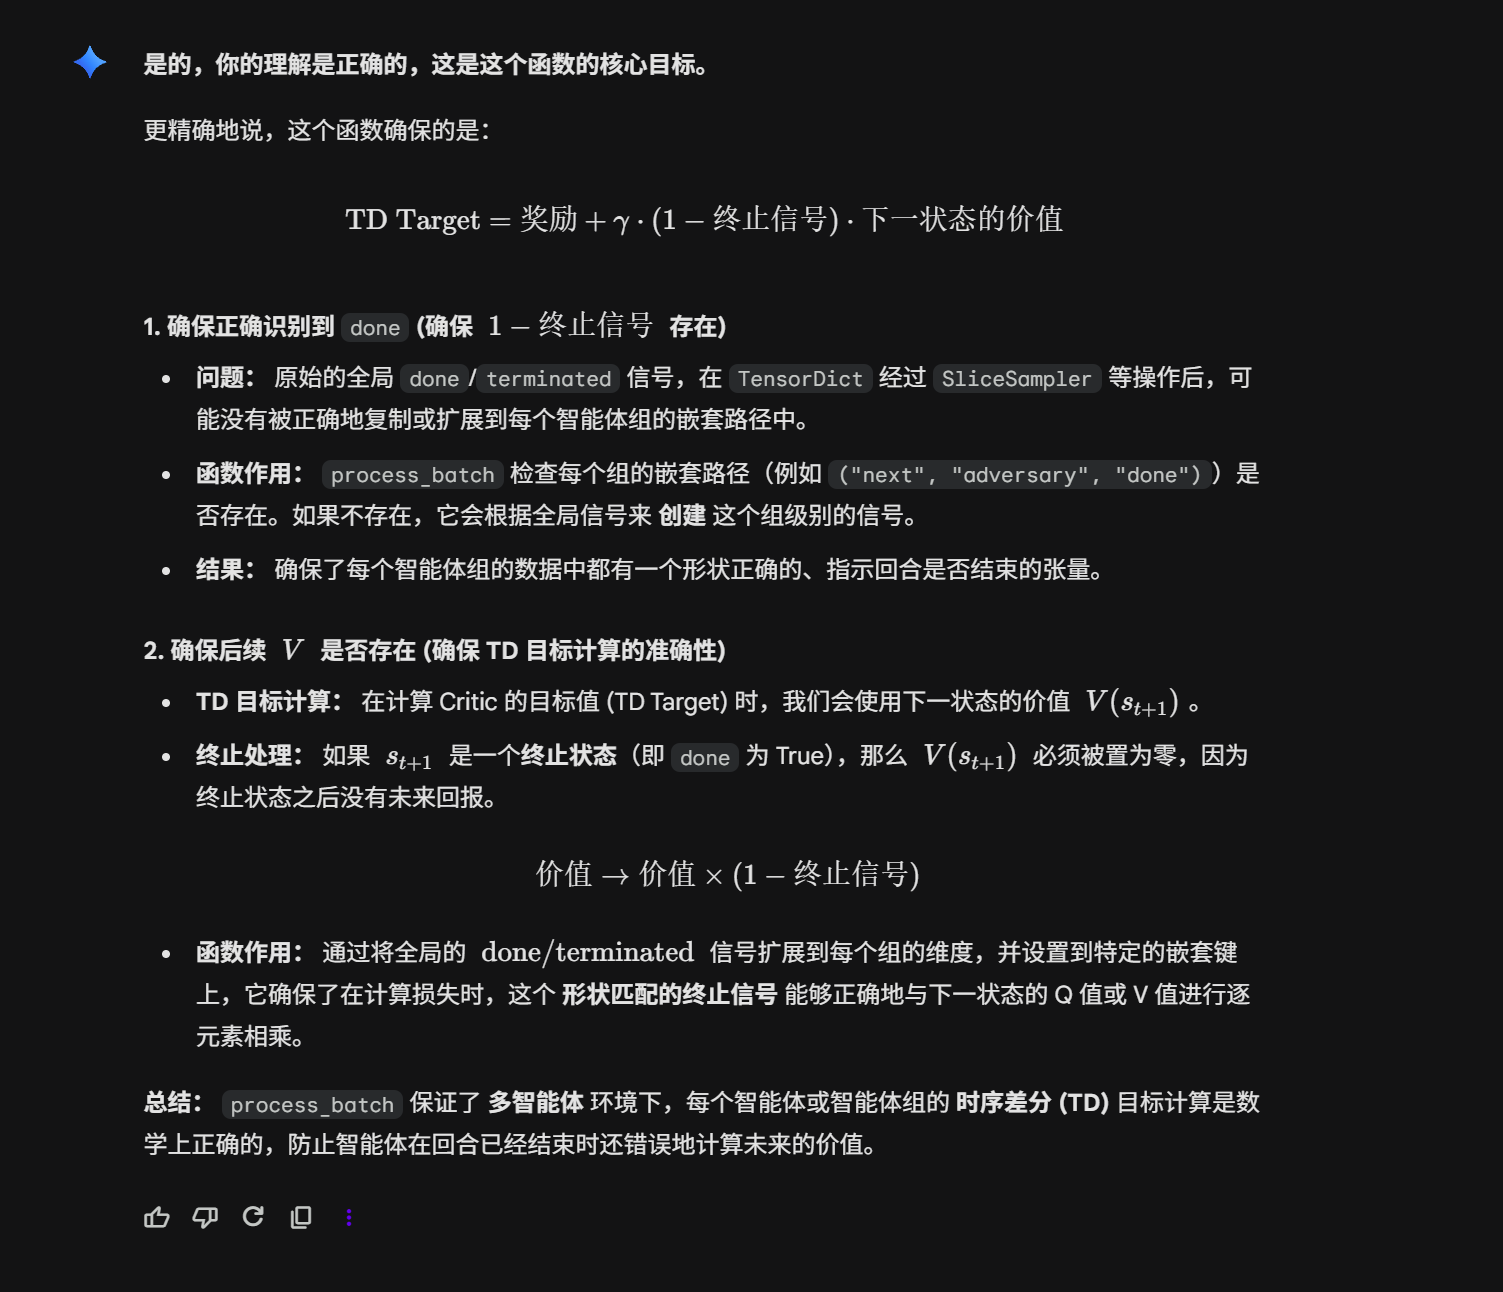
将done和terminated扩展到group而不再是全局,因为后面的V需要能被正确识别是否是done;
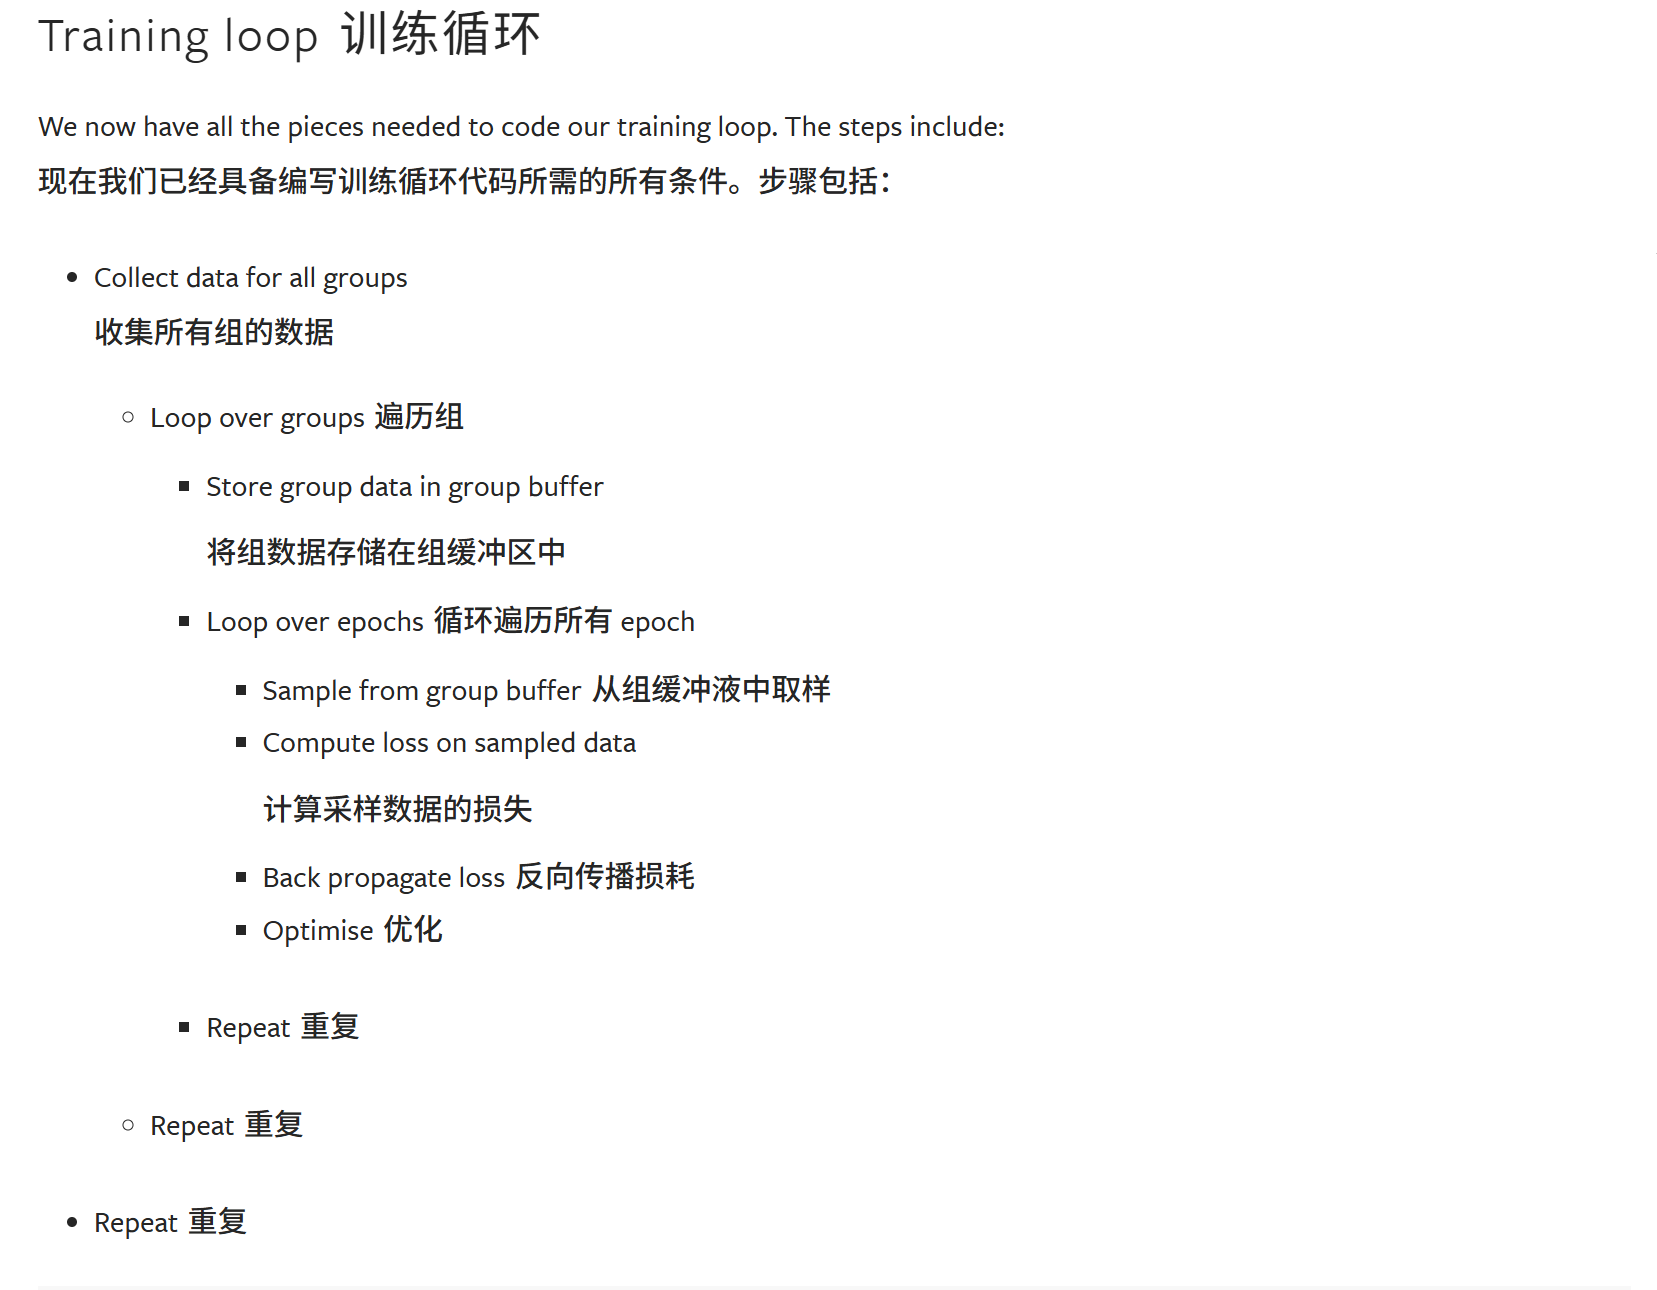
9.Train_loop