本篇文章主要介绍如何构建一个Agent能够解析PDF格式的简历,根据简历的内容,对简历进行优化,以新的格式重新整理内容,并且输出为PDF格式的文件。
1、环境依赖
参考:https://blog.csdn.net/jimmyleeee/article/details/155646865
对于依赖库有所不同,可以参考如下:
python
pip install langchain-community langchain-ollama pymupdf reportlab fpdf2 weasyprint2、构建可以优化简历的Agent
关于保存成PDF格式文件,尝试了三种库:
- reportlab : 实现函数:save_as_pdf1,有乱码问题,在PDF中显示了黑色的长方形方块
- fpdf2 :实现函数:save_as_pdf2,有乱码问题,在PDF中显示了问号
- weasyprint : 实现函数:save_as_pdf, 没有乱码问题,对Unicode的支持相对比较好。
python
from langchain_community.document_loaders import PyMuPDFLoader
from langchain_ollama import ChatOllama
from langchain_core.prompts import SystemMessagePromptTemplate, HumanMessagePromptTemplate, ChatPromptTemplate
from langchain_core.output_parsers import StrOutputParser
import json

# Configuration
base_url = "http://localhost:11434"
model = "qwen2.5"

# Initialize LLM
llm = ChatOllama(model=model, base_url=base_url)

# System prompt for resume polishing
system_prompt = SystemMessagePromptTemplate.from_template(
    """You are an expert HR consultant and resume writer. You specialize in optimizing resumes for Applicant Tracking Systems (ATS)
    and making them visually appealing while maintaining all relevant information. You always provide well-structured, professional
    responses in proper English."""
)

# Resume polishing prompt
polish_prompt = HumanMessagePromptTemplate.from_template("""
    You are tasked with taking a parsed resume and creating an improved, professionally formatted version.

    Original Resume Content:
    {resume_content}

    Please perform the following tasks:
    1. Restructure the information into a clear, logical format with appropriate sections
    2. Improve wording and phrasing to make it more professional and impactful
    3. Ensure consistent formatting throughout
    4. Optimize for readability while preserving all original information
    5. Fill in any missing section headers if needed

    Expected Output Structure:
    - Contact Information (Name, Email, Phone, LinkedIn/Website if available)
    - Professional Summary (A brief 2-3 sentence overview)
    - Technical Skills (Organized by category)
    - Work Experience (With company, role, dates, and bullet-point responsibilities/achievements)
    - Education (Degree, institution, graduation date)
    - Projects (If applicable)
    - Certifications (If applicable)
    - Additional Information (Languages, interests, etc.)

    Important Guidelines:
    - Maintain all factual information from the original
    - Use strong action verbs
    - Quantify achievements where possible
    - Keep formatting clean and professional
    - Do not add fictional information

    Provide only the polished resume content in a structured format, without any markdown or extra explanations.
""")

def load_pdf(file_path):
    """
    Load and parse PDF file

    Args:
        file_path (str): Path to the PDF file

    Returns:
        str: Parsed content from the PDF
    """
    loader = PyMuPDFLoader(file_path)
    docs = loader.load()
    return "\n".join([doc.page_content for doc in docs])

def polish_resume(resume_content):
    """
    Polish resume content using LLM

    Args:
        resume_content (str): Raw parsed resume content

    Returns:
        str: Polished resume content
    """
    messages = [system_prompt, polish_prompt]
    template = ChatPromptTemplate.from_messages(messages)

    polish_chain = template | llm | StrOutputParser()
    return polish_chain.invoke({"resume_content": resume_content})

def save_as_txt(content, output_path):
    """
    Save polished content as text file

    Args:
        content (str): Polished resume content
        output_path (str): Output file path
    """
    with open(output_path, 'w', encoding='utf-8') as f:
        f.write(content)
# implemented by weasyprint
def save_as_pdf(content, output_path):
    """
    Save polished content as PDF file using WeasyPrint (best Unicode support)

    Args:
        content (str): Polished resume content
        output_path (str): Output PDF file path
    """
    try:
        from weasyprint import HTML, CSS
        import tempfile
        import os

        # Create HTML content with proper encoding
        html_content = f"""
        <!DOCTYPE html>
        <html>
        <head>
            <meta charset="UTF-8">
            <style>
                body {{
                    font-family: "Microsoft YaHei", "SimSun", "PingFang SC", sans-serif;
                    font-size: 12pt;
                    line-height: 1.5;
                    margin: 1in;
                }}
                pre {{
                    white-space: pre-wrap;
                    word-wrap: break-word;
                }}
            </style>
        </head>
        <body>
            <pre>{content}</pre>
        </body>
        </html>
        """

        # Generate PDF
        html = HTML(string=html_content)
        html.write_pdf(output_path)
        print(f"PDF saved to {output_path}")

    except ImportError:
        print("WeasyPrint not installed. Install with: pip install weasyprint")
        txt_path = output_path.replace('.pdf', '.txt')
        save_as_txt(content, txt_path)
        print(f"TXT saved to {txt_path}")
    except Exception as e:
        print(f"Error creating PDF with WeasyPrint: {e}")
        # Fallback to text file
        txt_path = output_path.replace('.pdf', '.txt')
        save_as_txt(content, txt_path)
        print(f"TXT saved to {txt_path} as fallback")

# implemented by fpdf2
def save_as_pdf2(content, output_path):
    """
    Save polished content as PDF file using fpdf2 with better Unicode support

    Args:
        content (str): Polished resume content
        output_path (str): Output PDF file path
    """
    try:
        from fpdf import FPDF

        class PDF(FPDF):
            def header(self):
                pass

            def footer(self):
                pass

        pdf = PDF()
        pdf.add_page()
        pdf.set_auto_page_break(auto=True, margin=15)

        # Set font (you may need to specify a path to a Unicode font)
        try:
            # Try to use a Unicode font
            pdf.add_font('DejaVu', '', 'DejaVuSans.ttf', uni=True)
            pdf.set_font('DejaVu', '', 12)
        except:
            # Fallback to built-in font
            pdf.set_font('Arial', '', 12)

        # Add content
        lines = content.split('\n')
        for line in lines:
            pdf.cell(0, 10, line.encode('latin-1', 'replace').decode('latin-1'), ln=True)

        pdf.output(output_path)
        print(f"PDF saved to {output_path}")

    except ImportError:
        print("fpdf2 not installed. Saving as TXT instead.")
        txt_path = output_path.replace('.pdf', '.txt')
        save_as_txt(content, txt_path)
        print(f"TXT saved to {txt_path}")
    except Exception as e:
        print(f"Error creating PDF: {e}")
        # Fallback to text file
        txt_path = output_path.replace('.pdf', '.txt')
        save_as_txt(content, txt_path)
        print(f"TXT saved to {txt_path} as fallback")

# implemented by reportlab
def save_as_pdf1(content, output_path):
    """
    Save polished content as PDF file (requires additional libraries)

    Args:
        content (str): Polished resume content
        output_path (str): Output PDF file path
    """
    try:
        from reportlab.lib.pagesizes import letter
        from reportlab.platypus import SimpleDocTemplate, Paragraph, Spacer
        from reportlab.lib.styles import getSampleStyleSheet

        doc = SimpleDocTemplate(output_path, pagesize=letter)
        styles = getSampleStyleSheet()
        story = []

        # Split content into lines and create paragraphs
        lines = content.split('\n')
        for line in lines:
            if line.strip():
                story.append(Paragraph(line, styles['Normal']))
                story.append(Spacer(1, 12))

        doc.build(story)
        print(f"PDF saved to {output_path}")
    except ImportError:
        print("reportlab not installed. Saving as TXT instead.")
        txt_path = output_path.replace('.pdf', '.txt')
        save_as_txt(content, txt_path)
        print(f"TXT saved to {txt_path}")

def process_resume(input_pdf_path, output_path):
    """
    Main function to process resume from PDF to polished format

    Args:
        input_pdf_path (str): Input PDF file path
        output_path (str): Output file path (.txt or .pdf)
    """
    # Load PDF
    print("Loading PDF...")
    raw_content = load_pdf(input_pdf_path)

    # Polish content
    print("Polishing resume with LLM...")
    polished_content = polish_resume(raw_content)

    # Save result
    if output_path.endswith('.pdf'):
        save_as_pdf(polished_content, output_path)
    else:
        save_as_txt(polished_content, output_path)

    print(f"Polished resume saved to {output_path}")
    return polished_content


if __name__ == "__main__":
    input_path = "resume/test_resume.pdf"
    output_path = "polished_resumes/test_polished.pdf"  # or .pdf
    polished = process_resume(input_path, output_path)
    print(polished)
3、运行Agent进行测试
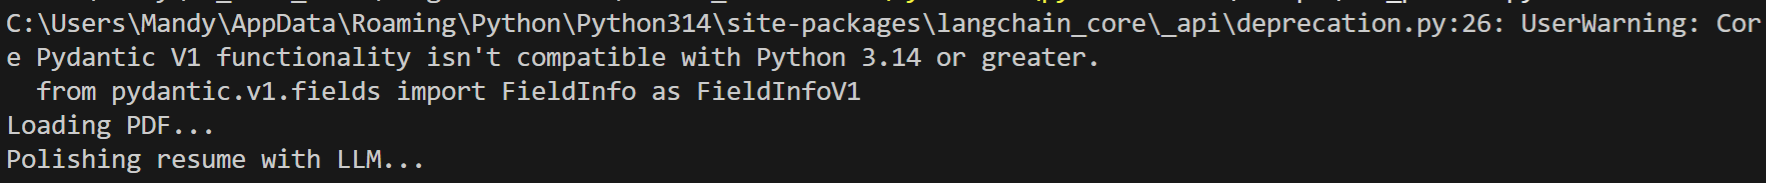
在weasyprint 实现的版本中,运行中由于遇到问题:
"Error creating PDF with WeasyPrint: cannot load library 'libgobject-2.0-0': error 0x7e. Additionally, ctypes.util.find_library() did not manage to locate a library called 'libgobject-2.0-0'
TXT saved to polished_resumes/test_polished.txt as fallback",【经过查询需要安装GTK,下载路径 https://github.com/tschoonj/GTK-for-Windows-Runtime-Environment-Installer,并且需要将GTK的可执行文件添加到PATH环境变量里才可以解决此问题。】导致了不能生成PDF,而输出了txt文件,在TXT的文件里,也没有了乱码的问题。 不过,在输出的结果中,公司名称和大学名称还不能翻译成英文,而是直接显示成了中文。 整体上,优化过的简历可以作为参考,通过Word或者WPS打开,简单改改还是可以使用的。 有兴趣进一步优化的,可以选择进一步尝试如何一步到位,解决公司和学校名称不能翻译的问题。