1.提示链模式 (Prompt Chaining)
前一个节点的输出作为下一个节点的输入
案例 : AI 文章生成系统
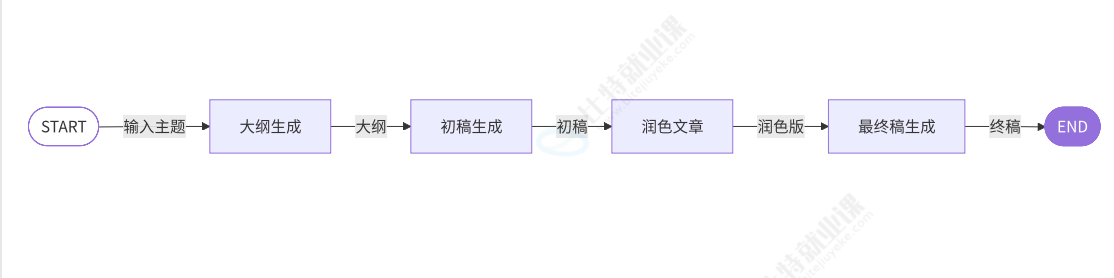
我们可以创建一个内容创作场景的工作流,包含 大纲 → 初稿 → 润色 → 最终稿。节点即可设计为:
-
generate_outline节点: 只负责大纲生成 -
generate_draft节点: 只负责初稿写作 -
polish_content节点: 只负责内容润色 -
finalize_content节点: 只负责最终整合from typing import TypedDict
from langgraph.graph import StateGraph, START, END
from langchain_core.messages import HumanMessage
from langchain.chat_models import init_chat_model初始化模型
model = init_chat_model("gpt-4o-mini")
==================== 状态定义 ====================
class InputState(TypedDict):
topic: strclass OutputState(TypedDict):
final_content: str内部状态必须包含所有中间字段 + 输入字段
class State(TypedDict):
topic: str # ⚠️ 必须包含,否则后续节点无法读取 topic
outline: str
draft: str
polished_draft: str==================== Prompt & 节点 ====================
PROMPT_1 = (
"根据主题生成文章大纲。\n"
"主题:{topic}\n"
"要求:\n"
"1.只需两个最核心标题\n"
"2.不用进行说明,只返回最终大纲"
)def node_outline(state: State):
"""根据主题生成文章内容大纲"""
print("~" * 30)
print("生成大纲中")
prompt = PROMPT_1.format(topic=state["topic"])
outline = model.invoke([HumanMessage(content=prompt)]).content
print(f"大纲已生成:\n{outline}\n")
return {"outline": outline}PROMPT_2 = (
"根据以下内容生成文章完整初稿。\n"
"主题:{topic}\n"
"大纲:{outline}\n"
"要求:\n"
"1.每个标题下,最多使用三句话的内容即可\n"
"2.不用进行说明,只返回最终结果"
)def node_draft(state: State):
"""根据内容大纲生成内容初稿"""
print("~" * 30)
print("生成初稿中")
prompt = PROMPT_2.format(topic=state["topic"], outline=state["outline"])
draft = model.invoke([HumanMessage(content=prompt)]).content
print(f"初稿已生成:\n{draft}\n")
return {"draft": draft}PROMPT_3 = (
"根据文章初稿进行润色。\n"
"主题:{topic}\n"
"初稿:{draft}\n"
"要求:\n"
"1.润色后,文章不能太长"
)def node_polished_draft(state: State):
"""根据文章初稿进行润色"""
print("~" * 30)
print("生成润色稿中")
prompt = PROMPT_3.format(topic=state["topic"], draft=state["draft"])
polished_draft = model.invoke([HumanMessage(content=prompt)]).content
print(f"润色稿已生成:\n{polished_draft}\n")
return {"polished_draft": polished_draft}PROMPT_4 = (
"根据润色版文章,生成文章终稿。\n"
"主题:{topic}\n"
"大纲:{outline}\n"
"润色版文章:{polished_draft}\n"
)def node_final_content(state: State):
"""生成终稿"""
print("~" * 30)
print("生成终稿中")
prompt = PROMPT_4.format(
topic=state["topic"],
outline=state["outline"],
polished_draft=state["polished_draft"]
)
final_content = model.invoke([HumanMessage(content=prompt)]).content
print(f"终稿已生成:\n{final_content}\n")
return {"final_content": final_content}==================== 构建工作流 ====================
builder = StateGraph(
State,
input_schema=InputState,
output_schema=OutputState
)添加节点(使用函数名作为节点ID)
builder.add_node("node_outline", node_outline)
builder.add_node("node_draft", node_draft)
builder.add_node("node_polished_draft", node_polished_draft)
builder.add_node("node_final_content", node_final_content)连接边
builder.add_edge(START, "node_outline")
builder.add_edge("node_outline", "node_draft")
builder.add_edge("node_draft", "node_polished_draft")
builder.add_edge("node_polished_draft", "node_final_content")
builder.add_edge("node_final_content", END)agent = builder.compile()
==================== 运行 ====================
result = agent.invoke({"topic": "人工智能未来的发展"})
print("=" * 50)
print("最终结果:")
print(result["final_content"])
print("=" * 50)
2.并行化模式(ParalleLization)
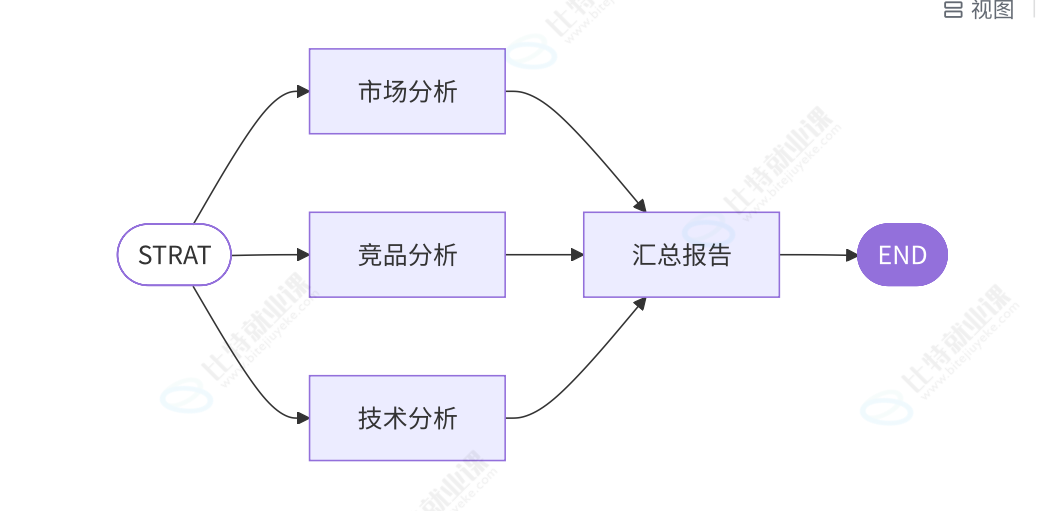
多个任务同时进行, 提高效率, 最终汇总结果
案例 : AI 并行生成汇总报告系统
实现一个工作流, 并行执行三个维度分析, 最后汇总
from typing import TypedDict
from langgraph.constants import START, END
from langgraph.graph import StateGraph

# 定义状态结构
class AnalysisState(TypedDict):
    concept: str       # 概念
    market: str        # 市场分析
    competitor: str    # 竞品分析
    tech: str          # 技术分析
    report: str        # 汇总报告

# --- 三个并行分析任务 ---

def market_task(state: AnalysisState):
    """市场分析"""
    return {"market": "用户关注续航、重量、防盗,对骑行社交"}

def competitor_task(state: AnalysisState):
    """竞品分析"""
    return {"competitor": "传统品牌智能化不足,互联网品牌续"}

def tech_task(state: AnalysisState):
    """技术分析"""
    return {"tech": "轻量化电池车身、GPS防盗、社交App集成."}

# --- 汇总结果 ---

def combine_results(state: AnalysisState):
    """生成最终报告"""
    report = f"产品分析报告\n\n"
    report += f"市场分析:\n{state['market']}\n\n"
    report += f"竞品分析:\n{state['competitor']}\n\n"
    report += f"技术分析:\n{state['tech']}\n\n"
    report += "建议:聚焦续航、防盗、社交功能的平衡发展"
    return {"report": report}

# --- 构建工作流 ---

builder = StateGraph(AnalysisState)

# 添加节点
builder.add_node("market", market_task)
builder.add_node("competitor", competitor_task)
builder.add_node("tech", tech_task)
builder.add_node("combine", combine_results)

# 并行执行三个分析 (扇出)
builder.add_edge(START, "market")
builder.add_edge(START, "competitor")
builder.add_edge(START, "tech")

# 汇总结果 (扇入)
builder.add_edge("market", "combine")
builder.add_edge("competitor", "combine")
builder.add_edge("tech", "combine")
builder.add_edge("combine", END)

workflow = builder.compile()

# --- 使用 ---
if __name__ == "__main__":
    result = workflow.invoke({"concept": "城市通勤智能电动自行"})
    print(result["report"])
3. 路由模式**(Routing)**
智能路由, 根据问题分类
动态分类,达到精准匹配处理能力。核心设计在于条件路由机
• 动态路径选择:可以基于 LLM 分析结果动态决定执行路径(结构化返回)
• 分支隔离:不同类型的问题由专用处理器处理
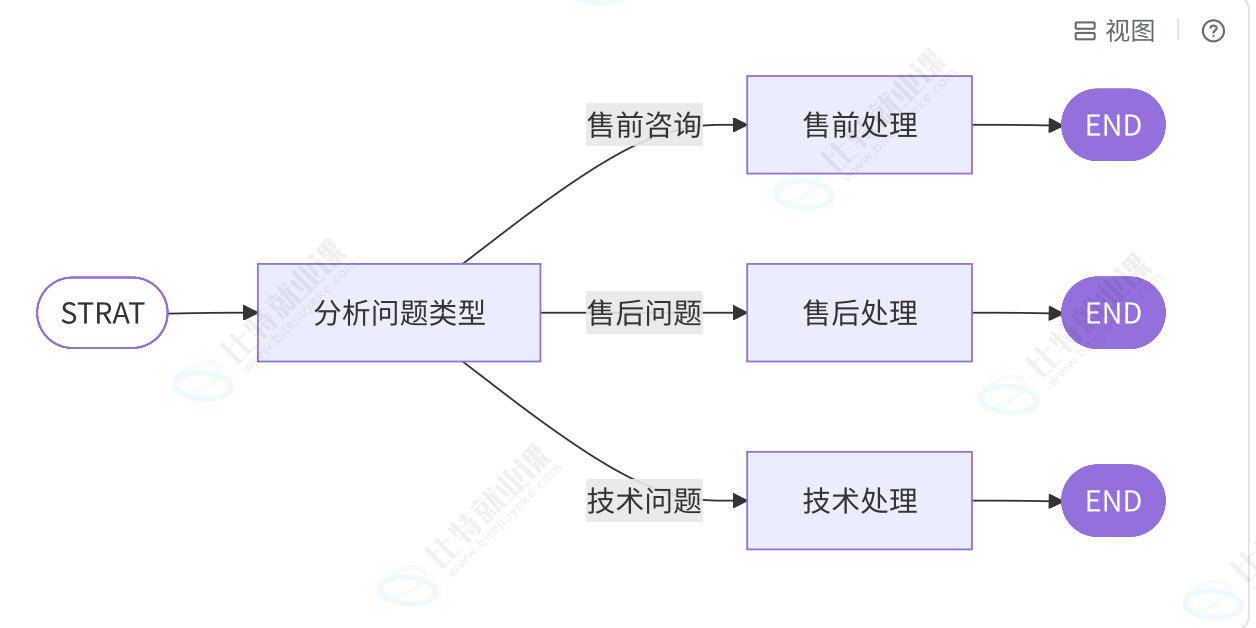
案例 : 实现一个智能客服系统,根据用户问题自制:
节点即可设计为:
-
model_call_router节点: 路由决策节点, 根据用户问题, 由 LLM 通过结构化返回进行智能决策。 -
pre_sale_handler节点: 处理售前咨询 -
after_sale_handler节点: 处理售后问题 -
technical_handler节点: 处理技术问题from typing import TypedDict, Literal
from langgraph.constants import START, END
from langgraph.graph.state import StateGraph
from pydantic import BaseModel, Field
from langchain.chat_models.base import init_chat_model
状态
class State(TypedDict):
input: str
decision: str # 路由决策
output: strclass Route(BaseModel):
decision: Literal["pre_sale","after_sale","technical"] = Field(
description = "根据用户问题类型决定路由到售前,售后还是技术处理"
)节点
def model_call_router(state: State):
model = init_chat_model("gpt-4o-mini")
result = model.with_structured_output(Route).invoke(state["input"])
return {
"decision":result.decision
}def pre_sale_handler(state: State):
"""处理售前咨询"""
return {"output":"已处理售前咨询"}def after_sale_handler(state: State):
"""处理售后咨询"""
return {"output":"已处理售后咨询"}def technical_handler(state: State):
"""处理技术问题"""
return {"output": "技术问题已处理,处理内容....."}路由函数 - 根据决策返回下一个节点
def route_decision(state: State):
if state["decision"] == "pre_sale":
return "pre_sale_handler" # 去售前处理节点
elif state["decision"] == "after_sale":
return "after_sale_handler" # 去售后处理节点
elif state["decision"] == "technical":
return "technical_handler" # 去技术处理节点构建路由工作流
router_builder = StateGraph(State)
添加处理节点
router_builder.add_node(pre_sale_handler)
router_builder.add_node(after_sale_handler)
router_builder.add_node(technical_handler)
router_builder.add_node(model_call_router)先经过路由决策
router_builder.add_edge(START, "model_call_router")
条件边: 根据路由结果选择分支
router_builder.add_conditional_edges(
"model_call_router",
route_decision,
["pre_sale_handler", "after_sale_handler", "technical_handler"]
)所有分支最终都结束
router_builder.add_edge("pre_sale_handler", END)
router_builder.add_edge("after_sale_handler", END)
router_builder.add_edge("technical_handler", END)
router_workflow = router_builder.compile()测试
test_cases = [
"我想了解一下你们产品的价格和功能", # 售前咨询"我购买的产品有质量问题,需要退货", # 售后问题 "这个软件安装后无法正常运行,报错代码0x80070005", # 技术问题 "请问你们的售后服务政策是什么", # 售前咨询 "我的订单已经发货但还没收到", # 售后问题 "如何配置数据库连接参数" # 技术问题]
for test_case in test_cases:
print("*" * 50)
result = router_workflow.invoke({"input": test_case})
print(f"用户问题: {test_case}\n{result['output']}")
4.协调者-工作者模式(Orchestrator-Workers)
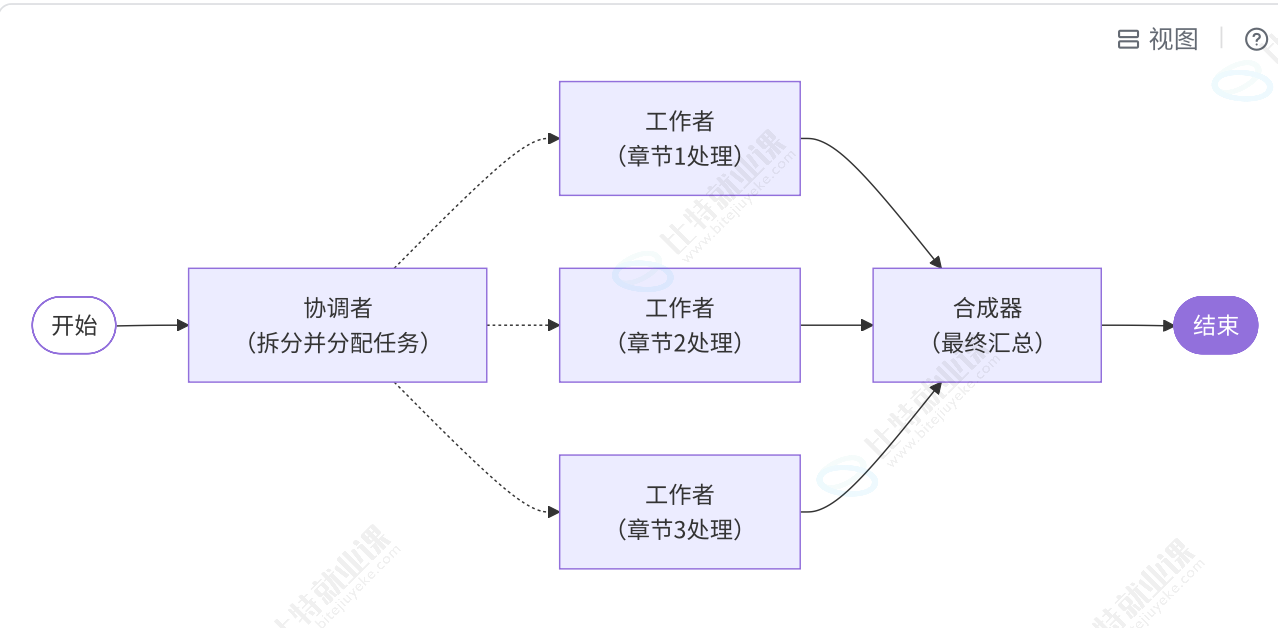
协调者-工作者 模式和并行化 模式都涉及同时执行多个任务,但它们的核心区别在于任务分配方式:
• 并行化 :任务在设计时就确定,所有任务同时开始
• 协调者-工作者 :任务在运行时由协调者动态分配
案例 : 生成文章
- 协调者:负责根据{topic}生成报告大纲。并根据生成的大纲,将生成内容的子任务指派给工作者
- 工作者:生成大纲对应的内容
-
- 注意:协调者生成3个标题,就需要3个工作者生成对应内容;生成10个标题,就需要10个工作者生成对应内容。
- 合成器:汇总所有工作者的成果
因此,关键在于任务指派,协调者在运行时需动态分配工作者,即边的数量在运行时才能确定
为了支持这种设计模式,LangGraph 支持从条件边返回 Send 对象。Send 有两个参数:第一个是节点的名称,第二个是要传递给该节点的状态
from langchain.chat_models import init_chat_model
from langgraph.constants import START, END
from langgraph.graph import StateGraph
from langgraph.types import Send
from typing import Annotated, TypedDict, List
import operator

from pydantic import BaseModel


class State(TypedDict):
    topic: str
    sections: list  # 协调者生成的任务清单
    completed_sections: Annotated[list, operator.add]  # 工作者完成的结果列表
    final_report: str

# 定义数据结构-结构化输出
class Section(BaseModel):
    name: str
    description: str

class Sections(BaseModel):
    sections: List[Section]

# 创建规划器
model = init_chat_model("gpt-4o-mini")

planner = model.with_structured_output(Sections)

# 协调者节点 - 制定计划
def orchestrator(state: State):
    """协调者:分析任务并制定执行计划"""
    report_sections = planner.invoke(
        f"为主题'{state['topic']}'制定报告大纲,包含3个章节"
    )
    return {"sections": report_sections.sections}

# 工作者节点 - 执行具体任务
def llm_call(state: State):
    """工作者:根据分配的任务生成内容"""
    section = state["section"]  # 从协调者接收的任务
    result = model.invoke(
        f"编写报告章节:{section.name},内容要求:{section.description}"
    )
    return {"completed_sections": [result.content]}  # 结果会自动合并

# 汇总节点
def synthesizer(state: State):
    """汇总所有工作者的成果"""
    completed_sections = state["completed_sections"]
    final_report = "\n---\n\n".join(completed_sections)
    return {"final_report": final_report}

# 构建工作流
builder = StateGraph(State)

builder.add_node("orchestrator", orchestrator)
builder.add_node("llm_call", llm_call)
builder.add_node("synthesizer", synthesizer)

builder.add_edge(START, "orchestrator")


# 任务分配函数 - 关键部分!
def assign_workers(state: State):
    """为每个任务创建工作者的"""
    # 为每个章节创建一个工作者任务
    worker_tasks = []
    for section in state["sections"]:
        worker_tasks.append(
            Send("llm_call", {"section": section})  # 发送任务给工作者
        )
    return worker_tasks

# 关键:协调者后创建多个工作者, 对于条件边来说
# 可以接受固定节点以外, 还可以接受Send对象
builder.add_conditional_edges(
    "orchestrator",
    assign_workers,
    ["llm_call"]  # 创建的工作者都指向llm_call节点
)

# 所有工作者完成后汇总
builder.add_edge("llm_call", "synthesizer")
builder.add_edge("synthesizer", END)

worker = builder.compile()

response = worker.invoke({"topic": "中国近代史"})
print(response)
5.评估器-优化器模式(Evaluator-optimizer)
先进行内容生成, 再进行评估质量, 如果需要改进就重新生成, 直到满足质量
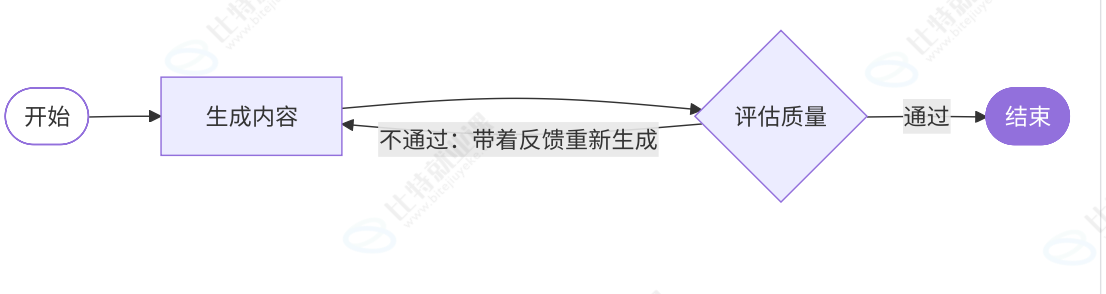
此处已经在上一篇中实现过了