文章目录
- 前言
- 一、序列式容器和关联式容器的区别
- [二、set 类](#二、set 类)
- 三、map类
-
- [1、先认识 pair](#1、先认识 pair)
- 2、再认识map
- 3、构造和遍历
- 4、常用接口
-
- [插入 insert](#插入 insert)
- [查找 find](#查找 find)
- [删除 erase](#删除 erase)
- [5、重点:operator \[\]](#5、重点:operator [])
- 6、实战:统计水果出现次数
- [7、multimap:允许重复 key 的 map](#7、multimap:允许重复 key 的 map)
- 8、map的实战小例子
- 总结
前言
我们学的 string、vector、list 这些,都叫序列式容器------ 元素是按插入顺序线性排列的,两个元素换个位置也还是那个容器。
而 map 和 set,属于另一大类:关联式容器。它们不是按插入顺序存的,而是按 key(关键字)有序组织的,底层是平衡二叉搜索树(红黑树),增删查都是 O (logN) 的效率,非常适合需要快速查找的场景。
一、序列式容器和关联式容器的区别
- 序列式容器:看重位置,元素和位置有强相关,比如 vector 按下标访问,list 按位置插入。
- 关联式容器:看重关键字(key),元素与 key 有强相关,按 key 来查找,和插入顺序没有关系。
STL里的关联式容器主要分两族:
- set 族:set、multiset ------ 纯 key 模型,只存关键字
- map 族:map、multimap ------ key-value 模型,存键值对
它们底层都是红黑树(一种平衡二叉搜索树),所以遍历出来默认都是升序的,增删查效率都是 O (logN)。
二、set 类
1、set 的特点
- 自动去重:相同的关键字 key 插不进去;
- 自动排序:默认升序,因为底层二叉搜索树中序遍历就是升序;
- 不允许修改关键字 key:改了 key 就破坏了搜索树的结构,所以迭代器都是 const 的,不能通过迭代器修改值
头文件
#include <set>
示例代码:
cpp
#include <iostream>
#include <set>		// set类的头文件
using namespace std;

int main()
{
	set<int> s;
	s.insert(3);
	s.insert(5);
	s.insert(1);
	s.insert(2);
	s.insert(3);	// 重复值,插入失败

	for (auto& d : s)
	{
		cout << d << " ";	// 1 2 3 5
	}
	cout << endl;
	return 0;
}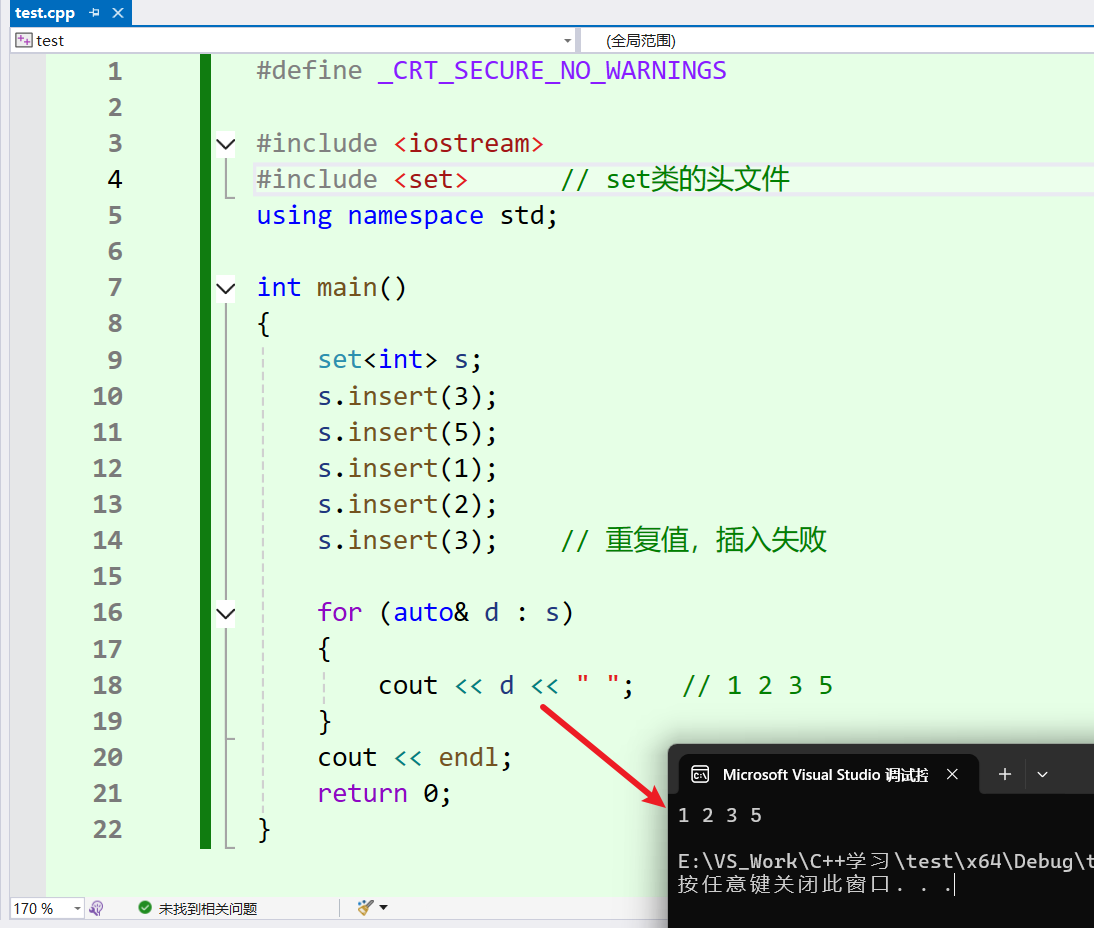
可以看到,插入顺序是 3 5 1 2 3,打印出来是 1 2 3 5 ------自动去重+自动排序。
2、构造和迭代器
set 的构造和其他容器差不多,常用的有:
- 无参构造
- 拷贝构造
- 迭代器区间构造(迭代器是双向迭代器,支持正向反向遍历)
- 初始化列表构造
构造代码:
cpp
#include <iostream>
#include <set>
using namespace std;

int main()
{
	//1. 无参构造:空set
	set<int> s1;

	//2. 初始化列表构造,自动去重排序
	set<int> s2 = { 4, 2, 7, 2, 8, 5, 9 };
	//s2实际存放:2 4 5 7 8 9

	//3. 迭代器区间构造:把别的容器一段区间拷贝过来
	int arr[] = { 10,20,30 };
	set<int> s3(arr, arr + 3);

	//4. 拷贝构造
	set<int> s4(s2);

	return 0;
}
迭代器遍历代码:
cpp
#include <iostream>
#include <set>
using namespace std;

int main()
{
    set<int> s = { 4, 2, 7, 2, 8, 5, 9 };

    //正向遍历:begin()第一个元素,end()是最后一个元素下一位
    for (auto it = s.begin(); it != s.end(); ++it)
    {
        cout << *it << " ";
    }
    //输出:2 4 5 7 8 9

    cout << endl;

    //反向遍历:rbegin()最后一个元素,rend()第一个元素前一位
    for (auto it = s.rbegin(); it != s.rend(); ++it)
    {
        cout << *it << " ";
    }
    //输出:9 8 7 5 4 2

	return 0;
}
反向迭代器
rbegin/rend,虽然写++it,实际是向前走。
注意:set 的迭代器指向的是 const 的 value,不能通过迭代器修改值。*it = 1;这种写法编译报错。
由于底层是平衡二叉搜索树,所以遍历其实是中序遍历这个平衡二叉搜索树。
3、常用接口
插入 insert
cpp
#include <iostream>
#include <set>
using namespace std;

int main()
{
	set<int> s;

	// 直接单个插入,返回值是pair<迭代器, bool>
	// first指向插入的位置,second表示是否插入成功
	pair<set<int>::iterator, bool> ret = s.insert(1);
	if (ret.second)
		cout << "插入成功" << endl;

	// 初始化列表插入
	s.insert({ 2,3,4 });

	// 迭代器区间插入
	int arr[] = { 6, 7, 8 };
	s.insert(arr, arr + 3);

	// 遍历
	for (auto& d : s)
	{
		cout << d << " ";
	}
	cout << endl;
	return 0;
}
insert 的返回值是pair<迭代器, bool>:
- first:指向 key 对应的结点(不管插入成功失败,都指向这个 key)
- second:true 插入成功,false 插入失败
查找 find
cpp
#include <iostream>
#include <set>
using namespace std;

int main()
{
	set<int> s;
	s.insert({ 1,2,3,4,6,7,8 });

	auto pos = s.find(5);
	if (pos != s.end())
		cout << "找到了:" << *pos << endl;
	else
		cout << "不存在" << endl;

	return 0;
}
别用算法库algorithm的
find,那个是 O (N) 遍历。set 自己的find是 O (logN)。
删除 erase
cpp
#include <iostream>
#include <set>
using namespace std;

int main()
{
	set<int> s;
	s.insert({ 1,2,3,4,6,7,8 });

	// 按迭代器删
	s.erase(s.begin());		// 删除 1

	// 按值删,返回删除的个数(set里要么0要么1)
	int num = s.erase(5);	// 删除 5
	if (num == 0)
	{
		cout << "没有该元素" << endl;
	}

	// 按区间删
	s.erase(s.begin(), s.end());// 全部删除

	return 0;
}
计数 count
cpp
#include <iostream>
#include <set>
using namespace std;

int main()
{
	set<int> s;
	s.insert({ 1,2,3,4,6,7,8 });

	int x = 0;
	cin >> x;
	if (s.count(x))
		cout << x << "存在" << endl;
	else cout << x << "不存在" << endl;

	return 0;
}
set 是自动去重的,所以 count 只能是 0 或 1,用来判断存在不存在很方便。
上下界 lower_bound /upper_bound
cpp
#include <iostream>
#include <set>
using namespace std;

int main()
{
	set<int> s = { 10, 20, 30, 40, 50 };

	auto itlow = s.lower_bound(30); // 返回 >=30的第一个迭代器位置 → 30
	auto itup = s.upper_bound(30);  // 返回 >30的第一个迭代器位置 → 40

	// 可以用来删一段区间
	s.erase(itlow, itup);

	return 0;
}
4、multiset:允许重复的 set
multiset 和 set 用法几乎一模一样,区别就是:允许 key 重复 。
区别:
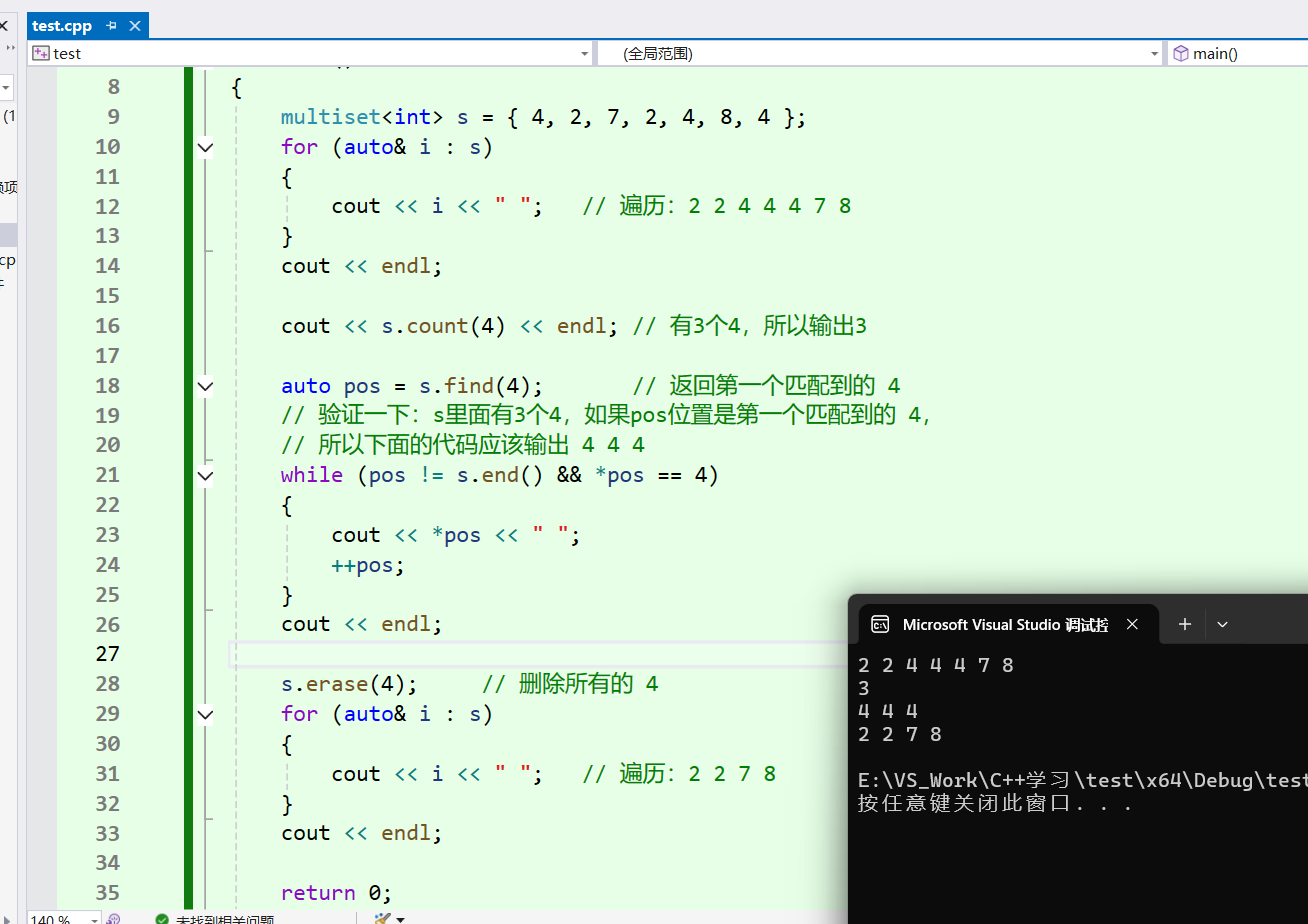
insert:总能插成功,因为允许重复find:返回中序遍历第一个匹配的迭代器count:返回实际有多少个erase(值):删除所有等于这个值的元素
cpp
#include <iostream>
#include <set>		// multiset的头文件
using namespace std;

int main()
{
    multiset<int> s = { 4, 2, 7, 2, 4, 8, 4 };
    for (auto& i : s)
    {
        cout << i << " ";   // 遍历:2 2 4 4 4 7 8
    }
    cout << endl;

    cout << s.count(4) << endl; // 有3个4,所以输出3

    auto pos = s.find(4);       // 返回第一个匹配到的 4
    // 验证一下:s里面有3个4,如果pos位置是第一个匹配到的 4,
    // 所以下面的代码应该输出 4 4 4
    while (pos != s.end() && *pos == 4)
    {
        cout << *pos << " ";
        ++pos;
    }
    cout << endl;

    s.erase(4);     // 删除所有的 4
    for (auto& i : s)
    {
        cout << i << " ";   // 遍历:2 2 7 8
    }
    cout << endl;

	return 0;
}
5、set 的实战小例子
例 1:两个数组的交集
cpp
class Solution {
public:
    vector<int> intersection(vector<int>& nums1, vector<int>& nums2) {
        set<int> ms1(nums1.begin(), nums1.end());
        set<int> ms2(nums2.begin(), nums2.end());

        auto pos1 = ms1.begin();
        auto pos2 = ms2.begin();
        vector<int> ret;

        while (pos1 != ms1.end() && pos2 != ms2.end()) {
            if (*pos1 == *pos2) {
                ret.push_back(*pos1);
                pos1++;
                pos2++;
            } else if (*pos1 < *pos2) {
                pos1++;
            } else
                pos2++;
        }
        return ret;
    }
};
例 2:判断链表有环
cpp
class Solution {
public:
    ListNode* detectCycle(ListNode* head) {
        ListNode* cur = head;
        set<ListNode*> ms;
        while(cur)
        {
            if(ms.count(cur))	// ms.count(cur)为1,说明之前有该结点了
            {
                return cur;
            }
            ms.insert(cur);
            cur = cur->next;
        }
        return nullptr;
    }
};
三、map类
1、先认识 pair
pair 是 C++ 标准库提供的模板结构体 ,作用:一次性打包两个不同(或相同)类型的数据,当成一个整体变量。
first:存放打包的第一个数据second:存放打包的第二个数据
头文件:
#include <utility>
cpp
#include <iostream>
#include <utility>
#include <string>
using namespace std;

int main()
{
    // 写法1:直接构造pair对象
    pair<string, string> kv1("apple", "苹果");
    cout << kv1.first << " : " << kv1.second << endl;

    // 写法2:make_pair自动推导类型(更简洁)
    auto kv2 = make_pair("banana", "香蕉");
    cout << kv2.first << " : " << kv2.second << endl;

	return 0;
}
pair本身不会自动排序,它就只是个 "装两个东西的小包"。
2、再认识map
map 里面每一个元素,本质就是一个 pair<Key, Value>
- pair.first → key 键
- pair.second → value 值
头文件
#include <map>
map特点:
- key 唯一,不能重复
插入相同 key,不会新增元素,只会覆盖原来的 value。 - 容器内部自动按照 key 升序排序 (默认
<比较) - 和set一样,查找、插入、删除时间复杂度 (O(logn))
- 可以通过
[key]快速访问 / 修改 value,像字典一样。
3、构造和遍历
cpp
#include <iostream>
#include <map>
#include <string>
using namespace std;

int main()
{
    // 初始化列表构造
    map<string, string> dict = {
        {"left", "左边"},
        {"right", "右边"},
        {"insert", "插入"}
    };

    // 迭代器遍历
    auto it = dict.begin();
    while (it != dict.end())
    {
        // it->first 是key,it->second 是value
        cout << it->first << ":" << it->second << endl;
        ++it;
    }

    // 范围for遍历
    for (const auto& e : dict)
        cout << e.first << ":" << e.second << endl;

    return 0;
}
遍历出来默认按 key 升序排列。
注意:map 里 key 是 const 的,不能改;value 可以改。想改 value 通过迭代器改
it->second = xxx就行。
4、常用接口
插入 insert
插入的是 pair 键值对:
cpp
#include <iostream>
#include <map>
#include <string>
using namespace std;

int main()
{
    map<string, string> dict;

    // insert插入pair对象有4种方法。与其他方法相比,最后一种方法最为方便
    pair<string, string> kv1("first", "第一个");
    dict.insert(kv1);
    dict.insert(pair<string, string>("second", "第二个"));
    dict.insert(make_pair("sort", "排序"));
    dict.insert({ "auto", "自动的" });

    // key已经存在的话,插入失败,second返回false
    auto ret = dict.insert({ "left", "左边剩余" });
    if (ret.second == false)
        cout << "left已经存在,插入失败" << endl;

    return 0;
}
insert 的返回值是pair<迭代器, bool>:
- first:指向 key 对应的结点(不管插入成功失败,都指向这个 key)
- second:true 插入成功,false 插入失败
查找 find
cpp
#include <iostream>
#include <map>
#include <string>
using namespace std;

int main()
{
    map<string, string> dict;

    // insert插入pair对象有4种方法。与其他方法相比,最后一种方法最为方便
    pair<string, string> kv1("first", "第一个");
    dict.insert(kv1);
    dict.insert(pair<string, string>("second", "第二个"));
    dict.insert(make_pair("sort", "排序"));
    dict.insert({ "auto", "自动的" });

    auto pos = dict.find("left");
    if (pos != dict.end())
        cout << "->" << pos->second << endl;
    else
        cout << "没找到" << endl;

    return 0;
}
删除 erase
和 set 差不多:
cpp
#include <iostream>
#include <map>
#include <string>
using namespace std;

int main()
{
    map<string, string> dict;

    // insert插入pair对象有4种方法。与其他方法相比,最后一种方法最为方便
    pair<string, string> kv1("first", "第一个");
    dict.insert(kv1);
    dict.insert(pair<string, string>("second", "第二个"));
    dict.insert(make_pair("sort", "排序"));
    dict.insert({ "auto", "自动的" });

    dict.erase(dict.begin());               // 按迭代器删
    dict.erase("sort");                     // 按key删,返回删除个数
    dict.erase(dict.begin(), dict.end());   // 按区间删

    return 0;
}
5、重点:operator \[\]
map 的[]运算符非常强大,查找、插入、修改都能干,是最常用的接口。
cpp
#include <iostream>
#include <map>
#include <string>
using namespace std;

int main()
{
    map<string, int> countMap;

    // 1. key不存在 → 插入key和默认值(int默认0),返回value的引用
    countMap["苹果"]++;
    cout << countMap["苹果"] << endl;     // 1

    // 2. key存在 → 返回value的引用,可以直接修改
    countMap["苹果"] = 5;

    // 3. key存在 → 查找value
    cout << countMap["苹果"] << endl;     // 5

    return 0;
}
\[\] 的底层原理:
\[\] 内部其实就是用 insert 实现的:
- 尝试插入
<key, value默认值> - 如果 key 不存在,插入成功,返回新插入 value 的引用
- 如果 key 存在,插入失败,返回已有 value 的引用
所以 \[\] 有个小特点:只要你用 \[\] 访问了一个不存在的 key,它就自动给你插进去了 。如果只是想判断存在不存在,用find或者count,别乱用 \[\],不然平白无故插入数据。
6、实战:统计水果出现次数
用 \[\] 写统计次数特别简洁:
cpp
#include<iostream>
#include<map>
#include<string>
using namespace std;
int main()
{
	string arr[] = { "苹果","西瓜","香蕉","草莓","香蕉","西瓜","香蕉","苹果","西瓜","苹果" };
	map<string, int> count;
	for (const string& str : arr) {
		// 方法一:利用find和iterator修改功能,统计水果出现的次数
		// 先查找水果是否在map中
		// 1.不在,说明水果第一次出现,则插入{水果,1}
		// 2.在,则查找到的节点中水果对应的次数++
		/*auto it = count.find(str);
		if (it != count.end()) {
			it->second++;
		}
		else {
			count.insert({ str, 1 });
		}*/

		// 方法二:利用operator[]的特性实现,更简洁
		count[str]++;
	}

	for (const auto& e : count) {
		cout << e.first << ":" << e.second << endl;
	}
	cout << endl;

	return 0;
}
7、multimap:允许重复 key 的 map
multimap 和 map 用法类似,区别是允许 key 重复。
区别:
- 不支持
operator[]------key 重复的话,\[\] 该返回哪个的 value?说不清楚,所以干脆不支持 find返回中序遍历第一个匹配的迭代器count返回 key 的个数erase(值)删除所有该 key 的元素
cpp
#include<iostream>
#include<map>
#include<string>
using namespace std;
int main()
{
	multimap<string, int> mm;
	mm.insert({ "苹果", 5 });
	mm.insert({ "苹果", 3 });
	mm.insert({ "苹果", 4 });
	mm.insert({ "香蕉", 2 });


	// 遍历
	for (auto& i : mm)
	{
		cout << i.first << " : " << i.second << endl;
	}

	cout << mm.count("苹果") << endl; // 3

	auto pos = mm.find("苹果");
	while (pos != mm.end() && pos->first == "苹果")
	{
		cout << pos->second << " ";
		++pos;
	}
	cout << endl;

	// 删除所有"苹果"
	mm.erase("苹果");
	// 遍历,由于删除了"苹果",所以只有"香蕉"
	for (auto& i : mm)
	{
		cout << i.first << " : " << i.second << endl;
	}

	return 0;
}
8、map的实战小例子
cpp
class Solution {
public:
    Node* copyRandomList(Node* head) {
        map<Node*,Node*> nodeMap;
        Node* copyhead = nullptr,* copycur = nullptr;
        Node* cur = head;
        while(cur)
        {
            if(copyhead == nullptr)
            {
                copycur = copyhead = new Node(cur->val);
            }
            else
            {
                copycur->next = new Node(cur->val);
                copycur = copycur->next;
            }
            // 建立<cur,copycur>的关系
            nodeMap[cur] = copycur;
            cur = cur->next;
        }

        // random
        cur = head;
        copycur = copyhead;
        while(cur)
        {
            if(cur->random)
            {
                copycur->random = nodeMap[cur->random];
            }
            else
            {
                copycur->random = nullptr;
            }
            cur = cur->next;
            copycur = copycur->next;
        }
        return copyhead;
    }
};
总结
map 和 set 是 STL 里非常实用的容器,它们的核心价值就是有序 + O (logN) 的增删查,适合需要快速查找、需要有序的场景。
如果这篇对你有帮助,点个赞收藏一下,后续持续更新 C++ 和 STL 系列~