一、环境配置
git clone https://github.com/SparkAudio/Spark-TTS.git

pip install -r requirements.txt
二、模型下载
从modelscope进行下载,pip install modelscope
import torch

from modelscope import snapshot_download

snapshot_download("SparkAudio/Spark-TTS-0.5B", local_dir="SparkAudio/Spark-TTS-0.5B")
执行python download.py进行下载。
三、使用
在example文件夹下能够看到infer脚本文件,
#!/bin/bash

# Copyright (c) 2025 SparkAudio
#               2025 Xinsheng Wang (w.xinshawn@gmail.com)
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
#   http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable law or agreed to in writing, software
# distributed under the License is distributed on an "AS IS" BASIS,
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
# See the License for the specific language governing permissions and
# limitations under the License.


# Get the absolute path of the script's directory
script_dir=$(dirname "$(realpath "$0")")

# Get the root directory
root_dir=$(dirname "$script_dir")

# Set default parameters
device=0
save_dir='example/results'
model_dir="pretrained_models/Spark-TTS-0.5B"
text="身临其境,换新体验。塑造开源语音合成新范式,让智能语音更自然。"
prompt_text="吃燕窝就选燕之屋,本节目由26年专注高品质燕窝的燕之屋冠名播出。豆奶牛奶换着喝,营养更均衡,本节目由豆本豆豆奶特约播出。"
prompt_speech_path="example/prompt_audio.wav"

# Change directory to the root directory
cd "$root_dir" || exit

source sparktts/utils/parse_options.sh

# Run inference
python -m cli.inference \
    --text "${text}" \
    --device "${device}" \
    --save_dir "${save_dir}" \
    --model_dir "${model_dir}" \
    --prompt_text "${prompt_text}" \
    --prompt_speech_path "${prompt_speech_path}"
运行
bash infer.sh能够成功合成语音,参数所表示的意思对应如下:
text 需要克隆语音所对应的文本
device 指定显卡编号
save_dir 克隆语音的保存路径
model_dir 大模型的保存路径
prompt_text 样本语音的文本信息
prompt_speech_path 样本语音的保存路径
python -m cli.inference \
    --text "你好" \
    --device 0 \
    --save_dir "result" \
    --model_dir pretrained_models/Spark-TTS-0.5B \
    --prompt_text "吃燕窝就选燕之屋,本节目由26年专注高品质燕窝的燕之屋冠名播出。豆奶牛奶换着喝,营养更均衡,本节目由豆本豆豆奶特约播出。" \
    --prompt_speech_path "example/prompt_audio.wav"
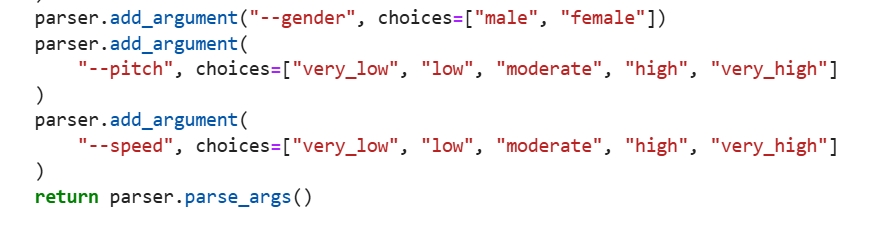
如果想要改变声音的性别,音调,速度,可以在infer.sh中看到对于这些参数的说明,但是这几个参数要一起加才能用,否则会报错