1.需求分析
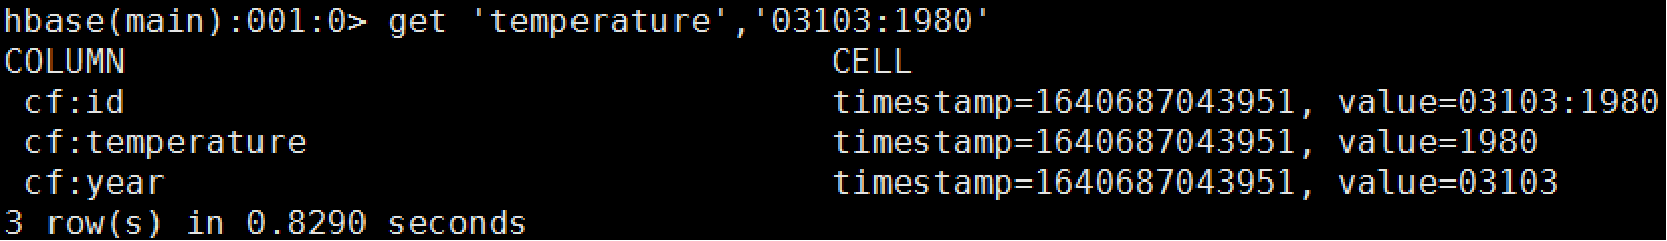
我们仍然以美国各个气象站每年的气温数据集为例,现在要求使用MapReduce读取该数据集,然后批量写入HBase数据库,最后利用HBase shell根据行键即席查询气温数据。
2.数据集准备
数据集的文件名为temperature.log,里面包含美国各个气象站每年的气温数据,数据的第一列为气象站ID,第二列为年份,第三列为气温值。具体样本数据如下所示: 03103,1980,41 03103,1981,98 03103,1982,70 03103,1983,74 03103,1984,77
3.代码实现
Mapper:
public static class MyMapper extends Mapper<LongWritable, Text,LongWritable,Text>{
	private Text word = new Text();
	@Override
	protected void map(LongWritable key, Text value, Context context) throws IOException, InterruptedException {
		//解析每条气温记录
		String[] records = value.toString().split(",");
		int length = records.length;
		if(length==3){
			//设置HBase行键rowKey
			String rowKey = records[0]+":"+records[1];
			word.set(rowKey+","+value.toString());
			context.write(key,word);
		}
	}}
Reducer:
public static class MyReducer extends TableReducer<LongWritable,Text, ImmutableBytesWritable>{
@Override
protected void reduce(LongWritable key, Iterable<Text> values, Context context) throws IOException, InterruptedException {
for(Text value:values){
String[] splits = value.toString().split(",");
String rowKey=splits[0];
//获取第一列作为RowKey
Put put =new Put(Bytes.toBytes(splits[0]));
//获取其他列作为HBase列簇中的字段
put.addColumn(Bytes.toBytes("cf"), Bytes.toBytes("id"), Bytes.toBytes(splits[0]));
put.addColumn(Bytes.toBytes("cf"), Bytes.toBytes("year"), Bytes.toBytes(splits[1]));
put.addColumn(Bytes.toBytes("cf"),Bytes.toBytes("temperature"), Bytes.toBytes(splits[2]));
ImmutableBytesWritable keys = new ImmutableBytesWritable(rowKey.getBytes());
context.write(keys,put);
}
}}
Main:
public static void main(String[] args) throws IOException, InterruptedException, ClassNotFoundException {
//设置HBase配置连接
Configuration conf= HBaseConfiguration.create();
conf.set("hbase.zookeeper.quorum", "hadoop1,hadoop2,hadoop3");
conf.set("hbase.zookeeper.property.clientPort", "2181");
Job job = new Job(conf, "BatchImportHBase");
job.setJobName("BatchImportHBase");
job.setJarByClass(BatchImportHBase.class);
job.setMapperClass(MyMapper.class);
//执行reducer类写入HBase
TableMapReduceUtil.initTableReducerJob("temperature", MyReducer.class, job, null, null, null, null, false);
job.setMapOutputKeyClass(LongWritable.class);
job.setMapOutputValueClass(Text.class);
job.setOutputKeyClass(ImmutableBytesWritable.class);
job.setOutputValueClass(Put.class);
FileInputFormat.setInputPaths(job, new Path(args[0]));
job.waitForCompletion(true) ;
}
4.测试运行
-
创建HBase表 hbase(main):002:0> create 'temperature','cf'
-
提交MapReduce作业
-
根据Rowkey查询气温数据