前言
这是 最近有一个 来自于朋友的 pyflink 的使用需求
然后 看到了 很多 pyflink 这边的和 使用 java, scala 的 api 使用上的很多差异
这里使用的 pyflink 版本是 1.16.3
也碰到了很多问题
首先需要 python 这边安装 apache-flink 1.16.3, 这个一般是通过 pip 安装
其次 本地需要有 安装 flink 1.16.3
测试用例如下
这里是做一个简单的从 csv 加载数据
然后 做一些 简单的转换, 然后持久化到了 目标文件处理方式不好, 仅仅是为了实现效果
当然 这里也是使用的 StreamExecutionEnvironment, 也仅仅是这里测试使用
和批处理一些较大的差异, 这里不细说, 也不是 这里的主题
from pyflink.table import (EnvironmentSettings, TableEnvironment, StreamTableEnvironment, Row,
                           DataTypes, CsvTableSource, CsvTableSink, WriteMode)
from pyflink.datastream.functions import ReduceFunction
from pyflink.datastream.connectors.file_system import StreamFormat, FileSource, FileSink
from pyflink.datastream.formats.csv import CsvReaderFormat, CsvBulkWriters, CsvSchema
from pyflink.datastream import StreamExecutionEnvironment, RuntimeExecutionMode
from pyflink.common import WatermarkStrategy
from pyflink.common.typeinfo import Types
from pyflink.common import Row
from pyflink.table import (EnvironmentSettings, TableEnvironment, TableDescriptor, Schema,
                           DataTypes, FormatDescriptor)
from pyflink.table.expressions import lit, col
from pyflink.table.udf import udtf
from pyflink.datastream.functions import AggregateFunction, SinkFunction
from pyflink.datastream import MapFunction, FilterFunction
from pyflink.datastream import KeySelector

import csv
import tempfile


env = StreamExecutionEnvironment.get_execution_environment()
t_env = StreamTableEnvironment.create(env)
t_env.get_config().set("parallelism.default", "1")
schema = CsvSchema.builder() \
    .add_string_column('country') \
    .add_number_column('year', number_type=DataTypes.INT()) \
    .add_string_column('sex') \
    .set_column_separator(',') \
    .set_use_header() \
    .build()
# source
CSV_FILE_PATH = '/Users/jerry/Tmp/17_pyspark_csv/suicide_clear_3fields.csv'
source = FileSource.for_record_stream_format(CsvReaderFormat.for_schema(schema), CSV_FILE_PATH).build()
ds = env.from_source(source, WatermarkStrategy.no_watermarks(), 'csv-source')


# transformation
class Person:
    def __init__(self, country, year, sex):
        self.country = country
        self.year = year
        self.sex = sex
        self.count = 1
    def __str__(self):
        return f"_Person_{self.country}, {self.year}, {self.sex}, {self.count}"

class MapToPerson(MapFunction):
    def map(self, value:Row):
        return Person(value.country, value.year, value.sex)

class FilterYearFunction(FilterFunction):
    def filter(self, value:Person):
        return value.year == 1987

mappedStream = ds.map(MapToPerson()).filter(FilterYearFunction())


# sink
class Person2CsvString(MapFunction):
    def __init__(self, outputPath):
        self.outputPath = outputPath

    def map(self, value:Person):
        csvString = f"{value.country},{value.year},{value.sex},{value.count}"
        with open(outputPath, mode='a', newline='', encoding='utf-8') as csvfile:
            writer = csv.writer(csvfile)
            writer.writerow([value.country, value.year, value.sex])
        return csvString


outputPath = "/Users/jerry/Tmp/17_pyspark_csv/output.csv"
mappedStream.map(Person2CsvString(outputPath)).print()
env.execute("CSV Read Job")
如果本地没有安装 $FLINK_HOME
会报错如下, 安装一下 flink 1.16.3, 配置一下 FLINK_HOME 就好了
然后 环境变量更新, 需要重启 pycharm 生效
Traceback (most recent call last):
  File "/Applications/PyCharm.app/Contents/helpers/pydev/pydevd.py", line 1758, in <module>
    main()
  File "/Applications/PyCharm.app/Contents/helpers/pydev/pydevd.py", line 1752, in main
    globals = debugger.run(setup['file'], None, None, is_module)
  File "/Applications/PyCharm.app/Contents/helpers/pydev/pydevd.py", line 1147, in run
    pydev_imports.execfile(file, globals, locals)  # execute the script
  File "/Applications/PyCharm.app/Contents/helpers/pydev/_pydev_imps/_pydev_execfile.py", line 18, in execfile
    exec(compile(contents+"\n", file, 'exec'), glob, loc)
  File "/Users/jerry/IdeaProjects/PartTimeJobs/20240525_HelloPyFlink/Test01FlinkReadCsvThenMapBean.py", line 22, in <module>
    env = StreamExecutionEnvironment.get_execution_environment()
  File "/Library/Frameworks/Python.framework/Versions/3.6/lib/python3.6/site-packages/pyflink/datastream/stream_execution_environment.py", line 827, in get_execution_environment
    gateway = get_gateway()
  File "/Library/Frameworks/Python.framework/Versions/3.6/lib/python3.6/site-packages/pyflink/java_gateway.py", line 64, in get_gateway
    _gateway = launch_gateway()
  File "/Library/Frameworks/Python.framework/Versions/3.6/lib/python3.6/site-packages/pyflink/java_gateway.py", line 119, in launch_gateway
    + stderr_info
RuntimeError: Java gateway process exited before sending its port number.
Stderr:
Error: Could not find or load main class org.apache.flink.client.python.PythonGatewayServer
如果 pyflink 版本 和 本地 flink 版本不对
可能会 报错如下, 这是 版本之间的一下差异 造成的
比如我这里本地 flink 版本是 1.13.6, pyflink 版本是 1.16.3
Traceback (most recent call last):
  File "/Applications/PyCharm.app/Contents/helpers/pydev/pydevd.py", line 1758, in <module>
    main()
  File "/Applications/PyCharm.app/Contents/helpers/pydev/pydevd.py", line 1752, in main
    globals = debugger.run(setup['file'], None, None, is_module)
  File "/Applications/PyCharm.app/Contents/helpers/pydev/pydevd.py", line 1147, in run
    pydev_imports.execfile(file, globals, locals)  # execute the script
  File "/Applications/PyCharm.app/Contents/helpers/pydev/_pydev_imps/_pydev_execfile.py", line 18, in execfile
    exec(compile(contents+"\n", file, 'exec'), glob, loc)
  File "/Users/jerry/IdeaProjects/PartTimeJobs/20240525_HelloPyFlink/Test01FlinkReadCsvThenMapBean.py", line 23, in <module>
    t_env = StreamTableEnvironment.create(env)
  File "/Library/Frameworks/Python.framework/Versions/3.6/lib/python3.6/site-packages/pyflink/table/table_environment.py", line 1706, in create
    return StreamTableEnvironment(j_tenv)
  File "/Library/Frameworks/Python.framework/Versions/3.6/lib/python3.6/site-packages/pyflink/table/table_environment.py", line 1653, in __init__
    super(StreamTableEnvironment, self).__init__(j_tenv)
  File "/Library/Frameworks/Python.framework/Versions/3.6/lib/python3.6/site-packages/pyflink/table/table_environment.py", line 99, in __init__
    self._config_chaining_optimization()
  File "/Library/Frameworks/Python.framework/Versions/3.6/lib/python3.6/site-packages/pyflink/table/table_environment.py", line 1623, in _config_chaining_optimization
    JChainingOptimizingExecutor(exec_env_field.get(self._j_tenv)))
  File "/Library/Frameworks/Python.framework/Versions/3.6/lib/python3.6/site-packages/pyflink/util/exceptions.py", line 187, in wrapped_call
    "command line argument '--jarfile' or the config option 'pipeline.jars'" % self._fqn)
TypeError: Could not found the Java class 'org.apache.flink.table.executor.python.ChainingOptimizingExecutor'. The Java dependencies could be specified via command line argument '--jarfile' or the config option 'pipeline.jars'
python2.7.x 和 python3.6.x 共存的情况
pycharm 在项目中使用的是 python 3.6.x
而外部命令行中环境变量中 python 指向的版本是 python 2.7.x
然后 执行 pyflink 相关操作的时候 可能需要借助外部命令行执行 python 命令
可能执行会报错 "No module named pyflink"
master:ProgramFiles jerry$ python -c "import pyflink;import os;print(os.path.dirname(os.path.abspath(pyflink.__file__))+'/lib')"
Traceback (most recent call last):
  File "<string>", line 1, in <module>
ImportError: No module named pyflink
然后 将外部命令行环境的 python 更新到 python 3.6.x 就行
master:bin jerry$ python -c "import pyflink;import os;print(os.path.dirname(os.path.abspath(pyflink.__file__))+'/lib')"
/Library/Frameworks/Python.framework/Versions/3.6/lib/python3.6/site-packages/pyflink/lib
效果截图
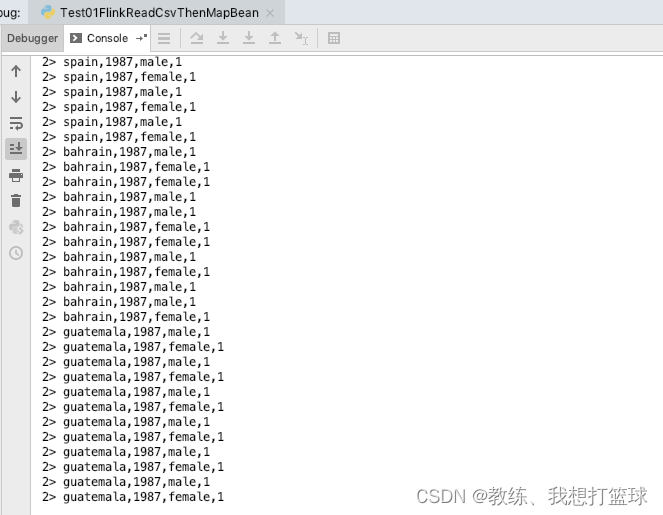
最终所有问题解决之后, 执行程序 效果如下
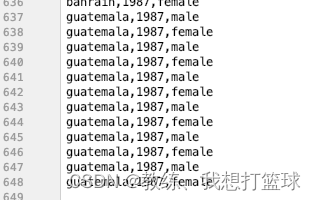
输出文件内容如下
完