首先搭建环境(略)并下载好huggingface的Qwen2-VL-2B-Instruct模型。
测试代码:
python
'''
Author: taifyang
Date: 2026-04-09 16:54:52
LastEditTime: 2026-05-12 16:47:14
Description:
'''
import argparse
import sys
from pathlib import Path

from PIL import Image
from transformers import AutoProcessor

from tensorrt_llm import LLM
from tensorrt_llm.sampling_params import SamplingParams


def load_image(image_path: str) -> Image.Image:
    path = Path(image_path)
    if not path.exists():
        raise FileNotFoundError(f"图片不存在: {image_path}")
    img = Image.open(path).convert("RGB")
    print(f"成功加载图片: {path.name},尺寸: {img.size}")
    return img


def main():
    parser = argparse.ArgumentParser()
    parser.add_argument("--model_path", type=str, default="/docker_share/TensorRT-LLM-1.2.0/Qwen2-VL-2B-Instruct")
    parser.add_argument("--image_path", type=str, default="/docker_share/TensorRT-LLM-1.2.0/bus.jpg")
    parser.add_argument("--prompt", type=str, default="图片中有什么?")
    parser.add_argument("--max_tokens", type=int, default=512)
    parser.add_argument("--temperature", type=float, default=0.5)
    args = parser.parse_args()

    # 1. 加载 processor(用于构建 prompt)
    processor = AutoProcessor.from_pretrained(args.model_path, trust_remote_code=True)
    print(f"成功加载 processor: {args.model_path}")

    # 2. 加载 TensorRT-LLM 模型
    print("正在加载 TensorRT-LLM 引擎...")
    llm = LLM(
        model=args.model_path,
        trust_remote_code=True,
        tokenizer=processor.tokenizer,
    )
    tokenizer = llm.tokenizer

    # 3. 加载原始图像
    image = load_image(args.image_path)

    # 4. 构建带视觉占位符的 prompt
    messages = [
        {
            "role": "user",
            "content": [
                {"type": "image"},
                {"type": "text", "text": args.prompt}
            ]
        }
    ]
    prompt_text = processor.apply_chat_template(
        messages,
        tokenize=False,
        add_generation_prompt=True
    )
    print(f"构造的 prompt (前200字符): {prompt_text[:200]}...")

    # 5. 构建输入:图像必须放在列表中
    inputs = [
        {
            "prompt": prompt_text,
            "multi_modal_data": {
                "image": [image]   # ← 关键修复:列表包裹
            }
        }
    ]

    # 6. 生成参数
    sampling_params = SamplingParams(
        max_tokens=args.max_tokens,
        temperature=args.temperature,
        top_p=0.9,
        stop_token_ids=[tokenizer.eos_token_id],
        stop=["<|im_end|>"],
    )

    # 7. 推理
    print("\n开始生成...")
    outputs = llm.generate(inputs, sampling_params=sampling_params)

    # 8. 输出结果
    print("\n===== 模型回答 =====")
    for output in outputs:
        print(output.outputs[0].text.strip())
    print("====================")


if __name__ == "__main__":
    main()
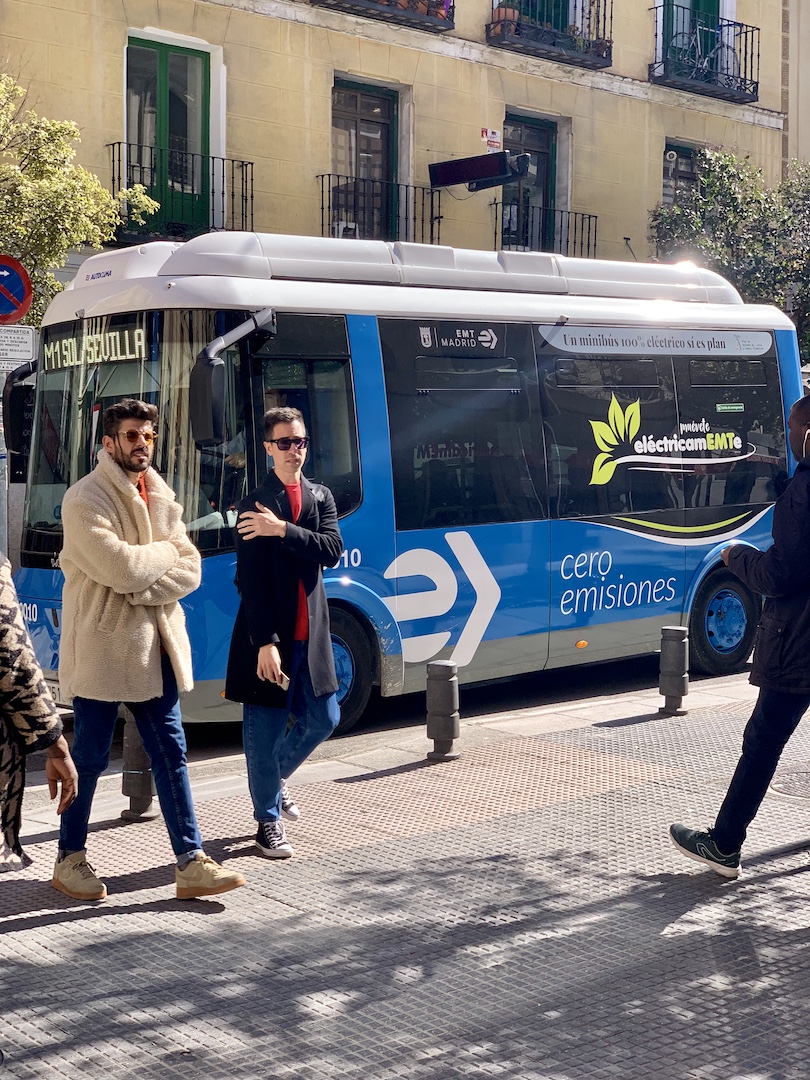
测试图片:
输出结果:
bash
/usr/local/lib/python3.12/dist-packages/torch/library.py:356: UserWarning: Warning only once for all operators,  other operators may also be overridden.
  Overriding a previously registered kernel for the same operator and the same dispatch key
  operator: flash_attn::_flash_attn_backward(Tensor dout, Tensor q, Tensor k, Tensor v, Tensor out, Tensor softmax_lse, Tensor(a6!)? dq, Tensor(a7!)? dk, Tensor(a8!)? dv, float dropout_p, float softmax_scale, bool causal, SymInt window_size_left, SymInt window_size_right, float softcap, Tensor? alibi_slopes, bool deterministic, Tensor? rng_state=None) -> Tensor
    registered at /usr/local/lib/python3.12/dist-packages/torch/_library/custom_ops.py:922
  dispatch key: ADInplaceOrView
  previous kernel: no debug info
       new kernel: registered at /usr/local/lib/python3.12/dist-packages/torch/_library/custom_ops.py:922 (Triggered internally at /opt/pytorch/pytorch/aten/src/ATen/core/dispatch/OperatorEntry.cpp:208.)
  self.m.impl(
/usr/local/lib/python3.12/dist-packages/modelopt/torch/__init__.py:36: UserWarning: transformers version 4.57.3 is incompatible with nvidia-modelopt and may cause issues. Please install recommended version with `pip install nvidia-modelopt[hf]` if working with HF models.
  _warnings.warn(
[TensorRT-LLM] TensorRT LLM version: 1.2.0
The image processor of type `Qwen2VLImageProcessor` is now loaded as a fast processor by default, even if the model checkpoint was saved with a slow processor. This is a breaking change and may produce slightly different outputs. To continue using the slow processor, instantiate this class with `use_fast=False`. Note that this behavior will be extended to all models in a future release.
成功加载 processor: /docker_share/TensorRT-LLM-1.2.0/Qwen2-VL-2B-Instruct
正在加载 TensorRT-LLM 引擎...
[05/12/2026-08:47:28] [TRT-LLM] [I] Using LLM with PyTorch backend
[05/12/2026-08:47:28] [TRT-LLM] [W] Using default gpus_per_node: 1
[05/12/2026-08:47:28] [TRT-LLM] [I] neither checkpoint_format nor checkpoint_loader were provided, checkpoint_format will be set to HF.
The argument `trust_remote_code` is to be used with Auto classes. It has no effect here and is ignored.
You are using a model of type qwen2_vl to instantiate a model of type . This is not supported for all configurations of models and can yield errors.
`torch_dtype` is deprecated! Use `dtype` instead!
rank 0 using MpiPoolSession to spawn MPI processes
/usr/local/lib/python3.12/dist-packages/torch/library.py:356: UserWarning: Warning only once for all operators,  other operators may also be overridden.
  Overriding a previously registered kernel for the same operator and the same dispatch key
  operator: flash_attn::_flash_attn_backward(Tensor dout, Tensor q, Tensor k, Tensor v, Tensor out, Tensor softmax_lse, Tensor(a6!)? dq, Tensor(a7!)? dk, Tensor(a8!)? dv, float dropout_p, float softmax_scale, bool causal, SymInt window_size_left, SymInt window_size_right, float softcap, Tensor? alibi_slopes, bool deterministic, Tensor? rng_state=None) -> Tensor
    registered at /usr/local/lib/python3.12/dist-packages/torch/_library/custom_ops.py:922
  dispatch key: ADInplaceOrView
  previous kernel: no debug info
       new kernel: registered at /usr/local/lib/python3.12/dist-packages/torch/_library/custom_ops.py:922 (Triggered internally at /opt/pytorch/pytorch/aten/src/ATen/core/dispatch/OperatorEntry.cpp:208.)
  self.m.impl(
Multiple distributions found for package optimum. Picked distribution: optimum
Multiple distributions found for package modelopt. Picked distribution: nvidia-modelopt
/usr/local/lib/python3.12/dist-packages/modelopt/torch/__init__.py:36: UserWarning: transformers version 4.57.3 is incompatible with nvidia-modelopt and may cause issues. Please install recommended version with `pip install nvidia-modelopt[hf]` if working with HF models.
  _warnings.warn(
[TensorRT-LLM] TensorRT LLM version: 1.2.0
[TensorRT-LLM][INFO] Refreshed the MPI local session
/usr/local/lib/python3.12/dist-packages/tensorrt_llm/serve/openai_protocol.py:104: UserWarning: Field name "schema" in "ResponseFormat" shadows an attribute in parent "OpenAIBaseModel"
  class ResponseFormat(OpenAIBaseModel):
`torch_dtype` is deprecated! Use `dtype` instead!
Loading safetensors weights in parallel: 100%|██████████| 1/1 [00:00<00:00,  1.63iLoading safetensors weights in parallel: 100%|██████████| 1/1 [00:00<00:00,  1.63it/s]
Loading weights concurrently: 100%|██████████| 568/568 [00:20<00:00, 28.29it/s]
Model init total -- 65.20s
[TensorRT-LLM][INFO] Max KV cache blocks per sequence: 1025 [window size=32769], tokens per block=32, primary blocks=2048, secondary blocks=0, max sequence length=32769
[TensorRT-LLM][INFO] Number of tokens per block: 32.
[TensorRT-LLM][INFO] [MemUsageChange] Allocated 1.75 GiB for max tokens in paged KV cache (65536).
[TensorRT-LLM][WARNING] Attention workspace size is not enough, increase the size from 0 bytes to 59335680 bytes
[TensorRT-LLM][WARNING] Attention workspace size is not enough, increase the size from 0 bytes to 42006528 bytes
[TensorRT-LLM][WARNING] [kv cache manager] storeContextBlocks: Can not find sequence for request 2048
[TensorRT-LLM][WARNING] [kv cache manager] storeContextBlocks: Can not find sequence for request 2052
[TensorRT-LLM][WARNING] [kv cache manager] storeContextBlocks: Can not find sequence for request 2049
[TensorRT-LLM][WARNING] [kv cache manager] storeContextBlocks: Can not find sequence for request 2050
[TensorRT-LLM][WARNING] [kv cache manager] storeContextBlocks: Can not find sequence for request 2051
[TensorRT-LLM][INFO] Max KV cache blocks per sequence: 1025 [window size=32769], tokens per block=32, primary blocks=5127, secondary blocks=0, max sequence length=32769
[TensorRT-LLM][INFO] Number of tokens per block: 32.
[TensorRT-LLM][INFO] [MemUsageChange] Allocated 4.38 GiB for max tokens in paged KV cache (164064).
[TensorRT-LLM][WARNING] Attention workspace size is not enough, increase the size from 0 bytes to 59335680 bytes
[TensorRT-LLM][WARNING] Attention workspace size is not enough, increase the size from 0 bytes to 42006528 bytes
成功加载图片: bus.jpg,尺寸: (810, 1080)
构造的 prompt (前200字符): <|im_start|>system
You are a helpful assistant.<|im_end|>
<|im_start|>user
<|vision_start|><|image_pad|><|vision_end|>图片中有什么?<|im_end|>
<|im_start|>assistant
...

开始生成...
/usr/local/lib/python3.12/dist-packages/torch/multiprocessing/reductions.py:598: UserWarning: TypedStorage is deprecated. It will be removed in the future and UntypedStorage will be the only storage class. This should only matter to you if you are using storages directly.  To access UntypedStorage directly, use tensor.untyped_storage() instead of tensor.storage()
  if storage.is_cuda:
huggingface/tokenizers: The current process just got forked, after parallelism has already been used. Disabling parallelism to avoid deadlocks...
To disable this warning, you can either:
        - Avoid using `tokenizers` before the fork if possible
        - Explicitly set the environment variable TOKENIZERS_PARALLELISM=(true | false)
Processed requests: 100%|███████████████████████████| 1/1 [00:00<00:00,  1.13it/s]

===== 模型回答 =====
图片中有一辆蓝色的电动公交车,上面有"cero emisiones"(零排放)的标志。公交车停在街道上,周围有行人。背景是一栋黄色的建筑,窗户上有绿色的栏杆。
====================
显存占用约10G。