Ultralytics:解读C2模块
- 前言
- 相关介绍
-
- [Ultralytics 简介](#Ultralytics 简介)
- 前提条件
- 实验环境
- [C2(CSP Bottleneck with 2 convolutions)](#C2(CSP Bottleneck with 2 convolutions))
- 参考文献
前言
- 由于本人水平有限,难免出现错漏,敬请批评改正。
- 更多精彩内容,可点击进入Python日常小操作专栏、OpenCV-Python小应用专栏、YOLO系列专栏、自然语言处理专栏、人工智能混合编程实践专栏或我的个人主页查看
- YOLOs-CPP:一个免费开源的YOLO全系列C++推理库(以YOLO26为例)
- PaddleOCR:Win10上安装使用PPOCRLabel标注工具
- 目标检测:使用自己的数据集微调DEIMv2进行物体检测
- 图像分割:PyTorch从零开始实现SegFormer语义分割
- 图像超分:使用自己的数据集微调Real-ESRGAN-x4plus进行超分重建
- 图像生成:PyTorch从零开始实现一个简单的扩散模型
- Stable Diffusion:使用自己的数据集微调 Stable Diffusion 3.5 LoRA 文生图模型
- 图像超分:使用自己的数据集微调Real-ESRGAN-x2plus进行超分重建
- Anomalib:使用Anomalib 2.1.0训练自己的数据集进行异常检测
- Anomalib:在Linux服务器上安装使用Anomalib 2.1.0
- 人工智能混合编程实践:C++调用封装好的DLL进行异常检测推理
- 人工智能混合编程实践:C++调用封装好的DLL进行FP16图像超分重建(v3.0)
- 隔离系统Python:源码编译3.11.8到自定义目录(含PGO性能优化)
- 在线机的Python环境迁移到离线机上
- Nuitka 将 Python 脚本封装为 .pyd 或 .so 文件
- Ultralytics:使用 YOLO11 进行速度估计
- Ultralytics:使用 YOLO11 进行物体追踪
- Ultralytics:使用 YOLO11 进行物体计数
- Ultralytics:使用 YOLO11 进行目标打码
- 人工智能混合编程实践:C++调用Python ONNX进行YOLOv8推理
- 人工智能混合编程实践:C++调用封装好的DLL进行YOLOv8实例分割
- 人工智能混合编程实践:C++调用Python ONNX进行图像超分重建
- 人工智能混合编程实践:C++调用Python AgentOCR进行文本识别
- 通过计算实例简单地理解PatchCore异常检测
- Python将YOLO格式实例分割数据集转换为COCO格式实例分割数据集
- YOLOv8 Ultralytics:使用Ultralytics框架训练RT-DETR实时目标检测模型
- 基于DETR的人脸伪装检测
- YOLOv7训练自己的数据集(口罩检测)
- YOLOv8训练自己的数据集(足球检测)
- YOLOv5:TensorRT加速YOLOv5模型推理
- YOLOv5:IoU、GIoU、DIoU、CIoU、EIoU
- 玩转Jetson Nano(五):TensorRT加速YOLOv5目标检测
- YOLOv5:添加SE、CBAM、CoordAtt、ECA注意力机制
- YOLOv5:yolov5s.yaml配置文件解读、增加小目标检测层
- Python将COCO格式实例分割数据集转换为YOLO格式实例分割数据集
- YOLOv5:使用7.0版本训练自己的实例分割模型(车辆、行人、路标、车道线等实例分割)
- 使用Kaggle GPU资源免费体验Stable Diffusion开源项目
- Stable Diffusion:在服务器上部署使用Stable Diffusion WebUI进行AI绘图(v2.0)
- Stable Diffusion:使用自己的数据集微调训练LoRA模型(v2.0)
相关介绍
Ultralytics 简介
Ultralytics 基于多年的计算机视觉和人工智能基础研究,创建了最先进的 (SOTA) YOLO 模型。我们的模型不断更新性能和灵活性,快速、准确且易于使用。他们擅长对象检测、跟踪、实例分割、语义分割、图像分类和姿势估计任务。
前提条件
- 熟悉Python、Pytorch
实验环境
bash
Package                  Version
------------------------ ------------
Python                   3.11.8
absl-py                  2.4.0
accelerate               1.13.0
annotated-doc            0.0.4
anyio                    4.13.0
calflops                 0.3.2
certifi                  2026.4.22
charset-normalizer       3.4.7
click                    8.3.3
colorama                 0.4.6
contourpy                1.3.3
cycler                   0.12.1
filelock                 3.29.0
flatbuffers              25.12.19
fonttools                4.62.1
fsspec                   2026.4.0
grpcio                   1.80.0
h11                      0.16.0
hf-xet                   1.5.0
httpcore                 1.0.9
httpx                    0.28.1
huggingface_hub          1.14.0
idna                     3.15
Jinja2                   3.1.6
kiwisolver               1.5.0
Markdown                 3.10.2
markdown-it-py           4.2.0
MarkupSafe               3.0.3
matplotlib               3.10.9
mdurl                    0.1.2
ml_dtypes                0.5.0
mpmath                   1.3.0
networkx                 3.6.1
numpy                    1.26.4
nvidia-cublas-cu12       12.8.3.14
nvidia-cuda-cupti-cu12   12.8.57
nvidia-cuda-nvrtc-cu12   12.8.61
nvidia-cuda-runtime-cu12 12.8.57
nvidia-cudnn-cu12        9.7.1.26
nvidia-cufft-cu12        11.3.3.41
nvidia-cufile-cu12       1.13.0.11
nvidia-curand-cu12       10.3.9.55
nvidia-cusolver-cu12     11.7.2.55
nvidia-cusparse-cu12     12.5.7.53
nvidia-cusparselt-cu12   0.6.3
nvidia-nccl-cu12         2.26.2
nvidia-nvjitlink-cu12    12.8.61
nvidia-nvtx-cu12         12.8.55
onnx                     1.19.0
onnxruntime-gpu          1.26.0
onnxslim                 0.1.94
opencv-python            4.6.0.66
packaging                26.2
pillow                   12.2.0
pip                      24.0
polars                   1.40.1
polars-runtime-32        1.40.1
protobuf                 7.34.1
psutil                   7.2.2
pycocotools              2.0.11
Pygments                 2.20.0
pyparsing                3.3.2
python-dateutil          2.9.0.post0
PyYAML                   6.0.3
regex                    2026.5.9
requests                 2.34.1
rich                     15.0.0
safetensors              0.7.0
scipy                    1.16.0
setuptools               65.5.0
shellingham              1.5.4
six                      1.17.0
sympy                    1.14.0
tabulate                 0.10.0
tensorboard              2.20.0
tensorboard-data-server  0.7.2
tokenizers               0.22.2
torch                    2.7.1+cu128
torchaudio               2.7.1+cu128
torchvision              0.22.1+cu128
tqdm                     4.67.3
transformers             5.8.1
triton                   3.3.1
typer                    0.25.1
typing_extensions        4.15.0
ultralytics              8.4.58
ultralytics-thop         2.0.19
urllib3                  2.7.0
Werkzeug                 3.1.8
C2(CSP Bottleneck with 2 convolutions)
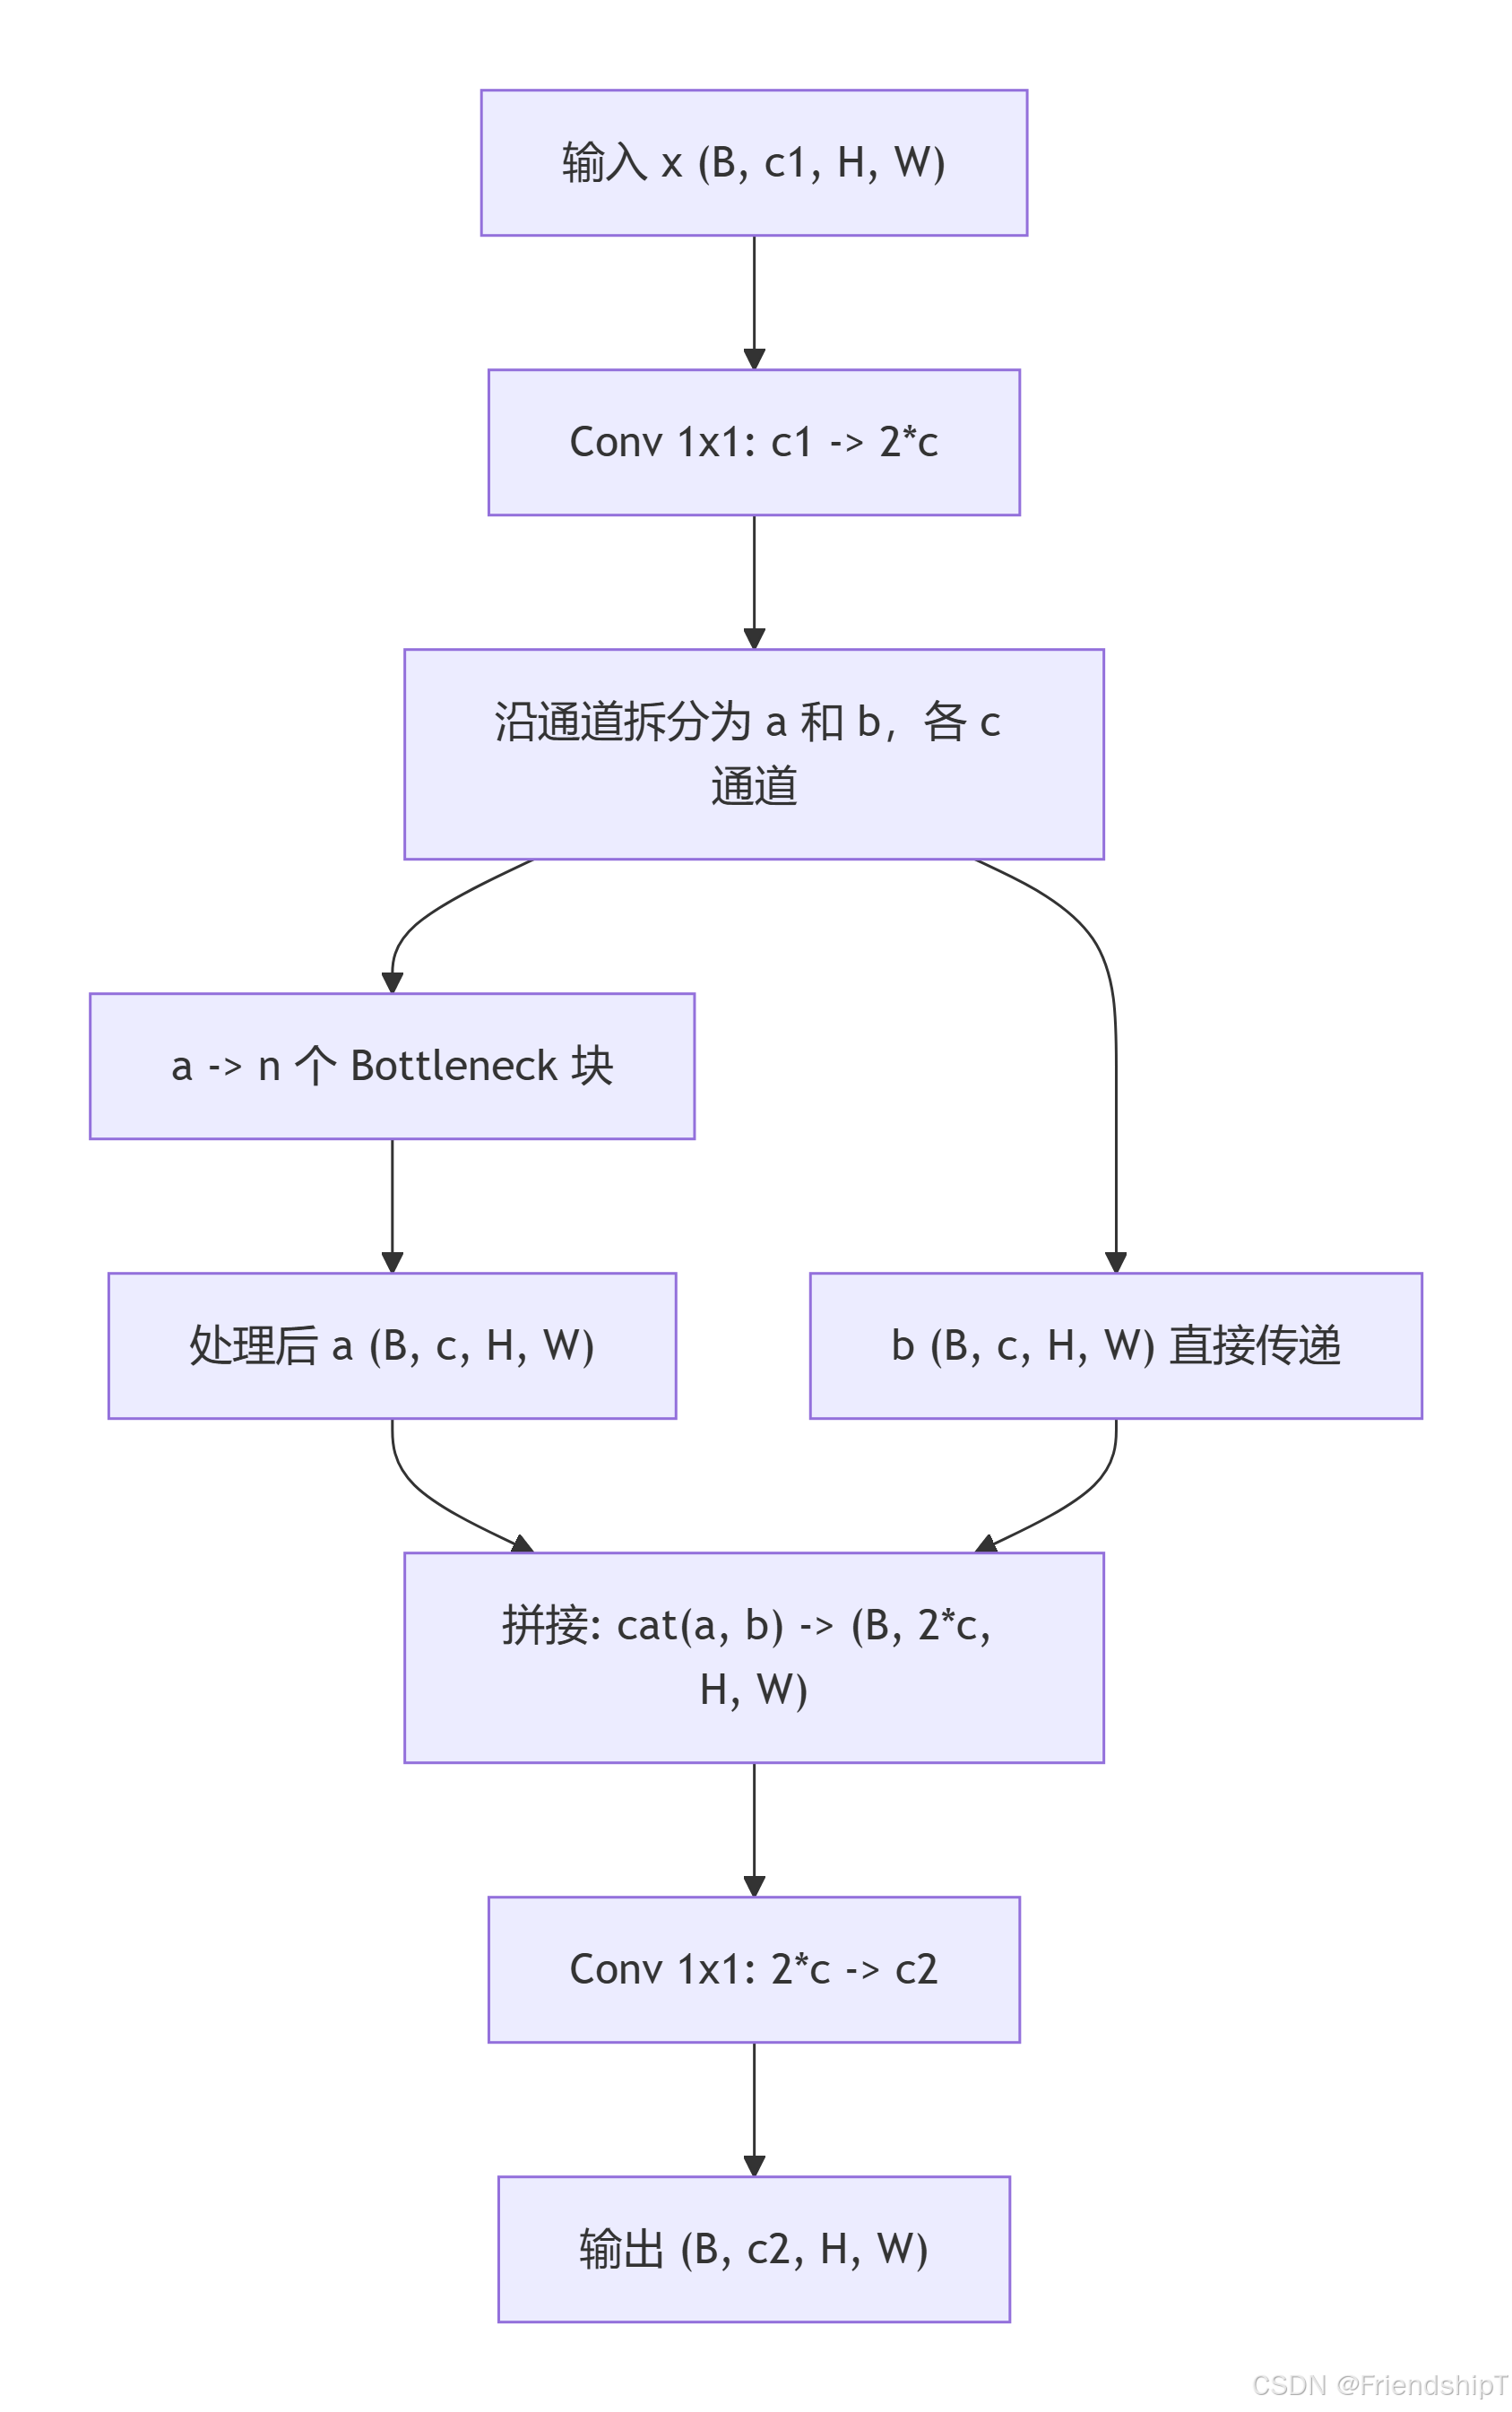
C2 是一种 CSP(Cross Stage Partial)瓶颈模块 ,它通过 1×1 卷积将通道分成两部分 ,一部分经过多个 Bottleneck 块进行深层特征提取,另一部分直接传递(shortcut),最后将两者拼接并通过 1×1 卷积融合。这种结构在 YOLOv5/v8 中广泛使用,以平衡计算量与特征表达能力。
代码实现
python
import cv2
import math
import torch
import numpy as np
import matplotlib.pyplot as plt
from torch import nn

def autopad(k, p=None, d=1):  # kernel, padding, dilation
    """Pad to 'same' shape outputs."""
    if d > 1:
        k = d * (k - 1) + 1 if isinstance(k, int) else [d * (x - 1) + 1 for x in k]  # actual kernel-size
    if p is None:
        p = k // 2 if isinstance(k, int) else [x // 2 for x in k]  # auto-pad
    return p

class Conv(nn.Module):
    """Standard convolution module with batch normalization and activation.

    Attributes:
        conv (nn.Conv2d): Convolutional layer.
        bn (nn.BatchNorm2d): Batch normalization layer.
        act (nn.Module): Activation function layer.
        default_act (nn.Module): Default activation function (SiLU).
    """

    default_act = nn.SiLU()  # default activation

    def __init__(self, c1, c2, k=1, s=1, p=None, g=1, d=1, act=True):
        """Initialize Conv layer with given parameters.

        Args:
            c1 (int): Number of input channels.
            c2 (int): Number of output channels.
            k (int): Kernel size.
            s (int): Stride.
            p (int, optional): Padding.
            g (int): Groups.
            d (int): Dilation.
            act (bool | nn.Module): Activation function.
        """
        super().__init__()
        self.conv = nn.Conv2d(c1, c2, k, s, autopad(k, p, d), groups=g, dilation=d, bias=False)
        self.bn = nn.BatchNorm2d(c2)
        self.act = self.default_act if act is True else act if isinstance(act, nn.Module) else nn.Identity()

    def forward(self, x):
        """Apply convolution, batch normalization and activation to input tensor.

        Args:
            x (torch.Tensor): Input tensor.

        Returns:
            (torch.Tensor): Output tensor.
        """
        return self.act(self.bn(self.conv(x)))

    def forward_fuse(self, x):
        """Apply convolution and activation without batch normalization.

        Args:
            x (torch.Tensor): Input tensor.

        Returns:
            (torch.Tensor): Output tensor.
        """
        return self.act(self.conv(x))

class Bottleneck(nn.Module):
    """Standard bottleneck."""

    def __init__(
        self, c1: int, c2: int, shortcut: bool = True, g: int = 1, k: tuple[int, int] = (3, 3), e: float = 0.5
    ):
        """Initialize a standard bottleneck module.

        Args:
            c1 (int): Input channels.
            c2 (int): Output channels.
            shortcut (bool): Whether to use shortcut connection.
            g (int): Groups for convolutions.
            k (tuple): Kernel sizes for convolutions.
            e (float): Expansion ratio.
        """
        super().__init__()
        c_ = int(c2 * e)  # hidden channels
        self.cv1 = Conv(c1, c_, k[0], 1)
        self.cv2 = Conv(c_, c2, k[1], 1, g=g)
        self.add = shortcut and c1 == c2

    def forward(self, x: torch.Tensor) -> torch.Tensor:
        """Apply bottleneck with optional shortcut connection."""
        return x + self.cv2(self.cv1(x)) if self.add else self.cv2(self.cv1(x))

class C2(nn.Module):
    """CSP Bottleneck with 2 convolutions."""

    def __init__(self, c1: int, c2: int, n: int = 1, shortcut: bool = True, g: int = 1, e: float = 0.5):
        """Initialize a CSP Bottleneck with 2 convolutions.

        Args:
            c1 (int): Input channels.
            c2 (int): Output channels.
            n (int): Number of Bottleneck blocks.
            shortcut (bool): Whether to use shortcut connections.
            g (int): Groups for convolutions.
            e (float): Expansion ratio.
        """
        super().__init__()
        self.c = int(c2 * e)  # hidden channels
        self.cv1 = Conv(c1, 2 * self.c, 1, 1)
        self.cv2 = Conv(2 * self.c, c2, 1)  # optional act=FReLU(c2)
        # self.attention = ChannelAttention(2 * self.c)  # or SpatialAttention()
        self.m = nn.Sequential(*(Bottleneck(self.c, self.c, shortcut, g, k=((3, 3), (3, 3)), e=1.0) for _ in range(n)))

    def forward(self, x: torch.Tensor) -> torch.Tensor:
        """Forward pass through the CSP bottleneck with 2 convolutions."""
        a, b = self.cv1(x).chunk(2, 1)
        return self.cv2(torch.cat((self.m(a), b), 1))
功能
- 通道拆分与特征融合 :通过 1×1 卷积将输入通道扩展为
2 * hidden,然后沿通道维均分成两部分(a和b)。 - 深层特征提取 :一部分(
a)通过n个Bottleneck块进行非线性变换,捕获丰富语义信息。 - 残差短路连接 :另一部分(
b)直接保留,保持梯度流动和特征多样性。 - 特征拼接与压缩 :将处理后的
a与原始b拼接,再通过 1×1 卷积恢复为输出通道数c2。
初始化参数
| 参数 | 类型 | 说明 |
|---|---|---|
c1 |
int | 输入通道数 |
c2 |
int | 输出通道数 |
n |
int | Bottleneck 块的数量(默认 1) |
shortcut |
bool | Bottleneck 内部是否使用残差连接(默认 True) |
g |
int | 分组卷积的组数(默认 1) |
e |
float | 隐藏层通道扩展比(相对于 c2,默认 0.5) |
前向方法
forward(x):输入x([B, c1, H, W]),输出[B, c2, H, W]。
计算流程:
y = self.cv1(x):1×1 卷积,通道数变为2 * self.c(self.c = int(c2 * e))。a, b = y.chunk(2, dim=1):沿通道维均分为两部分,每部分通道数为self.c。a_processed = self.m(a):将a依次通过n个Bottleneck块(每个块保持通道数self.c)。cat = torch.cat((a_processed, b), dim=1):拼接得到通道数2 * self.c。self.cv2(cat):1×1 卷积,将通道数压缩至c2,输出最终结果。
使用示例
python
if __name__ == '__main__':
    # 1. 创建随机输入
    x = torch.randn(1, 32, 64, 64)

    # 2. 创建 C2 模块:输入32,输出64,n=2(两个Bottleneck块)
    c2_block = C2(c1=32, c2=64, n=2, shortcut=True, g=1, e=0.5)

    # 3. 前向传播
    with torch.no_grad():
        out = c2_block(x)
    print("输入形状:", x.shape)   # [1, 32, 64, 64]
    print("输出形状:", out.shape) # [1, 64, 64, 64]

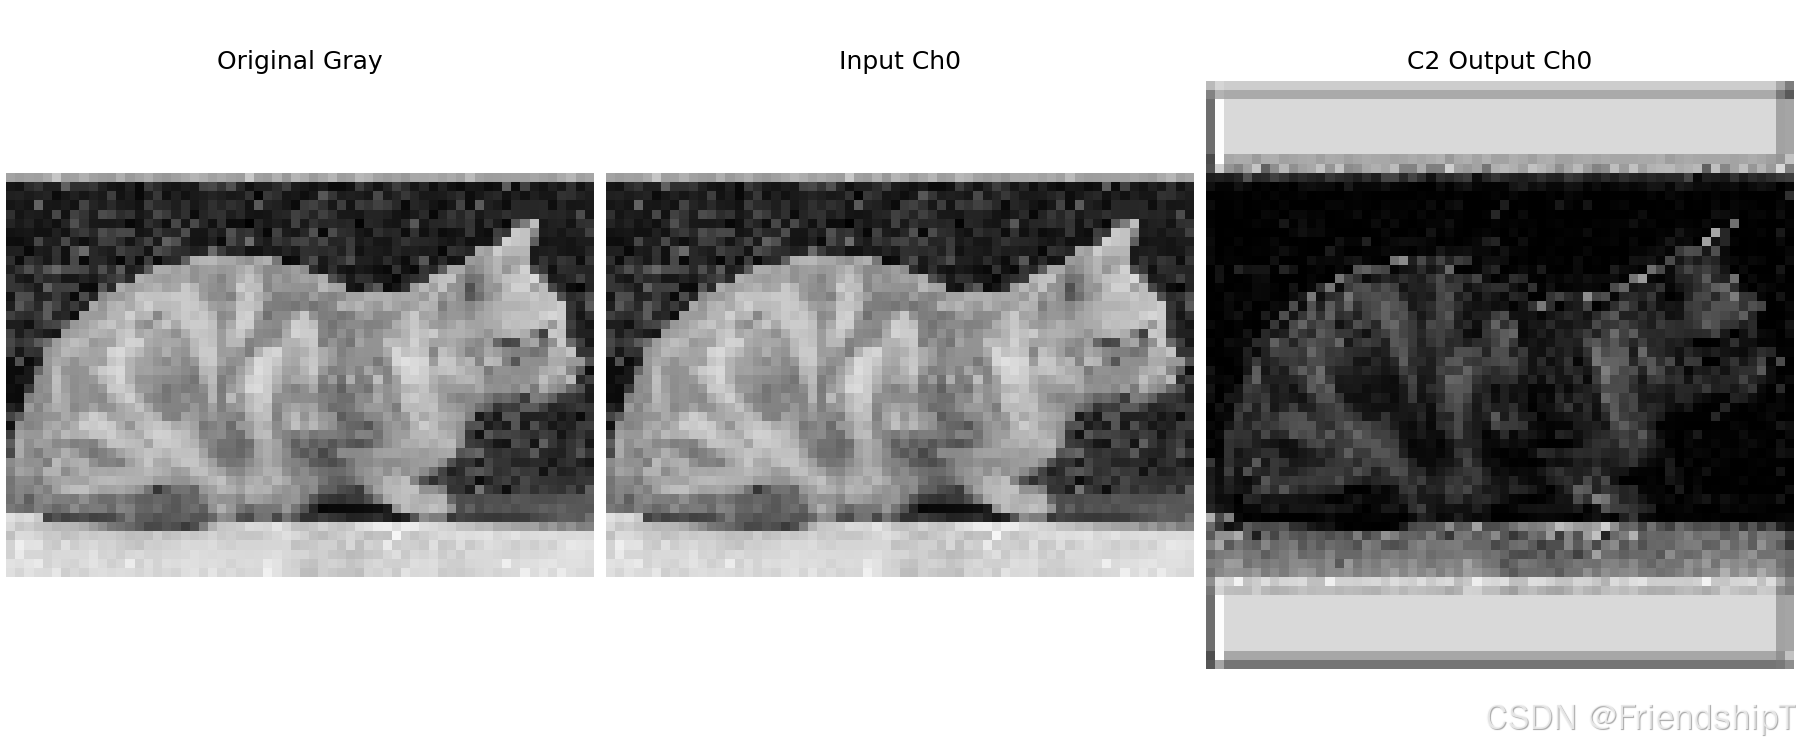
    # 4. 使用真实图像演示
    img_path = "cat_640x640.png"
    img_bgr = cv2.imread(img_path)
    if img_bgr is not None:
        # 缩放到 64x64,转为灰度图
        img_gray = cv2.cvtColor(cv2.resize(img_bgr, (64, 64)), cv2.COLOR_BGR2GRAY)
        img_tensor = torch.from_numpy(img_gray).float().unsqueeze(0).unsqueeze(0)  # [1,1,64,64]
        # 扩展通道至32(模拟特征图)
        x_img = img_tensor.repeat(1, 32, 1, 1)  # [1,32,64,64]

        # 创建 C2(输入32,输出32,n=1)
        c2_img = C2(c1=32, c2=32, n=1, shortcut=True)
        with torch.no_grad():
            out_img = c2_img(x_img)  # [1,32,64,64]

        # 可视化:输入通道0、输出通道0
        inp_ch0 = x_img[0, 0].cpu().numpy()
        out_ch0 = out_img[0, 0].cpu().numpy()

        def norm(arr):
            return (arr - arr.min()) / (arr.max() - arr.min() + 1e-8)

        plt.figure(figsize=(12, 5), constrained_layout=True)
        plt.subplot(1, 3, 1)
        plt.imshow(img_gray, cmap='gray')
        plt.title("Original Gray")
        plt.axis("off")
        plt.subplot(1, 3, 2)
        plt.imshow(norm(inp_ch0), cmap='gray')
        plt.title("Input Ch0")
        plt.axis("off")
        plt.subplot(1, 3, 3)
        plt.imshow(norm(out_ch0), cmap='gray')
        plt.title("C2 Output Ch0")
        plt.axis("off")
        plt.savefig("c2_demo.png", dpi=150)
print("可视化已保存为 c2_demo.png")输出示例:
输入形状: torch.Size([1, 32, 64, 64])
输出形状: torch.Size([1, 64, 64, 64])
可视化已保存为 c2_demo.png
流程示意图
代码解读
__init__:self.c = int(c2 * e):隐藏层通道数(用于a和b两部分)。self.cv1:1×1 卷积,将输入通道c1扩展至2 * self.c,为拆分做准备。self.m:由n个Bottleneck组成的序列,每个Bottleneck的输入/输出通道均为self.c,shortcut和g参数传递,k固定为(3,3),e=1.0(不压缩通道)。self.cv2:1×1 卷积,将拼接后的2 * self.c通道压缩至c2。
forward:self.cv1(x)后通过.chunk(2, 1)沿通道维均分成a和b。self.m(a)对a进行深层处理。- 拼接后通过
self.cv2输出。
注意事项
- 通道数计算 :
self.c = int(c2 * e),当e=0.5时隐藏层通道为输出通道的一半,cv1输出为2*self.c = c2,此时若不经过cv2则输出通道已为c2,但cv2仍用于融合可学习性。 - Bottleneck 参数 :内部
Bottleneck的k固定为(3,3),e=1.0,即不压缩通道,只做空间特征提取。 - 空间尺寸不变:所有卷积步长为 1,填充自动 same,因此输入输出空间尺寸相同。
- CSP 思想:将特征图拆分为两部分,一部分深层处理,一部分直通,有助于梯度流和特征复用。
- 可扩展性 :注释中提到了可添加
ChannelAttention或SpatialAttention,便于引入注意力机制。
优缺点
优点
- 高效特征融合:通过拆分-处理-拼接,减少计算量,同时保留原始特征信息。
- 梯度流动优化 :直通路径(
b)缓解深层网络梯度消失,便于训练。 - 灵活配置 :可通过
n控制深度,e控制通道压缩比,适应不同规模模型。 - 模块化设计 :基于
Bottleneck构建,易于替换和扩展。
缺点
- 通道拆分限制 :要求
2 * self.c能被 2 整除(通常可以),但若c2*e非整数需调整。 - 无法改变空间尺寸 :仅用于同尺度特征变换,不包含下采样功能(需配合
Conv步长实现)。 - 参数冗余 :当
n较大或e较大时,参数量和计算量可能较高。
在 YOLOv5/v8 中,C2 是构建 C3(CSP Bottleneck with 3 convolutions)和 C2f(更轻量版本)的基础。实际使用时,可根据任务需求调整 e、n 和 shortcut,并在深层网络适当增加 n 以增强表示能力。
参考文献
1 https://docs.ultralytics.com/
2 https://github.com/ultralytics/ultralytics.git
- 由于本人水平有限,难免出现错漏,敬请批评改正。
- 更多精彩内容,可点击进入Python日常小操作专栏、OpenCV-Python小应用专栏、YOLO系列专栏、自然语言处理专栏、人工智能混合编程实践专栏或我的个人主页查看
- YOLOs-CPP:一个免费开源的YOLO全系列C++推理库(以YOLO26为例)
- PaddleOCR:Win10上安装使用PPOCRLabel标注工具
- 目标检测:使用自己的数据集微调DEIMv2进行物体检测
- 图像分割:PyTorch从零开始实现SegFormer语义分割
- 图像超分:使用自己的数据集微调Real-ESRGAN-x4plus进行超分重建
- 图像生成:PyTorch从零开始实现一个简单的扩散模型
- Stable Diffusion:使用自己的数据集微调 Stable Diffusion 3.5 LoRA 文生图模型
- 图像超分:使用自己的数据集微调Real-ESRGAN-x2plus进行超分重建
- Anomalib:使用Anomalib 2.1.0训练自己的数据集进行异常检测
- Anomalib:在Linux服务器上安装使用Anomalib 2.1.0
- 人工智能混合编程实践:C++调用封装好的DLL进行异常检测推理
- 人工智能混合编程实践:C++调用封装好的DLL进行FP16图像超分重建(v3.0)
- 隔离系统Python:源码编译3.11.8到自定义目录(含PGO性能优化)
- 在线机的Python环境迁移到离线机上
- Nuitka 将 Python 脚本封装为 .pyd 或 .so 文件
- Ultralytics:使用 YOLO11 进行速度估计
- Ultralytics:使用 YOLO11 进行物体追踪
- Ultralytics:使用 YOLO11 进行物体计数
- Ultralytics:使用 YOLO11 进行目标打码
- 人工智能混合编程实践:C++调用Python ONNX进行YOLOv8推理
- 人工智能混合编程实践:C++调用封装好的DLL进行YOLOv8实例分割
- 人工智能混合编程实践:C++调用Python ONNX进行图像超分重建
- 人工智能混合编程实践:C++调用Python AgentOCR进行文本识别
- 通过计算实例简单地理解PatchCore异常检测
- Python将YOLO格式实例分割数据集转换为COCO格式实例分割数据集
- YOLOv8 Ultralytics:使用Ultralytics框架训练RT-DETR实时目标检测模型
- 基于DETR的人脸伪装检测
- YOLOv7训练自己的数据集(口罩检测)
- YOLOv8训练自己的数据集(足球检测)
- YOLOv5:TensorRT加速YOLOv5模型推理
- YOLOv5:IoU、GIoU、DIoU、CIoU、EIoU
- 玩转Jetson Nano(五):TensorRT加速YOLOv5目标检测
- YOLOv5:添加SE、CBAM、CoordAtt、ECA注意力机制
- YOLOv5:yolov5s.yaml配置文件解读、增加小目标检测层
- Python将COCO格式实例分割数据集转换为YOLO格式实例分割数据集
- YOLOv5:使用7.0版本训练自己的实例分割模型(车辆、行人、路标、车道线等实例分割)
- 使用Kaggle GPU资源免费体验Stable Diffusion开源项目
- Stable Diffusion:在服务器上部署使用Stable Diffusion WebUI进行AI绘图(v2.0)
- Stable Diffusion:使用自己的数据集微调训练LoRA模型(v2.0)