这个交互式 Notebook 将介绍一些 Elasticsearch 基础操作,使用官方 Elasticsearch Python 客户端。你将使用 Sentence Transformers 对文本进行嵌入,并执行语义搜索。学习如何将传统基于文本的搜索与语义搜索结合,构建混合搜索系统。
如果你想使用本地部署,你可以参考文章 "如何在 Linux,MacOS 及 Windows 上进行安装 Elasticsearch" 来进行安装。并参考代码 https://github.com/liu-xiao-guo/semantic_search_getstarted
创建 Elastic Cloud 部署
如果你没有 Elastic Cloud 部署,可以在这里注册免费试用。
登录 Elastic Cloud 账户后,进入创建部署页面并选择创建部署(Create deployment)。保持所有设置为默认值。
安装软件包并导入模块
开始之前,我们需要使用 Python 客户端连接到我们的 Elastic 部署。由于我们使用的是 Elastic Cloud 部署,因此将使用 Cloud ID 来标识我们的部署。
首先,我们需要安装 Elasticsearch Python 客户端。
!pip install -qU "elasticsearch<9" sentence-transformers==2.7.0在此示例中,我们使用 sentence_transformers 库中的 all-MiniLM-L6-v2 模型。你可以在 Hugging Face 上阅读有关此模型的更多信息。
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("all-MiniLM-L6-v2")
初始化 Elasticsearch 客户端
现在,我们可以实例化 Elasticsearch Python 客户端,并提供部署中的 Cloud ID 和密码。
from elasticsearch import Elasticsearch
from getpass import getpass

# https://www.elastic.co/search-labs/tutorials/install-elasticsearch/elastic-cloud#finding-your-cloud-id
ELASTIC_CLOUD_ID = getpass("Elastic Cloud ID: ")

# https://www.elastic.co/search-labs/tutorials/install-elasticsearch/elastic-cloud#creating-an-api-key
ELASTIC_API_KEY = getpass("Elastic Api Key: ")

# 创建客户端实例
client = Elasticsearch(
    # 用于本地开发
    # hosts=["http://localhost:9200"]
    cloud_id=ELASTIC_CLOUD_ID,
    api_key=ELASTIC_API_KEY,
)
如果你正在本地运行 Elasticsearch 或使用自托管部署,则可以改为传入 Elasticsearch 主机地址。阅读更多关于如何连接本地 Elasticsearch 的信息。
启用遥测
了解你正在使用此 Notebook,有助于我们决定将精力投入到哪些方面来改进我们的产品。
我们希望你运行以下代码,以便我们收集匿名使用统计信息。有关详细信息,请参阅 telemetry.py。谢谢!
!curl -O -s https://raw.githubusercontent.com/elastic/elasticsearch-labs/main/telemetry/telemetry.py

from telemetry import enable_telemetry

client = enable_telemetry(client, "00-quick-start")
测试客户端
在继续之前,请通过此测试确认客户端已成功连接。
print(client.info())输出:
{
  'name': 'instance-0000000000',
  'cluster_name': 'a72482be54904952ba46d53c3def7740',
  'cluster_uuid': 'g8BE52TtT32pGBbRzP_oKA',
  'version': {
    'number': '8.12.2',
    'build_flavor': 'default',
    'build_type': 'docker',
    'build_hash': '48a287ab9497e852de30327444b0809e55d46466',
    'build_date': '2024-02-19T10:04:32.774273190Z',
    'build_snapshot': False,
    'lucene_version': '9.9.2',
    'minimum_wire_compatibility_version': '7.17.0',
    'minimum_index_compatibility_version': '7.0.0'
  },
  'tagline': 'You Know, for Search'
}
索引测试数据
我们的客户端已经设置完成,并连接到了 Elastic 部署。现在,我们需要一些数据来测试 Elasticsearch 查询基础功能。我们将使用一个包含以下字段的图书小型索引:
-
title -
authors -
publish_date -
num_reviews -
publisher
创建索引
首先确保不存在之前创建的名为 book_index 的索引。
client.indices.delete(index="book_index", ignore_unavailable=True)输出:
ObjectApiResponse({'acknowledged': True})🔐 注意:你可以随时返回此部分并运行上面的删除函数,以删除索引并从头开始。
让我们创建一个 Elasticsearch 索引,并为测试数据配置正确的映射。
# 定义映射
mappings = {
    "properties": {
        "title_vector": {
            "type": "dense_vector",
            "dims": 384,
            "index": "true",
            "similarity": "cosine",
        }
    }
}

# 创建索引
client.indices.create(index="book_index", mappings=mappings)
输出:
ObjectApiResponse({'acknowledged': True, 'shards_acknowledged': True, 'index': 'book_index'})索引测试数据
运行以下命令上传一些测试数据,其中包含来自该数据集的 10 本热门编程书籍的信息。model.encode 会使用我们之前初始化的模型,将文本实时编码为向量。
import json
from urllib.request import urlopen

url = "https://raw.githubusercontent.com/elastic/elasticsearch-labs/main/notebooks/search/data.json"
response = urlopen(url)
books = json.loads(response.read())

operations = []
for book in books:
    operations.append({"index": {"_index": "book_index"}})
    # 使用模型将标题转换为嵌入向量
    book["title_vector"] = model.encode(book["title"]).tolist()
    operations.append(book)

client.bulk(index="book_index", operations=operations, refresh=True)
输出:
ObjectApiResponse({'errors': False, 'took': 88, 'items': [{'index': {'_index': 'book_index', '_id': 'caRpvY4BKY8PuI1qPluy', '_version': 1, 'result': 'created', 'forced_refresh': True, '_shards': {'total': 2, 'successful': 2, 'failed': 0}, '_seq_no': 0, '_primary_term': 1, 'status': 201}}, {'index': {'_index': 'book_index', '_id': 'cqRpvY4BKY8PuI1qPluy', '_version': 1, 'result': 'created', 'forced_refresh': True, '_shards': {'total': 2, 'successful': 2, 'failed': 0}, '_seq_no': 1, '_primary_term': 1, 'status': 201}}, {'index': {'_index': 'book_index', '_id': 'c6RpvY4BKY8PuI1qPluy', '_version': 1, 'result': 'created', 'forced_refresh': True, '_shards': {'total': 2, 'successful': 2, 'failed': 0}, '_seq_no': 2, '_primary_term': 1, 'status': 201}}, {'index': {'_index': 'book_index', '_id': 'dKRpvY4BKY8PuI1qPluy', '_version': 1, 'result': 'created', 'forced_refresh': True, '_shards': {'total': 2, 'successful': 2, 'failed': 0}, '_seq_no': 3, '_primary_term': 1, 'status': 201}}, {'index': {'_index': 'book_index', '_id': 'daRpvY4BKY8PuI1qPluy', '_version': 1, 'result': 'created', 'forced_refresh': True, '_shards': {'total': 2, 'successful': 2, 'failed': 0}, '_seq_no': 4, '_primary_term': 1, 'status': 201}}, {'index': {'_index': 'book_index', '_id': 'dqRpvY4BKY8PuI1qPluy', '_version': 1, 'result': 'created', 'forced_refresh': True, '_shards': {'total': 2, 'successful': 2, 'failed': 0}, '_seq_no': 5, '_primary_term': 1, 'status': 201}}, {'index': {'_index': 'book_index', '_id': 'd6RpvY4BKY8PuI1qPluy', '_version': 1, 'result': 'created', 'forced_refresh': True, '_shards': {'total': 2, 'successful': 2, 'failed': 0}, '_seq_no': 6, '_primary_term': 1, 'status': 201}}, {'index': {'_index': 'book_index', '_id': 'eKRpvY4BKY8PuI1qPluy', '_version': 1, 'result': 'created', 'forced_refresh': True, '_shards': {'total': 2, 'successful': 2, 'failed': 0}, '_seq_no': 7, '_primary_term': 1, 'status': 201}}, {'index': {'_index': 'book_index', '_id': 'eaRpvY4BKY8PuI1qPluy', '_version': 1, 'result': 'created', 'forced_refresh': True, '_shards': {'total': 2, 'successful': 2, 'failed': 0}, '_seq_no': 8, '_primary_term': 1, 'status': 201}}, {'index': {'_index': 'book_index', '_id': 'eqRpvY4BKY8PuI1qPluy', '_version': 1, 'result': 'created', 'forced_refresh': True, '_shards': {'total': 2, 'successful': 2, 'failed': 0}, '_seq_no': 9, '_primary_term': 1, 'status': 201}}]})附带说明:格式化 Elasticsearch 响应
你的 API 调用会返回难以阅读的嵌套 JSON。我们将创建一个名为 pretty_response 的小函数,用于从示例中返回清晰、易读的输出。
def pretty_response(response):
    if len(response["hits"]["hits"]) == 0:
        print("Your search returned no results.")
    else:
        for hit in response["hits"]["hits"]:
            id = hit["_id"]
            publication_date = hit["_source"]["publish_date"]
            score = hit["_score"]
            title = hit["_source"]["title"]
            summary = hit["_source"]["summary"]
            publisher = hit["_source"]["publisher"]
            num_reviews = hit["_source"]["num_reviews"]
            authors = hit["_source"]["authors"]
            pretty_output = f"\nID: {id}\nPublication date: {publication_date}\nTitle: {title}\nSummary: {summary}\nPublisher: {publisher}\nReviews: {num_reviews}\nAuthors: {authors}\nScore: {score}"
            print(pretty_output)
创建查询
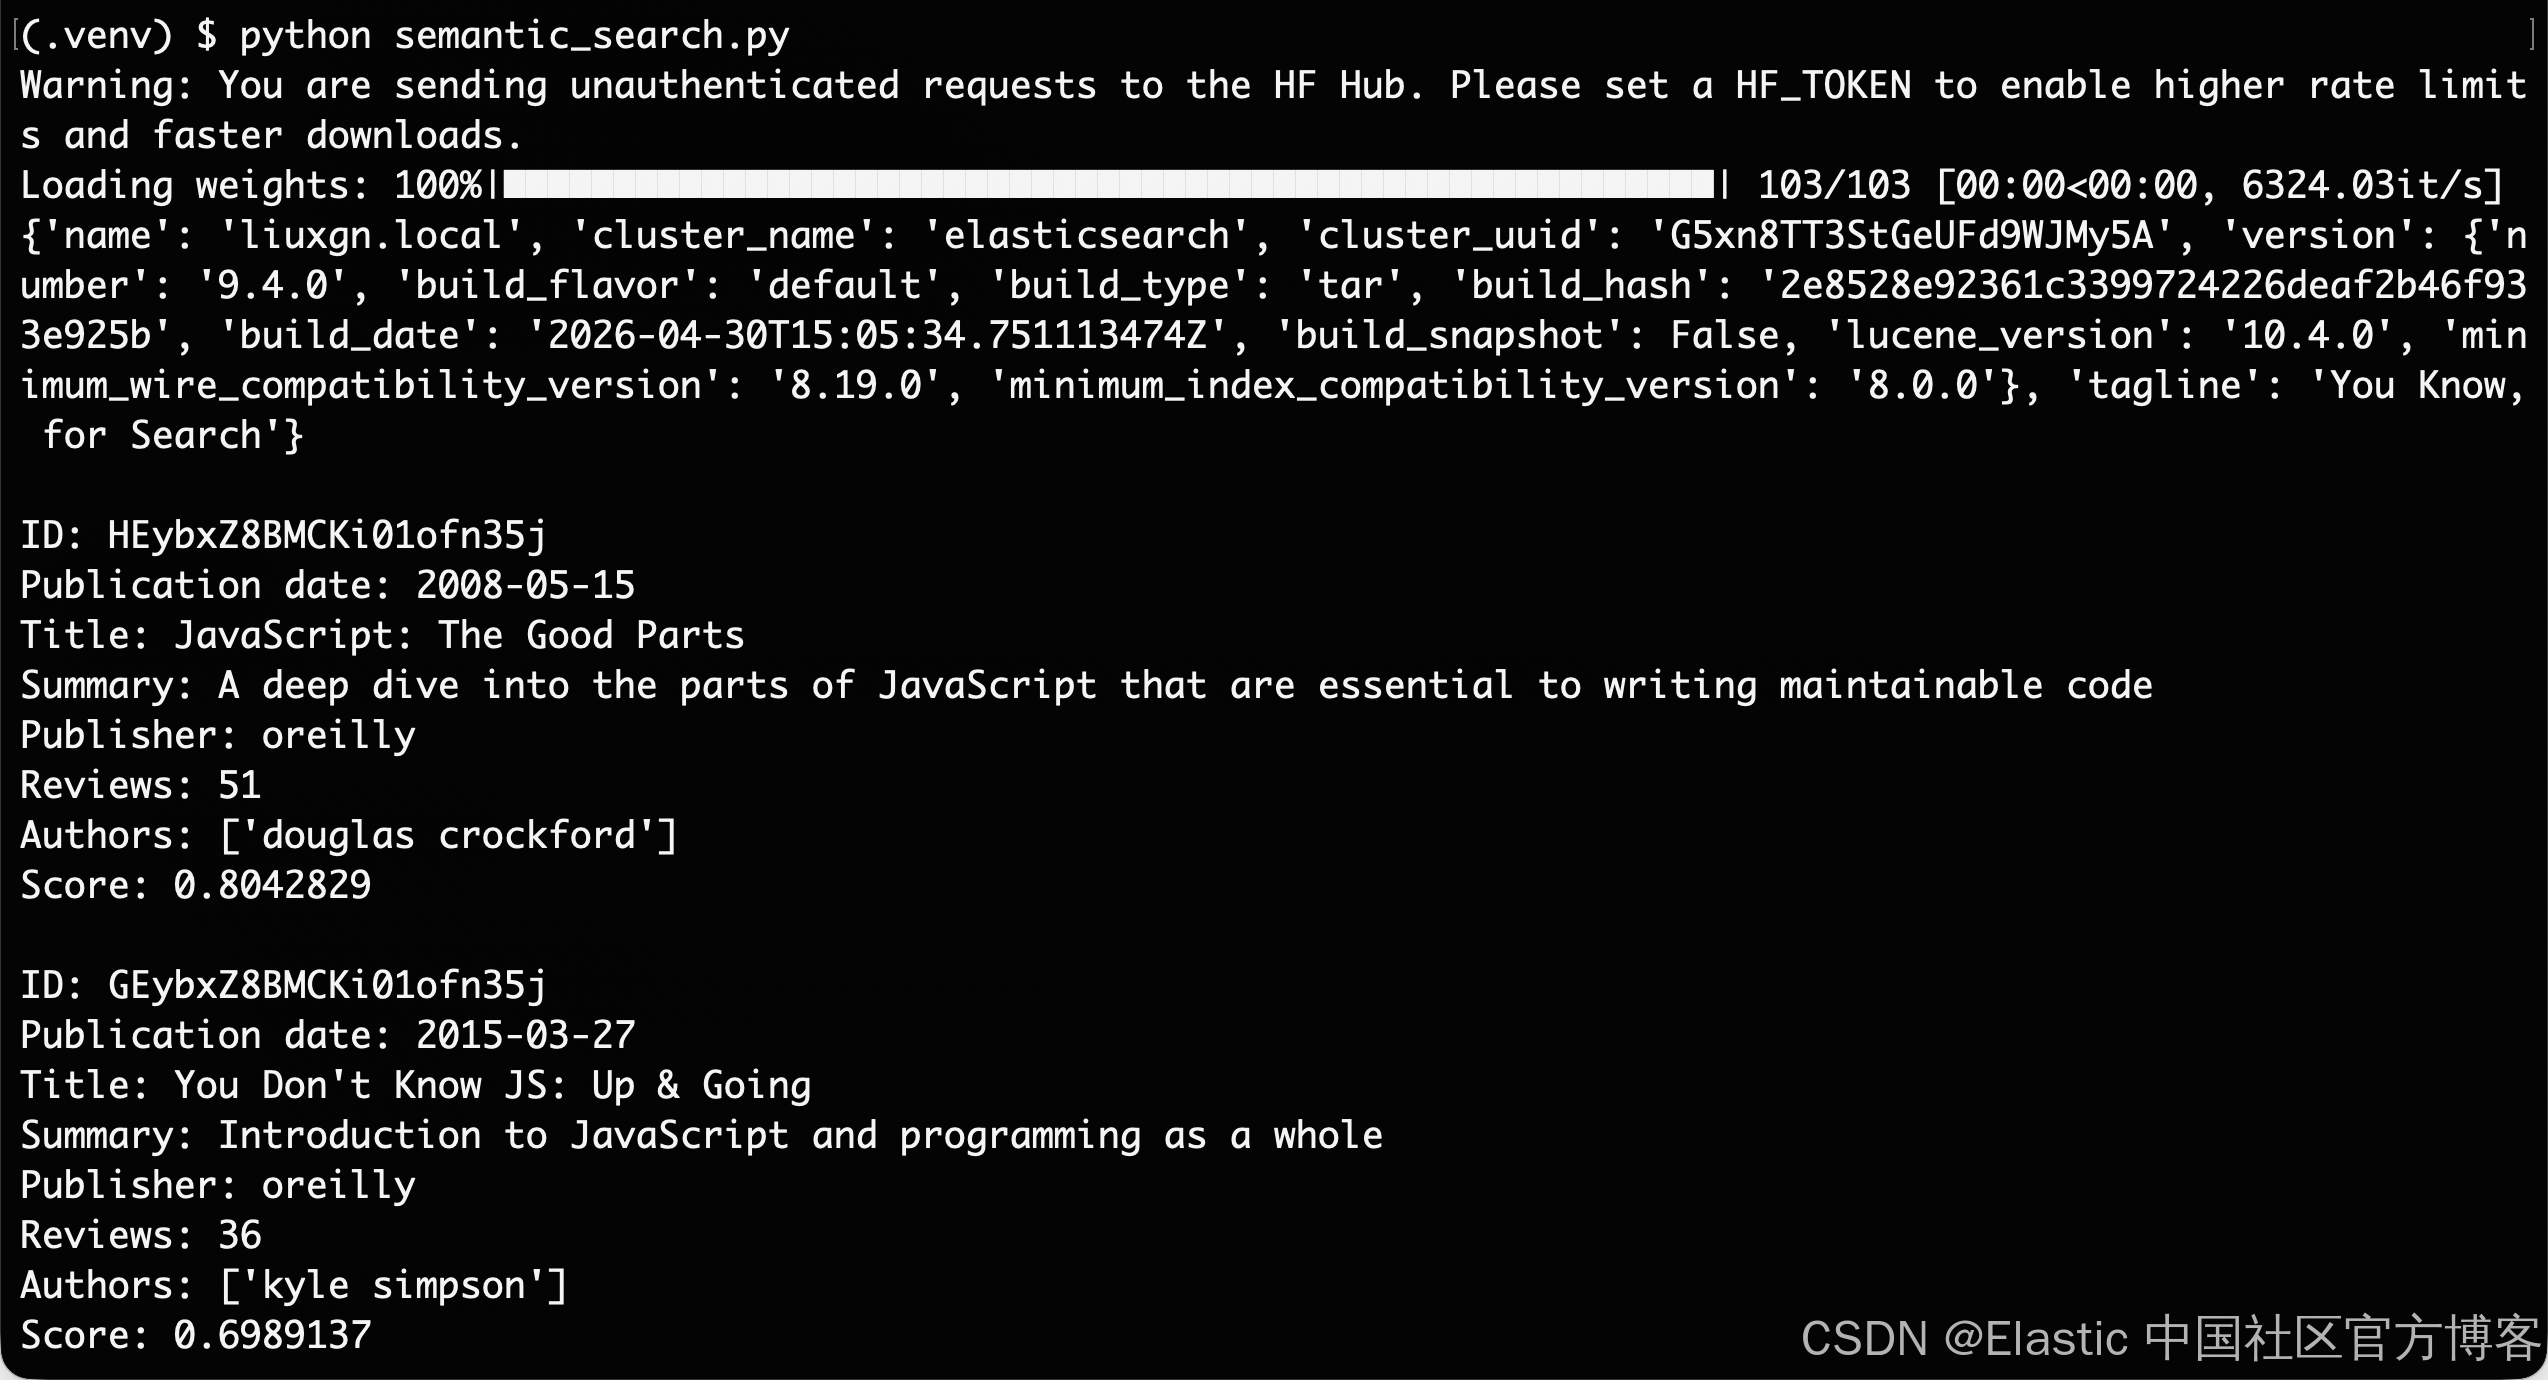
现在,我们已经对图书进行了索引,希望对与给定查询相似的图书执行语义搜索。我们会对查询进行嵌入,然后执行搜索。
response = client.search(
    index="book_index",
    knn={
        "field": "title_vector",
        "query_vector": model.encode("javascript books"),
        "k": 10,
        "num_candidates": 100,
    },
)

pretty_response(response)
结果:
得分:0.8042828
标题:JavaScript:优良部分
简介:深入探索 JavaScript 中对于编写可维护代码至关重要的部分
出版社:oreilly
得分:0.6989136
标题:你不知道的 JavaScript:入门
简介:JavaScript 和整体编程的介绍
出版社:oreilly
得分:0.6796988
标题:精通 JavaScript
简介:现代编程入门
出版社:no starch press
(其余结果略)
过滤
过滤上下文主要用于过滤结构化数据。例如,可以使用过滤上下文回答以下问题:
Does this timestamp fall into the range 2015 to 2016?
Is the status field set to "published"?
当查询子句传递给过滤参数时,例如 bool 查询中的 filter 或 must_not 参数,过滤上下文就会生效。
更多信息请参阅 Elasticsearch 文档中的过滤上下文。
示例:关键词过滤
下面示例展示如何向查询添加关键词过滤。
该示例根据标题向量检索与 "javascript books" 相似的热门图书,同时限制出版社为 Addison-Wesley。
response = client.search(
    index="book_index",
    knn={
        "field": "title_vector",
        "query_vector": model.encode("javascript books"),
        "k": 10,
        "num_candidates": 100,
        "filter": {"term": {"publisher.keyword": "addison-wesley"}},
    },
)

pretty_response(response)
结果:
得分:0.6206549
标题:The Pragmatic Programmer:Your Journey to Mastery
简介:面向软件工程师和开发者的实用编程指南
出版社:addison-wesley
得分:0.56499225
标题:设计模式:可复用面向对象软件的基础
简介:适用于任何面向对象语言的设计模式指南
出版社:addison-wesley