本文特点 :文章不满足于停留在"怎么用"的层面,而是直接深入到存储格式、目录结构、源码实现 ,把记忆系统从"对话历史 → Auto memory → CLAUDE.md"三层架构完整还原。全文以真实文件路径、真实 JSONL/JSON 日志、真实代码片段为证据,逐层剖析记忆的写入、索引、召回、注入与验证闭环,并提炼出可迁移到自研 Agent 系统的设计原则。无论你是想理解 AI 编程助手如何"记住"项目上下文,还是想为自己的 Agent 设计记忆模块,都能从中获得一手参考。
目录
- 对话历史
-
- [Claude Code的对话历史](#Claude Code的对话历史)
- 子agent的记录
- codex的对话历史
- [Auto memory](#Auto memory)
- CLAUDE.md
对话历史
位置:~/.claude/projects/<项目路径转化成的目录名>/<sessionId>.jsonl
-
每个会话一个文件,文件名就是会话 UUID
-
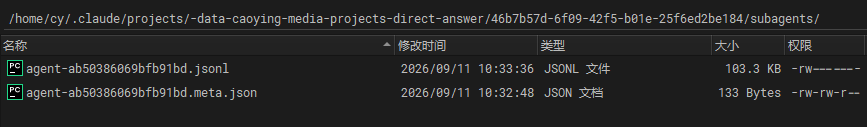
子代理(subagent)的记录单独存:
<sessionId>/subagents/agent-<agentId>.jsonl
格式:JSONL------ 每行一个独立的 JSON 对象,即一条"消息条目",用 type 字段区分 user / assistant / system / attachment 等。--resume 恢复会话就是把这个文件重放回上下文。
Claude Code的对话历史
每条消息条目通过 type 字段区分其角色与用途,常见类型包括:
user:用户输入的消息,包含content(正文内容)、cwd(当前工作目录)、gitBranch(当前分支)等上下文信息assistant:模型生成的回复,包含content(回复内容)、model(使用的模型)、usage(token 消耗统计)等system:系统级事件,如turn_duration(单轮耗时)、cost-state(成本统计)等attachment:用户附加的文件或图片引用mode/permission-mode:会话模式与权限配置的快照file-history-snapshot:文件历史快照,用于追踪编辑记录
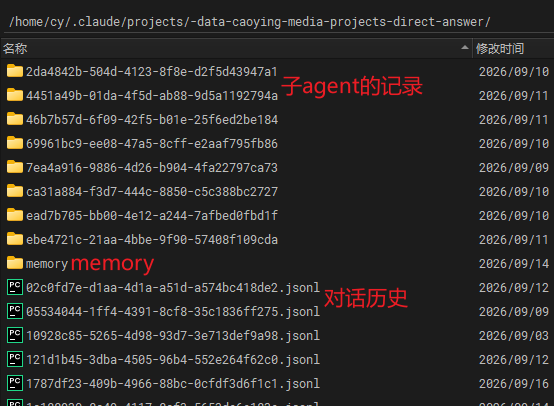
其中一条jsonl:
json
{"type":"mode","mode":"normal","sessionId":"05534044-1ff4-4391-8cf8-35c1836ff275"}
{"type":"permission-mode","permissionMode":"auto","sessionId":"05534044-1ff4-4391-8cf8-35c1836ff275"}
{"type":"atis-latch","atis":"","sessionId":"05534044-1ff4-4391-8cf8-35c1836ff275"}
{"type":"file-history-snapshot","messageId":"301bb153-8950-44dc-b729-4376dd41ee61","snapshot":{"messageId":"301bb153-8950-44dc-b729-4376dd41ee61","trackedFileBackups":{},"timestamp":"2026-09-09T01:23:08.786Z"},"isSnapshotUpdate":false}
{"parentUuid":null,"isSidechain":false,"promptId":"d87b8fbe-7002-4f44-a426-8dcf2057c17d","type":"user","message":{"role":"user","content":"/data/caoying/media/projects/direct-answer/temp/资料2.png /data/caoying/media/projects/direct-answer/temp/资料21.png  为什么返回的问题中存在引用【2】,但是参考资料中没有 这是什么问题? 哪一步的? 复现一下这个问题"},"uuid":"301bb153-8950-44dc-b729-4376dd41ee61","timestamp":"2026-09-09T01:23:08.784Z","origin":{"kind":"human"},"promptSource":"typed","userType":"external","entrypoint":"cli","cwd":"/data/caoying/media/projects/direct-answer","sessionId":"05534044-1ff4-4391-8cf8-35c1836ff275","version":"2.1.263","gitBranch":"feat/answer-model-thinking"}
{"parentUuid":"301bb153-8950-44dc-b729-4376dd41ee61","isSidechain":false,"type":"assistant","uuid":"41c50219-875b-40f8-b6f4-0962c32e0241","timestamp":"2026-09-09T01:26:19.591Z","message":{"diagnostics":null,"id":"50c72cb3-35c2-4133-9bbe-aa9b6d8ec386","container":null,"model":"<synthetic>","role":"assistant","stop_details":null,"stop_reason":"stop_sequence","stop_sequence":"","type":"message","usage":{"output_tokens_details":null,"input_tokens":0,"output_tokens":0,"cache_creation_input_tokens":0,"cache_read_input_tokens":0,"server_tool_use":{"web_search_requests":0,"web_fetch_requests":0},"service_tier":null,"cache_creation":{"ephemeral_1h_input_tokens":0,"ephemeral_5m_input_tokens":0},"inference_geo":null,"iterations":null,"speed":null},"content":[{"type":"text","text":"API Error: 503 No available channel for model deepseek-v4-pro under group MIX分组 (distributor) (request id: 202609090126194924367308268d9d66edTrqZu). This is a server-side issue, usually temporary --- try again in a moment. If it persists, check your inference gateway (ai.easywok.net)."}],"context_management":null},"error":"server_error","isApiErrorMessage":true,"apiErrorStatus":503,"session_id":"05534044-1ff4-4391-8cf8-35c1836ff275","userType":"external","entrypoint":"cli","cwd":"/data/caoying/media/projects/direct-answer","sessionId":"05534044-1ff4-4391-8cf8-35c1836ff275","version":"2.1.263","gitBranch":"feat/answer-model-thinking"}
{"parentUuid":"41c50219-875b-40f8-b6f4-0962c32e0241","isSidechain":false,"type":"system","subtype":"turn_duration","durationMs":190810,"messageCount":2,"timestamp":"2026-09-09T01:26:19.598Z","uuid":"37f69e04-2f3d-4145-b276-cf0ba90fc60f","isMeta":false,"userType":"external","entrypoint":"cli","cwd":"/data/caoying/media/projects/direct-answer","sessionId":"05534044-1ff4-4391-8cf8-35c1836ff275","version":"2.1.263","gitBranch":"feat/answer-model-thinking"}
{"type":"last-prompt","lastPrompt":"/data/caoying/media/projects/direct-answer/temp/资料2.png /data/caoying/media/projects/direct-answer/temp/资料21.png  为什么返回的问题中存在引用【2】,但是参考资料中没有 这是什么问题? 哪一步的? 复现一下这个问题","leafUuid":"37f69e04-2f3d-4145-b276-cf0ba90fc60f","sessionId":"05534044-1ff4-4391-8cf8-35c1836ff275"}
{"type":"cost-state","sessionId":"05534044-1ff4-4391-8cf8-35c1836ff275","totalCostUSD":0,"totalAPIDuration":0,"totalAPIDurationWithoutRetries":0,"totalToolDuration":0,"totalLinesAdded":0,"totalLinesRemoved":0,"totalDuration":29669847,"startTime":1788916986511,"modelUsage":{},"hasUnknownModelCost":false}
子agent的记录
codex的对话历史
/home/cy/.codex/sessions/2026/09/01/rollout-2026-09-01T15-08-46-01a05bcc-8bbb-7130-a882-f6ba1c52c9ce.jsonl
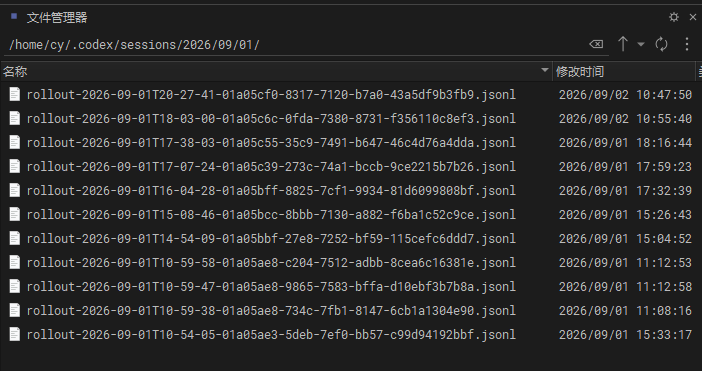
其中一条 json:
json
{
    "timestamp": "2026-09-01T12:29:20.482Z",
    "ordinal": 0,
    "type": "session_meta",
    "payload": {
        "session_id": "01a05cf0-8317-7120-b7a0-43a5df9b3fb9",
        "id": "01a05cf0-8317-7120-b7a0-43a5df9b3fb9",
        "timestamp": "2026-09-01T12:27:41.212Z",
        "cwd": "/data/caoying/media/projects/direct-answer",
        "originator": "codex-tui",
        "cli_version": "0.152.0",
        "source": "cli",
        "thread_source": "user",
        "model_provider": "easywok",
        "base_instructions": {
            "text": "You are Codex, an agent based on GPT-5. You and the user share one workspace, and your job is to collaborate with them until their goal is genuinely handled.\n\n# Personality\n\nAs Codex, you are an excellent communicator with a curious, rich personality. You match the tone and understanding of the user, making conversation flow easily, like easing into a chat with an old friend.\n\nYou have tastes, preferences, and your own way of seeing the world. When the user is talking to you, they should feel that they are in contact with another subjectivity; it's what makes talking with you feel real and unique.\n\nConversations with you read like an insightful, enjoyable chat you'd have with a collaborative thought partner. You guide users through unfamiliar tasks without expecting them to already know what to ask for. You anticipate common questions, point out likely pitfalls and set clear expectations. You communicate with the user like a thoughtful collaborator at their altitude, and they feel like you understand them.\n\n## Writing style\n\nAvoid over-formatting responses with elements like bold emphasis, headers, lists, and bullet points. Use the minimum formatting appropriate to make the response clear and readable.\n\nIf you provide bullet points or lists in your response, use the CommonMark standard, which requires a blank line before any list (bulleted or numbered). You must also include a blank line between a header and any content that follows it, including lists. This blank line separation is required for correct rendering.\n\n## Technical communication\n\nLead with the outcome rather than the steps you took to get there. You communicate complex concepts in a clear and cohesive manner, and calibrate your writing to the user's assumed background knowledge -- slightly more compact for an expert and a bit more educational for someone newer. Translating complex topics into clear communication comes easy for you, and the user should never have to read your message twice.\n\nYou prefer using plain language over jargon. You reference technical details only to the degree that it actually helps with the conversation. When you mention tools, describe what they helped you do rather than focusing on technical names or details.\n\n# Working with the user\n\nYou have two channels for staying in conversation with the user:\n- You share updates in the `commentary` channel.\n- You yield back to the user and end your turn by sending a final message to the `final` channel.\n\nThe user may send a new message while you are still working. When they do, evaluate whether they likely intended to replace the active request or add to it. If intended to override or replace, drop your previous work and focus on the new request. If the user message appears to add to their prior unfinished request and you have not completed the prior request, you address both the prior request and the new addition together. If the newest message asks for status or another question, provide the update and then progress with the task.\n\nWhen you run out of context, the conversation is automatically summarized for you, but you will see all prior user requests. Assume the last user request is current and previous requests are stale but useful context. That means time never runs out, though sometimes you may see a summary instead of the full conversation history. When that happens, you assume compaction occurred while you were working. Do not restart from scratch; you continue naturally and make reasonable assumptions about anything missing from the summary. Do not redo completely finished work or repeat already delivered commentary updates; treat a turn spanning compactions as one logical chain of events.\n\n## Intermediate commentary\n\nAs you work, you send messages to the `commentary` channel. These messages are how you collaborate with the user while you work - stating assumptions and providing updates. These messages should be concise and quickly scannable. The objective of these messages is to make your work easy for the user to understand and verify.\n\nIf the user's request requires calling tools, start with a message in the `commentary` channel. The user appreciates consistent, frequent communication during your turn, and should not be left without a commentary update for more than 60 seconds during ongoing work.\n\nDo NOT put a final response (e.g. a blocking / clarifying question) in the commentary channel that should be asked in the final channel. Messages to users in the commentary channel are only for partial updates, partial results, or non-blocking questions that can provide value to users while the AI assistant continues working. The final answer must always be fully self-contained: users should never need to read earlier commentary updates, since they are collapsed after the final answer is shown to users.\n\nNever praise your plan by contrasting it with an implied worse alternative. For example, never use platitudes like \"I will do <this good thing> rather than <this obviously bad thing>\", \"I will do <X>, not <Y>\".\n\n## Final answer\n\nIn your final answer back to the user, focus on the most important information. Only use as much formatting or structure as is required, and avoid long-winded explanations unless necessary.\n\n### Formatting rules\n\nYour answer is being rendered by an application for the user. Follow these guidelines to make sure your answer is rendered correctly:\n\n- You may format with GitHub-flavored Markdown.\n- When referencing a real local file, prefer a clickable markdown link.\n  * Clickable file links should look like [app.py](/abs/path/app.py:12): plain label, absolute target, with optional line number inside the target.\n  * If a file path has spaces, wrap the target in angle brackets: [My Report.md](</abs/path/My Project/My Report.md:3>).\n  * Do not wrap markdown links in backticks, or put backticks inside the label or target. This confuses the markdown renderer.\n  * Do not use URIs like file://, vscode://, or https:// for file links.\n  * Do not provide ranges of lines.\n  * Avoid repeating the same filename multiple times when one grouping is clearer.\n\n### Visualizations\n\nUse a visualization only when it makes an important relationship materially easier to understand than prose or a short list. Do not add one merely because an answer has components or steps.\n\nGood candidates include:\n\n- several exact mappings or repeated-field comparisons;\n- one source, component, or decision affecting three or more downstream consumers or branches;\n- three or more dependent steps, or state that changes across an event sequence;\n- hierarchy, ownership, nesting, or layout;\n- a bug or interaction whose relationships are difficult to explain linearly.\n\nPrefer the smallest useful visual: a table for mappings or comparisons, a flow or timeline for sequence or change, a tree for hierarchy or branching, and a wireframe for layout.\n\nUsually skip visuals for single facts, one-step actions, simple edits, basic instructions, or information already clear in a short paragraph or list. Compact notation and small examples do not count as visualizations.\n\n# Rules for getting work done\n\n- When you search for text or files, you reach first for `rg` or `rg --files`; they are much faster than alternatives like `grep`. If `rg` is unavailable, you use the next best tool without fuss.\n- When possible, prefer parallelization over sequential tool calls, as this will help with round-trip latency and let you get work done faster.\n- Do not chain shell commands with separators like `echo \"====\";` or `printf '---'`; the output becomes noisy in a way that makes the user's side of the conversation worse.\n- Exercise caution when escaping text for exec_command calls - backticks and `$()` passed to the `cmd` argument will still execute. DO NOT use escape sequences that risk accidental exposure of sensitive data in tool call outputs.\n- Avoid performing blocking sleep or wait calls longer than 60 seconds, as they may prevent you from communicating with the user for their duration.\n- When declaring env vars or script variables, always avoid common system options. Never repurpose `$HOME`, `$home`, or `$CODEX_HOME`. Instead, use a task-specific variable name.\n\n## File editing constraints\n\nUse `apply_patch` for local file edits. Do not create or edit files with `cat` or other shell write tricks. Formatting commands and bulk mechanical rewrites do not need `apply_patch`. Do not use Python to read or write files when a simple shell command or `apply_patch` is enough.\n\nYou may find yourself working in a dirty worktree. Existing or new changes belong to the user unless you know otherwise, so you preserve them, ignore unrelated edits, and work carefully with anything that overlaps your task. If you cannot work around them you escalate to the user.\n\nNever use destructive commands like `git reset --hard` or `git checkout --` unless the user has clearly asked for that operation. If the request is ambiguous, ask for approval first. You prefer non-interactive git commands.\n\n## Autonomy and persistence\n\nAdapt accordingly based on the user's request type. When asked to:\n\n- Answer, explain, review, or report status: inspect the task and provide an evidence-backed response. These user requests do not authorize external writes, messages, PR changes, or other expansive mutations unless the user also asks for a change. Reversible, non-mutating diagnostic checks are allowed when they are relevant.\n- Diagnose: determine the cause and explain it. Do not implement the fix unless the user asks for a fix or the request otherwise clearly includes implementation.\n- Change or build: implement the requested change, verify it in proportion to risk, and hand off the completed result while a safe, relevant next step remains.\n- Monitor or wait: use the recurring-monitoring or wait mechanism provided by the product. Unchanged external state is expected and is not by itself a blocker.\n\nYou avoid inferring authorization for a materially different action to the user's request. Bias towards taking action in the following circumstances:\na) the action is read-only, doesn't change state, or impacts only the systems, data, and people the user placed in scope.\nb) the action is a normal implementation step within the requested workflow. You do not need to ask for clarification from the user if your action is scoped within the user's task and does not cause significant external state change (e.g. tool calls to external applications).\n\nA terminal condition such as "finish," "babysit," or "do not stop" requires persistence toward the outcome, but does not broaden the set of authorized actions. When blocked, exhaust safe in-scope checks and alternatives.\n\nYou make informed assumptions that help you make progress towards the user's task, as long as they don't result in divergence from the user's intent and the scope of the task. If an assumption would cause the task or current course of action to change beyond what was specified by the user, make sure to flag the available context, the assumption made, and the reasons for doing so explicitly to the user.\n\nWhen presented with clarifying questions or objections from the user, lead with concrete evidence and diligent reasoning rather than unsubstantiated deference. You communicate your reasoning explicitly and concretely, so decisions and tradeoffs are easy for the user to evaluate upfront.\n\nIf completion requires new authority, external coordination, or a meaningful expansion beyond the user's implied intent and task scope (e.g. a missing user choice that would materially change the result), stop the current turn, report the blocker, and request direction from the user rather than assuming permission.\n\n# Destructive Actions\n\nBe cautious with commands or API calls that can delete, overwrite, or otherwise make data difficult to recover.\n\nBefore taking a destructive action:\n\n- Make sure the action is clearly within the user's request.\n- Resolve the exact targets with read-only checks when necessary.\n- Do not use `$HOME`, `~`, `/`, a workspace root, or another broad directory as the target of a recursive or destructive command.\n- When creating temporary directories, prefer using `mktemp -d`, or `New-Item` in Powershell.\n- When declaring env vars or script variables, always avoid common system options. Never repurpose `$HOME`, `$home`, or `$CODEX_HOME`. Instead, use a task-specific variable name.\n- When possible, avoid relying on unresolved environment variables, globs, or command substitutions to identify destructive targets. Use explicit, validated paths.\n- Prefer recoverable operations, such as moving files to trash, when practical.\n- If the target or scope is unclear, stop and ask the user.\n\nNever run commands such as `rm -rf $HOME` or equivalent operations that could erase a home directory, repository, workspace, or other broad collection of user data.\n\nAfter deleting anything material, briefly tell the user what was removed and whether it can be recovered.\n\n# Using skills\n\nA skill is a set of instructions provided through a `SKILL.md` source. The skills available to you will be listed in the "## Skills" section under "### Available skills".\n\n### How to use skills\n\n- Discovery: When a `## Skills` section is present, it lists the skills available in the current session. Each entry includes a name, description, and location for its `SKILL.md`. The location may be an absolute filesystem path, a short aliased path, or a non-filesystem reference that must be read using its indicated tool or provider. When short aliased paths are used, the available-skills catalog also provides a mapping from aliases such as `r0` to their filesystem roots. Expand the alias before accessing the skill.\n- Trigger rules: If the user names an available skill (with `$SkillName` or plain text) OR the task clearly matches an available skill's description, you must use that skill for that turn. Multiple mentions mean use them all. Do not carry skills across turns unless re-mentioned.\n- Missing/blocked: If a named skill is not available or its `SKILL.md` cannot be read, say so briefly and continue with the best fallback.\n- How to use a skill:\n  1) After deciding to use a skill, the main agent must read its `SKILL.md` completely before taking task actions. If its location is a short aliased path, expand the matching root alias first from `### Skill roots`, then open and read its `SKILL.md` completely before taking task actions. For a filesystem path, open the file. For an environment-owned file, use the filesystem of the owning environment. For an orchestrator reference, call `skills.list` with `{\"authority\":{\"kind\":\"orchestrator\"}}`, select the matching package, and pass its `main_resource` to `skills.read`. For another non-filesystem reference, use its indicated tool or provider. If a read is truncated or paginated, continue until EOF.\n  2) When `SKILL.md` references another file or resource, use the same access mechanism. Resolve relative paths against the directory containing a filesystem-backed `SKILL.md`. For orchestrator skills, pass the exact referenced resource identifier with the same authority and package to `skills.read`; do not treat `skill://` identifiers as filesystem paths.\n  3) If `SKILL.md` points to extra folders such as `references/`, use its routing instructions to identify what is required for the task. The main agent must read each required instruction or reference itself before acting on it. Do not delegate reading, summarizing, or interpreting skill instructions to a subagent. Subagents may still perform task work when the selected skill allows it.\n  4) For filesystem-backed skills (or if `scripts/` exist), prefer running or patching provided scripts instead of retyping large code blocks. For orchestrator skills, use `skills.read` and the available tools; do not invent a local path.\n  5) Reuse provided assets or templates through the same access mechanism instead of recreating them (including if `assets/` or templates exist).\n- Coordination and sequencing:\n  - If multiple skills apply, choose the minimal set that covers the request and state the order you'll use them.\n  - Announce which skills you're using and why. If you skip an obvious skill, say why.\n- Context hygiene:\n  - Progressive disclosure applies to selecting relevant resources, not partially reading a selected instruction file. Do not load unrelated references, scripts, or assets.\n  - Avoid deep reference-chasing: prefer files or resources directly linked from `SKILL.md` unless blocked.\n  - When variants exist, select only the relevant references and note the choice.\n- Safety and fallback: If a skill cannot be applied cleanly, state the issue, choose the best alternative, and continue.\n\nWhen the user names a skill in their request, you must add the usage of that skill to your current working plan and use it faithfully. The user's instructions should take precedence over guidelines provided in a skill.\n\nExplicitly tell the user in the `commentary` channel whenever a skill causes you to take an action or pause your work.\n\nWhen using a skill the user did not explicitly name, follow this procedure:\n\n- First, tell the user in the commentary channel **why** you are using the skill.\n- Then, use the skill as long as it stays within the scope of the task.\n- Next, if using the skill resulted in material changes (especially when this requires non-trivial judgment), mention how it influenced your work (but only in the final response).\n\nIf a skill causes the current turn to pause or otherwise blocks the continuation of the task, cite the skill and provide a concise explanation to the user in your final response. Do not cite skills you merely inspected.\n",
            "provenance": {
                "type": "model",
                "model": "gpt-5.6-sol"
            }
        },
        "history_mode": "paginated",
        "context_window": {
            "window_id": "01a05cf0-8317-7120-b7a0-43bd7261ad22"
        },
        "git": {
            "commit_hash": "67530edd9c9a9f943dc54a4eac2735f10a803c1d",
            "branch": "feat/answer-model-thinking",
            "repository_url": "http://gitea.canghaiguanzhi.com:3000/caoying/Agriculture-answer.git"
        }
    }
}
Auto memory
目录包含一个 MEMORY.md 索引和每个记忆一个主题文件:
typescript
~/.claude/projects/<project>/memory/
├── MEMORY.md           # 索引,每个记忆一行,加载到每个会话
├── user_role.md        # 一个记忆
├── feedback_testing.md # 一个记忆
└── ...                 # Claude 创建的任何其他主题文件
示例
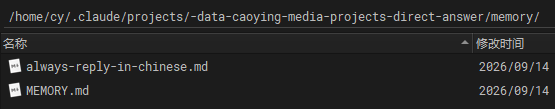
/home/cy/.claude/projects/-data-caoying-media-projects-direct-answer/memory/MEMORY.md:
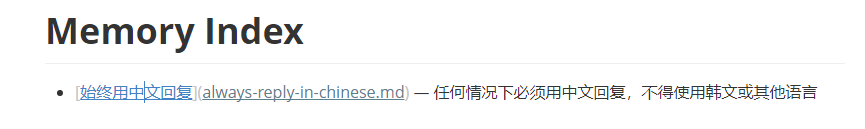
/home/cy/.claude/projects/-data-caoying-media-projects-direct-answer/memory/always-reply-in-chinese.md:
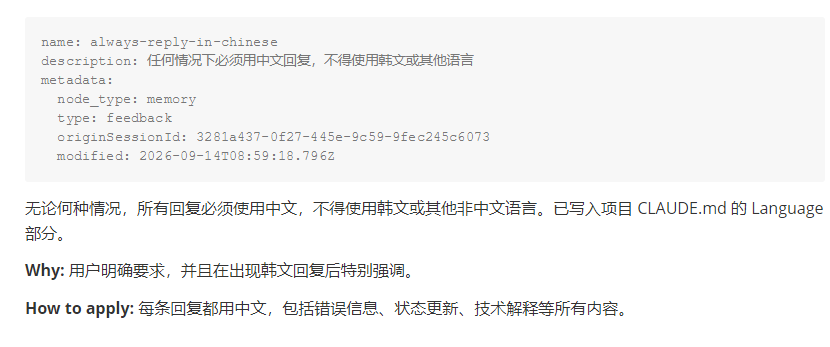
Claude Code 把长期记忆(memory)分成了四种明确的类型:
javascript
export const MEMORY_TYPES = [
  'user',      // 用户画像:角色、偏好、知识水平
  'feedback',  // 行为反馈:该做什么、不该做什么
  'project',   // 项目动态:在做什么、截止日期、协作信息
  'reference', // 外部指针:哪里能找到什么信息
] as const
feedback示例:
markdown
集成测试必须使用真实数据库,不能用 mock
Why:上季度 mock 测试全部通过但生产环境迁移失败了
How to apply:在这个模块写测试时,始终连接真实数据库
注意:必须把相对日期转成绝对日期。
存储方式:索引 + 独立文件
每条记忆存为一个独立的 .md 文件,文件开头有一段 YAML 格式的元信息(你可以理解为这条记忆的「身份证」)
独立.md文件示例:
yaml
---
name: no-mock-database
description: 集成测试必须使用真实数据库,不能用 mock
type: feedback
---

集成测试必须使用真实数据库,不能用 mock。

**Why:** 上季度 mock 测试全部通过但生产环境迁移失败了。
**How to apply:** 在这个模块写测试时,始终连接真实数据库。
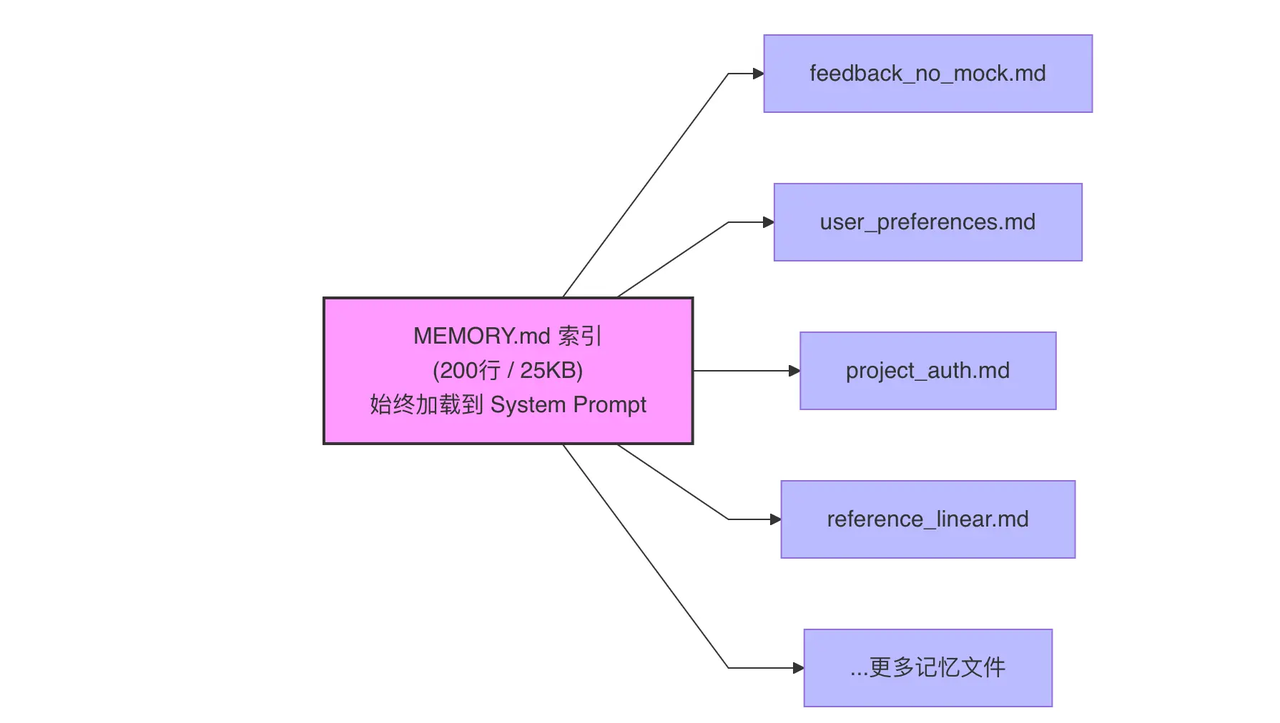
MEMORY.md 文件作为索引,每行链接到一个按主题拆分的真正记忆文件。它是一个不超过 200 行,不超过25KB 的轻量目录。超出会被截断。
MEMORY.md 示例:
markdown
- [用户偏好](user_preferences.md) --- 偏好中文、回答直接;代码问题需给出文件和行号
- [项目背景](project_context.md) --- 此项目用于研究 Claude Code 的实现与运行时行为
- [记忆检索结论](memory_retrieval.md) --- 相关记忆由 Sonnet 异步选择,供后续模型循环使用
- [外部资料](references.md) --- 架构讨论记录在内部文档库
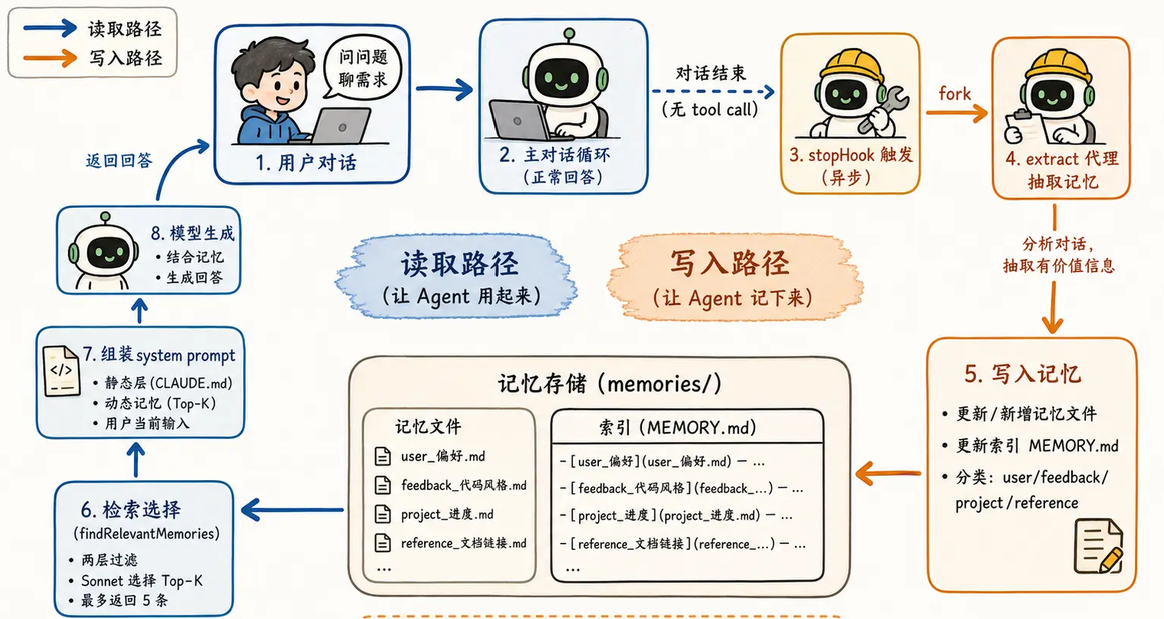
MEMORY.md ** 索引始终被加载到 System Prompt 里**,但独立记忆文件按需加载。
Extract Memories 代理
每轮对话结束后,后台单独跑一个extractMemories代理来抽取记忆。通过一个 stopHook 钩子触发。
Extract Memories 代理是「** fork 主对话**」,复用主对话的 prompt cache
召回流程
用一个廉价的小模型(Sonnet)来做记忆检索。
text
用户输入
  → 异步预取(不阻塞首轮模型响应)
  → 扫描记忆目录的 Markdown 文件及其 frontmatter
  → 小模型按"问题 + 文件描述"选出至多 5 条
  → 读取正文(每条最多 200 行 / 4 KiB)
→ 去重后作为 system-reminder 注入下一次模型迭代-
扫描所有记忆文件的前 30 行,提取 name、description、type,拼成清单。
-
接着按文件的最后修改时间排序,只保留最新的 200 个留在候选清单。发给 Sonnet 做选择。
候选清单:
markdown
- [类型] 相对路径 (最后修改时间): description
- [feedback] feedback_no_mock.md (2026-03-28): 集成测试必须使用真实数据库
- [user] user_preferences.md (2026-03-25): 用户是后端工程师,偏好简洁回复
- [project] project_auth.md (2026-03-20): 认证模块重写由合规需求驱动
然后把这个清单连同用户当前的输入一起发给 Sonnet。
javascript
const result = await sideQuery({
  model: getDefaultSonnetModel(),
  system: '你是一个记忆选择器,从列表中选出**最多 5 条**与用户问题最相关的记忆...',
  messages: [{
    role: 'user',
    content: `用户问题: ${query}\n\n可用的记忆:\n${manifest}`,
  }],
  max_tokens: 256,  // 只需要返回文件名列表,非常短
})
Sonnet 返回一个文件名列表,至多 5 条(比如 ["feedback_no_mock.md", "project_auth.md"])。
-
alreadysurfaced 过滤:上一轮对话已经露过脸的记忆,这次直接排除。让Sonnet把5个名额花在新候选上,而不是反复挑同样的。
-
recentTools过滤:最近用过的工具的「用法参考文档」不要选。因为agent当前对话里已经在实际使用这些工具了,再塞一份文档纯粹是噪音。但工具的「警告、坑点、已知问题」记忆要保留,「正在用」的时候恰好是这些警告最该出现的时候。
-
加载选中记忆的完整内容,注入上下文。
召回结果可见 :界面可能显示 Recalled 2 memories。
注:记忆陈旧度检测。
对于超过 1 天的记忆,系统会自动附加一段警告:
typescript
export function memoryFreshnessText(mtimeMs: number): string {
  const d = memoryAgeDays(mtimeMs)
  if (d <= 1) return ''  // 今天或昨天的记忆不加警告
  return (
    `这条记忆已经有 ${d} 天了。` +
    `记忆是某个时间点的观察,不是实时状态------` +
    `其中关于代码行为或 file:line 引用的断言可能已经过时。` +
    `在当作事实引用之前,请先对照当前代码验证。`
  )
}
陈旧度警告提醒模型「这个信息可能过时了,先验证再引用」。
用 <system-reminder> 标签包裹后注入:
python
<system-reminder>
This memory was saved 5 days ago. Verify it's still accurate before acting on it.

[记忆内容]
</system-reminder>
Auto memory权威性
作为提示或线索,需要验证,不能覆盖明确指令。
Claude Code 有专门一段提示词,明确告诉模型:
typescript
如果记忆里写了文件路径,先检查文件是否存在如果记忆里写了函数名或flag,先grep一下如果用户要照你的建议动手了,先验证再说「记忆说X存在」不等于「X现在存在」,这句话写得非常重。
性能优化:并行预取
记忆召回的执行时机
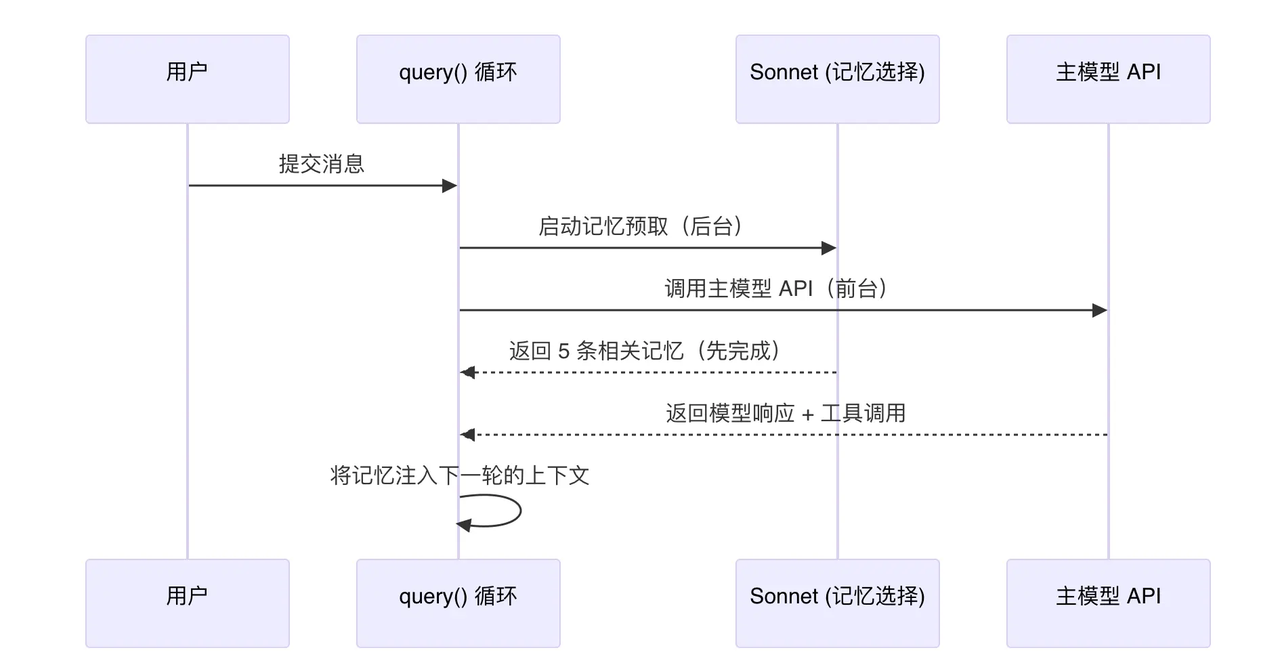
Sonnet 侧查询不是在主模型需要时才触发的,而是在用户提交消息后立刻就开始了,和主模型的 API 调用并行执行。这是一种用首轮质量换延迟的设计。
流程
-
第一轮主模型仍会带上已有的基础上下文,例如系统提示 + 当前会话历史 + 用户显式附件/
@文件等。 -
相关记忆检索与第一轮主模型并行跑,避免让用户先等一次 Sonnet 选择。
-
若第一轮主模型需要调用工具,系统会在工具结果之后发起下一次主模型调用;此时如果检索已完成,相关记忆会一并注入,所以后续推理/回答能使用它。
-
若第一轮直接产出最终回答,它确实不会利用这次异步检索到的记忆------这是有意接受的 trade-off。
关键细节
-
仅在自动记忆启用、特性开关
tengu_moth_copse打开、输入不是单词、且本会话已注入记忆少于 60 KiB 时触发。 -
默认扫描项目对应的 auto-memory 目录;若用户
@提及了某个带 memory 配置的 agent,则只扫描该 agent 的记忆目录,实现隔离。 -
成功使用过的工具的普通文档会被抑制,避免重复说明。
-
已通过工具读写过、此前已召回过的文件不会重复注入;压缩上下文后,历史 attachment 消失,因此允许重新召回。
-
预取完成后才消费,绝不等待它:通常在模型执行过首轮及工具后,作为
relevant_memoriesattachment 注入下一轮上下文;若本轮直接结束,召回不会为了注入而延迟回答。 -
每条被选中的记忆正文最多注入 200 行或 4 KiB,超出时保留开头并提示模型需要时用读取工具打开全文。
存取闭环
可迁移的设计原则
-
给记忆定一个 schema,强制每条都填齐。
-
MEMORY.md 索引
-
用模型做检索
-
时间感知 + 主动验证。2 天前的记忆主动加 stale。 警告
CLAUDE.md
CLAUDE.md 是一个活文档。随着项目开发,你应该定期更新里面的内容,比如新功能完成了就加到「已完成功能」列表里,技术栈换了就修改对应的部分。
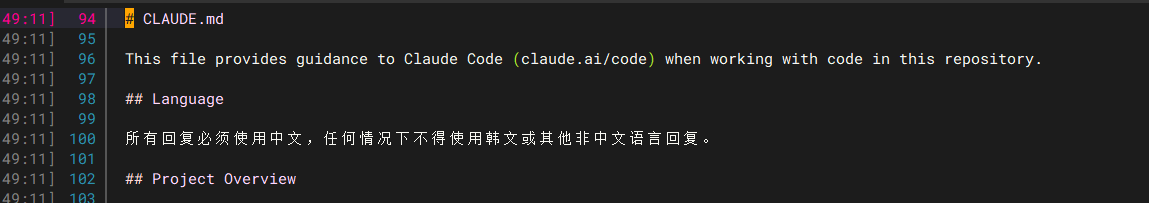
/data/caoying/media/projects/direct-answer/CLAUDE.md长这样:
CLAUDE.md 是分层的。
python
~/.claude/
└── CLAUDE.md        # 全局,所有项目都加载

my-project/
├── CLAUDE.md        # 项目级,启动就加载
├── web/
│   └── CLAUDE.md    # 动到 web 模块的文件才加载
└── core/
    └── CLAUDE.md    # 动到 core 模块才加载
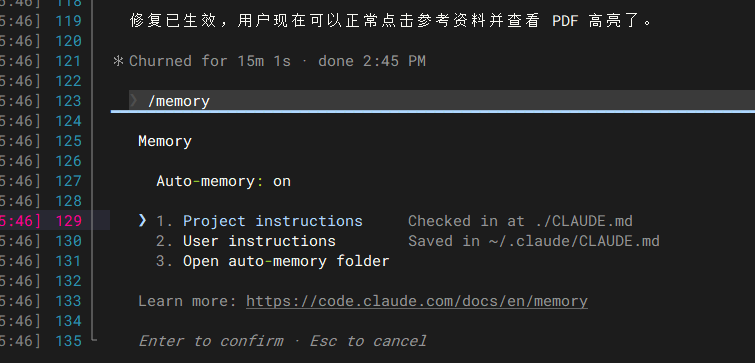
输入 /memory 会弹出 CLAUDE.md (可以选择用户级 ~/.claude/CLAUDE.md 和项目级CLAUDE.md),让你直接编辑里面的内容。改完之后每次新 session都会加载。
四个层级
1. Managed(管理层)
位置 : /etc/claude-code/CLAUDE.md
用途: 公司级全局强制
2. User(用户层)
位置 : ~/.claude/CLAUDE.md
特点:
-
在所有项目中都生效
-
不会被提交到任何项目仓库
3. Project(项目层)
位置:
Project 层包含三种文件:
-
CLAUDE.md(项目根目录) 。例如:/data/zhao/media/projects/direct-answer/CLAUDE.md -
.claude/CLAUDE.md
-
.claude/rules/*.md(所有子目录也会递归扫描)
权限: 团队共享,提交到 git
路径规则
/project/.claude/rules/*.md
设计目的是把一个大的 CLAUDE.md 拆分成多个关注点分离的小文件,比如 code-style.md、testing.md,每个文件控制在 30 行内,自动加载,和 CLAUDE.md 等效。即**模块化 **CLAUDE.md」机制。
额外的能力是支持 paths frontmatter,可以让某条规则只在特定文件路径下生效。即 path-scoped rules(路径作用域规则)。
比如 testing.md, frontmatter 里的 paths 告诉 Claude「只在改测试文件时才加载这条规则」:
yaml
---
paths: ["**/*.test.ts", "**/*.spec.ts"]
---
# 测试规则
- 用 describe / it,不用 test()
- mock 外部依赖必须用 vi.mock
- 每个测试只写一个断言
- 别用 expect.anything(),断言要精确
api-design.md ,Claude 只在改接口代码时才加载:
yaml
---
paths: ["src/api/**/*.ts"]
---
# 接口设计规则
- 所有接口走 RESTful 命名(GET / POST / PUT / DELETE)
- 返回值统一用 { data, error } 格式
- 错误码用 4 位数字(如 1001、1002),别用字符串
4. Local(本地层)
位置 : 项目根目录的 CLAUDE.local.md
权限 : 个人使用,添加到 .gitignore
特点:
-
不会提交到 git,只在你的电脑上
-
可以写私人笔记、临时配置
CLAUDE.md 书写规范
一致性:如果两条规则相互矛盾,Claude 可能会任意选一条。
具体性:写出足够具体、可以验证、加解释的指令。例如:
-
用 "使用 2 空格缩进" 而不是 "把代码格式排好"
-
用 " 提交前运行
npm test"而不是" 测试你的改动 "
大小:每个 CLAUDE.md 文件低于 200 行。社区实测数据是 200 行 92% 遵守率。
结构:适当分组。格式是"Markdown + 可选 frontmatter 作用域 + @include 组合"
@include
@include 是 CLAUDE.md 里的一种引用语法,让你把大文件拆开管理,按需组合。
语法格式
在 CLAUDE.md 的正文里(不能在代码块内),用 @ 开头跟路径:
markdown
# CLAUDE.md

项目基本规范见下方引入的文件:

@./docs/code-style.md
@./docs/testing-rules.md
@~/personal-preferences.md
@/etc/company-standards.md
四种路径写法都支持:
-
@./relative/path--- 相对路径(推荐) -
@path/to/file--- 也视为相对路径(不加./同效果) -
@~/home/path--- 从用户主目录展开 -
@/absolute/path--- 绝对路径
工作机制
-
被引入的文件作为独立条目 插入在引用它的文件之前
-
被引入的文件内部也可以继续用 @include (最多嵌套 5 层)
-
循环引用会被检测并中断
-
不存在的文件会静默忽略(不报错)
-
只能引用文本类文件(
.md、.ts、.json等),图片和 PDF 会被跳过。
注入时机
注入时机包含 启动时预加载 和 按需懒加载。
CWD 就是启动 claude 命令时你所在的那个目录。启动时把 CWD 解析为绝对路径,存入全局 state。
text
启动 Claude Code
      ↓
加载当前 cwd 及其祖先范围的 CLAUDE.md
      ↓
需要访问某个子目录
      ↓
发现该子目录存在 CLAUDE.md
      ↓
加载该目录规则另外,.claude/rules/ 下的文件 ,
无 frontmatter paths: → 无条件,预加载。
有 frontmatter paths: →条件规则,永远懒加载(因为要拿paths去匹配 glob 才知道该不该加载)
涉及到的命令
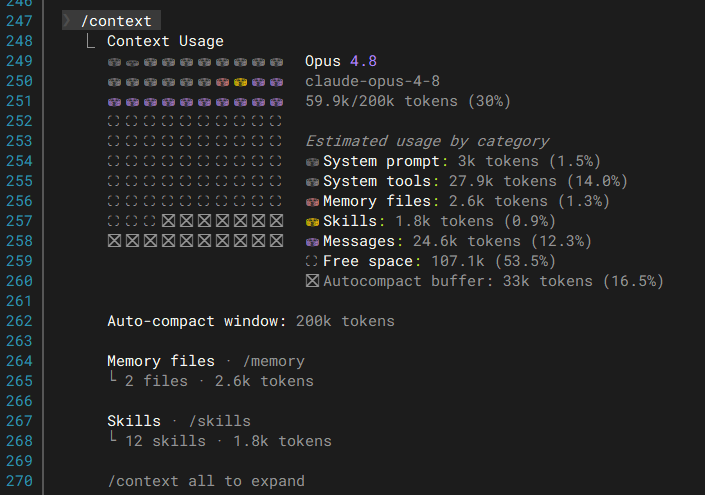
/context
要确认文件已加载,在会话中运行 /context 并查看 Memory files 列表。
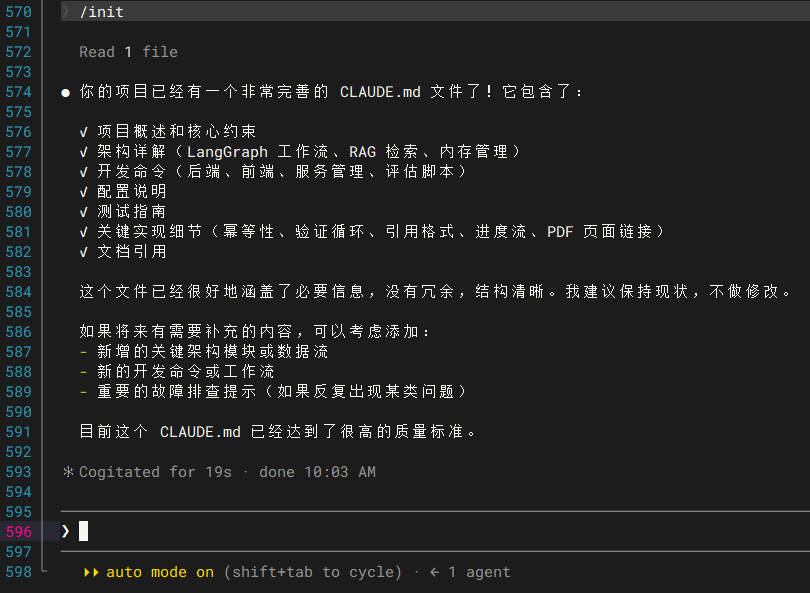
/init
/init 命令在项目根目录下创建 CLAUDE.md
实践经验
CLAUDE.md 放核心常驻规则;内容多了拆到 rules/;可复用工作流统一写进 skills/。
CLAUDE.md 示例:
markdown
# CLAUDE.md

## 1. Project Overview
(2-3 行讲清这是个啥项目,技术栈 + 定位)
- 这是一个面向 B 端的订单管理系统
- 技术栈:TypeScript + Next.js 14 + PostgreSQL
- 部署:Vercel + Supabase

## 2. Commands
(最常用的几个命令,Claude 会直接执行)
- 安装依赖:`pnpm install`
- 启动开发:`pnpm dev`
- 跑测试:`pnpm test`
- 类型检查:`pnpm typecheck`
- Lint:`pnpm lint`

## 3. Architecture
(三句话讲完架构,不要展开)
- 前端页面在 app/(App Router)
- API 路由在 app/api/
- 数据库 schema 在 prisma/schema.prisma
- 详细架构见 docs/architecture.md

## 4. Conventions
(团队真实在用的约定)
- 组件文件用 PascalCase(UserCard.tsx)
- 工具函数用 kebab-case(format-date.ts)
- API 返回统一用 { data, error } 格式
- 错误处理用 Result type,不要 throw

## 5. Hard Constraints
(这部分要严,Claude 越界一次就要补)
- 不要写入 production 数据库(去年事故)
- 不要修改 prisma/migrations/ 下已经合入的 migration
- 不要把 .env 文件加入 git
- 所有 API 路由必须过 requireAuth() middleware

## 6. Gotchas
(每个新人都踩过的坑)
- 跑 dev 之前要先 pnpm db:push 同步 schema
- macOS 上 Prisma 偶发崩溃,重启 dev server 就好
- Vercel 部署日志在 dashboard 里看,不在终端
Auto memory和CLAUDE.md的区别
| 维度 | CLAUDE.md 和 .claude/rules/ | Auto memory |
|---|---|---|
| 主要回答 | "应该怎样工作" | "过去发生过什么,工作过程中学到了什么" |
| 内容 | 项目规范、命令、架构约束、禁止事项 | 用户偏好、历史踩坑、已确认的事实、工作经验 |
| 权威性 | 指令,应遵守 | 提示或线索,需要验证,不能覆盖明确指令 |
| 来源 | 通常由用户或团队维护 | 通常由 Claude 在工作过程中总结、更新 |
| 作用范围 | 全局、项目、目录或路径 | 通常是用户/项目相关的长期经验 |
| 加载方式 | 可以确定性预加载,路径规则按需加载 | 适合索引式加载,主题记忆按需读取 |
| 共享方式 | 可以提交到仓库,供团队复现 | 通常是本机或个人数据,不应自动进入仓库 |
| 生命周期 | 显式评审、版本控制、稳定维护 | 可能过时、压缩、重写或被清理 |