[iBOT] Image BERT Pre-Training with Online Tokenizer

1、目的

探索visual tokenizer编码下的MIM(Masked Image Modeling)

2、方法

iBOT(i mage B ERT pre-training with O nline Tokenizer)
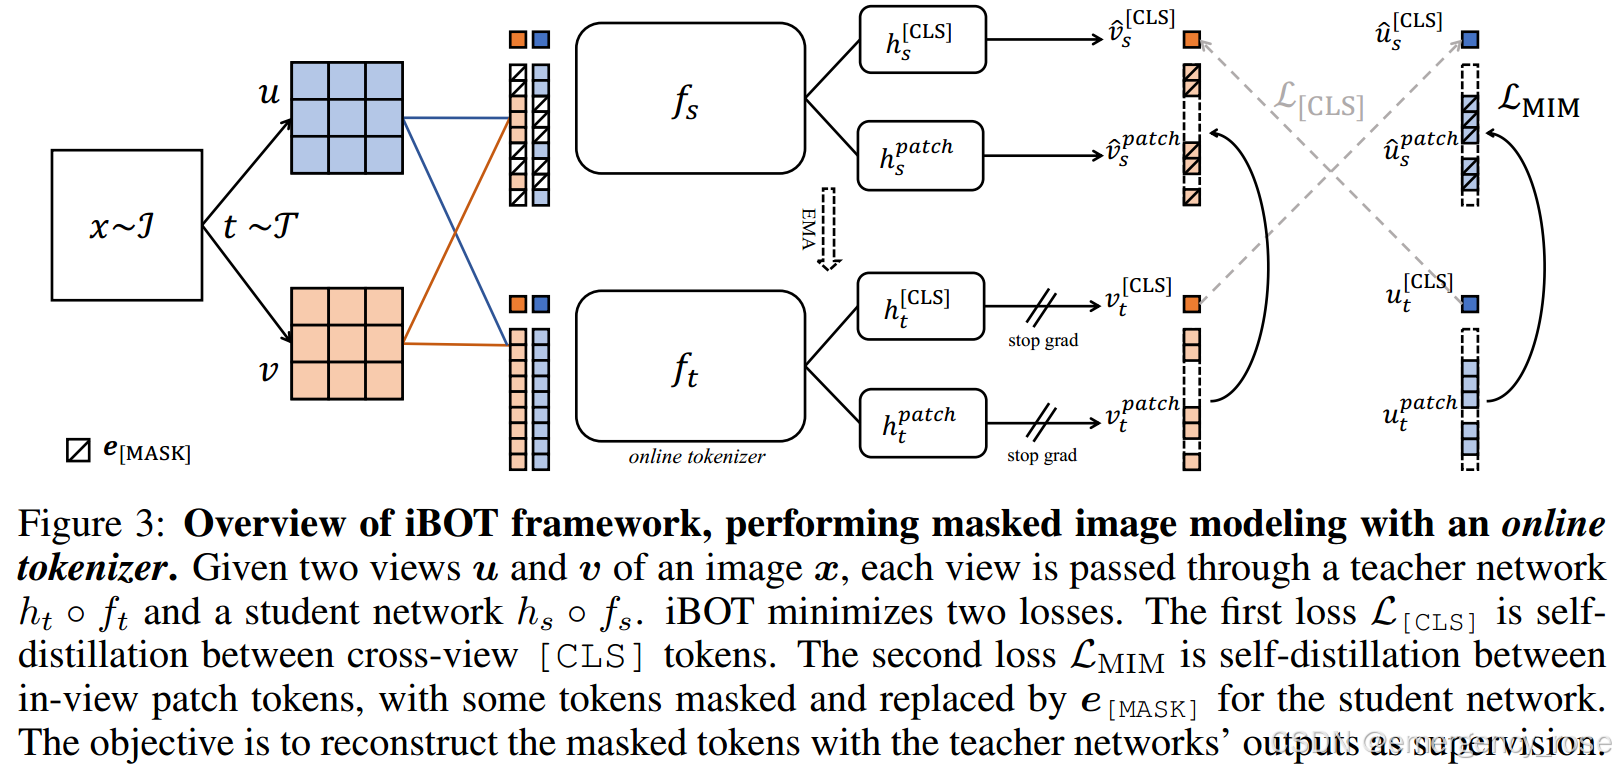
1)knowledge distillation(KD)

distill knowledge from the tokenizer

2)self-distillation

twin teacher as online tokenizer

3)visual tokenizer

-> transform the masked patches to supervisory signals for the target model

-> 通过enforce the similarity of cross-view images on class tokens,来捕获到high-level visual semantics

-> 无须额外的训练,通过momentum update来和MIM一同被优化

-> online,而不是pre-fixed

4)网络结构

-> ,

-> 用softmax之后的token,而非ont-hot

5)multi-crop
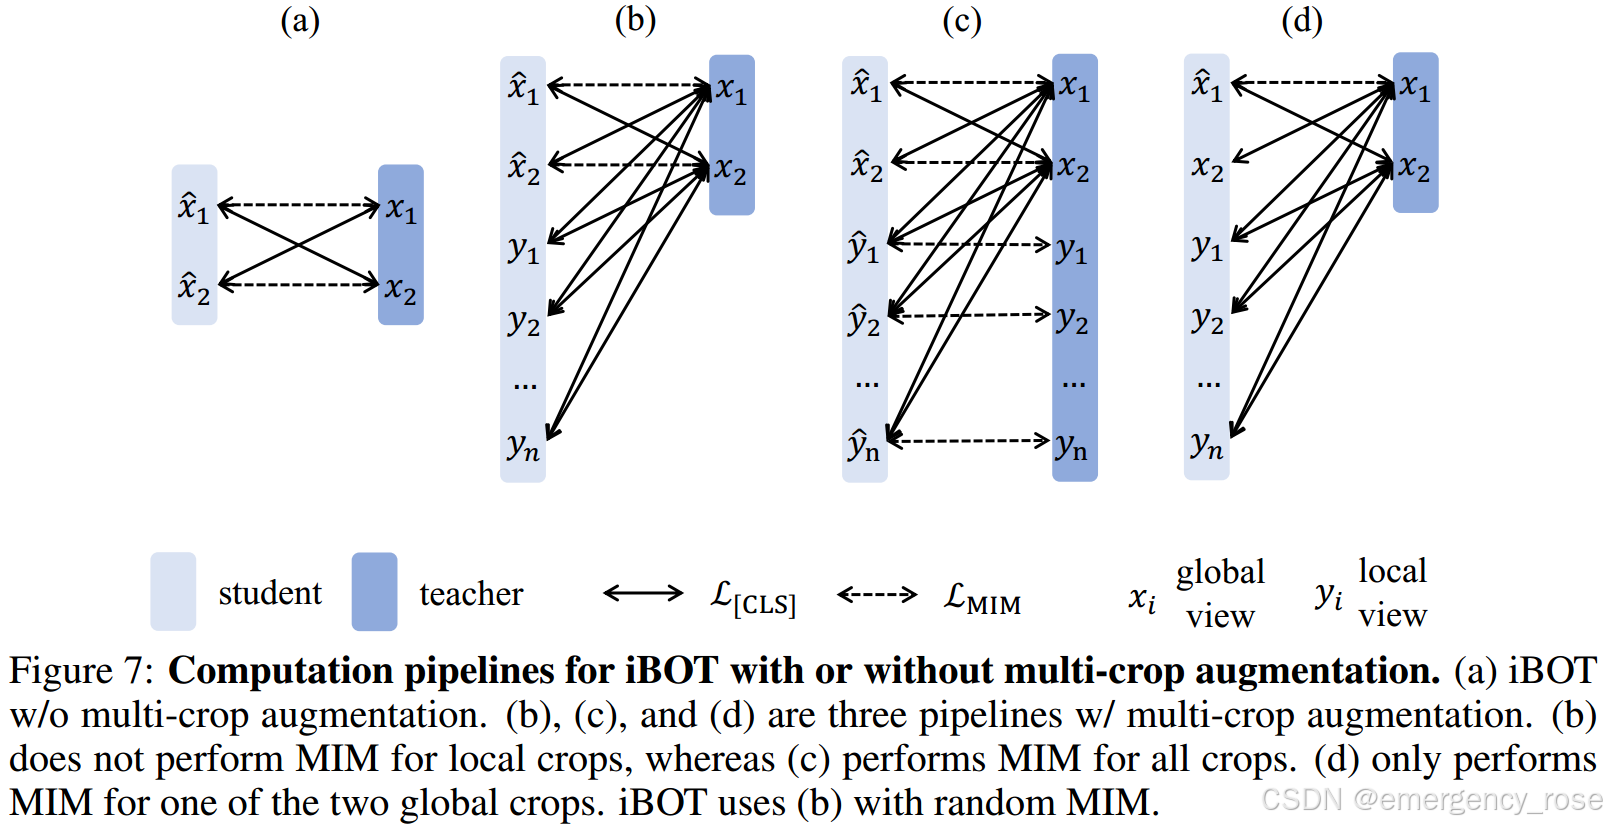
6)MIM

​​​​​​​

3、结论

1)iBOT is more scalable to larger models

2)iBOT requires more data to train larger model

相关推荐
Bowen_J1 小时前
Apple Foundation Models:Apple AI核心框架
人工智能·ai编程·apple
IT_陈寒1 小时前
Redis那个过期删除策略,差点让我线上崩了
前端·人工智能·后端
阿里云大数据AI技术1 小时前
AI 原生大数据服务 ADA 快速入门:完成首次对话式数据分析
大数据·人工智能
字节跳动开源1 小时前
小红书/抖音图文排版利器——一个杂志风skill
人工智能·开源·设计
Bacon1 小时前
我把 Codex 塞进了 Touch Bar:一个 30pt 高的额度与对话面板
人工智能
衡石科技2 小时前
企业级 BI 的安全治理:衡石如何贯通认证、数据权限与审计
大数据·人工智能·安全·商业智能
网易云信2 小时前
折叠屏适配,iPhone Duo 真机已交付:网易云信 IMUIKit Swift 的实践
人工智能
Be for thing3 小时前
Pytorch【12】transforms进阶|图像数据增强实战,提升模型泛化能力
人工智能·pytorch·机器学习
十有八七3 小时前
手搓 Agent(一):先有大脑——大模型只会做一件事
前端·人工智能·后端
锋行天下3 小时前
「踩坑实录」给 LangGraph Agent 接两个 FastMCP,我被 langchain 偷偷改了工具名
前端·人工智能·后端