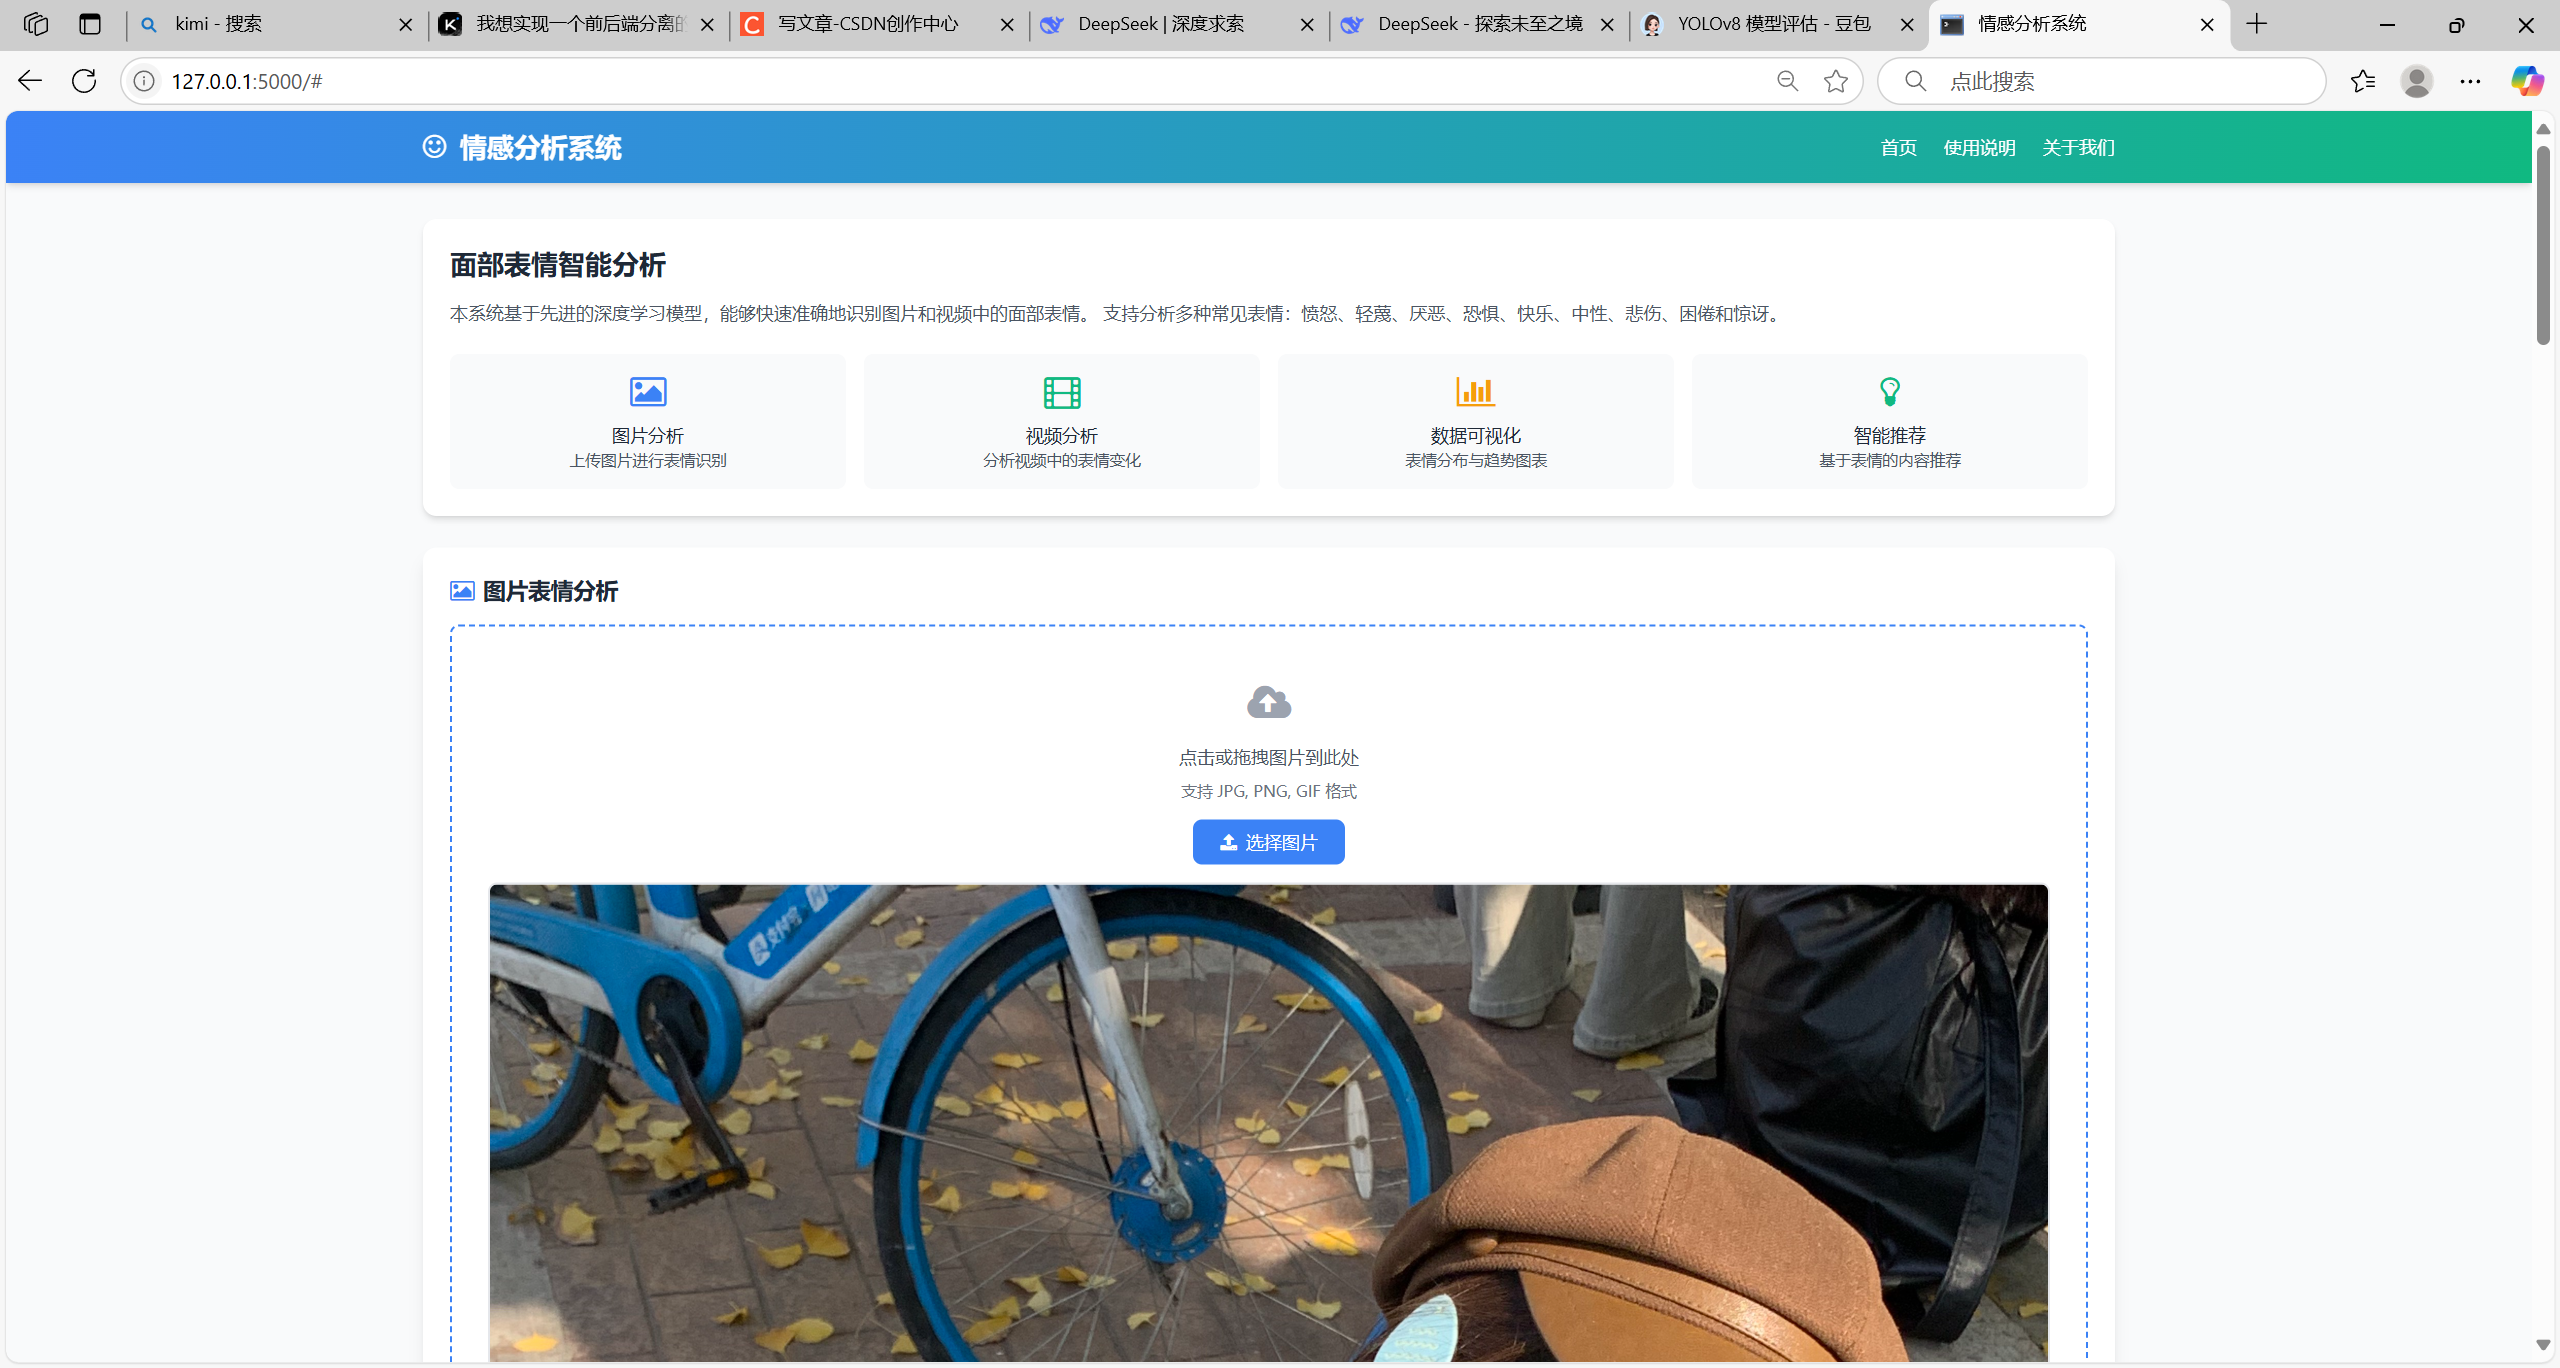
可以通过摄像头或视频文件进行表情检测。系统会在画面上实时标注人脸和识别出的表情,并提供统计信息和推荐内容。
python
运行
import cv2
import torch
import torch.nn as nn
import numpy as np
from torchvision import transforms, models
from PIL import Image
import time
import os
import argparse
from collections import defaultdict, deque

# 设置中文字体支持
try:
    cv2.putText(np.zeros((1, 1, 3), dtype=np.uint8), "测试", (0, 0),
                cv2.FONT_HERSHEY_SIMPLEX, 0.5, (255, 255, 255), 1)
except:
    print("警告: 系统可能不支持中文字体,表情名称可能显示为乱码")

# 表情类别映射
EMOTION_CLASSES = {
    0: "angry",
    1: "contempt",
    2: "disgust",
    3: "fear",
    4: "happy",
    5: "natural",
    6: "sad",
    7: "sleepy",
    8: "surprised"
}

# 表情中文映射
EMOTION_CHINESE = {
    "angry": "愤怒",
    "contempt": "轻蔑",
    "disgust": "厌恶",
    "fear": "恐惧",
    "happy": "快乐",
    "natural": "中性",
    "sad": "悲伤",
    "sleepy": "困倦",
    "surprised": "惊讶"
}

# 表情颜色映射(用于可视化)
EMOTION_COLORS = {
    "angry": (0, 0, 255),        # 红色
    "contempt": (255, 191, 0),   # 浅蓝色
    "disgust": (0, 255, 0),      # 绿色
    "fear": (255, 0, 255),       # 紫色
    "happy": (0, 255, 255),      # 黄色
    "natural": (128, 128, 128),  # 灰色
    "sad": (255, 0, 0),          # 蓝色
    "sleepy": (255, 255, 0),     # 青色
    "surprised": (0, 165, 255)   # 橙色
}

# 表情推荐映射
RECOMMENDATIONS = {
    "angry": "推荐冥想放松视频、舒缓音乐",
    "contempt": "推荐人文纪录片、思想深度内容",
    "disgust": "推荐自然风景、美食视频",
    "fear": "推荐励志演讲、勇气主题内容",
    "happy": "推荐搞笑视频、喜剧电影片段",
    "natural": "推荐综合热门内容",
    "sad": "推荐治愈音乐、温馨短片",
    "sleepy": "推荐活力舞蹈、提神饮品介绍",
    "surprised": "推荐奇闻轶事、探索发现内容"
}

def parse_args():
    """解析命令行参数"""
    parser = argparse.ArgumentParser(description='实时表情检测系统')
    parser.add_argument('--video_file', type=str, default='0',
                        help='视频文件路径或摄像头ID (默认: 0)')
    parser.add_argument('--model_file', required=True,
                        help='预训练模型文件路径')
    parser.add_argument('--out_dir', type=str, default='output',
                        help='输出结果目录')
    parser.add_argument('--gpu', action='store_true',
                        help='是否使用GPU')
    parser.add_argument('--face_detector', type=str, default='haar',
                        choices=['haar', 'dnn'], help='人脸检测器类型')
    parser.add_argument('--fps', type=int, default=30,
                        help='显示帧率')
    return parser.parse_args()

def load_model(model_path, device):
    """加载预训练模型"""
    # 创建模型结构(这里假设使用MobileNetV2)
    model = models.mobilenet_v2(pretrained=False)

    # 修改分类器以匹配情感分析的类别数
    num_classes = len(EMOTION_CLASSES)
    model.classifier[1] = nn.Linear(model.last_channel, num_classes)

    # 加载预训练权重
    model.load_state_dict(torch.load(model_path, map_location=device))
    model.to(device)
    model.eval()

    print(f"已加载模型: {model_path}")
    return model

def load_face_detector(detector_type='haar'):
    """加载人脸检测器"""
    if detector_type == 'haar':
        # 使用OpenCV的Haar级联分类器
        face_cascade = cv2.CascadeClassifier(cv2.data.haarcascades + 'haarcascade_frontalface_default.xml')
        if face_cascade.empty():
            raise ValueError("无法加载Haar级联分类器,请检查OpenCV安装")
        return face_cascade
    elif detector_type == 'dnn':
        # 使用OpenCV的DNN人脸检测器(更准确但速度较慢)
        model_file = "opencv_face_detector_uint8.pb"
        config_file = "opencv_face_detector.pbtxt"

        # 检查模型文件是否存在
        if not os.path.exists(model_file) or not os.path.exists(config_file):
            print("警告: DNN人脸检测器模型文件不存在,将使用Haar级联分类器")
            return load_face_detector('haar')

        net = cv2.dnn.readNetFromTensorflow(model_file, config_file)
        return net
    else:
        raise ValueError(f"不支持的人脸检测器类型: {detector_type}")

def detect_faces(image, face_detector, detector_type='haar'):
    """检测图像中的人脸"""
    if detector_type == 'haar':
        # Haar级联分类器检测
        gray = cv2.cvtColor(image, cv2.COLOR_BGR2GRAY)
        faces = face_detector.detectMultiScale(
            gray, scaleFactor=1.1, minNeighbors=5, minSize=(30, 30))
        return [(x, y, x+w, y+h) for (x, y, w, h) in faces]
    else:
        # DNN检测器
        blob = cv2.dnn.blobFromImage(image, 1.0, (300, 300), [104, 117, 123], False, False)
        face_detector.setInput(blob)
        detections = face_detector.forward()

        faces = []
        h, w = image.shape[:2]
        for i in range(detections.shape[2]):
            confidence = detections[0, 0, i, 2]
            if confidence > 0.5:  # 置信度阈值
                box = detections[0, 0, i, 3:7] * np.array([w, h, w, h])
                (x1, y1, x2, y2) = box.astype("int")
                faces.append((x1, y1, x2, y2))

        return faces

def preprocess_face(face_image):
    """预处理人脸图像用于表情识别"""
    transform = transforms.Compose([
        transforms.Resize((224, 224)),
        transforms.ToTensor(),
        transforms.Normalize(mean=[0.485, 0.456, 0.406], std=[0.229, 0.224, 0.225])
    ])

    # 转换为PIL图像
    face_pil = Image.fromarray(cv2.cvtColor(face_image, cv2.COLOR_BGR2RGB))
    return transform(face_pil).unsqueeze(0)

def detect_emotion(model, face_tensor, device):
    """检测人脸表情"""
    with torch.no_grad():
        face_tensor = face_tensor.to(device)
        outputs = model(face_tensor)
        probabilities = torch.nn.functional.softmax(outputs, dim=1)
        confidence, predicted = torch.max(probabilities, 1)

    emotion_id = predicted.item()
    confidence = confidence.item()
    return emotion_id, confidence

def draw_results(frame, faces, emotions, confidences):
    """在图像上绘制检测结果"""
    for i, (face, emotion_id, confidence) in enumerate(zip(faces, emotions, confidences)):
        x1, y1, x2, y2 = face
        emotion = EMOTION_CLASSES[emotion_id]
        emotion_cn = EMOTION_CHINESE.get(emotion, emotion)
        color = EMOTION_COLORS[emotion]

        # 绘制人脸框
        cv2.rectangle(frame, (x1, y1), (x2, y2), color, 2)

        # 绘制表情标签
        label = f"{emotion_cn}: {confidence:.2f}"
        cv2.putText(frame, label, (x1, y1-10),
                   cv2.FONT_HERSHEY_SIMPLEX, 0.9, color, 2)

    return frame

def main():
    args = parse_args()

    # 创建输出目录
    if not os.path.exists(args.out_dir):
        os.makedirs(args.out_dir)
        print(f"创建输出目录: {args.out_dir}")

    # 设置设备
    device = torch.device("cuda" if args.gpu and torch.cuda.is_available() else "cpu")
    print(f"使用设备: {device}")

    # 加载模型
    model = load_model(args.model_file, device)

    # 加载人脸检测器
    face_detector = load_face_detector(args.face_detector)

    # 打开视频文件或摄像头
    try:
        video_file = int(args.video_file)  # 尝试作为摄像头ID
    except ValueError:
        video_file = args.video_file  # 作为文件路径

    cap = cv2.VideoCapture(video_file)

    if not cap.isOpened():
        print(f"无法打开视频源: {args.video_file}")
        return

    # 获取视频信息
    fps = cap.get(cv2.CAP_PROP_FPS)
    width = int(cap.get(cv2.CAP_PROP_FRAME_WIDTH))
    height = int(cap.get(cv2.CAP_PROP_FRAME_HEIGHT))

    print(f"视频源: {args.video_file}")
    print(f"分辨率: {width}x{height}")
    print(f"帧率: {fps:.2f} FPS")

    # 创建视频写入器(可选)
    if isinstance(video_file, str) or args.video_file != '0':  # 非默认摄像头
        output_path = os.path.join(args.out_dir, f"output_{os.path.basename(str(video_file))}")
        fourcc = cv2.VideoWriter_fourcc(*'mp4v')
        out = cv2.VideoWriter(output_path, fourcc, args.fps, (width, height))
    else:
        out = None

    # 表情统计
    emotion_history = defaultdict(lambda: deque(maxlen=30))  # 保存最近30帧的表情
    frame_count = 0
    start_time = time.time()

    # 创建显示窗口
    cv2.namedWindow("实时表情检测", cv2.WINDOW_NORMAL)
    cv2.resizeWindow("实时表情检测", 1024, 768)

    try:
        while True:
            ret, frame = cap.read()
            if not ret:
                break

            frame_count += 1

            # 检测人脸
            faces = detect_faces(frame, face_detector, args.face_detector)

            emotions = []
            confidences = []

            # 对每个检测到的人脸进行表情识别
            for face in faces:
                x1, y1, x2, y2 = face

                # 提取人脸区域
                face_image = frame[y1:y2, x1:x2]
                if face_image.size == 0:
                    continue

                # 预处理人脸图像
                face_tensor = preprocess_face(face_image)

                # 检测表情
                emotion_id, confidence = detect_emotion(model, face_tensor, device)

                emotions.append(emotion_id)
                confidences.append(confidence)

                # 更新表情历史
                emotion_history[face].append(emotion_id)

            # 绘制检测结果
            result_frame = draw_results(frame.copy(), faces, emotions, confidences)

            # 计算FPS
            elapsed_time = time.time() - start_time
            current_fps = frame_count / elapsed_time

            # 显示FPS和其他信息
            cv2.putText(result_frame, f"FPS: {current_fps:.1f}", (10, 30),
                       cv2.FONT_HERSHEY_SIMPLEX, 0.7, (0, 255, 0), 2)

            # 显示主导表情(如果有检测到人脸)
            if faces and emotions:
                # 统计当前帧中最常见的表情
                emotion_counts = defaultdict(int)
                for emotion_id in emotions:
                    emotion_counts[emotion_id] += 1

                dominant_emotion_id = max(emotion_counts, key=emotion_counts.get)
                dominant_emotion = EMOTION_CLASSES[dominant_emotion_id]
                dominant_emotion_cn = EMOTION_CHINESE.get(dominant_emotion, dominant_emotion)
                dominant_color = EMOTION_COLORS[dominant_emotion]

                # 显示主导表情
                cv2.putText(result_frame, f"主导表情: {dominant_emotion_cn}", (10, 60),
                           cv2.FONT_HERSHEY_SIMPLEX, 0.7, dominant_color, 2)

                # 显示推荐内容
                recommendation = RECOMMENDATIONS.get(dominant_emotion, "无推荐内容")
                cv2.putText(result_frame, f"推荐: {recommendation}", (10, 90),
                           cv2.FONT_HERSHEY_SIMPLEX, 0.6, (255, 255, 255), 2)

            # 显示帧
            cv2.imshow("实时表情检测", result_frame)

            # 写入输出视频
            if out:
                out.write(result_frame)

            # 按 'q' 键退出
            if cv2.waitKey(1) & 0xFF == ord('q'):
                break

    except KeyboardInterrupt:
        print("程序被用户中断")
    finally:
        # 释放资源
        cap.release()
        if out:
            out.release()
        cv2.destroyAllWindows()
        print(f"程序已退出,共处理 {frame_count} 帧")

if __name__ == "__main__":
    main()
使用说明
- 安装依赖:
bash
pip install torch torchvision opencv-python numpy pillow-
下载人脸检测模型(可选):
- 如果使用 DNN 人脸检测器,需要下载模型文件:
opencv_face_detector_uint8.pbopencv_face_detector.pbtxt
- 模型文件可以从 OpenCV 官方仓库获取
- 如果使用 DNN 人脸检测器,需要下载模型文件:
-
运行程序:
bash
python realtime_emotion_detection.py --model_file data/pretrained/mobilenet_v2_1.0_CrossEntropyLoss_20230313090258/model/latest_model_099_94.7200.pth --video_file 0- 参数说明 :
--video_file: 视频文件路径或摄像头 ID(默认 0 表示内置摄像头)--model_file: 预训练模型文件路径(必填)--out_dir: 输出结果目录--gpu: 是否使用 GPU 加速--face_detector: 人脸检测器类型(haar 或 dnn)--fps: 显示帧率
功能特点
- 实时检测:通过摄像头或视频文件进行表情检测
- 多人脸支持:同时检测和识别画面中的多个人脸表情
- 表情可视化:在人脸周围绘制边框和表情标签
- 统计信息:显示当前主导表情和推荐内容
- 性能监控:实时显示处理帧率
按q键可以退出程序。如果输入的是视频文件,程序会生成带检测结果的输出视频。