Language Models Struggle to Use Representations Learned In-Context
Authors: Michael A. Lepori, Tal Linzen, Ann Yuan, Katja Filippova
Deep-Dive Summary:
论文总结:大语言模型中的思维链提示(Chain-of-Thought Prompting)
1. 引言与背景
虽然大型语言模型(LLMs)在各种自然语言处理任务中表现出色,但在处理需要多步推理的任务(如算术推理、常识推理和符号推理)时,其表现往往不尽如人意。本文探讨了如何通过一种简单而有效的方法------**思维链提示(Chain-of-Thought Prompting, CoT)**来提升这些模型的推理能力。
2. 什么是思维链提示(CoT)?
思维链是指在给出最终答案之前,产生的一系列中间推理步骤。思维链提示法通过在少样本提示(Few-shot Prompting)中加入这些推理过程,引导模型学会"思考"后再回答。
如上图所示,标准提示直接给出"问题-答案"对,而思维链提示则在答案前增加了一段逻辑推导。这种方法不需要对模型进行微调,只需通过提示词(Prompting)即可触发。
3. 思维链提示的核心特性
思维链提示具有以下几个关键优势:
- 分解任务:它允许模型将多步问题分解为更小的中间步骤,从而将计算资源分配给需要更多推理的部分。
- 可解释性:它为模型的推理路径提供了一个窗口,使我们能够观察到模型是如何得出结论的,并方便调试。
- 普适性:它可以应用于数学应用题、符号操纵和常识推理等多种任务。
- 易用性:只需在提示中增加几个推理示例,即可在预训练好的大型模型中激活该能力。
4. 算术推理实验
研究团队在包括 GSM8K、SVAMP、ASDiv、AQuA 和 MAWPS 在内的多个数学应用题基准测试中验证了思维链提示的效果。
实验设置
实验使用了多个大型语言模型,包括 LaMDA、GPT-3、Codex 和 PaLM,参数量级从 7 B 7B 7B 到 540 B 540B 540B 不等。
5. 实验结果与涌现能力
实验结果表明,思维链提示在不同模型上的表现具有明显的规模效应:
- 涌现性 :思维链提示对于小型模型(约 < 10 B <10B <10B 参数)基本无效,甚至可能降低性能。
- 规模增长 :其提升效果在模型规模达到约 100 B 100B 100B 参数时显著爆发。
- 超越最先进水平 :例如,使用思维链提示的 PaLM 540 B 540B 540B 在 GSM8K 数据集上的表现优于经过微调的专用模型。
此外,思维链提示对不同提示词(Prompters)的风格以及不同的样本顺序都表现出了较强的鲁棒性。
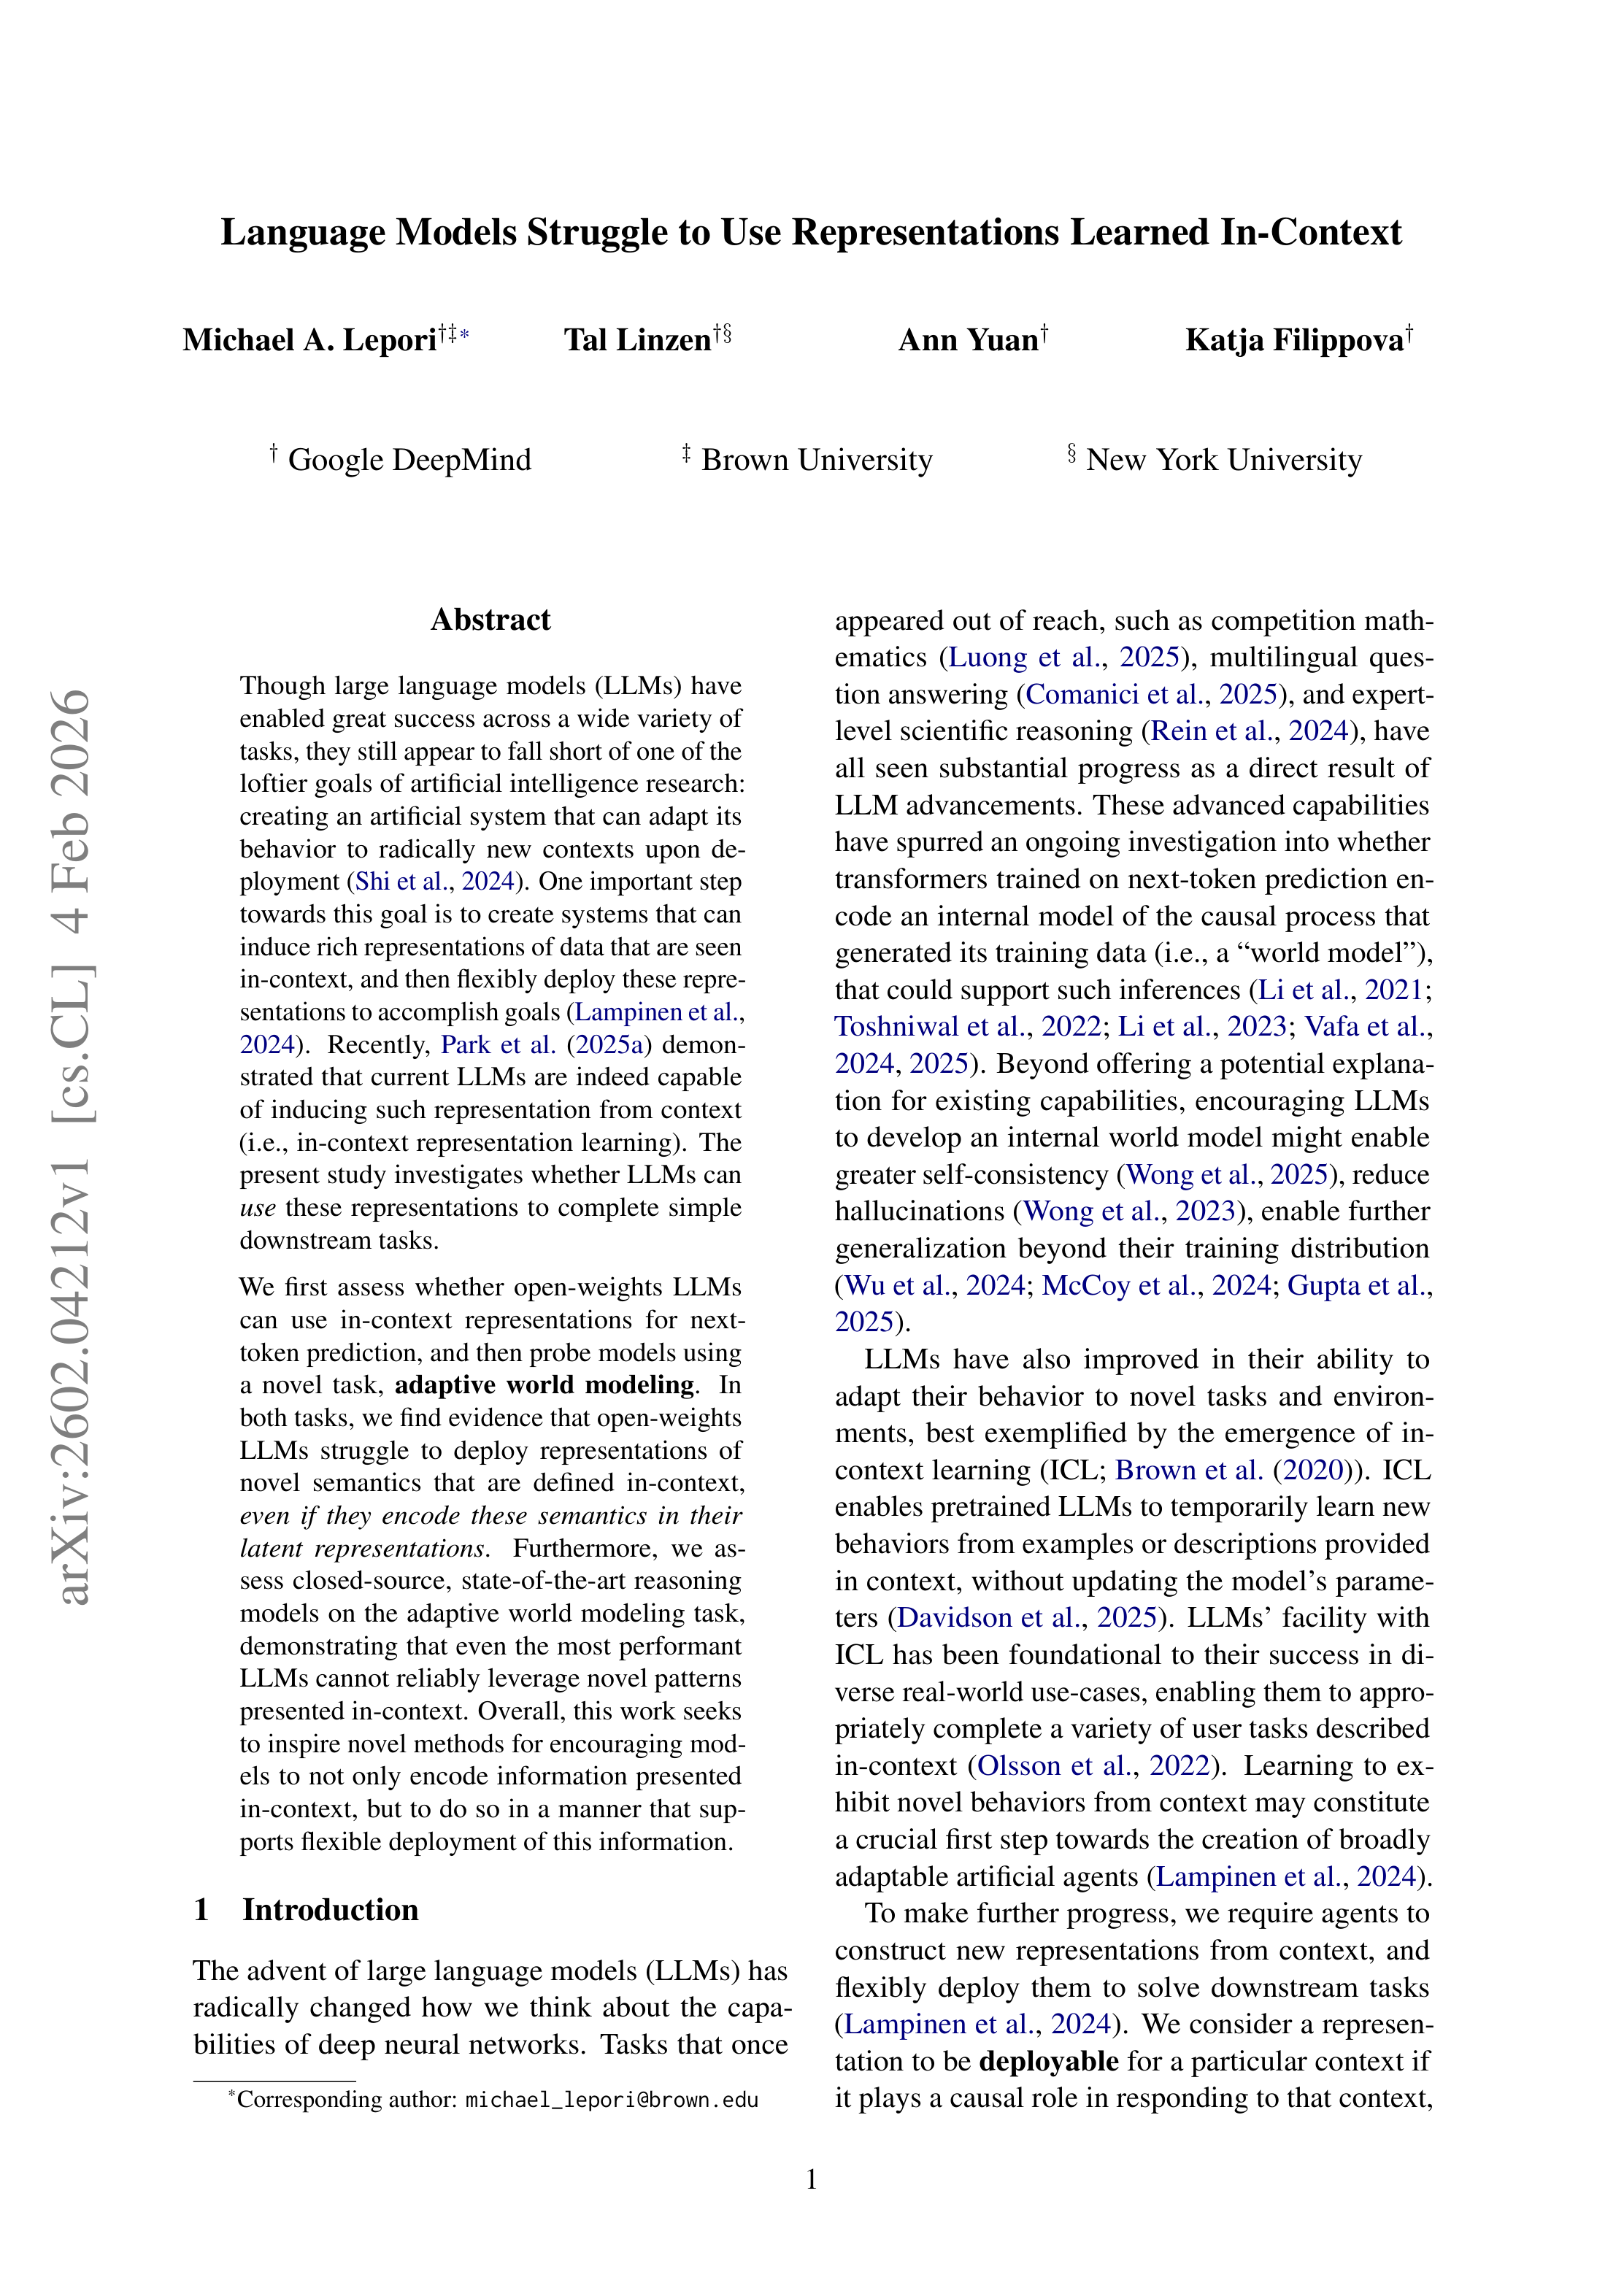
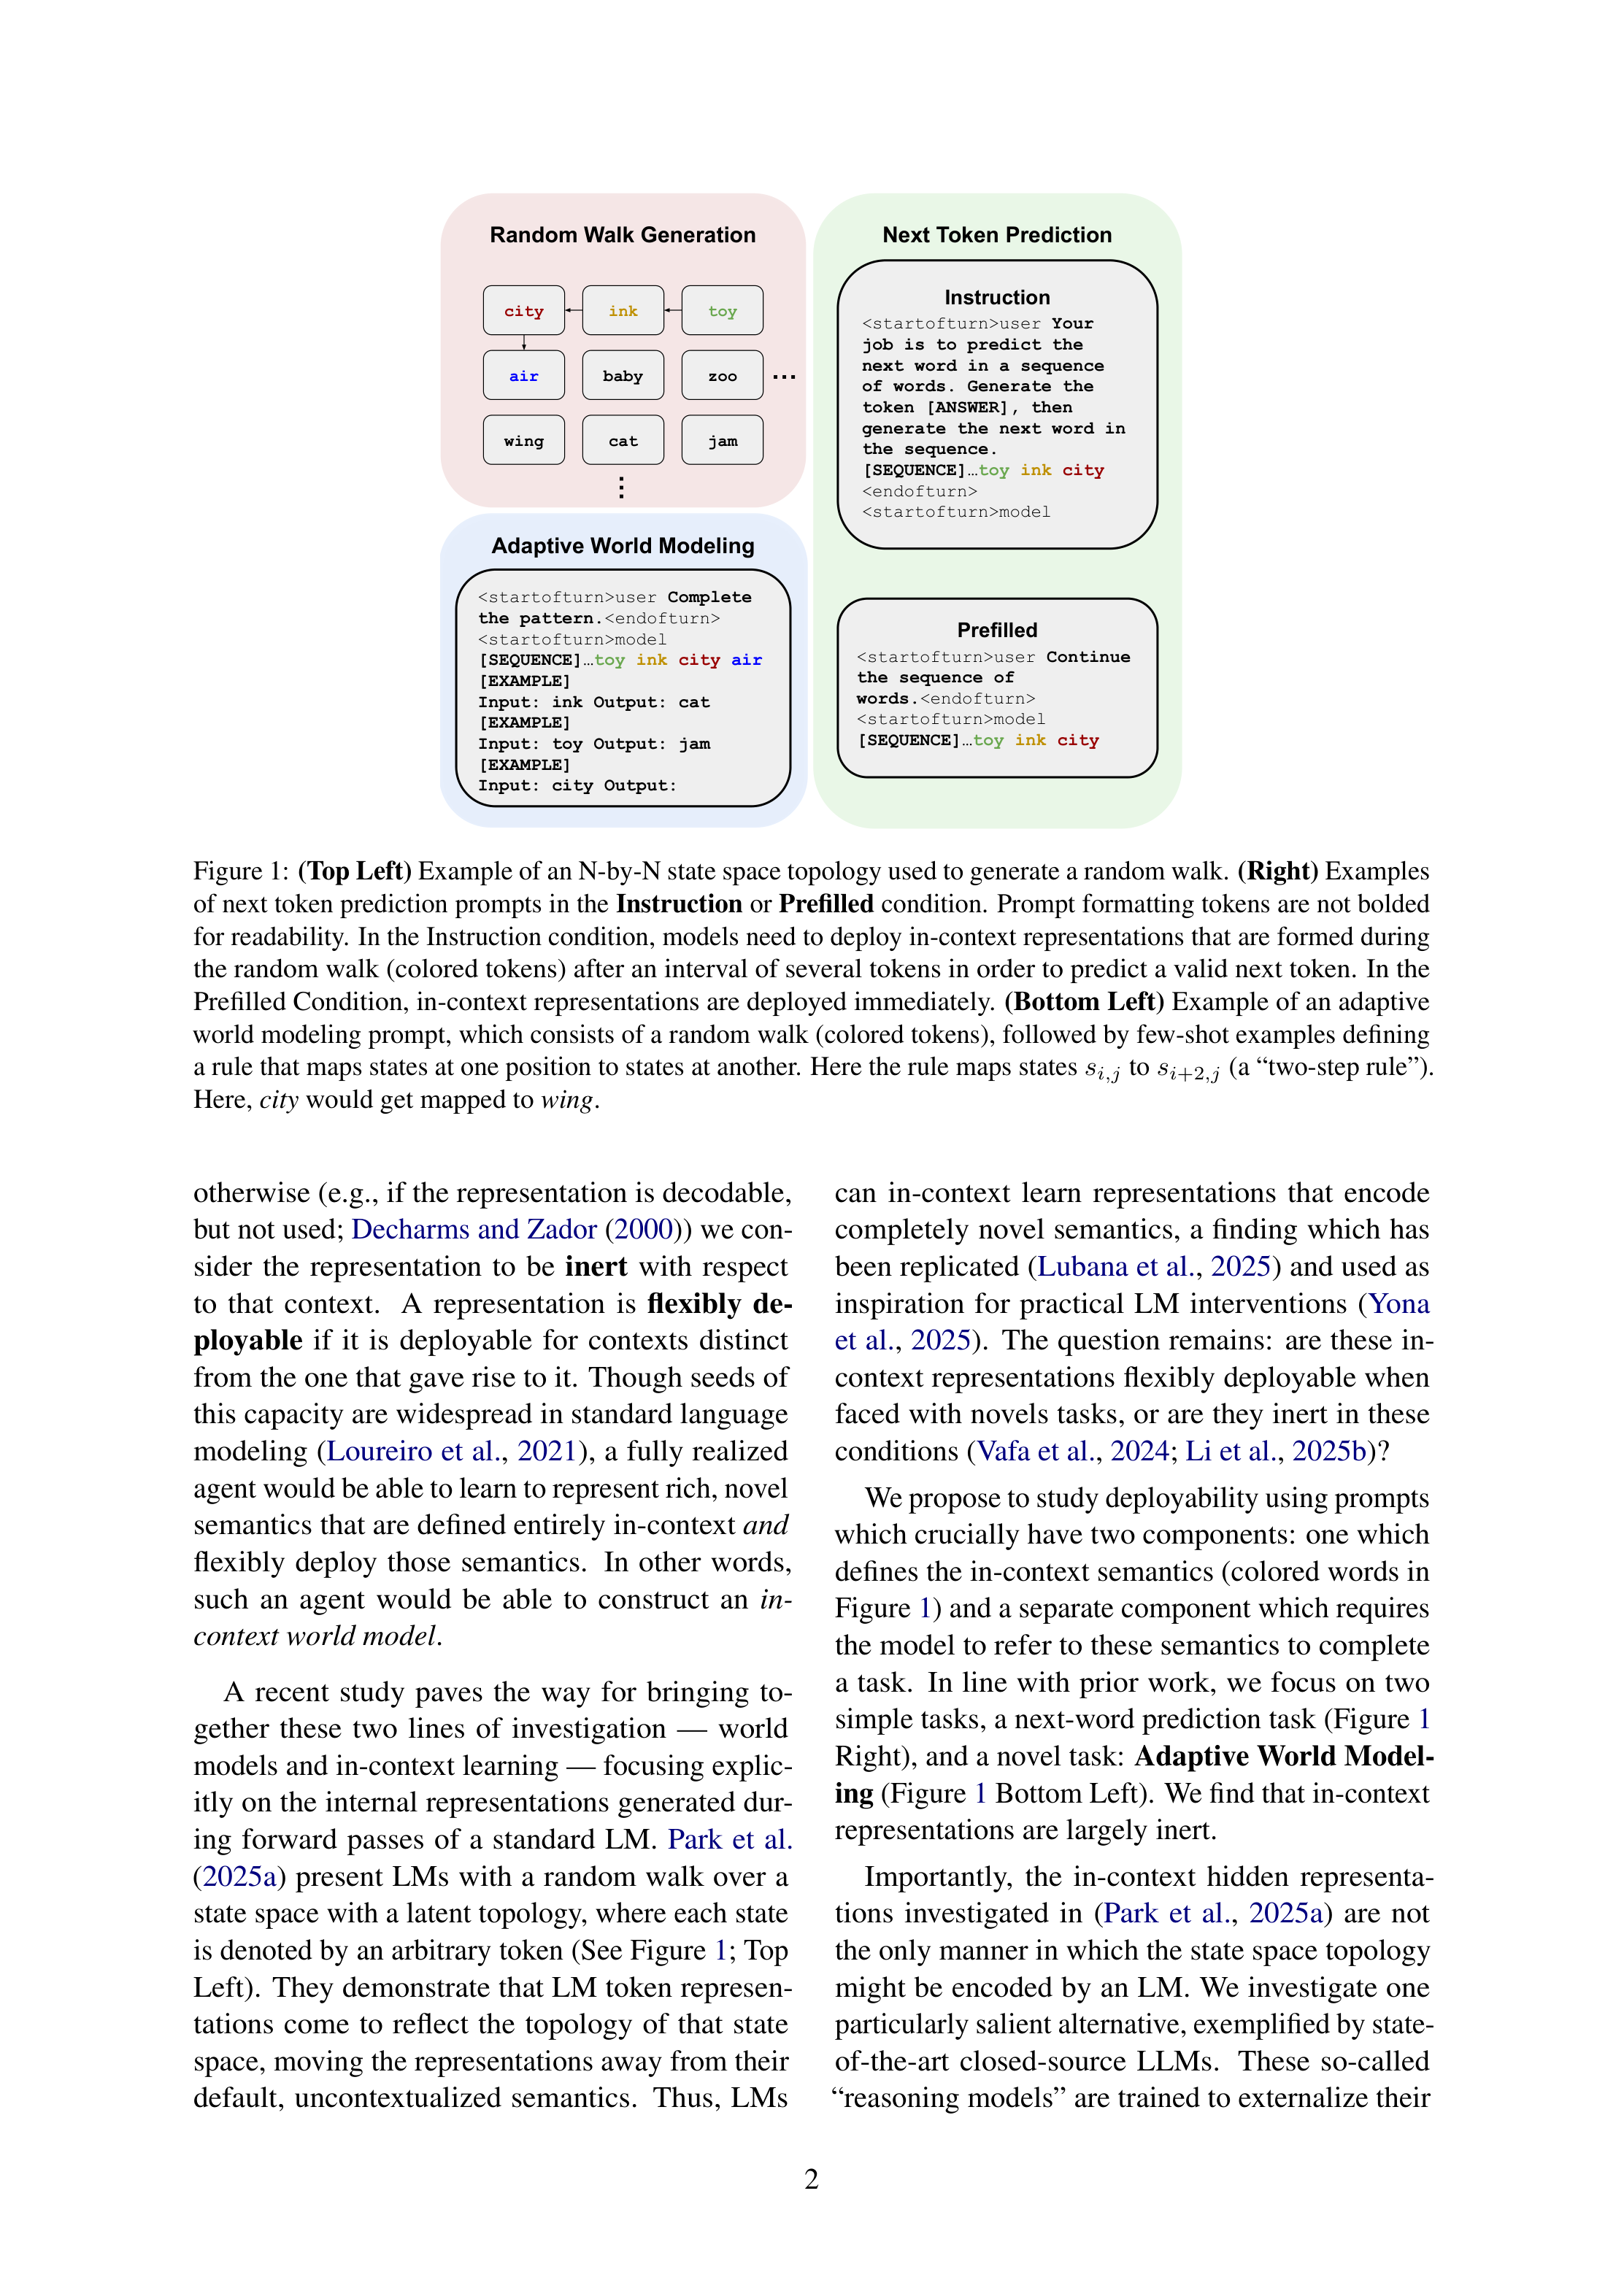
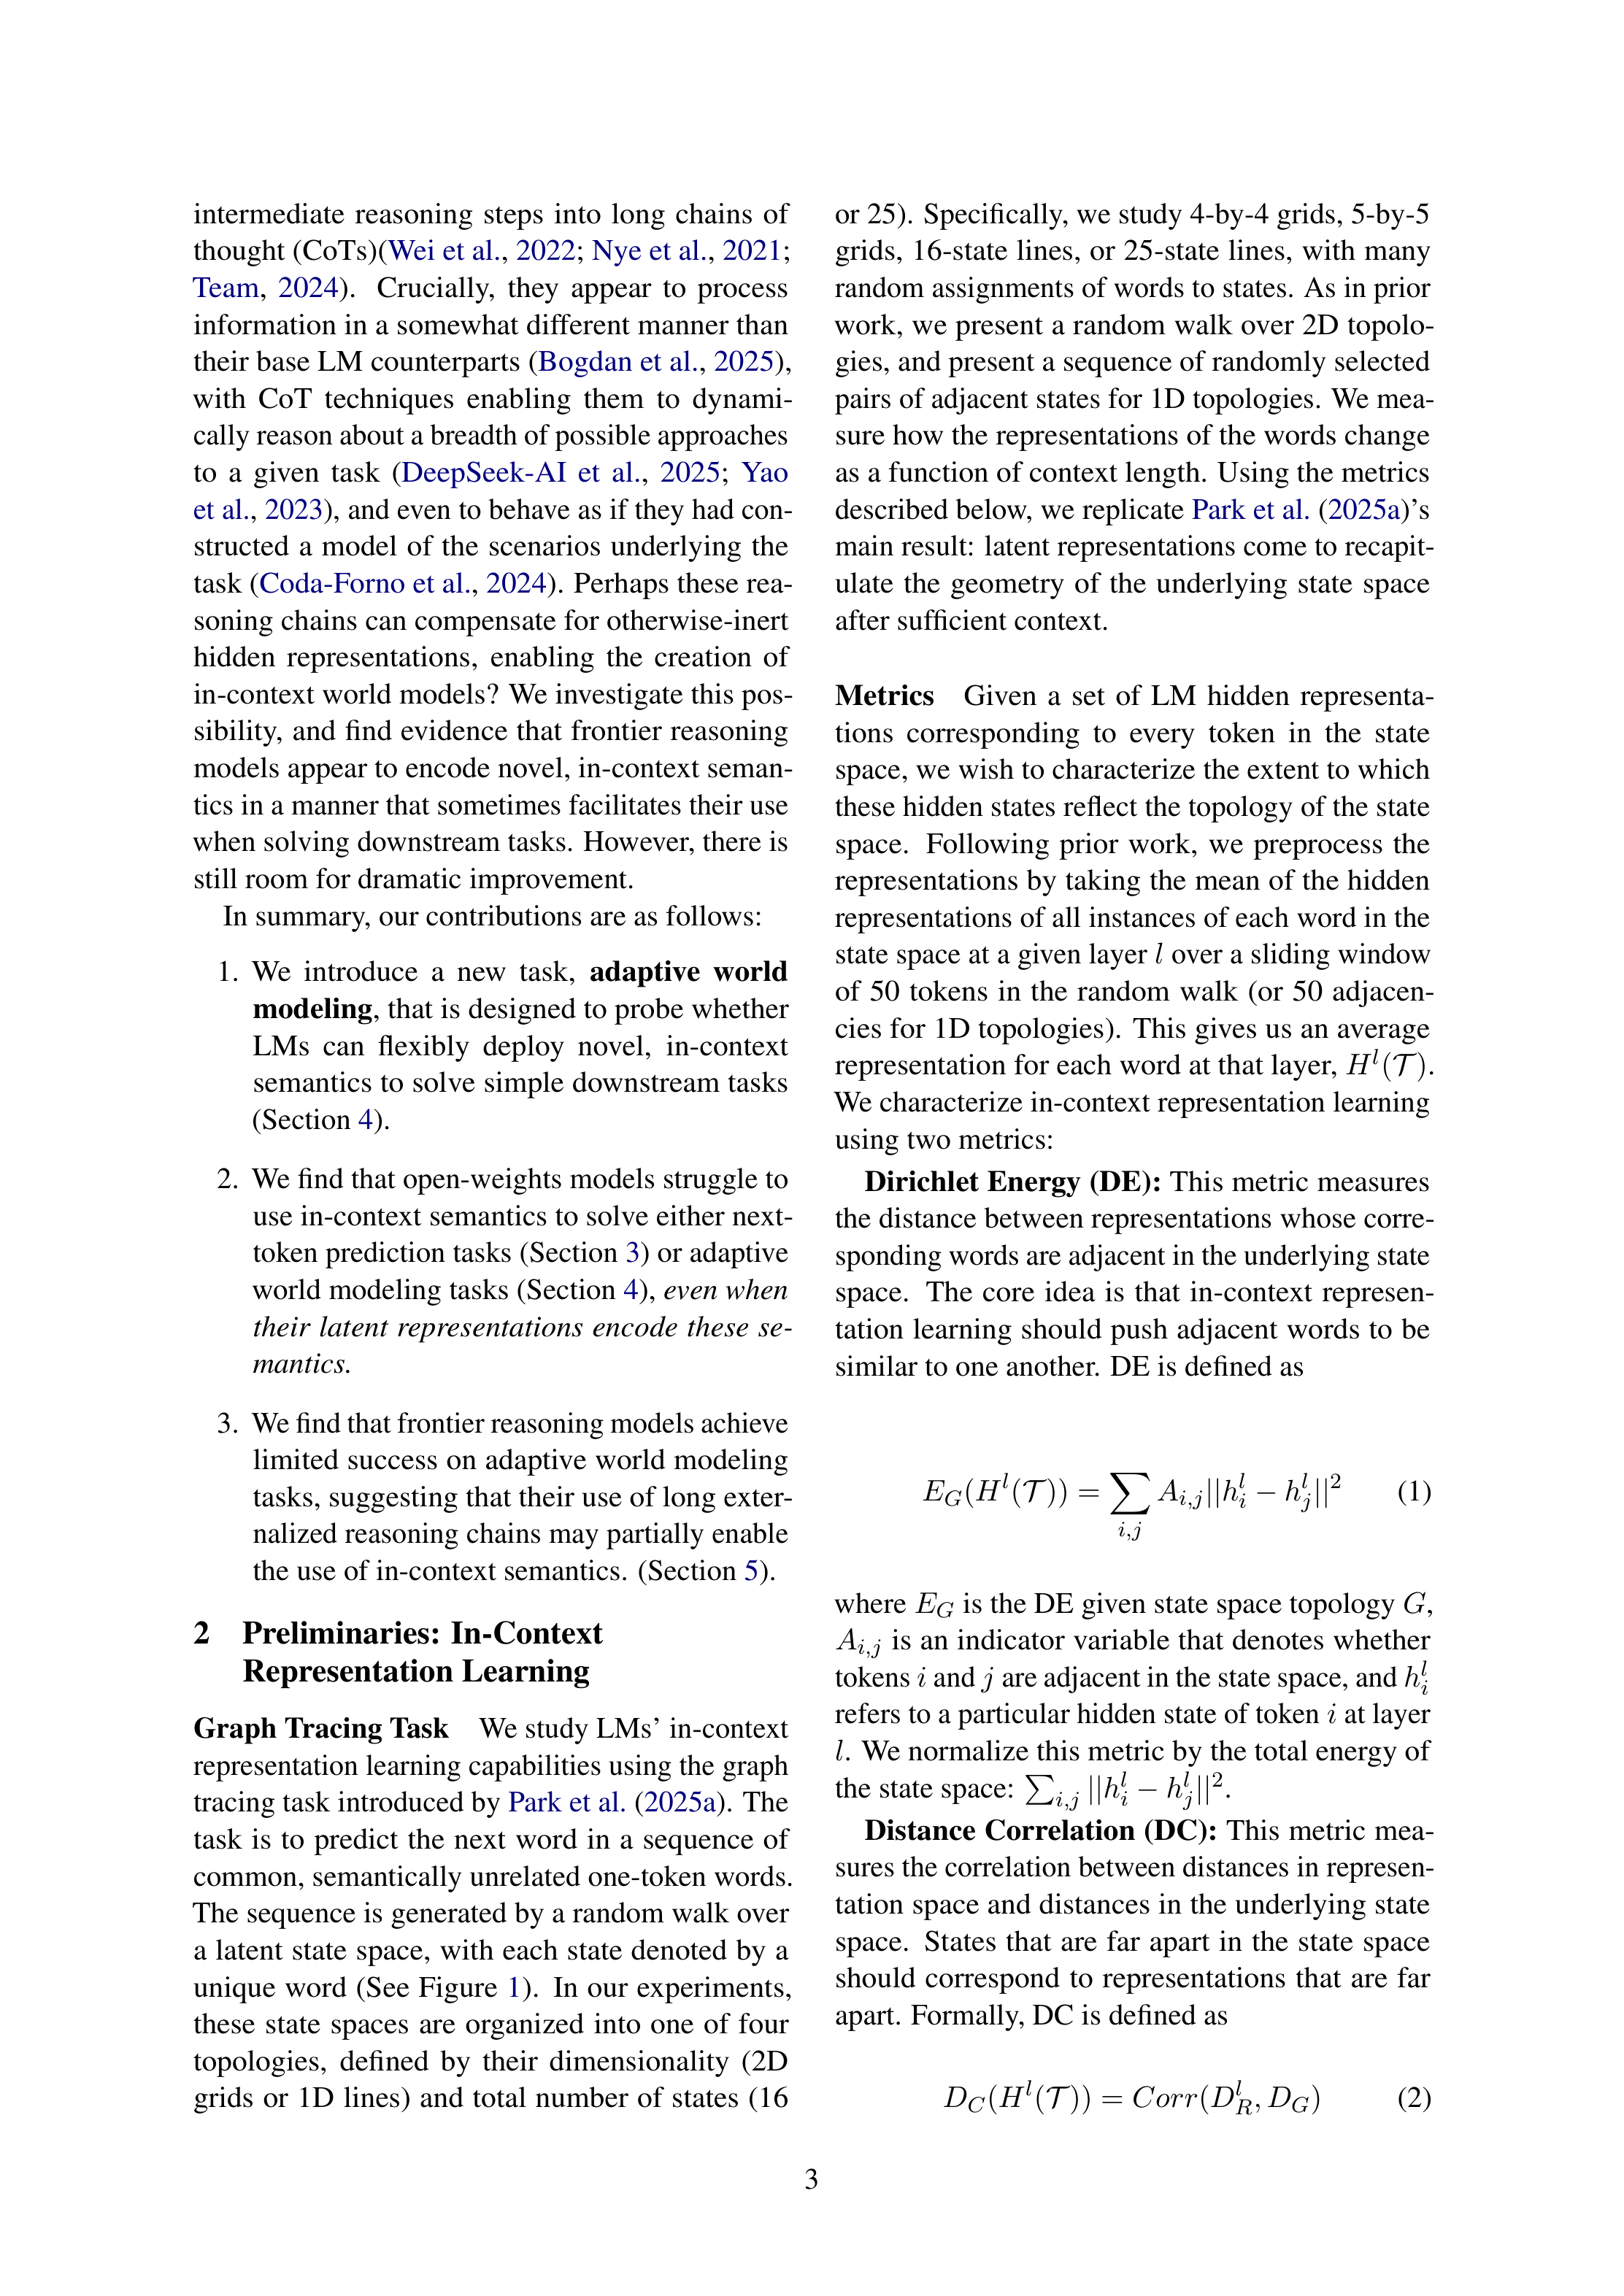
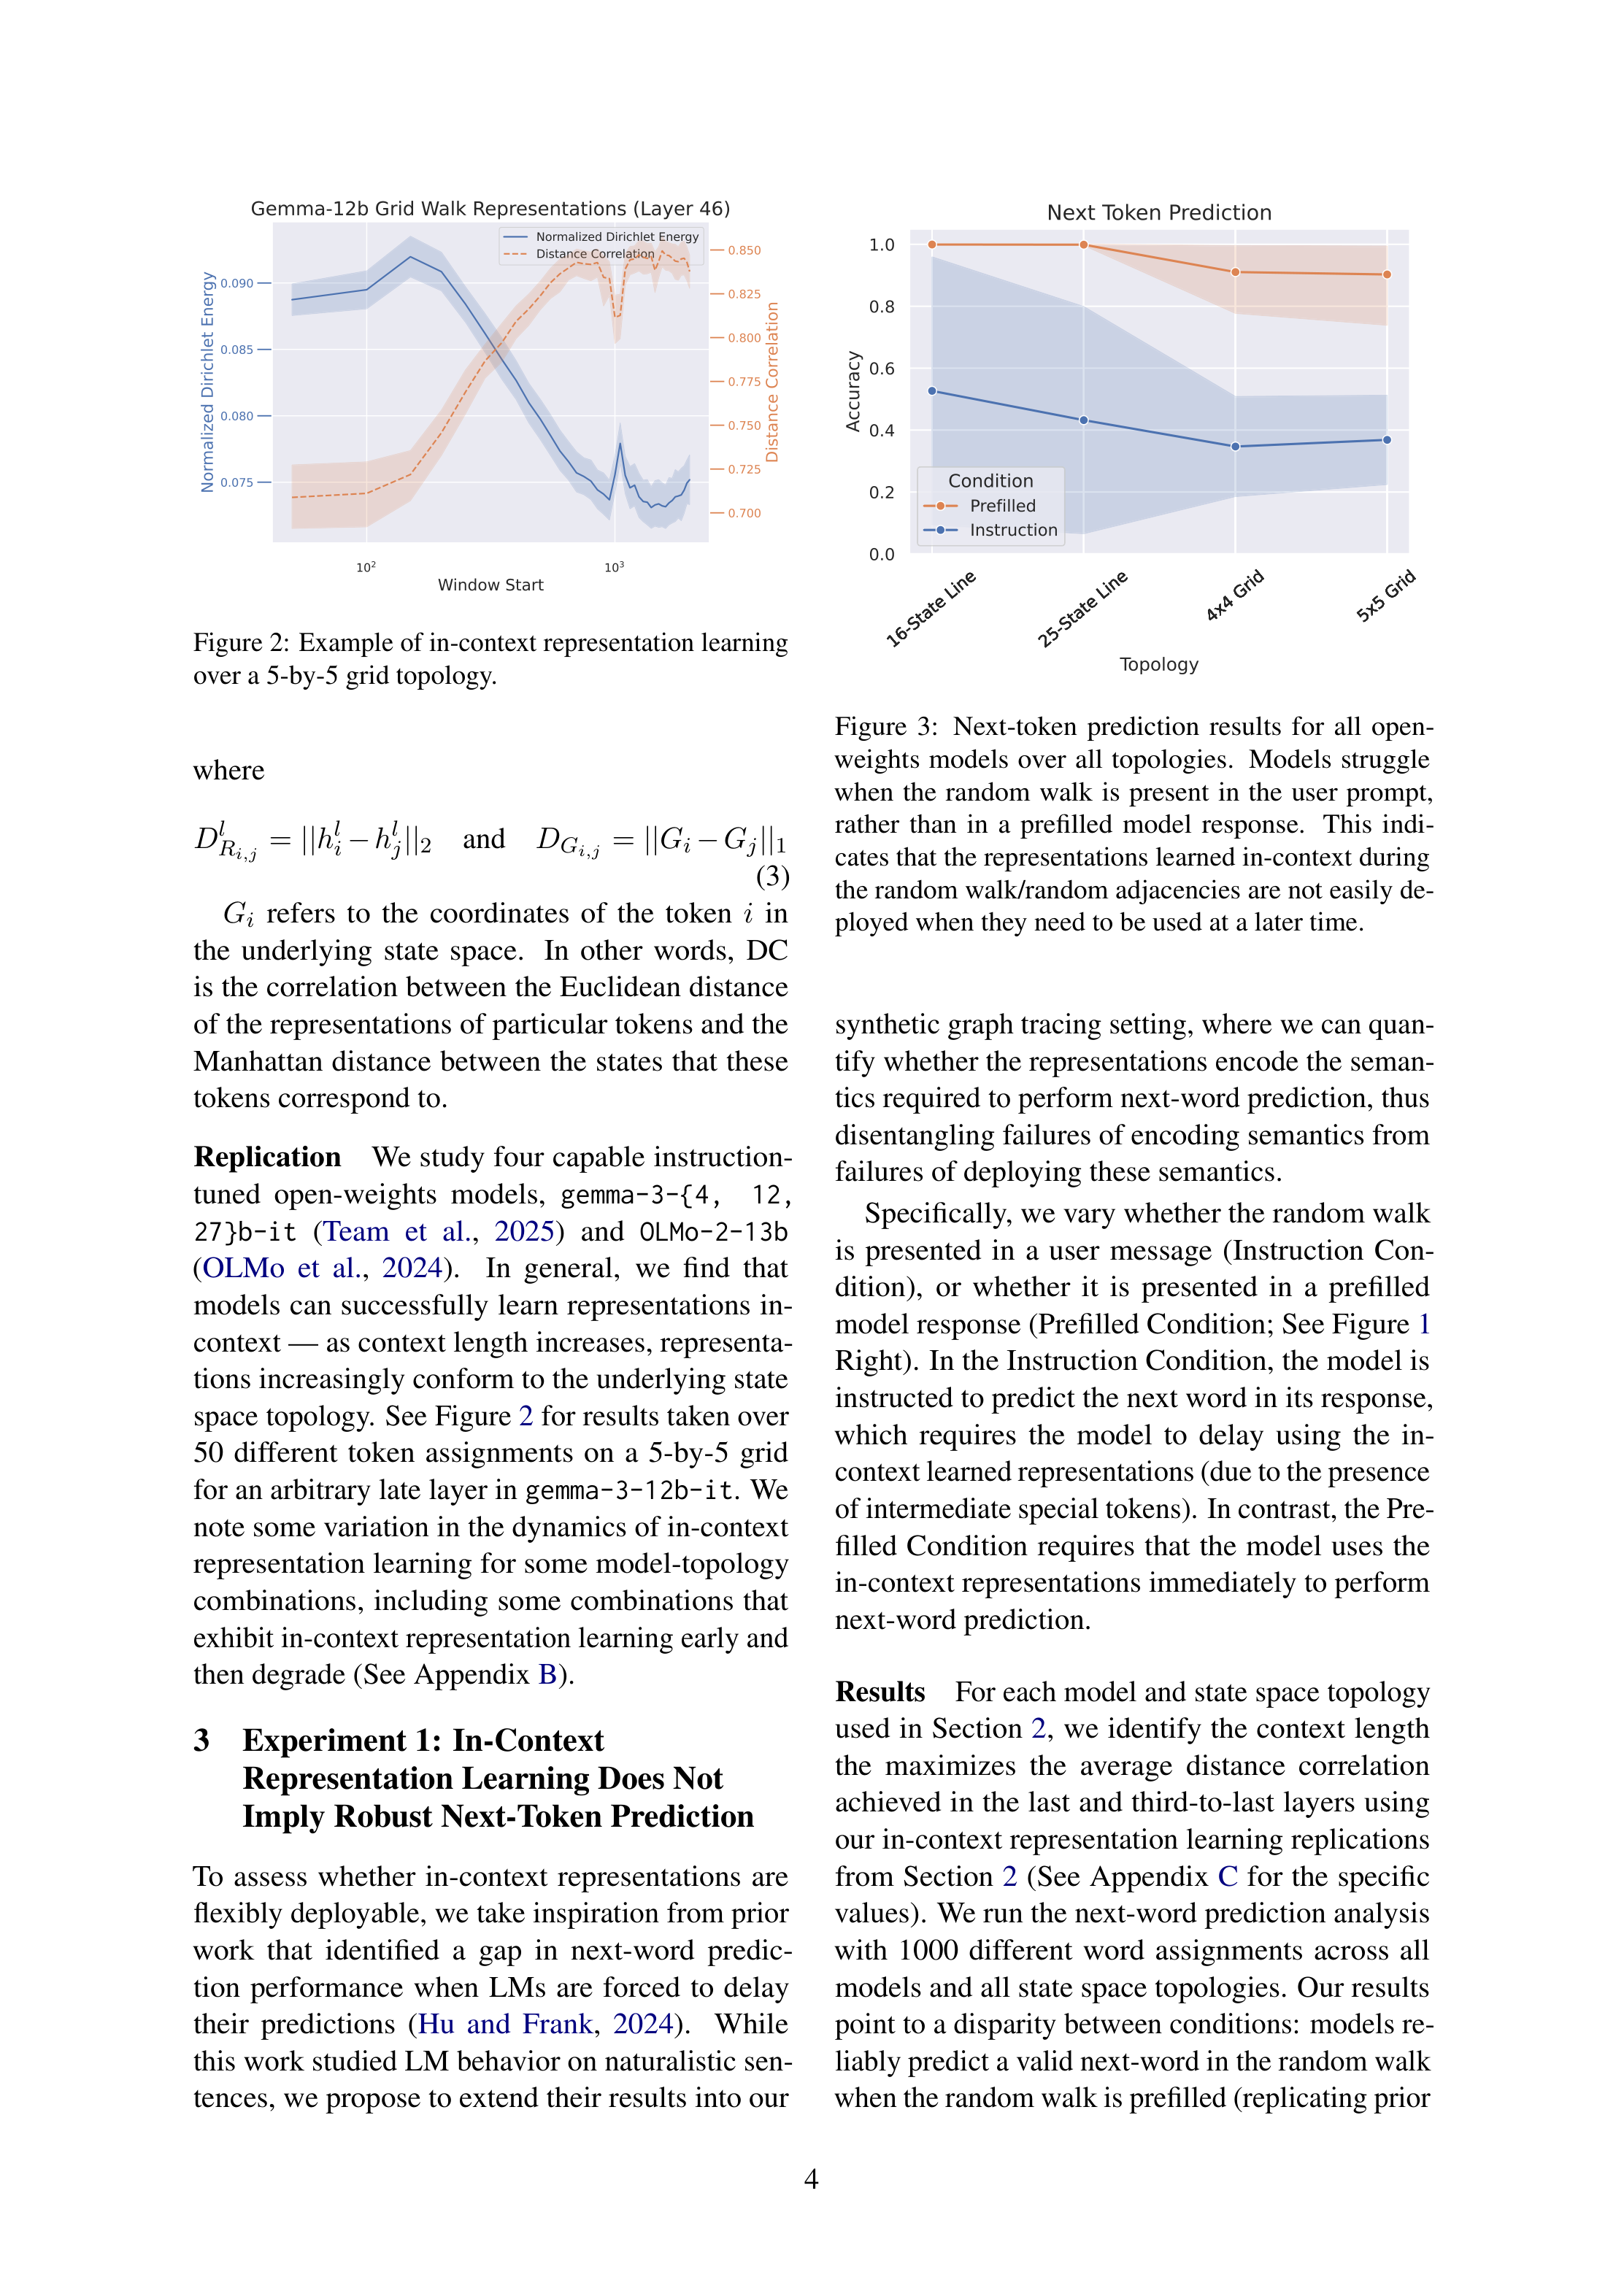
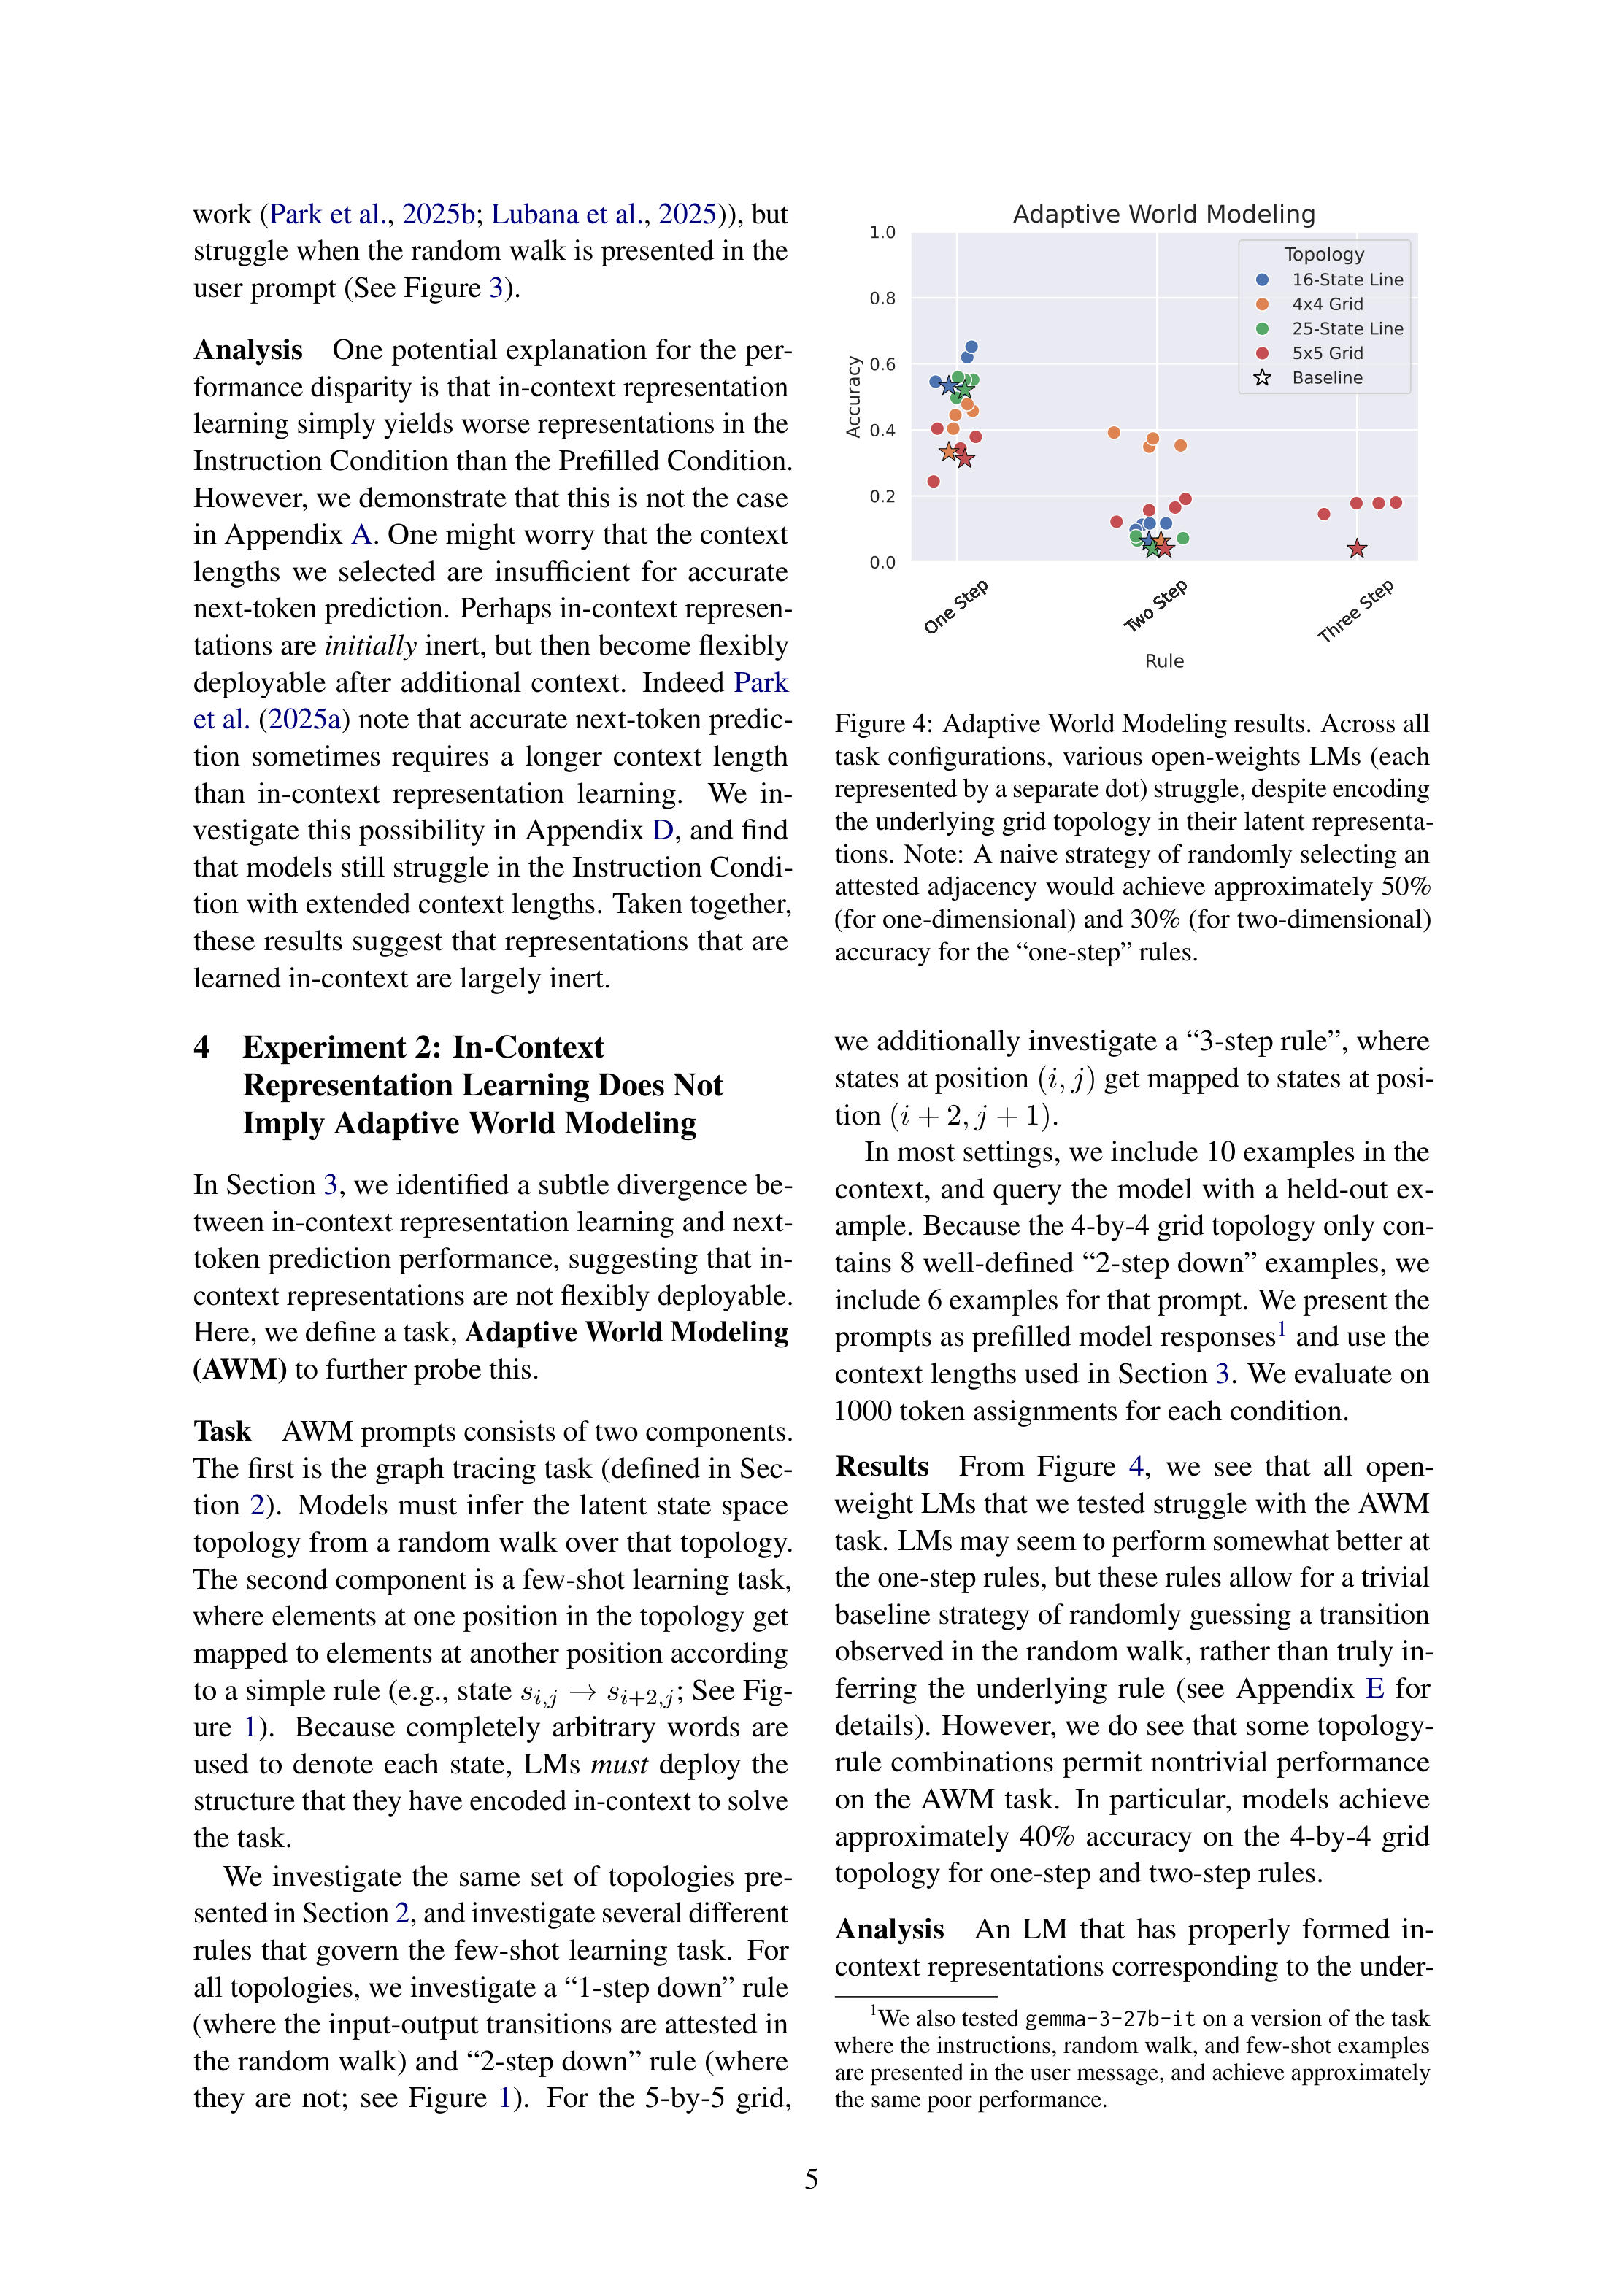
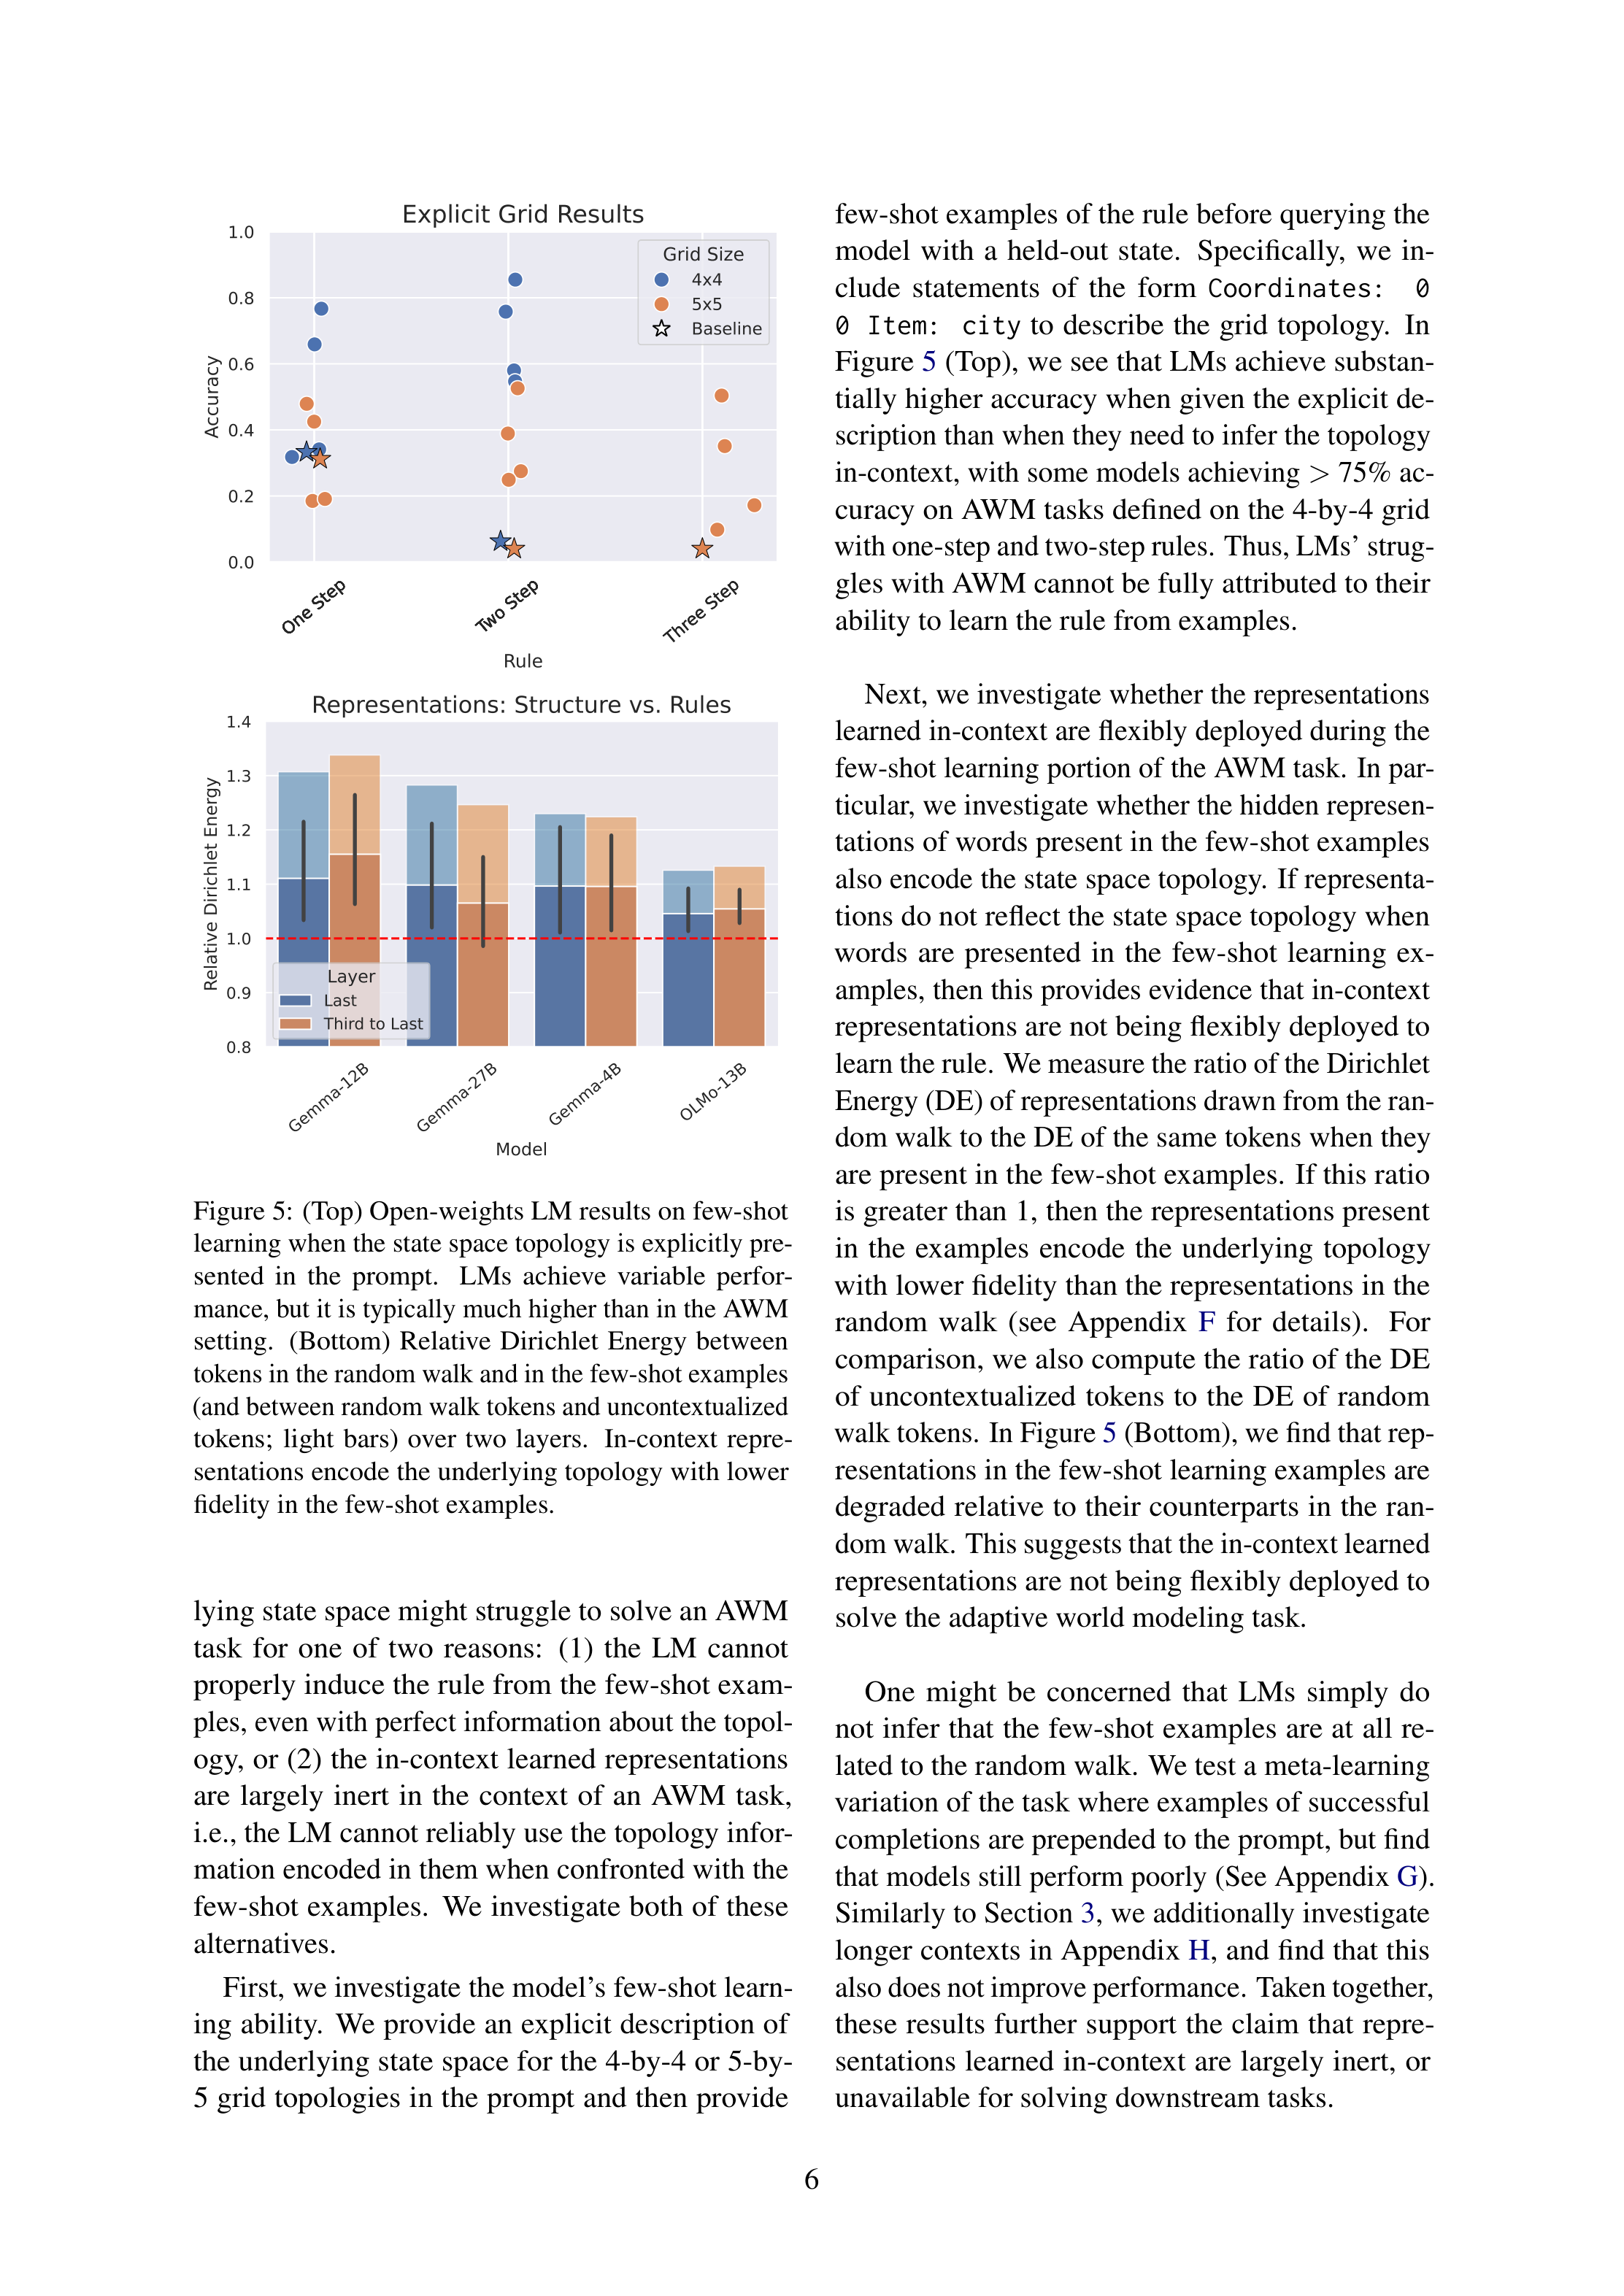
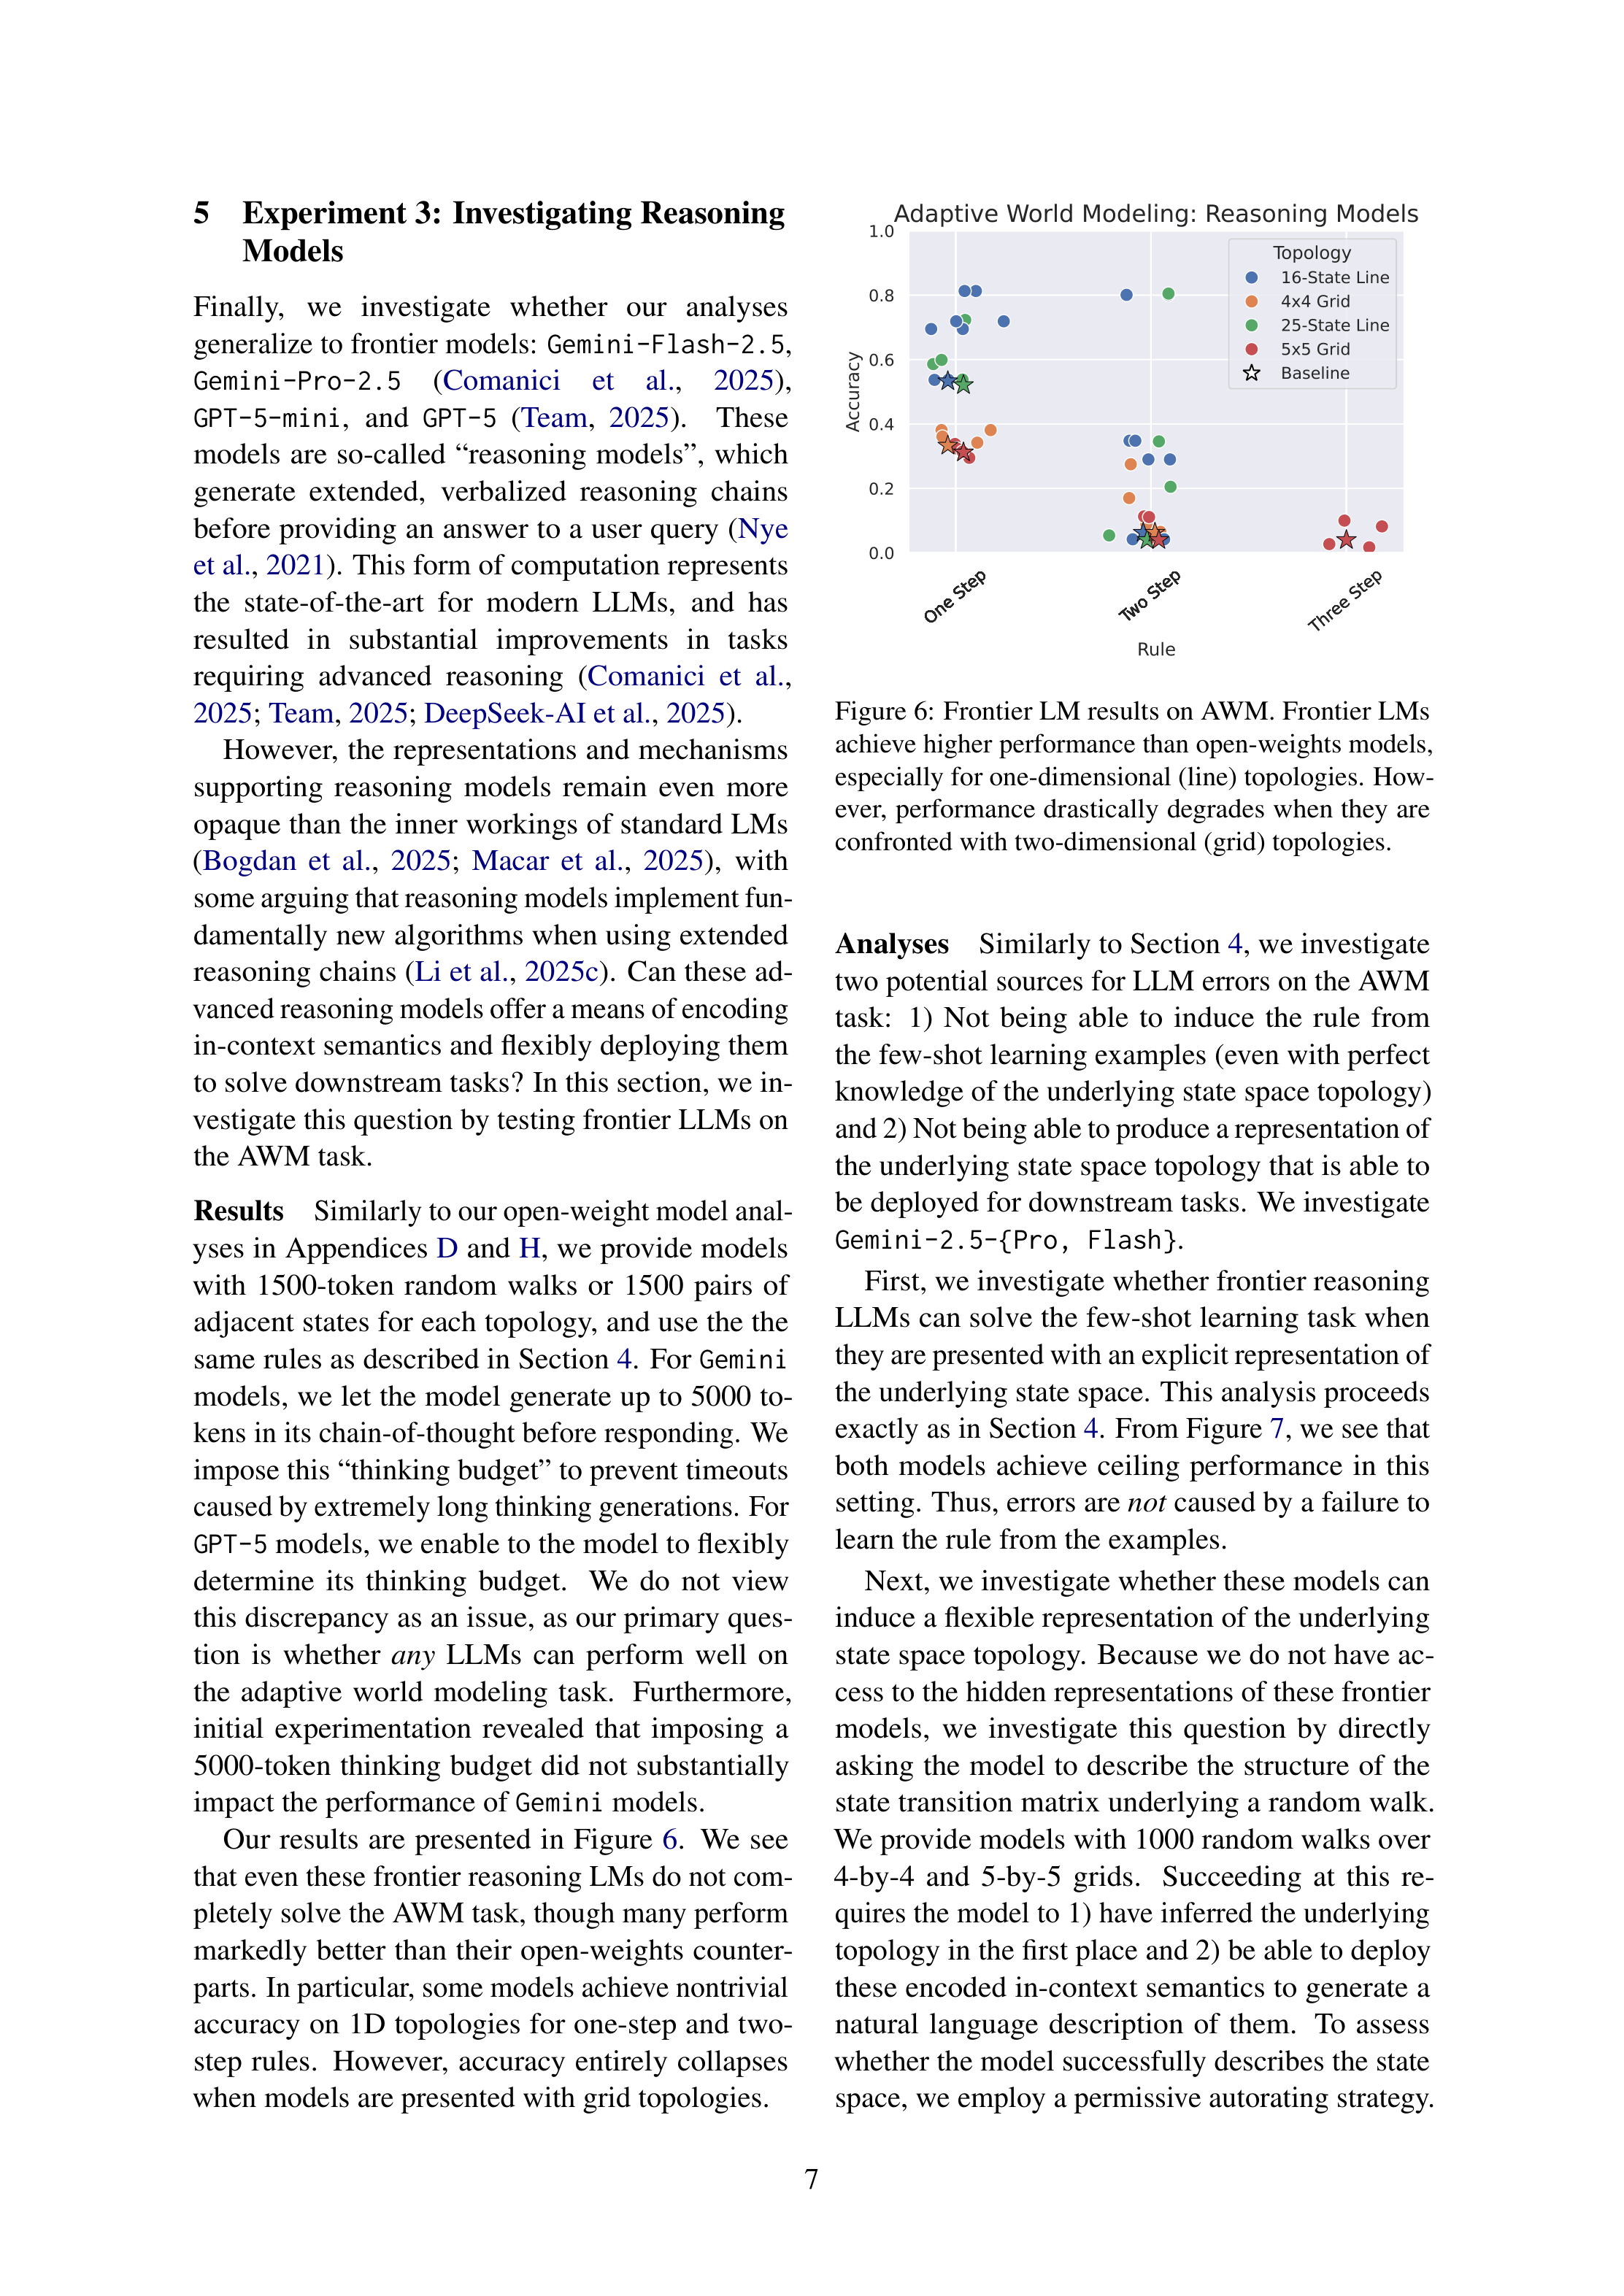
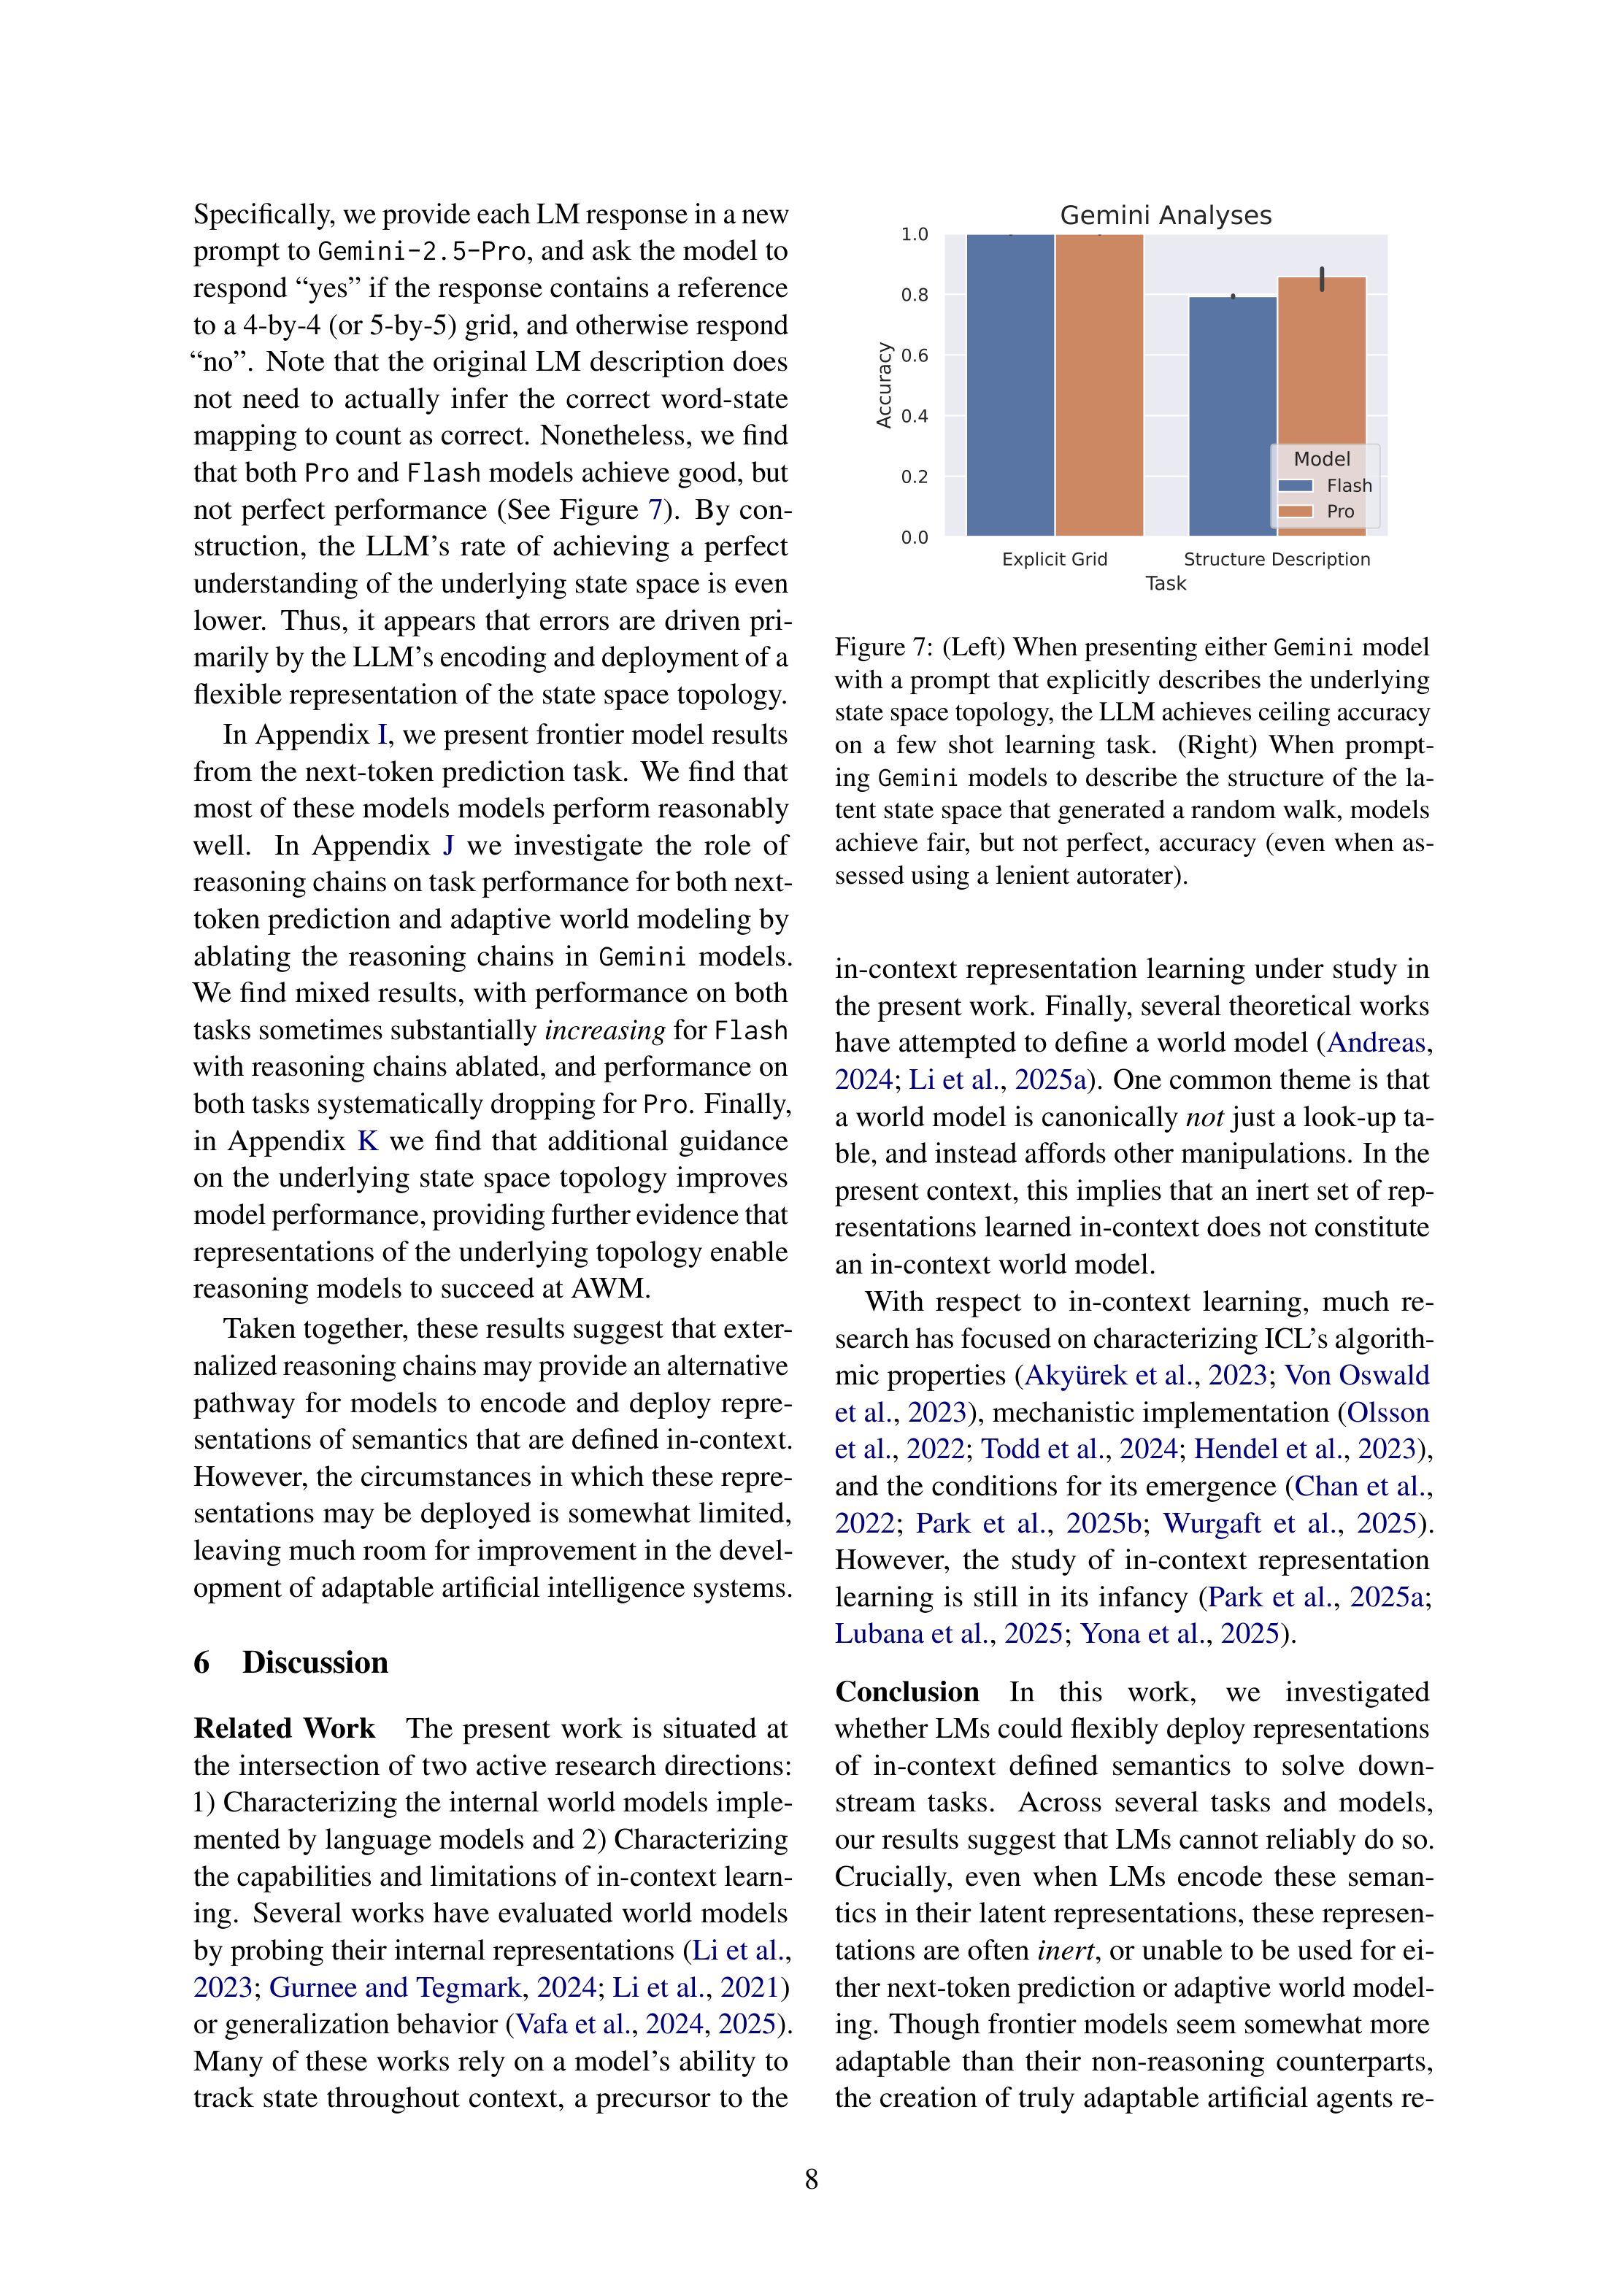
Original Abstract: Though large language models (LLMs) have enabled great success across a wide variety of tasks, they still appear to fall short of one of the loftier goals of artificial intelligence research: creating an artificial system that can adapt its behavior to radically new contexts upon deployment. One important step towards this goal is to create systems that can induce rich representations of data that are seen in-context, and then flexibly deploy these representations to accomplish goals. Recently, Park et al. (2024) demonstrated that current LLMs are indeed capable of inducing such representation from context (i.e., in-context representation learning). The present study investigates whether LLMs can use these representations to complete simple downstream tasks.
We first assess whether open-weights LLMs can use in-context representations for next-token prediction, and then probe models using a novel task, adaptive world modeling. In both tasks, we find evidence that open-weights LLMs struggle to deploy representations of novel semantics that are defined in-context, even if they encode these semantics in their latent representations. Furthermore, we assess closed-source, state-of-the-art reasoning models on the adaptive world modeling task, demonstrating that even the most performant LLMs cannot reliably leverage novel patterns presented in-context. Overall, this work seeks to inspire novel methods for encouraging models to not only encode information presented in-context, but to do so in a manner that supports flexible deployment of this information.
PDF Link: 2602.04212v1
部分平台可能图片显示异常,请以我的博客内容为准
