Ultralytics:解读PSABlock模块
前言
- 由于本人水平有限,难免出现错漏,敬请批评改正。
- 更多精彩内容,可点击进入Python日常小操作专栏、OpenCV-Python小应用专栏、YOLO系列专栏、自然语言处理专栏、人工智能混合编程实践专栏或我的个人主页查看
- YOLOs-CPP:一个免费开源的YOLO全系列C++推理库(以YOLO26为例)
- PaddleOCR:Win10上安装使用PPOCRLabel标注工具
- 目标检测:使用自己的数据集微调DEIMv2进行物体检测
- 图像分割:PyTorch从零开始实现SegFormer语义分割
- 图像超分:使用自己的数据集微调Real-ESRGAN-x4plus进行超分重建
- 图像生成:PyTorch从零开始实现一个简单的扩散模型
- Stable Diffusion:使用自己的数据集微调 Stable Diffusion 3.5 LoRA 文生图模型
- 图像超分:使用自己的数据集微调Real-ESRGAN-x2plus进行超分重建
- Anomalib:使用Anomalib 2.1.0训练自己的数据集进行异常检测
- Anomalib:在Linux服务器上安装使用Anomalib 2.1.0
- 人工智能混合编程实践:C++调用封装好的DLL进行异常检测推理
- 人工智能混合编程实践:C++调用封装好的DLL进行FP16图像超分重建(v3.0)
- 隔离系统Python:源码编译3.11.8到自定义目录(含PGO性能优化)
- 在线机的Python环境迁移到离线机上
- Nuitka 将 Python 脚本封装为 .pyd 或 .so 文件
- Ultralytics:使用 YOLO11 进行速度估计
- Ultralytics:使用 YOLO11 进行物体追踪
- Ultralytics:使用 YOLO11 进行物体计数
- Ultralytics:使用 YOLO11 进行目标打码
- 人工智能混合编程实践:C++调用Python ONNX进行YOLOv8推理
- 人工智能混合编程实践:C++调用封装好的DLL进行YOLOv8实例分割
- 人工智能混合编程实践:C++调用Python ONNX进行图像超分重建
- 人工智能混合编程实践:C++调用Python AgentOCR进行文本识别
- 通过计算实例简单地理解PatchCore异常检测
- Python将YOLO格式实例分割数据集转换为COCO格式实例分割数据集
- YOLOv8 Ultralytics:使用Ultralytics框架训练RT-DETR实时目标检测模型
- 基于DETR的人脸伪装检测
- YOLOv7训练自己的数据集(口罩检测)
- YOLOv8训练自己的数据集(足球检测)
- YOLOv5:TensorRT加速YOLOv5模型推理
- YOLOv5:IoU、GIoU、DIoU、CIoU、EIoU
- 玩转Jetson Nano(五):TensorRT加速YOLOv5目标检测
- YOLOv5:添加SE、CBAM、CoordAtt、ECA注意力机制
- YOLOv5:yolov5s.yaml配置文件解读、增加小目标检测层
- Python将COCO格式实例分割数据集转换为YOLO格式实例分割数据集
- YOLOv5:使用7.0版本训练自己的实例分割模型(车辆、行人、路标、车道线等实例分割)
- 使用Kaggle GPU资源免费体验Stable Diffusion开源项目
- Stable Diffusion:在服务器上部署使用Stable Diffusion WebUI进行AI绘图(v2.0)
- Stable Diffusion:使用自己的数据集微调训练LoRA模型(v2.0)
相关介绍
Ultralytics 简介
Ultralytics 基于多年的计算机视觉和人工智能基础研究,创建了最先进的 (SOTA) YOLO 模型。我们的模型不断更新性能和灵活性,快速、准确且易于使用。他们擅长对象检测、跟踪、实例分割、语义分割、图像分类和姿势估计任务。
前提条件
- 熟悉Python、Pytorch
实验环境
bash
Package                  Version
------------------------ ------------
Python                   3.11.8
absl-py                  2.4.0
accelerate               1.13.0
annotated-doc            0.0.4
anyio                    4.13.0
calflops                 0.3.2
certifi                  2026.4.22
charset-normalizer       3.4.7
click                    8.3.3
colorama                 0.4.6
contourpy                1.3.3
cycler                   0.12.1
filelock                 3.29.0
flatbuffers              25.12.19
fonttools                4.62.1
fsspec                   2026.4.0
grpcio                   1.80.0
h11                      0.16.0
hf-xet                   1.5.0
httpcore                 1.0.9
httpx                    0.28.1
huggingface_hub          1.14.0
idna                     3.15
Jinja2                   3.1.6
kiwisolver               1.5.0
Markdown                 3.10.2
markdown-it-py           4.2.0
MarkupSafe               3.0.3
matplotlib               3.10.9
mdurl                    0.1.2
ml_dtypes                0.5.0
mpmath                   1.3.0
networkx                 3.6.1
numpy                    1.26.4
nvidia-cublas-cu12       12.8.3.14
nvidia-cuda-cupti-cu12   12.8.57
nvidia-cuda-nvrtc-cu12   12.8.61
nvidia-cuda-runtime-cu12 12.8.57
nvidia-cudnn-cu12        9.7.1.26
nvidia-cufft-cu12        11.3.3.41
nvidia-cufile-cu12       1.13.0.11
nvidia-curand-cu12       10.3.9.55
nvidia-cusolver-cu12     11.7.2.55
nvidia-cusparse-cu12     12.5.7.53
nvidia-cusparselt-cu12   0.6.3
nvidia-nccl-cu12         2.26.2
nvidia-nvjitlink-cu12    12.8.61
nvidia-nvtx-cu12         12.8.55
onnx                     1.19.0
onnxruntime-gpu          1.26.0
onnxslim                 0.1.94
opencv-python            4.6.0.66
packaging                26.2
pillow                   12.2.0
pip                      24.0
polars                   1.40.1
polars-runtime-32        1.40.1
protobuf                 7.34.1
psutil                   7.2.2
pycocotools              2.0.11
Pygments                 2.20.0
pyparsing                3.3.2
python-dateutil          2.9.0.post0
PyYAML                   6.0.3
regex                    2026.5.9
requests                 2.34.1
rich                     15.0.0
safetensors              0.7.0
scipy                    1.16.0
setuptools               65.5.0
shellingham              1.5.4
six                      1.17.0
sympy                    1.14.0
tabulate                 0.10.0
tensorboard              2.20.0
tensorboard-data-server  0.7.2
tokenizers               0.22.2
torch                    2.7.1+cu128
torchaudio               2.7.1+cu128
torchvision              0.22.1+cu128
tqdm                     4.67.3
transformers             5.8.1
triton                   3.3.1
typer                    0.25.1
typing_extensions        4.15.0
ultralytics              8.4.58
ultralytics-thop         2.0.19
urllib3                  2.7.0
Werkzeug                 3.1.8
PSABlock(位置敏感注意力模块)
PSABlock 是一种 Transformer 风格 的模块,它结合了 多头自注意力(Attention) 和 前馈网络(FFN) ,并通过 残差连接 构建深度结构。该模块常用于 YOLOv8 等网络中的 C2f 内部,以增强特征表达能力,特别适合需要全局上下文建模的任务。
代码实现
python
import cv2
import math
import torch
import numpy as np
import matplotlib.pyplot as plt
from torch import nn

def autopad(k, p=None, d=1):  # kernel, padding, dilation
    """Pad to 'same' shape outputs."""
    if d > 1:
        k = d * (k - 1) + 1 if isinstance(k, int) else [d * (x - 1) + 1 for x in k]  # actual kernel-size
    if p is None:
        p = k // 2 if isinstance(k, int) else [x // 2 for x in k]  # auto-pad
    return p

class Conv(nn.Module):
    """Standard convolution module with batch normalization and activation.

    Attributes:
        conv (nn.Conv2d): Convolutional layer.
        bn (nn.BatchNorm2d): Batch normalization layer.
        act (nn.Module): Activation function layer.
        default_act (nn.Module): Default activation function (SiLU).
    """

    default_act = nn.SiLU()  # default activation

    def __init__(self, c1, c2, k=1, s=1, p=None, g=1, d=1, act=True):
        """Initialize Conv layer with given parameters.

        Args:
            c1 (int): Number of input channels.
            c2 (int): Number of output channels.
            k (int): Kernel size.
            s (int): Stride.
            p (int, optional): Padding.
            g (int): Groups.
            d (int): Dilation.
            act (bool | nn.Module): Activation function.
        """
        super().__init__()
        self.conv = nn.Conv2d(c1, c2, k, s, autopad(k, p, d), groups=g, dilation=d, bias=False)
        self.bn = nn.BatchNorm2d(c2)
        self.act = self.default_act if act is True else act if isinstance(act, nn.Module) else nn.Identity()

    def forward(self, x):
        """Apply convolution, batch normalization and activation to input tensor.

        Args:
            x (torch.Tensor): Input tensor.

        Returns:
            (torch.Tensor): Output tensor.
        """
        return self.act(self.bn(self.conv(x)))

    def forward_fuse(self, x):
        """Apply convolution and activation without batch normalization.

        Args:
            x (torch.Tensor): Input tensor.

        Returns:
            (torch.Tensor): Output tensor.
        """
        return self.act(self.conv(x))

class Attention(nn.Module):
    """Attention module that performs self-attention on the input tensor.

    Args:
        dim (int): The input tensor dimension.
        num_heads (int): The number of attention heads.
        attn_ratio (float): The ratio of the attention key dimension to the head dimension.

    Attributes:
        num_heads (int): The number of attention heads.
        head_dim (int): The dimension of each attention head.
        key_dim (int): The dimension of the attention key.
        scale (float): The scaling factor for the attention scores.
        qkv (Conv): Convolutional layer for computing the query, key, and value.
        proj (Conv): Convolutional layer for projecting the attended values.
        pe (Conv): Convolutional layer for positional encoding.
    """

    def __init__(self, dim: int, num_heads: int = 8, attn_ratio: float = 0.5):
        """Initialize multi-head attention module.

        Args:
            dim (int): Input dimension.
            num_heads (int): Number of attention heads.
            attn_ratio (float): Attention ratio for key dimension.
        """
        super().__init__()
        self.num_heads = num_heads
        self.head_dim = dim // num_heads
        self.key_dim = int(self.head_dim * attn_ratio)
        self.scale = self.key_dim**-0.5
        nh_kd = self.key_dim * num_heads
        h = dim + nh_kd * 2
        self.qkv = Conv(dim, h, 1, act=False)
        self.proj = Conv(dim, dim, 1, act=False)
        self.pe = Conv(dim, dim, 3, 1, g=dim, act=False)

    def forward(self, x: torch.Tensor) -> torch.Tensor:
        """Forward pass of the Attention module.

        Args:
            x (torch.Tensor): The input tensor.

        Returns:
            (torch.Tensor): The output tensor after self-attention.
        """
        B, C, H, W = x.shape
        N = H * W
        qkv = self.qkv(x)
        q, k, v = qkv.view(B, self.num_heads, self.key_dim * 2 + self.head_dim, N).split(
            [self.key_dim, self.key_dim, self.head_dim], dim=2
        )

        attn = (q.transpose(-2, -1) @ k) * self.scale
        attn = attn.softmax(dim=-1)
        x = (v @ attn.transpose(-2, -1)).view(B, C, H, W) + self.pe(v.reshape(B, C, H, W))
        x = self.proj(x)
        return x

class PSABlock(nn.Module):
    """PSABlock class implementing a Position-Sensitive Attention block for neural networks.

    This class encapsulates the functionality for applying multi-head attention and feed-forward neural network layers
    with optional shortcut connections.

    Attributes:
        attn (Attention): Multi-head attention module.
        ffn (nn.Sequential): Feed-forward neural network module.
        add (bool): Flag indicating whether to add shortcut connections.

    Methods:
        forward: Performs a forward pass through the PSABlock, applying attention and feed-forward layers.

    Examples:
        Create a PSABlock and perform a forward pass
        >>> psablock = PSABlock(c=128, attn_ratio=0.5, num_heads=4, shortcut=True)
        >>> input_tensor = torch.randn(1, 128, 32, 32)
        >>> output_tensor = psablock(input_tensor)
    """

    def __init__(self, c: int, attn_ratio: float = 0.5, num_heads: int = 4, shortcut: bool = True) -> None:
        """Initialize the PSABlock.

        Args:
            c (int): Input and output channels.
            attn_ratio (float): Attention ratio for key dimension.
            num_heads (int): Number of attention heads.
            shortcut (bool): Whether to use shortcut connections.
        """
        super().__init__()

        self.attn = Attention(c, attn_ratio=attn_ratio, num_heads=num_heads)
        self.ffn = nn.Sequential(Conv(c, c * 2, 1), Conv(c * 2, c, 1, act=False))
        self.add = shortcut

    def forward(self, x: torch.Tensor) -> torch.Tensor:
        """Execute a forward pass through PSABlock.

        Args:
            x (torch.Tensor): Input tensor.

        Returns:
            (torch.Tensor): Output tensor after attention and feed-forward processing.
        """
        x = x + self.attn(x) if self.add else self.attn(x)
        x = x + self.ffn(x) if self.add else self.ffn(x)
        return x
功能
- 多头自注意力 :通过
Attention模块捕获全局空间依赖,让每个位置关注所有位置。 - 前馈网络:使用两个 1×1 卷积(先升维再降维)进行非线性变换,增强特征表示。
- 残差连接 :可选(
shortcut参数),默认启用,在每个子层后添加输入,促进梯度传播。 - 位置敏感 :
Attention内部包含位置编码(深度卷积),使得注意力具有位置感知能力。
初始化参数
| 参数 | 类型 | 说明 |
|---|---|---|
c |
int | 输入和输出通道数(模块不改变通道数) |
attn_ratio |
float | Attention 模块的键维度比例(默认 0.5) |
num_heads |
int | 注意力头数(默认 4,c 必须能被其整除) |
shortcut |
bool | 是否使用残差连接(默认 True) |
前向方法
forward(x):输入x([B, c, H, W]),输出[B, c, H, W]。
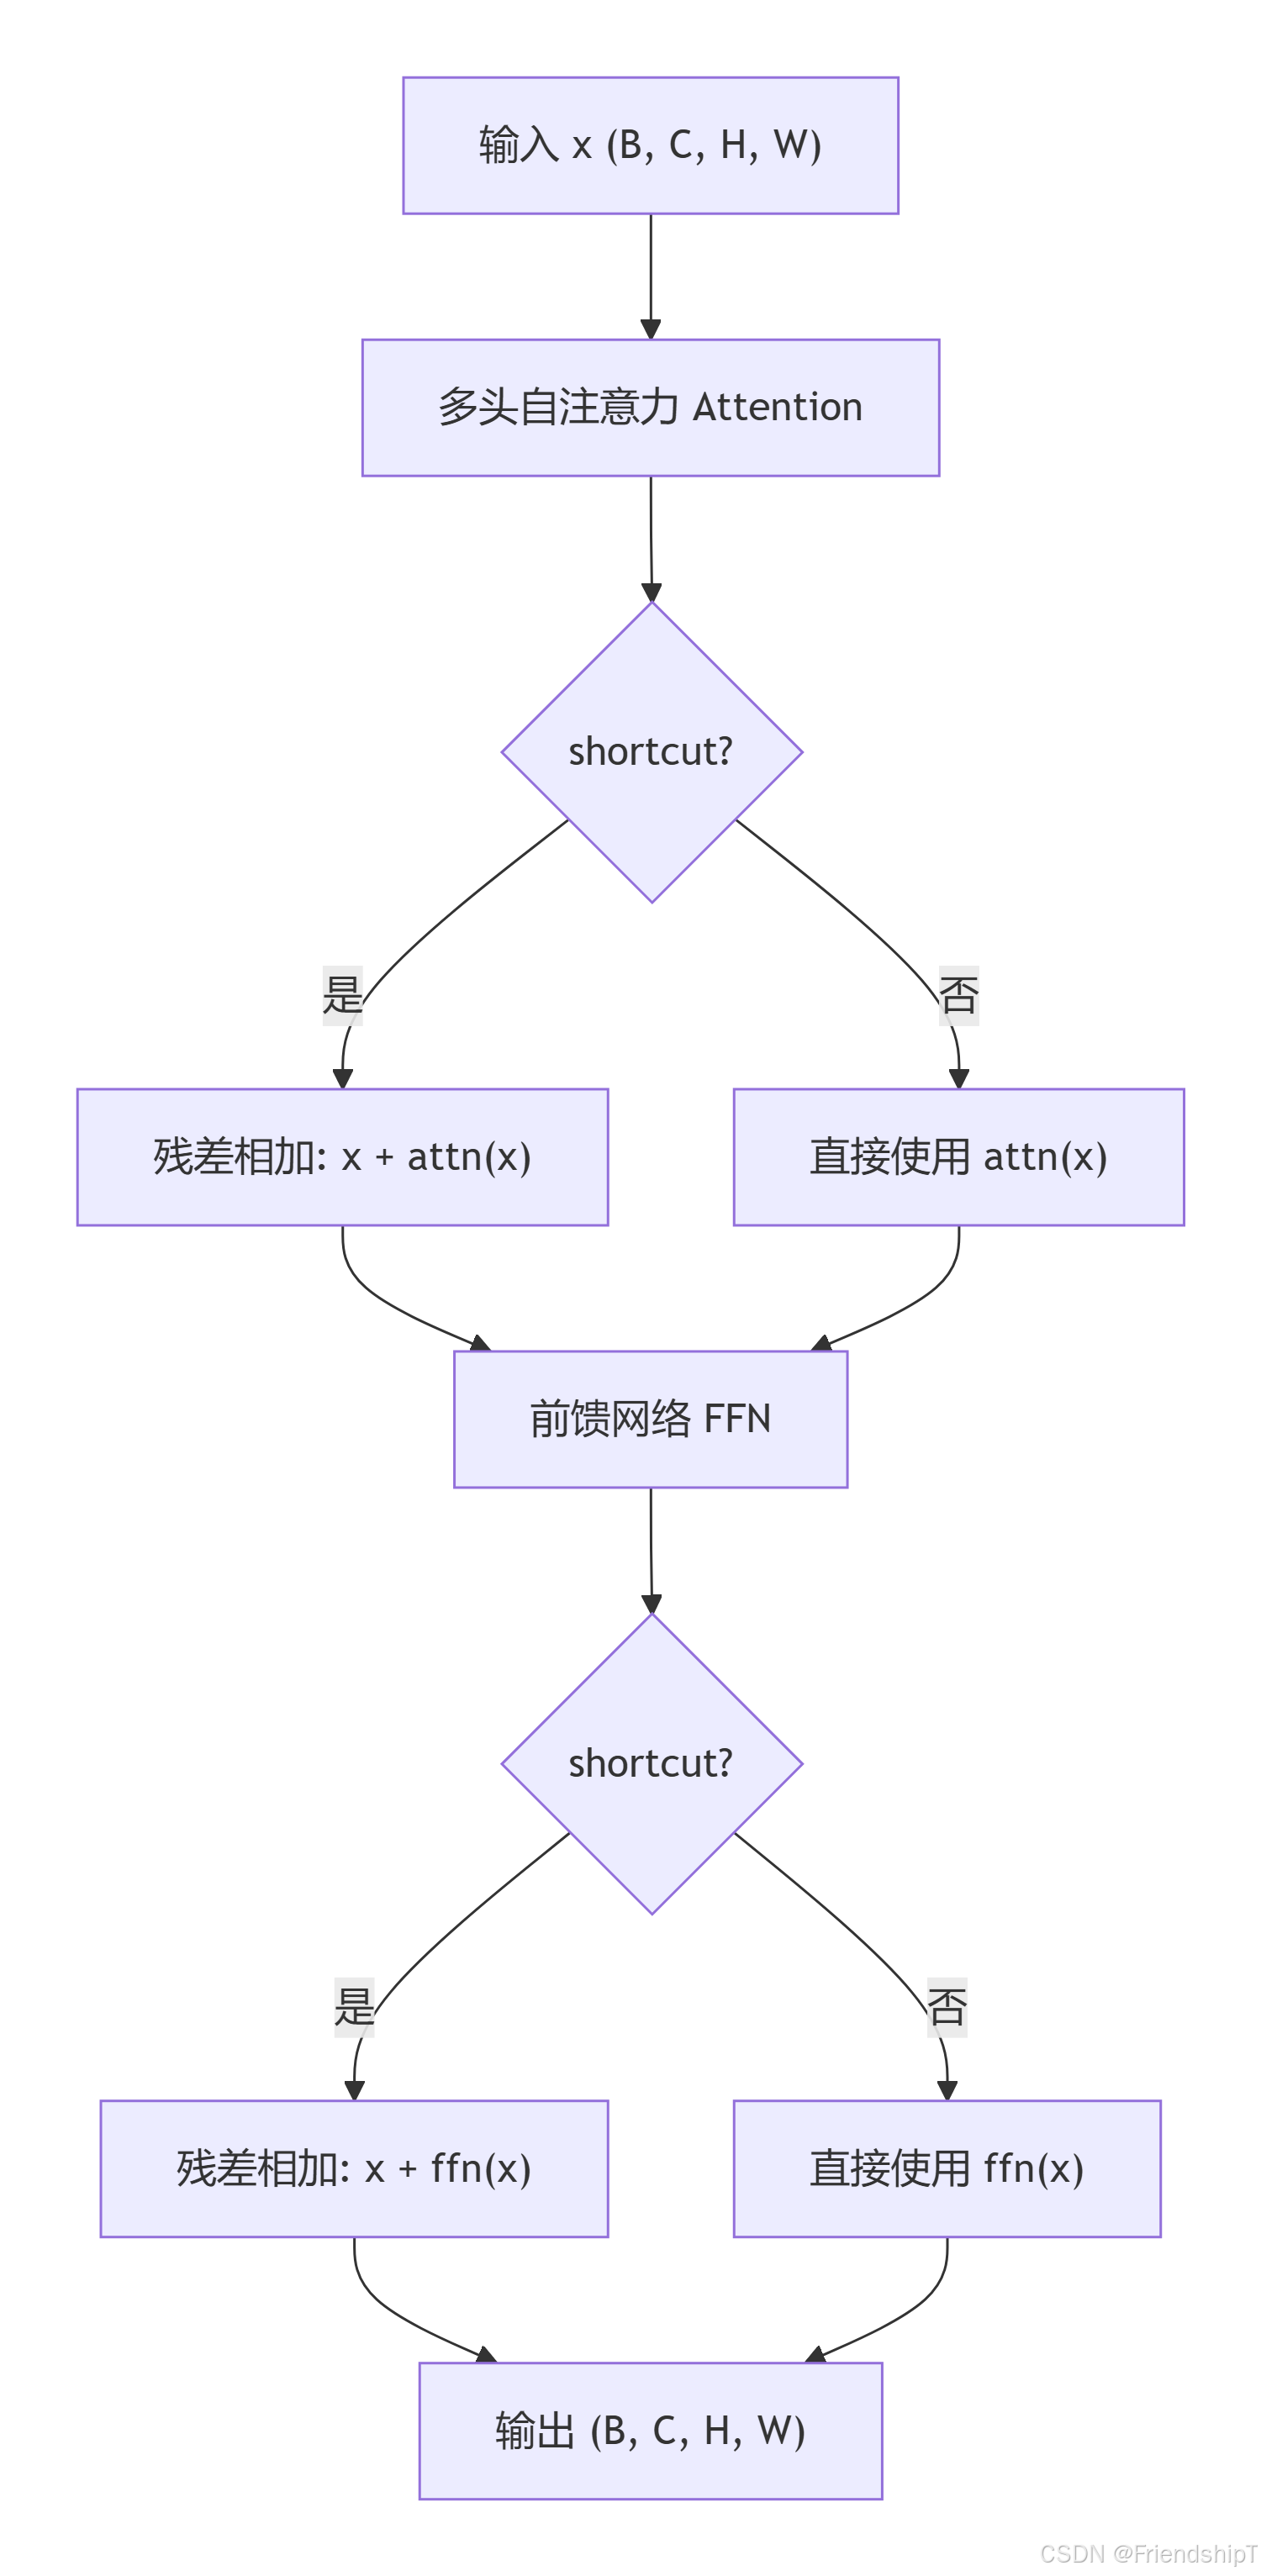
计算流程:
- 第一个残差块:
x = x + self.attn(x)(若shortcut=True)或x = self.attn(x)(若shortcut=False)。 - 第二个残差块:
x = x + self.ffn(x)(若shortcut=True)或x = self.ffn(x)(若shortcut=False)。 - 返回最终结果。
使用示例
python
if __name__ == '__main__':
    # 1. 创建随机输入
    x = torch.randn(1, 64, 32, 32)

    # 2. 创建 PSABlock 模块
    psa = PSABlock(c=64, attn_ratio=0.5, num_heads=4, shortcut=True)

    # 3. 前向传播
    with torch.no_grad():
        out = psa(x)
    print("输入形状:", x.shape)   # [1, 64, 32, 32]
    print("输出形状:", out.shape) # [1, 64, 32, 32]

    # 4. 使用真实图像演示(扩展为多通道)
    img_path = "cat_640x640.png"
    img_bgr = cv2.imread(img_path)
    if img_bgr is not None:
        # 缩放到 64x64,转为灰度图
        img_gray = cv2.cvtColor(cv2.resize(img_bgr, (64, 64)), cv2.COLOR_BGR2GRAY)
        img_tensor = torch.from_numpy(img_gray).float().unsqueeze(0).unsqueeze(0)  # [1,1,64,64]
        # 扩展通道数至 64(模拟特征图)
        x_img = img_tensor.repeat(1, 64, 1, 1)  # [1,64,64,64]

        # 创建 PSABlock(c=64)
        psa_img = PSABlock(c=64, attn_ratio=0.5, num_heads=4, shortcut=True)
        with torch.no_grad():
            out_img = psa_img(x_img)  # [1,64,64,64]

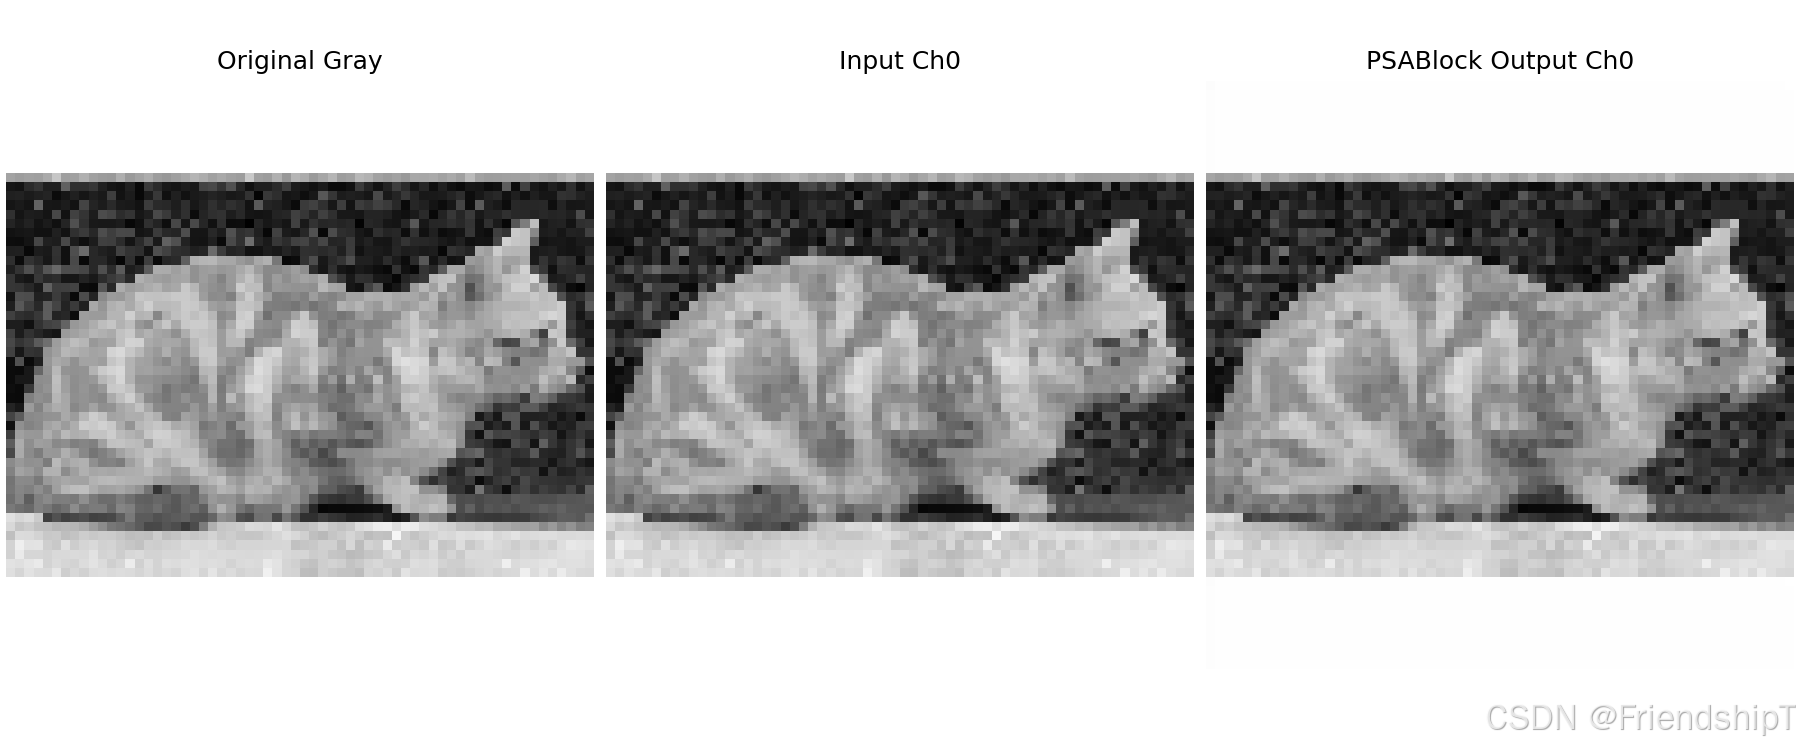
        # 可视化:输入通道0、输出通道0
        inp_ch0 = x_img[0, 0].cpu().numpy()
        out_ch0 = out_img[0, 0].cpu().numpy()

        def norm(arr):
            return (arr - arr.min()) / (arr.max() - arr.min() + 1e-8)

        plt.figure(figsize=(12, 5), constrained_layout=True)
        plt.subplot(1, 3, 1)
        plt.imshow(img_gray, cmap='gray')
        plt.title("Original Gray")
        plt.axis("off")
        plt.subplot(1, 3, 2)
        plt.imshow(norm(inp_ch0), cmap='gray')
        plt.title("Input Ch0")
        plt.axis("off")
        plt.subplot(1, 3, 3)
        plt.imshow(norm(out_ch0), cmap='gray')
        plt.title("PSABlock Output Ch0")
        plt.axis("off")
        plt.savefig("psablock_demo.png", dpi=150)
print("可视化已保存为 psablock_demo.png")输出示例:
输入形状: torch.Size([1, 64, 32, 32])
输出形状: torch.Size([1, 64, 32, 32])
可视化已保存为 psablock_demo.png
流程示意图
代码解读
__init__:self.attn = Attention(c, attn_ratio, num_heads):初始化自注意力模块。self.ffn = nn.Sequential(Conv(c, c*2, 1), Conv(c*2, c, 1, act=False)):两层 1×1 卷积,先升维至2c,再降维回c,第二层无激活(act=False,仅 BN 无激活)。self.add = shortcut:存储残差标志。
forward:- 若
self.add为真,使用残差连接;否则直接应用子层。 - 顺序:先注意力,再 FFN。
- 若
注意事项
- 通道数不变:该模块输入输出通道数相同,适用于特征细化而非维度变换。
- 空间尺寸不变:所有卷积步长为 1,填充自动 same,空间尺寸保持不变。
- 残差控制 :若
shortcut=False,模块相当于两个子层的串联,无残差,可能影响深层梯度。 - FFN 设计:使用 1×1 卷积实现,相当于全连接层,但保持空间结构。
- 与标准 Transformer 块对比:本模块用卷积实现投影和位置编码,更适用于视觉特征图。
优缺点
优点
- 全局上下文建模:自注意力捕获长距离依赖,提升特征表示能力。
- 卷积实现高效:所有操作均为卷积,易于在 GPU 上加速,且保留空间结构。
- 即插即用 :可嵌入 YOLOv8 的
C2f等模块,替代传统 Bottleneck。 - 灵活配置 :通过
attn_ratio和num_heads调节计算复杂度。
缺点
- 计算量较大:自注意力的复杂度与空间尺寸平方相关,在高分辨率特征图上开销大。
- 无显式归一化:内部未包含 LayerNorm 或 BatchNorm,可能需外部添加。
- 位置编码依赖深度卷积:对 V 的卷积编码可能引入额外参数。
在 YOLOv8 中,PSABlock 可作为 C2f 的替代组件,用于构建更强大的特征提取层。使用时建议在中等分辨率特征图(如 16×16 或 8×8)上启用,以避免显存溢出。
参考文献
1 https://docs.ultralytics.com/
2 https://github.com/ultralytics/ultralytics.git
- 由于本人水平有限,难免出现错漏,敬请批评改正。
- 更多精彩内容,可点击进入Python日常小操作专栏、OpenCV-Python小应用专栏、YOLO系列专栏、自然语言处理专栏、人工智能混合编程实践专栏或我的个人主页查看
- YOLOs-CPP:一个免费开源的YOLO全系列C++推理库(以YOLO26为例)
- PaddleOCR:Win10上安装使用PPOCRLabel标注工具
- 目标检测:使用自己的数据集微调DEIMv2进行物体检测
- 图像分割:PyTorch从零开始实现SegFormer语义分割
- 图像超分:使用自己的数据集微调Real-ESRGAN-x4plus进行超分重建
- 图像生成:PyTorch从零开始实现一个简单的扩散模型
- Stable Diffusion:使用自己的数据集微调 Stable Diffusion 3.5 LoRA 文生图模型
- 图像超分:使用自己的数据集微调Real-ESRGAN-x2plus进行超分重建
- Anomalib:使用Anomalib 2.1.0训练自己的数据集进行异常检测
- Anomalib:在Linux服务器上安装使用Anomalib 2.1.0
- 人工智能混合编程实践:C++调用封装好的DLL进行异常检测推理
- 人工智能混合编程实践:C++调用封装好的DLL进行FP16图像超分重建(v3.0)
- 隔离系统Python:源码编译3.11.8到自定义目录(含PGO性能优化)
- 在线机的Python环境迁移到离线机上
- Nuitka 将 Python 脚本封装为 .pyd 或 .so 文件
- Ultralytics:使用 YOLO11 进行速度估计
- Ultralytics:使用 YOLO11 进行物体追踪
- Ultralytics:使用 YOLO11 进行物体计数
- Ultralytics:使用 YOLO11 进行目标打码
- 人工智能混合编程实践:C++调用Python ONNX进行YOLOv8推理
- 人工智能混合编程实践:C++调用封装好的DLL进行YOLOv8实例分割
- 人工智能混合编程实践:C++调用Python ONNX进行图像超分重建
- 人工智能混合编程实践:C++调用Python AgentOCR进行文本识别
- 通过计算实例简单地理解PatchCore异常检测
- Python将YOLO格式实例分割数据集转换为COCO格式实例分割数据集
- YOLOv8 Ultralytics:使用Ultralytics框架训练RT-DETR实时目标检测模型
- 基于DETR的人脸伪装检测
- YOLOv7训练自己的数据集(口罩检测)
- YOLOv8训练自己的数据集(足球检测)
- YOLOv5:TensorRT加速YOLOv5模型推理
- YOLOv5:IoU、GIoU、DIoU、CIoU、EIoU
- 玩转Jetson Nano(五):TensorRT加速YOLOv5目标检测
- YOLOv5:添加SE、CBAM、CoordAtt、ECA注意力机制
- YOLOv5:yolov5s.yaml配置文件解读、增加小目标检测层
- Python将COCO格式实例分割数据集转换为YOLO格式实例分割数据集
- YOLOv5:使用7.0版本训练自己的实例分割模型(车辆、行人、路标、车道线等实例分割)
- 使用Kaggle GPU资源免费体验Stable Diffusion开源项目
- Stable Diffusion:在服务器上部署使用Stable Diffusion WebUI进行AI绘图(v2.0)
- Stable Diffusion:使用自己的数据集微调训练LoRA模型(v2.0)