断断续续地做图像识别的应用,使用过各种图像识别算法,一开始使用openCV 做教室学生计数的程序。以后又使用YOLO 做医学伤口检测程序。最近,开始使用meta 公司的Detectron2.打算做OCR 文档结构分析
Detectron2 的开发者是 Meta 的 Facebook AI 研究 (FAIR) 团队,他们表示"我们开发 Detectron2 的目标是支持当今各种尖端的物体检测和分割模型,同时也服务于不断变化的尖端研究领域。"
Detectron2 是一个基于 Pytorch 框架构建的深度学习模型,据称该框架是目前最有前途的模块化目标检测库之一。
本文记录在MAC Mini M4 上做的测试。
安装
bash
pip install 'git+https://github.com/facebookresearch/detectron2.git@v0.4#egg=detectron2'
pip install layoutparser
pip install Pillow==9.5.0
代码
python
#https://towardsdatascience.com/understanding-detectron2-demo-bc648ea569e5/
import argparse

import cv2
import numpy as np
import re

from detectron2 import model_zoo
from detectron2.config import get_cfg, CfgNode
from detectron2.data import MetadataCatalog
from detectron2.engine import DefaultPredictor
from detectron2.structures import Instances
from detectron2.utils.visualizer import Visualizer, VisImage


def _get_parsed_args() -> argparse.Namespace:
    """
    Create an argument parser and parse arguments.

    :return: parsed arguments as a Namespace object
    """

    parser = argparse.ArgumentParser(description="Detectron2 demo")

    # default model is the one with the 2nd highest mask AP
    # (Average Precision) and very high speed from Detectron2 model zoo
    parser.add_argument(
        "--base_model",
        default="COCO-InstanceSegmentation/mask_rcnn_R_101_FPN_3x.yaml",
        help="Base model to be used for training. This is most often "
             "appropriate link to Detectron2 model zoo."
    )

    parser.add_argument(
        "--images",
        nargs="+",
        help="A list of space separated image files that will be processed. "
             "Results will be saved next to the original images with "
             "'_processed_' appended to file name."
    )

    return parser.parse_args()


if __name__ == "__main__":
    args: argparse.Namespace = _get_parsed_args()

    cfg: CfgNode = get_cfg()
    cfg.merge_from_file(model_zoo.get_config_file(args.base_model))
    cfg.MODEL.ROI_HEADS.SCORE_THRESH_TEST = 0.4
    cfg.MODEL.WEIGHTS = model_zoo.get_checkpoint_url(args.base_model)
    cfg.MODEL.DEVICE = "mps"
    predictor: DefaultPredictor = DefaultPredictor(cfg)

    image_file: str
    for image_file in args.images:
        img: np.ndarray = cv2.imread(image_file)

        output: Instances = predictor(img)["instances"]
        v = Visualizer(img[:, :, ::-1],
                       MetadataCatalog.get(cfg.DATASETS.TRAIN[0]),
                       scale=1.0)
        result: VisImage = v.draw_instance_predictions(output.to("cpu"))
        result_image: np.ndarray = result.get_image()[:, :, ::-1]

        # get file name without extension, -1 to remove "." at the end
        out_file_name: str = re.search(r"(.*)\.", image_file).group(0)[:-1]
        out_file_name += "_processed.png"

        cv2.imwrite(out_file_name, result_image)
注意:在这个过程中出现错误:
bash
raise AssertionError("Torch not compiled with CUDA enabled")

AssertionError: Torch not compiled with CUDA enabled
Mac Mini 的GPU 称为mps。我添加了cfg.MODEL.DEVICE = "mps"。你可以测试一下:
python
import torch
print(torch.mps.is_available())
True
运行
python
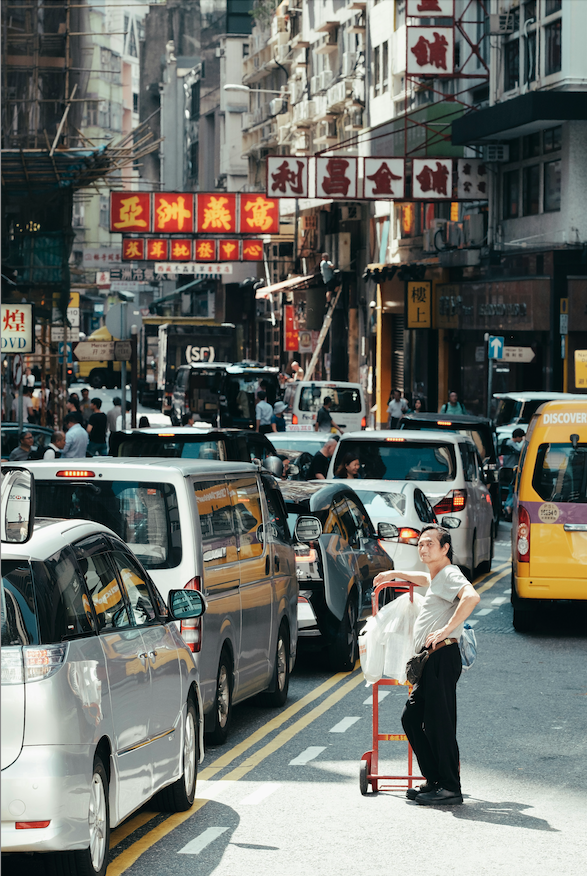
python detectron2_demo4.py --images david-clarke-KTF-gr3uWvs-unsplash.jpg输入的图片
输出
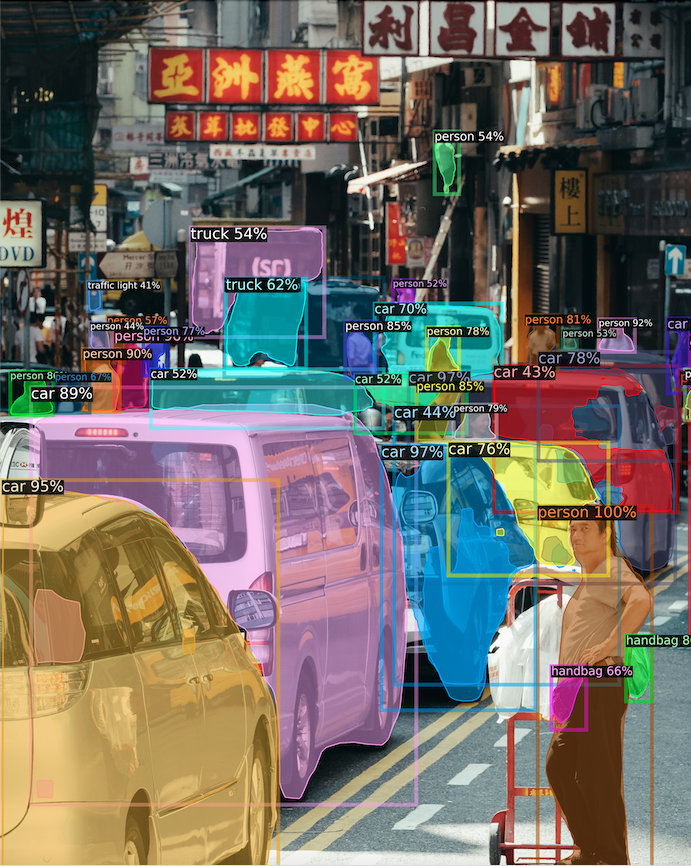
输出的速度比较慢,大约121秒。
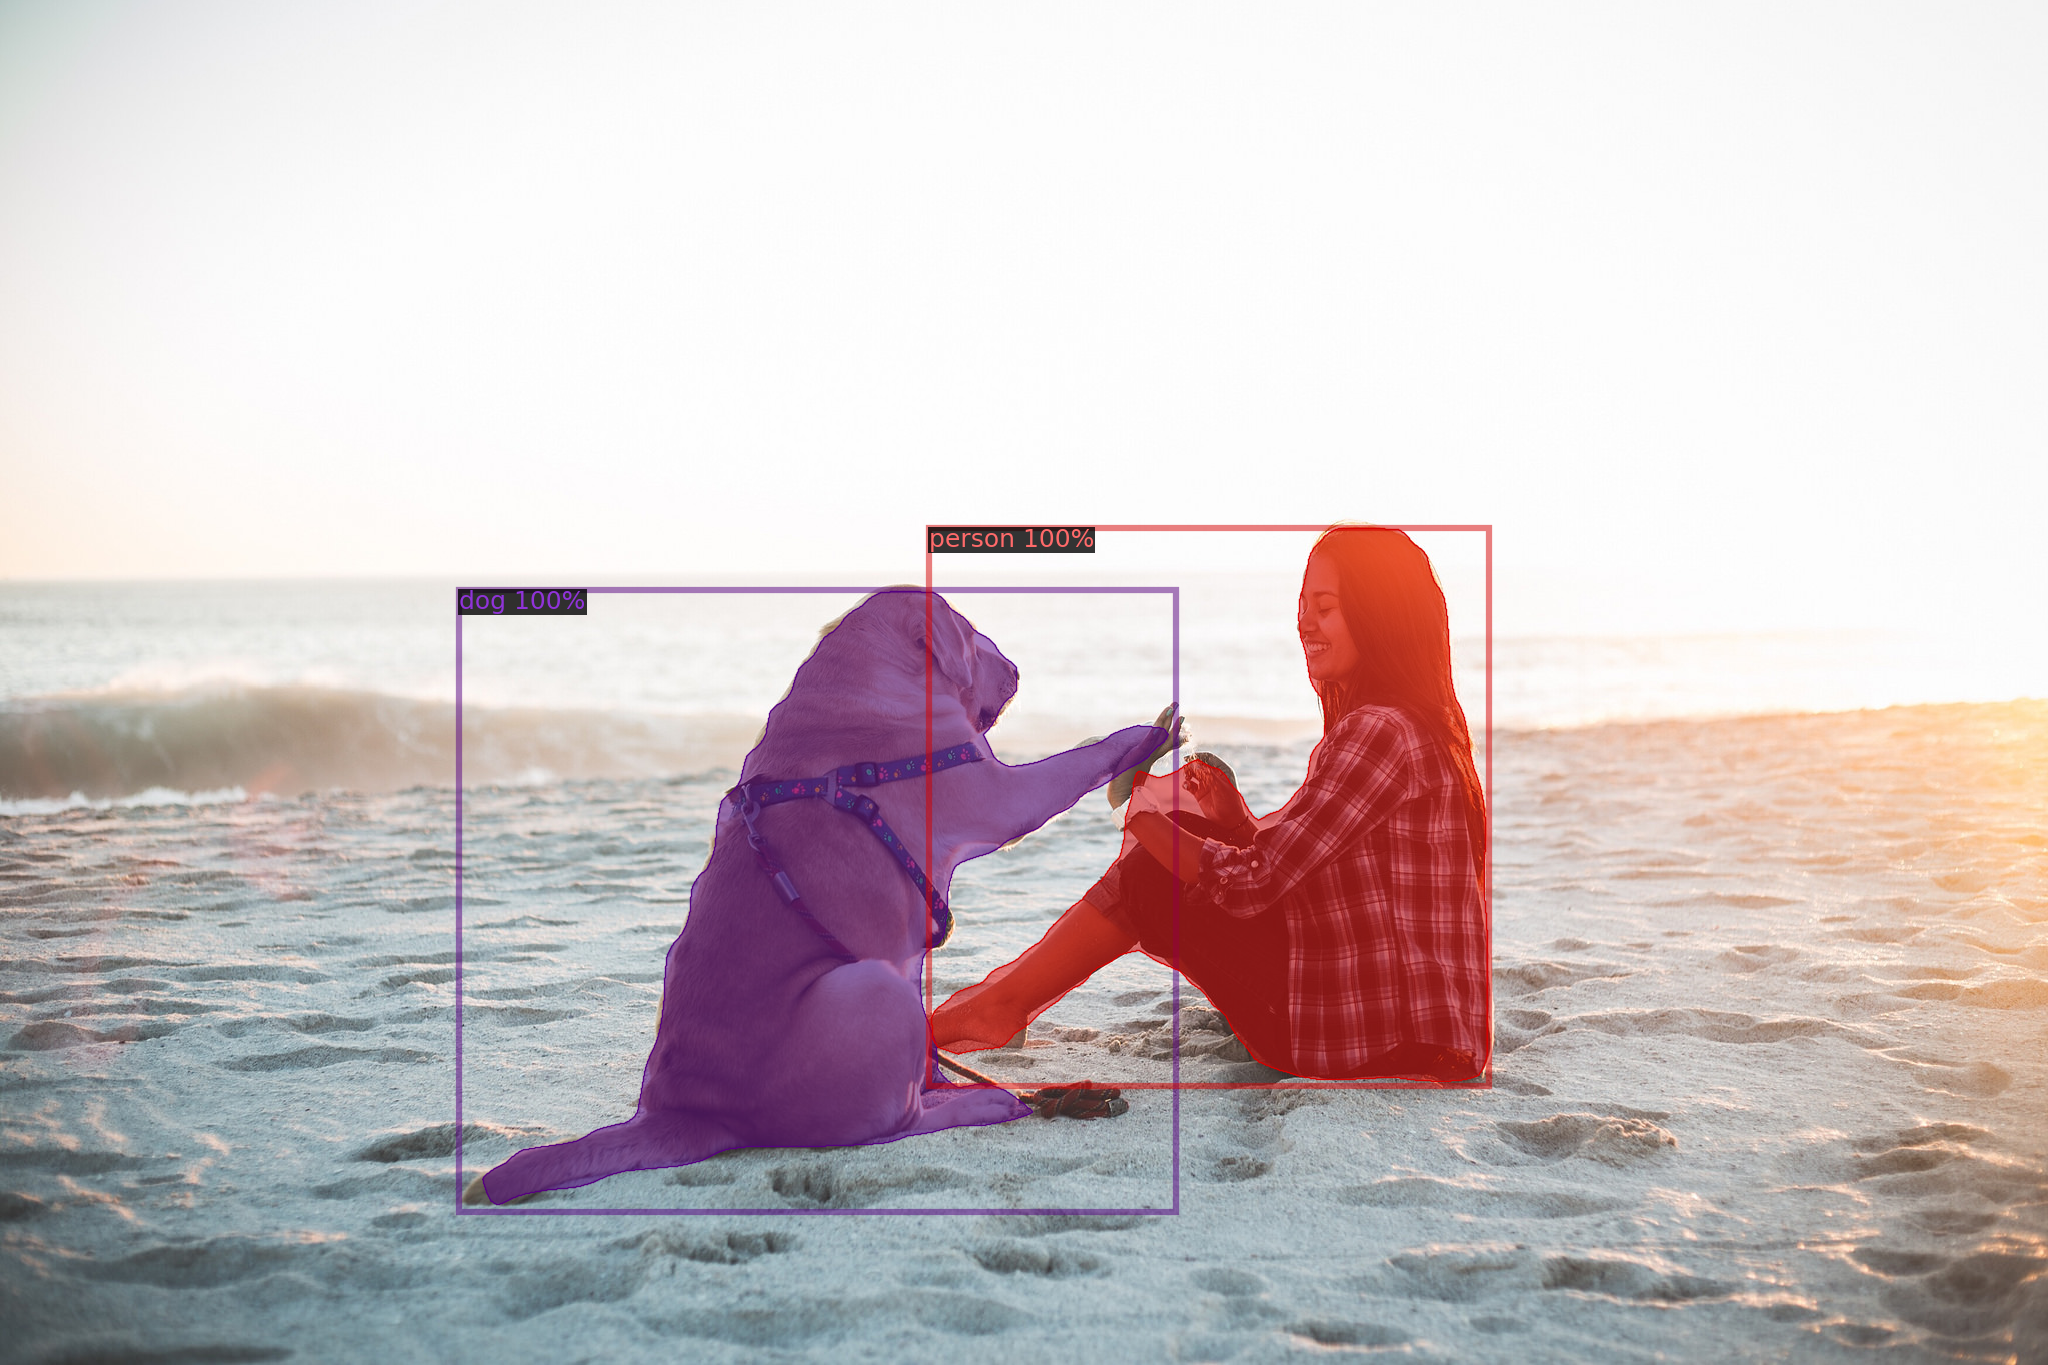
另一个图片识别
姑娘与狗
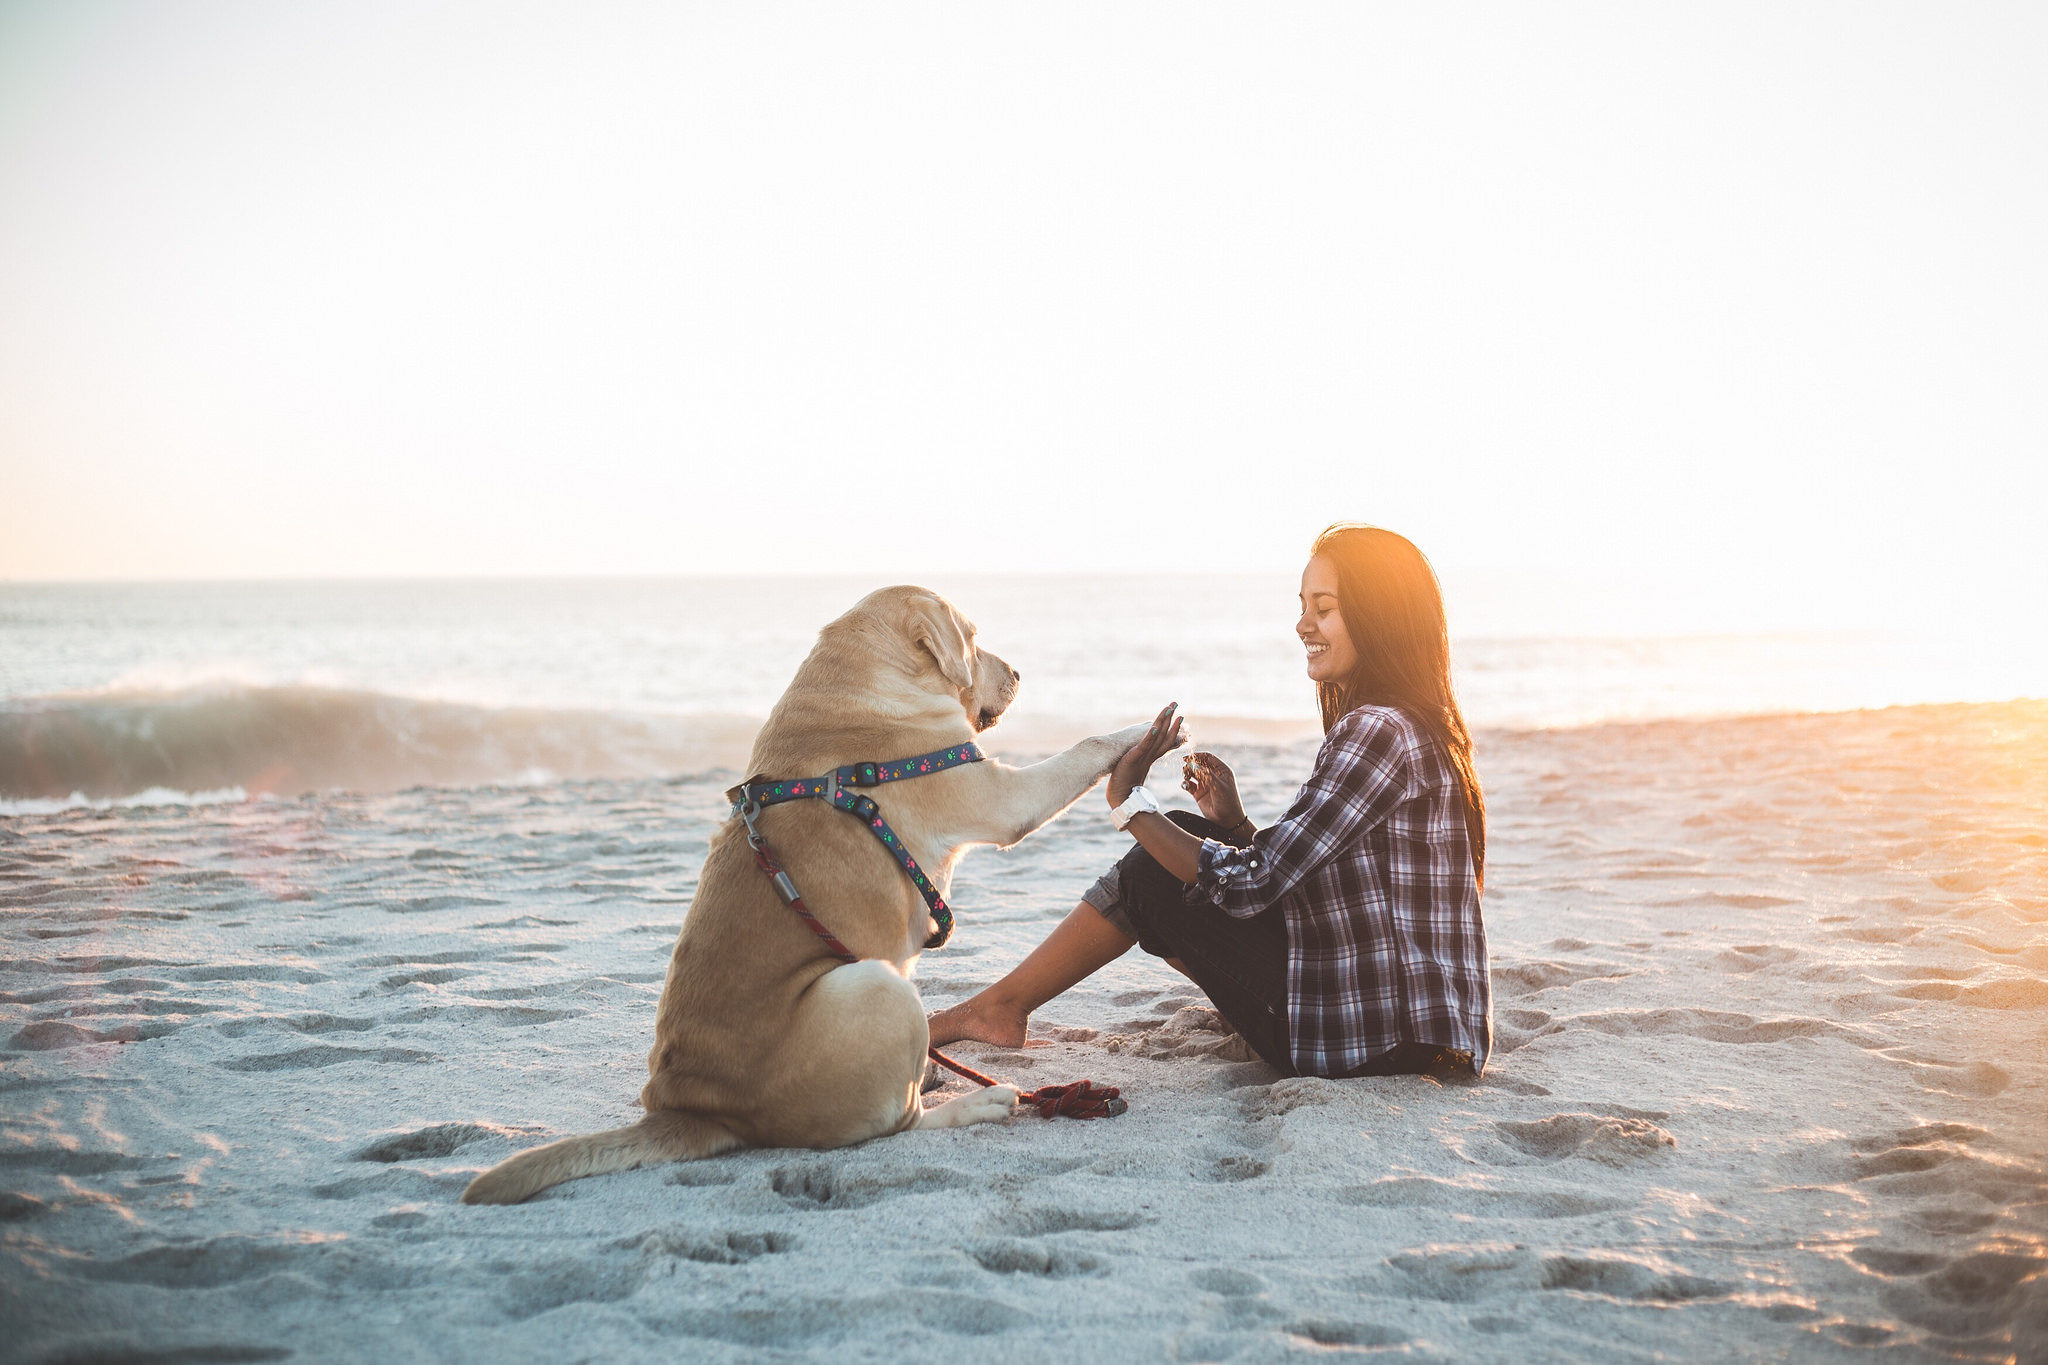
耗费时间99秒。
先这样吧,日后慢慢地学习。